


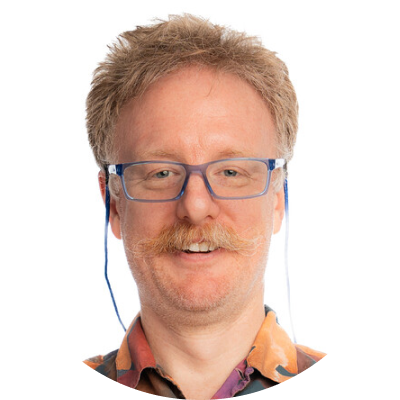
Richie helps individuals and organizations get better at using data and AI. He's been a data scientist since before it was called data science, and has written two books and created many DataCamp courses on the subject. He is a host of the DataFramed podcast, and runs DataCamp's webinar program.
Chat with AI Richie about every episode of DataFramed - all data champs welcome!
Key Quotes
What is needed is to be able to generate each one of those LLM results much faster, and for that you need an underlying architecture that's much more efficient at moving data. That's basically SambaNova's dataflow architecture — nine years into the company, we've been figuring out the communication inefficiencies so that everything can run at eighty, ninety percent utilization. Once you move that data faster, you can generate a thousand or two thousand tokens per second per agent. When you chain agents together, overall results are 10X or 20X faster.
Today's world of AI is maybe the '90s of how bits used to move on the internet. They were very expensive, and we used to pay attention to every bit that's moving, how many kilobits I've sent, and then count my internet bill. It's the same situation today with tokens: how many I've consumed and what my bill is going to be. In the future, I don't think we'll be looking at how many tokens we're consuming. For that to happen, tokens have to become a lot cheaper, and that means models have to become a lot more efficient algorithmically.
Key Takeaways
Data control is becoming a first-class infrastructure decision. Before picking a provider, decide up front whether data residency, security requirements, or a provider's capability limits push you toward hosting models yourself rather than calling an external API.
Better prompting beats bigger models more often than you'd think. Clearly scoping the problem and asking a model to verify its own output reduces hallucinations more reliably than simply switching to a larger, pricier model.
Judge AI infrastructure by efficiency, not raw compute. Power draw per rack, not just tokens produced, increasingly determines whether new AI capacity can be added to existing facilities without waiting years for new data centers.
文字稿
Richie Cotton: Hi, Sumti. Welcome to the show.
Sumti Jairath: Thanks for having me.
Richie Cotton: Yeah, great to have you here. To begin with I wanna start with a gripe, is why are a lot of AI agents, they're too slow, they're too expensive. How do we make them faster and better?
Sumti Jairath: So AI agents slow part happening for couple of reasons.
One, you remember like only couple of years back that pretty much how models used to hallucinate a lot. It's little lesser now, but a lot of contribution comes from, is from couple of factors. One is that making models bigger and bigger, like more parameters in there, more intelligence in there, more ways of thinking around it.
So that certainly add the parameter count, bigger context lengths and so on. And then second is the, the bigger reason is the reasoning as it came in a way that earlier, if you recall, we used to just interact with the single model, type in, "Oh, here is my question," and then it'll just reply and a lot of hallucination will happen.
And then as reasoning developed in the past few I'll say couple of years now we pretty much we give a model a chance to reflect on what it is saying, validate it, and then come out with. That in turn ends up generating a lot of tokens in between. So really what is that end to end when a user is interacting, it is just they feel like, "Okay, I've given my prompt, whole bunch of agents did something to it, and my response came in, and there is a large delay in between."
And that's what basically few of the factors which are causing that really we are the, the slowness is coming. Now, there is a big factor on what platform these group of agents are running on and how that platform or underlying infrastructure makes a difference for its slowness or fastness of it.
We'll touch on a little bit of that part as well. But really from the needs point of view, that's what is happening. That's a group of agents, big models, lots of tokens generated and that kind of causing the slowness.
Richie Cotton: That's interesting that a lot of the innovations then over the last couple of years about having bigger models and having models that think for longer, these are essentially the, the source of the, the problems i-in terms of speed then.
It reminds me, 'cause there's been this sort of principle in software engineering for decades now about how you want things that are fast, good and cheap, but you only get to pick two. And this has been around for a while. Is there a fundamental solution then, or does this trade-off still apply?
Sumti Jairath: There is. So being to the way that as we're touching that need is that this is how we want to do it, or at least the, the ML research today parks us there, that you want to give models to, to reflect on its responses, and you want models to be bigger because that's the only way we have found so far to pack intelligence into it.
How to make it faster the, and cheaper. I think there are two different dimensions, but, and both of them there can be solutions of that. So if you look at the fast part of the agent, really what's happening underneath in these models is that all those ton of parameters which it has to generate every token, it has to read in all those parameters and then figure out, okay, this will be my next token and the token after that, and so on.
It generates that, then reflects and so on. Keeps going on that. On the traditional architectures on which these models are run, we call like a GPU-like architectures, the data movement is very inefficient because as you see that parameters reading and then the KB caches along with that and reading of those and processing them, all of that is a data movement problem.
And in these big model scenarios where the models are distributed across hundreds of chips and so on, it creates the scenario where it takes a long time to move all that data and synchronize the results as the processing is happening on the way and be able to generate that next token.
And hence you see that every token generation that's running is like at twenty tokens per second, fifty tokens per second, hundred tokens per second, that type of thing. Which was fine when you were interacting with a single model on that. But when you chain now twenty of these agents and every one of them, if you generate at twenty to fifty tokens per second, it causes a long delay by the time you get the response.
So what is needed is to be able to generate each one of those LLM results much faster. And hence you need is a underlying architecture that is much more efficient at moving the data. And hence basically Samba, SambaNova, basically data flow architecture, which is all about right from the beginning on a like now it's nine years into the company, we are basically figuring out all the communication inefficiencies and cleaning those parts up so that everything can run at eighty percent, ninety percent utilization.
And moment you move that data faster The same thing, you can generate a thousand tokens per second, two thousand tokens per second per agent basis. So then when you chain them together, overall results are 10X faster, 20X faster on that. That's the idea which is basically brewing out there since you hear a lot more since the beginning of this year, the premium tokens on that, that in this agentic world, everybody wants-- everybody felt that slowness, that it takes a long time every time I submit my job to the whole bunch of these agents.
That's what was going on underneath, and then everybody started to explore the solution of, "How can I make it faster?" NVIDIA kind of pitched at the beginning of the year, GTC as well, that Groq acquisition with NVIDIA was something to address something like that in future versus with solutions like Salmon or that's already there, basically where you can plug in the fast decoding solutions and then get that agentic system that is producing these tokens faster.
So that's the vector on the the fast part. Then question is on the like, "Okay, how can I get cheaper as well?" So really what is the cheap-- the, the cost expensive part on this whole thing is that what we call it the whole memory hierarchy. So you're trying to do two things. Your every agent/model wants to become bigger And then turns out a single model is not enough for carrying out all your tasks.
What you need is a bunch of agents that can do the work. But turns out that not all agents are active at all the times, basically. That, that you're shuttling your calls to, "Okay, here is my prompt and agent one, you do the work," then 10 agents do the work, and then another two do the work, and so on, but not all 100 agents are busy all the time.
So you need to have a platform that has enough of a memory to be able to hold all that information, in this case, information of parameters of those models as well as the KV caches on the machine itself. So if your cluster size for that single instance is smaller, it'll be cheaper on that. And the way to address that is to have the right memory.
So this is where SambaNova comes in, is that right from the beginning, we had the three levels of memory hierarchy, where there is a, the SRAM on chip, which produces-- that gives us the tiling. That's where the speed part comes from. And then the HBM and the DDR, which adds tens of terabytes of memory per machine, and be able to hold all those agents together, be able to hold all those bigger models in the same machine and being able to serve from that one.
So that brings in all of the cost of a single system down, as well as a huge benefit on the power side of things. Now you don't need 100 kilowatt, 200 kilowatt, 500 kilowatt racks. You can serve these models with 10, 20, 30 kilowatt racks.
Richie Cotton: It sounds like there's so many possible optimizations out on this inference engineering side of things.
Maybe just to take a step back, I think a lot of people, they interact with an agent or a model, and then there's all these different layers of infrastructure below that. Do you just wanna give an overview of what all these different layers are, just so people have a, a, a concept of it?
Sumti Jairath: Everybody draws their own set of layers as we from SambaNova see it right from, because we do the full stack, so I'll just give the, the structure right from there. So at the bottom of the, the layer is basically the chips that, that are the, the engines which are doing all the work.
This is a combination of basically everything that goes into the primary ones are your accelerators, which you call these days are GPUs, RDUs, XPUs all of those things underneath. On there they work with CPUs of the system along with storage and networking and those pieces. So that's the first, your hardware layer where all the innovation gets packed, where is it traditional way of computing or new way of computing, and what ML is telling us and how the, the future chip should be done.
All of that innovation happens at that level. So SambaNova in that part does its own RDUs, and hence we're differentiating a little bit in the previous section here, which is basically how memory hierarchy and the SRAMs and everything makes difference in cost and cost in the speed part. Then a layer on top of it is that once you have that system underneath it, what kind of system software you put on top of it?
So compilers, runtimes, all of those things that's a layer through which various developers who are developing the model interact with these machines on there. So if I'm developing an inference model Deep Sea GLM and so on that's the compiler I'm interacting with, that's the runtime I'm interacting with.
Then on top of it comes, is a model layer, which is the, your ML applications. Now, this is the developer who is coming onto this machine using the bottom two layers and putting the model together. And then the, the layer on top of what it is the serving layer, which is basically we are a collection of model set, and these are how the billing will work, how the orchestration will work, because underneath you have a, not a single machine, but whole bunch of machines in a data center.
So which model is getting served on which machine and how to build this user, how to provide SLAs and so on. So that's a layer that keeps track of it. And then the topmost layer is the, the API layer, basically, which is standard OpenAI or a, a API that, that you want to serve user with. So in the end, what, when a user comes in on any cloud service, they really see is the topmost layer, which is that, "Oh, here I go.
I sign up, I get my key, I plug it into my app. I see what rate I'm going to get billed at, and then pretty much I start sending my prompts to that URL with my key and then get the response." But underneath, then rest of the layers behind the scene are working to provide you that SLA, that efficiency, that speed, that cost,
Richie Cotton: basically.
Okay. Yeah. There's many layers of depth into the infrastructure kind of below what and I guess for people who are trying to figure out where should their models run, like choosing an inference platform, like what do you need to worry about?
Sumti Jairath: Two things going on, on, on that one.
If we talk about the enterprise part, there, there is a little bit of the, the personal stuff like, "Oh, where should I take it?" But if we touch on the enterprise part first, enterprise sovereign part I would say. So the easiest choice is that there is a model provider that's providing me with those SLAs and costs, and I just go there And a lot of people are using that totally good way of using the models.
That's where you get a choice of model, which is like it could be a frontier lab the latest and greatest model. In that case, you interact with it through the API. Or it could be open source model. And there are providers for each one of them out there and you can go and pick and choose.
Now, there is this sense which is starting to develop is that, so we've lived through the world of search which is basically last twenty, twenty-five years. Bas- we have gotten used to send my search to Google or wherever your choice of search engine, and then you get the results back and so on.
But with AI, this is sending the prompts and getting the responses back is to the next level, where you're sending a lot of information in that prompt and getting the replies back. So there is that uncomfortness of that, is it fine for me to send this information to some place, even though all the agreements are signed and everything else?
But still information is leaving your house or your company and then going somewhere else and somebody else is responsible for. Plus, there is that always to improve models, you know that this information in some way is going to get into the next generation of the models as well.
So that's prompting the idea of that, or should I just deploy these models in-house? Then I get to keep that censorship of like in a way that whatever really the... I get that security basically that data never left my data center, and I can just deploy it in my data center part.
Second reason that is starting to come out is that the censorship part, which is as models are becoming more and more capable, now you're starting to see that the, the provider is starting to limit the capability. Oh, I will make a choice whether you get that capability or not on this. And that's starting to make folks a bit uncomfortable as well that, okay if there is a proof of existence that certain capability exists in the world, I must have it as well.
So when they don't get it from the provider, then they are starting to look for that, "Okay, can I just recreate it within my lab?" It could be just a used open source model if it has that capability and deploy it. So there are several of these reasons which are starting to develop out there that security and censorship, which is basically why not take your open source model, which are cap- getting capable enough, and put it in your data center and deploy it out there.
Richie Cotton: Okay. Yeah. This is very interesting, this idea of sovereignty and which bits of the AI infrastructure stack you want to control yourself. I guess sovereignty, it comes from a, a nation idea, but it's also for individual companies as well.
Sumti Jairath: Yes. Yeah. Yes. Exactly. So yeah, the first part was really for companies, certainly it is their co- the data leaving my company, but it's much, much more prominent on the sovereign AI because every country wants to keep just its data local to its region on there.
Richie Cotton: Absolutely. Okay. Maybe we'll talk about individual companies first. But, so suppose you say, "Okay, we've got the sensitive data. We don't want to send it out via an API to, to some large language model provider." W- what do you need to do then to keep that data security, to keep their data privacy as well?
Sumti Jairath: Yeah. So the, the process generally goes like this that in that case, you make a choice of the models that are available to you that you find suitable for your application, so a lot of open source models on, on there. Then you work with the provider, like one of the infrastructure provider. Could be SambaNova, could be anybody, could even buy GPUs on, on that.
So really the act there is that provisioning your data center figuring out the power storage, everything, all the resource needs, installing those machines and then having those layers of which we talked earlier that the serving stack and so on comes on top of it and then the models get deployed and served.
Now, with these solutions available, also available from SambaNova, these are becoming a lot more click button solutions, so serves every type of customer on there. There are customers who are just getting started- On this path where it is like, okay I have a need to serve AI for my engineering team, for my developers, for my customers, but I don't know how to build this infrastructure on my own.
And we provide a solution called Samba Managed for those, where basically it's a click button from customer's point of view. They own the machines, they own the whole AI infra. It sits in their data centers And they are controlling which customers or which of their employees get access to that API and answer.
But all of this is managed by SambaNova. So in a way that the, the customer who is installing all this, they don't need to know anything about or they need not worry about, like, how to manage this infrastructure. And as those customers become more capable in dealing with those problems over time, then they can take the management aspect on themselves as well.
Then there is the customers who are a lot more experts in, in all of this. So there we ship the product like SambaStack, which is right from the beginning, we don't need to be in the loop. This whole solution of those serving layers just lands in customer data center. They deploy it, they hook it up into their data centers in whichever way they want to deploy.
It could be just the, our RDUs, or it could be a combination of that. They have a preexisting GPUs in their data center where they're serving the workloads, and then G-- and RDUs come in and are added to that data center, and then they start to do a lot of those like disaggregated inferencing, where basically pre-fills may run on the GPUs, decode for speed and efficiency may run on RDUs and all of those fancy infrastructure with BLLM and everything we support there as well.
So that's a second set of this.
Richie Cotton: Okay. So it sounds like there's a real sort of continuum of different options depending on how much convenience you want and how much control you want. So you start off... we talked about the one extreme is using o-other providers you're just accessing the models through an API, and the next thing is you've got a managed set of like a managed service and then you go into maybe I'm running my own data center, and gradually you can get more and more control.
Is that about right?
Sumti Jairath: Exactly. Yeah. Yeah.
Richie Cotton: Okay. In, in terms of deciding which one you want, we talked about data privacy and security issues. Are there any other factors that are gonna affect your decision about how you decide what your your AI infrastructure's gonna look like?
Sumti Jairath: So other thing which are starting to play a role is the cost part of it as well. Pretty much when you go out the choice and the model serving you have, you may not have... that solution may be expensive. The one, one example I can pick is, for example, coding agents. That has become so popular in, in recent months.
And everybody seeing enough value out of it i-in a way that every software developer out there can be 3X more effective, 5X more effective, 10X more, like the mileage varies. No doubt on that it provides productivity and efficiency scale varies from problem to problem on that. So that's a motivator, which is basically that everybody wants to enable their software developers to have access to the coding agents.
Choice could be that, okay, you go out there and then you do Codex, you do Cl-Claude, one of these like solutions. But if you unlock this, then every one of those engineer, every one of those developer is sending all the requests to these models, and it may pile up a lot of expenses very quickly on, on that.
On one side, you don't want to throttle the engineers because the, the possibilities are infinite right now, so you don't want to kind of limit. On the other side, you don't want to have that much of expense. Now, if you analyze that, what's happening, you don't need the expensive tokens for most of your...
So 90% of the, the work done in that can be handled by a much cheaper model on that. Versus 10% requires that intelligence of a frontier model that, that is needed here. Yeah. So people are starting to build solutions of that sort in-house. So in a way, that only way to do those then the custom things is that you study your profiles and see like really what's going on, what kind of agent mix I need.
And then you put together a solution in-house where basically all of your developers are accessing your solution, and that's where the call is getting made on that, or this is the reasoning part of the thing, and I need a powerful model. I'll go use one of the frontier model for that. And then once I have those results, then whole bunch of parse a log file to some, refactor my code to test my code.
Those are the things which can be done by the much cheaper open source models, and then you put them together in-house on, on that. So that's other reason, which is basically the, the cost and efficiency driving the decision here that do you go and use somebody else's solution or you just build your own custom.
Richie Cotton: Okay. That's very interesting specifically about the point on choosing models there. So you said, like quite openly, it's the reasoning, planning stuff that requires a frontier model, but everything else, like even writing code at this point doesn't necessarily need a, a frontier model. In a lot of cases, you can save some money by using the smaller, cheaper models as well.
Okay. I'm curious as to who needs to go about organizing all this stuff. Is it gonna be like a, a chief information officer or chief technology officer who needs to figure out all the, the infrastructure then? Or who makes these decisions?
Sumti Jairath: Yeah, largely at the CIO level, basically, where they see that what is the demand on one side and then other side how they are piling up the expenses and where the requests are going.
And kind of them working with CTOs and so on, okay, this is... Because technology is still new, there is like always needs a deeper analysis of really this is what we are seeing, these are the, the solutions possible, how do we factor in and build that layer and then go about the solution.
Richie Cotton: Okay.
These decisions generally come from the top down and then you decide how much
Sumti Jairath: And then pretty much bubbles up to those as well.
Richie Cotton: Okay. So I know there was a, a, a fad like a few months ago where it was like all these AI engineers was like buying Mac Minis to run their own sort of local inference.
Is is... Have you seen anything from the, this other of side of things on what's going on with these sort of local solutions?
Sumti Jairath: So that was largely like I'd say the control on your data is one part. So it's sovereign AI thing. So keeps your data local to your, in, in your house, all of those agents basically all those agents making call to the models part of it.
So certainly very interesting part where I would say this was more of a not on the enterprise side, but on the personal side, everybody starting to integrate AI into their day-to-day tasks they do. Like everything that was, they were monitoring, they were doing travel planning to my email monitoring, to my tasks, to my this, like all of those calendar reminders and everything else, like if you have a personal assistant on that, leave those kind of orchestration of those agents running on your Mac Mini or whatever spare computer you got a- at home.
And then you integrate different models. And and frankly, really a lot of what we talked early on here Pretty much people applying on a personal level as well where it was that, okay, I have the orchestrator running here, and I can as well point it to the ch- the GPD class of model or Claude class of models, and then do it.
And then they see okay, these agents are all day working, like whether they're generating code for me or whether they are, like, doing my these random tasks, but they're burning tokens so it's costing me a lot. Or why not, since I have the Mac Mini, I... Why not I install Ollama on my Mac Mini as well?
It can run all those free, cheaper models, much smaller models in this case. Even if it is slower, that's fine, but these are the tasks which are running in the background and they start to deploy those models. So that way they re- start to redirect some of the traffic of okay, complex reasoning, go do on Claude, come back, and then for...
Once you figure out executional steps could be on my Ollama local Mac Mini part of it. Very much the enterprise world reflected at y- at your home as well. If just that access to the technology became w- with that step be it's it's present at your home basically now.
Richie Cotton: Okay.
Yeah, it's very cool that you can have all this stuff basically like a, a mini server in a box. Actually, i- is this something we might see from SambaNova in the future, like your own personal AI platform?
Sumti Jairath: We so far are focused on the data centers and the edge in the data center. We're not so architecturally totally possible, but the market that we're trying to take care of is really just the data centers for now.
Richie Cotton: All right. No plans to fight Apple on the personal level then. Okay.
Sumti Jairath: Would love to do it as an engineer, but but really too much to do on the data center side so far. So I don't think as a company we'll get enough time to be able to address that.
Richie Cotton: All right. M- maybe not this quarter.
Okay. Since you mentioned data centers there's been a lot of talk it's been going for a couple of years now, about whether or not we're in an AI bubble. Are we building too many data centers for AI? Are we not building enough? I haven't found a consensus yet. Do you have a take on this?
Sumti Jairath: So question is, are data centers for what?
Because we n- demand for tokens is so much that we need to serve that demand, and hence to serve that demand we need data centers where all these machines are installed, AI infrastructure is installed that can generate these tokens on there. So then question, okay, so where is the demand coming from on this?
And what that triggers is that what are the popular AI applications out there? Now, there is one side which is every enterprise, every person, they're building their AI apps and that's kind of- trickling in those tokens. Nothing comes out popular as yet on, on that. Versus then something start to happen, I would say end of last year, beginning of this year, where you start to hear coding agents on that.
That was, I would say, first very big application of-- apart from means I think we have seen the autonomous cars AI application, but that business is very well contained on those car companies and what they're on. So inferencing tokens are really on the car and the training of those models. We are seeing the robotics and everything else yet to come, how that'll be consumed, but those will be like again, tied to the machines.
The real AI application, which is hungry for the tokens, really came I call it like coding agents was the part where everybody saw that and you can see from the revenue the ARRs that at least that what OpenAI and and Anthropic and every numbers that you hear, like 100 billion ARRs and then growing very rapidly.
So this one big application kind of restarted that discussion of that, okay, once you start hitting that level of maturity where applications start to serve and now in this case, entire software development, pretty much it's an integrated tool and the money along with that is measure. That itself is like, okay, we don't have enough tokens to serve the market, and hence we need to build the data centers on that.
So we have enough, and this year you're seeing getting fueled by that. What will be the second application there and the third and the fourth, b- when the medical sciences reaches that point, when the legal reaches that point and then, and so on, basically we are, these keep serving the big domains.
That is yet to be determined. And hence this is why answering that question that are we overbuilding or are we underbuilding, like the, the data center part not clear yet. It was questionable, I would say mid next year. With coding agents, it is certainly, oh, we are certainly underbuilt right now because the demand is so much high and that's going to happen.
As more applications come in, then that means we are still underbuilt and more of these are needed. If it saturates, that means, okay, we overdid it at that point. But it is really getting driven by what is that popular AI app that changes the economics of everything that out there, and then basically you need to feed in.
I think if I were to just guess, we are underbuilding right now because a lot of these applications means everybo- every one of these domains will find their, the, the trigger point where it's like, okay, now it's good enough and it just overtakes that area and then AI applied widely into that.
Richie Cotton: Okay. Yeah. So I suppose with building a, these, particularly these large AI data centers, they're huge campuses and they take years to build predicting what the demand's gonna be five years down the line that's gotta be a bit of a mug's game. So I can certainly see how it's very difficult to get the exact capacity right.
Sumti Jairath: Yes. The one thing I will add on that one, this is where how Salmon Ward philosophy differs there is the most popular platform being there, being GPUs to build the data centers. The, the, the two things are getting conflated there, which is that yes, there is a token demand And yes, data centers need to have these AI infrastructure and AI machines to produce those tokens.
But just because we are solving that problem with the inefficient machines, which is like traditional architectures, what it is triggering is that, oh, I need to have those gigawatt data centers. The newly built gigawatt data centers, they are each machine could be 300 kilowatt, 500 kilowatt rack on that.
Versus if you look at from SambaNova's perspective that Yes, more tokens are needed. Yes, those data centers need that capacity, but these machines can be a lot more efficient in producing those tokens on that. And once you build that efficient machine, it need not be a 100, 200, 500 kilowatt rack, it can be 10, 20, 30 kilowatt rack.
And once you have that solution, which is what SambaNova solution is, now you can go into your existing data centers and your greenfield data centers, like the, the data centers which are getting vacated out of telecom or from the crypto wave of things. These machines can... And this is what we see at SambaNova, basically that those, those data centers are available and ready all across the globe, and you can just put these machines in there and serve your token capacity using a better model on that.
So that way you get, basically, you redeploy or you reuse your existing data centers, you deploy SambaNova machines, power efficient, and you get a premium token speed that solves the agentic problem. So the difference is that you don't need to wait for your gigawatt data center to be ready before you can take a step on AI.
You can take that step today.
Richie Cotton: Okay. So this is really changed what's going on at the chip level, at the hardware level for individual machines, and you can, it sound like it's about an order of magnitude power saving then, Exactly.
Sumti Jairath: Yep
Richie Cotton: Okay. Actually I don't know what the lifespan of these these components in the data center is.
Like, how often do the chips, do the, the GPUs do the do the, do those bits of hardware get changed out?
Sumti Jairath: So usually it is the, the useful life is every data center determines their own, so it is a three to six years is the life for these. But really the way... The three years is the prime life, and after that the machines get switched into serving the non-critical workloads or where you can afford to run your older workloads on that and fill in the capacity.
But really it runs from three to six years of life. Okay. Maybe some of these older things they get switched out and we're gonna have like the more like generative AI native hardware, like take- being standard in, in a few years' time. Okay. All right. So i-it sounds like 'cause there's so much building going on AI infrastructures like it's the, the new set of hot careers.
Richie Cotton: Talk me through what job roles are available and what skills you need to get involved in working in AI infrastructure.
Sumti Jairath: Yeah, no, a-as SambaNova, we do the full stack, all those layers that I described earlier. We're looking for engineers in all of those layers of the stack. So whether you are a chip designer or verification engineer, pretty much like we need a ton of or like we keep building the future generations of the, the silicon.
So system engineers, the, the chip engineers, all of that is the skill set for the first layer. Then the next one, compiler and runtime system software background, like ton of folks needed there. Then our ML side of things, ML models, ML infrastructure so we're looking for engineers in that research, as well as the building the models on, on that.
Because as being a newer architecture, it enables us to rethink the problem in newer ways as well. So a lot of ML research part also happens in SambaNova, so looking for those. And certainly then the serving layer of billing and orchestration and cloud orchestration part, APIs and so on.
So engineering in, in that areas as well. So we're looking for- engineers in all of the areas
Richie Cotton: above Okay. So lots of different engineering options. I presume these are all things where do you need a degree? Do you need a research background as well, or is it, what's, what are the sort of qualifications required?
Sumti Jairath: No, all, all levels we need and these requirements are listed on our website for each of the role kind of differs a little bit but if you have a bachelor's about, or above degree, and we encourage both sides of it, experienced folks as well as passing out from school just fresh.
We have had a great success on both ends of it. We nurture a variety of folks coming in from school, and then they become our, the, the, the superstar engineers over time on, on there, as well as the experienced folks basically who kind of mentor these folks and work hand-in-hand together.
Richie Cotton: Very good stuff. So it sounds like a good variety of options there. It does seem it's maybe one of the most exciting parts of of what's going on with AI, just like building all this cool stuff. One thing I'd like to talk about before we wrap up is the Samanova API, 'cause y- you course you've got an option to build to use data science agents from that.
So what kind of things are people building with these data science agents using the Samanova API?
Sumti Jairath: We touched a little bit on this while we were talking about... So really, Samanova provides the API, and then we work with customers, and then we see that what all they're doing. So various domain, but they're focused on things like these as well.
One which I described is this whole coding agent. It's very popular, everybody burning a ton of tokens around around it, and then them using these APIs for building that, those hybrid solutions of that how to use a frontier model along with the open source model, and then you get benefits of both.
Basically being cheaper as a result, and faster as a result because- Whatever runs on the open source model on SambaNova side of hardware would be a much faster as well. So there is a lot of activity in, in that domain using these APIs and being able to build the coding agents. Other side we see is a lot of deep research customizations where basically there are a lot of open source solutions available, but the needs per companies vary a lot.
Oh, I got a particular type of contracts, or I got a particular type of information, or I want to do a web search here and then apply certain transformation and then process the data, and so on. So to be able to extract those results per domain-wise intelligently out of it. So building those custom solutions where they basically take a, an orchestrator layer and then they take our APIs, plug it together, integrate all the tooling that is custom to their...
how do I plug in my-- the, the bug reporting engine? How do I plug in my Slack into it, and how do I plug in my various tools which are inside, like my billing part of it? And then really come up with an answer which otherwise is a lot harder to do on that. So a lot of deep research integrations happening on that.
And then third area where we're seeing a lot of traction is now the multimodality part as well, which is one side of it is that being able to absorb along with text all the video clips as well, and being able to pinpoint that what's happening in the clip, extract that information or where is the particular clip that, that gives me a part information because that thing done manually is very hard And the second part of it is really the audio piece of it.
A lot of conversation engines, lot of customer support automated through the kind of voice agents in this case. All of that requires with what pretty much what SambaNova gives, which is that to be able to handle voice in a live manner, you need to have a very low latency. You need to feel conversational, where you say something, agent says something, and then you reply back and that whole thing need to look live.
So that requires very low latency where ba- basically speed of tokens again matters. And in that case, so this is where SambaNova is excellent at. And then second part in there is that a lot of domains, lot of accents, lot of context setting, those are all many tiny models out there. So you need to be able to take all those models and host it together, and based on the sentiment, based on the language somebody's talking in, based on the accent somebody's talking in, you pick and choose the right model and have it serve tokens at a very high speed on that one.
So seeing a lot of traction in the audio side of things where Ton of agents, hundreds to thousands of these agents, which are like languages, accents, sentiments, and so on. And depending on the context, pick the right one and serve fast tokens and that start to create, take care of the audio side of things.
Richie Cotton: Okay. Yeah, of course. Certainly audio is, if you've got a bit of a lag in between you saying something and the AI saying something back, I can imagine that's a terrible user experience. So yeah. We're back to where we started. Speed is important in, in some use cases for AI. All right.
Finally I always want more people to learn from. So whose work are you most excited about at the moment?
Sumti Jairath: So pretty much I personally believe in that even though all these efficiencies and everything else exists and there is work going on, for AI to be pervasive and be able to get into everything, it'll need to get a lot more cheaper from here on as well.
It is like I call it today's world of AI is maybe the '90s of how bits used to move on internet. They were very expensive, and we used to pay attention to every bit that's moving, how many kilobits I've sent, and then I've used to count my internet bill. It's the same situation today, or how many tokens I've consumed and then what my bill is going to be and how do I throttle versus we look at today, I don't even look at how many terabits I'm using on my internet.
It's just I focus more on the achievements out of it the, the bits serve the purpose in the back. Same way AI is going to be like I don't think in future we would be looking at how many tokens I'm consuming. We'll be more focused on the, on that. So for that to happen, the tokens have to become a lot more cheaper, and that means the models algorithmically have to become a lot more efficient in, in that case.
So that's the work that we are focused at Ensemble and that's what we follow. And what is going to really require for that is the model understanding. So many names out there who are researching, Chris Olah from Anthropic and many others who are, like, really looking into how these models respond, what's going on inside, and once you crack that open, it starts to enable a lot of these things.
The model explainability part, as well as designing a better model that's a lot more efficient. Like today's races right now is more of a brute force that we are in the phase of where we are exploring the capability of the model. So it does not matter if it's inefficient, everybody's after "Okay, what capability can I like..."
Everybody's looking for that singularity first, and then make it efficient. At SambaNova, we are yes, interested in singularity, but along with that, keep making progress towards making it efficient as well to make it much more pervasive for everybody's use.
Richie Cotton: Yeah, there's two very different goals is like, can you make more powerful AI, and can you make AI that is good enough that, that's cheap and fast and all the rest of it?
Sumti Jairath: And I think both can run in parallel and SambaNova, we're showing both of those paths, that models keep getting better and better, and they give you better answers. Along with that, there are ways to do things which make it more efficient, whether it was speed of the tokens, whether it is the capacity of those parameters, and then going forward, pretty much making them a lot efficient on compute as well.
Richie Cotton: All right. Fantastic stuff. Thank you so much for your time, Sumti.
Sumti Jairath: Thank you for having me.
Richie Cotton: Hi, Sumti. Welcome to the show.
Sumti Jairath: Thanks for having me.
Richie Cotton: Yeah, great to have you here. To begin with I wanna start with a gripe, is why are a lot of AI agents, they're too slow, they're too expensive. How do we make them faster and better?
Sumti Jairath: So AI agents slow part happening for couple of reasons.
One, you remember like only couple of years back that pretty much how models used to hallucinate a lot. It's little lesser now, but a lot of contribution comes from, is from couple of factors. One is that making models bigger and bigger, like more parameters in there, more intelligence in there, more ways of thinking around it.
So that certainly add the parameter count, bigger context lengths and so on. And then second is the, the bigger reason is the reasoning as it came in a way that earlier, if you recall, we used to just interact with the single model, type in, "Oh, here is my question," and then it'll just reply and a lot of hallucination will happen.
And then as reasoning developed in the past few I'll say couple of years now we pretty much we give a model a chance to reflect on what it is saying, validate it, and then come out with. That in turn ends up generating a lot of tokens in between. So really what is that end to end when a user is interacting, it is just they feel like, "Okay, I've given my prompt, whole bunch of agents did something to it, and my response came in, and there is a l
Sumti Jairath is Chief Architect at SambaNova Systems, where he's focused on machine learning, big data analytics, and software-defined hardware since 2017. Before that, he spent close to eight years as a Senior Hardware Architect at Oracle working on hardware acceleration for machine learning and data analytics, and earlier held processor and server design roles at Hewlett Packard and Sun Microsystems. He holds a B.Tech in Electronics and Communication Engineering from the National Institute of Technology, Kurukshetra.