SQL subqueries are a powerful tool in database management, allowing for more complex and efficient data retrieval. This guide will walk you through the fundamentals of SQL subqueries, offering insights into their practical applications and advanced techniques. Whether you're a beginner or an experienced professional, mastering subqueries can significantly enhance your SQL skills.
For those new to SQL, consider starting with our Intermediate SQL course to build a strong foundation. Also, I find the SQL Basics Cheat Sheet, which you can download, is a helpful reference because it has all the most common SQL functions. Finally, I want to say that subqueries are a common SQL interview question, so if you are preparing for an interview, you've come to the right place for a review.
What is a SQL Subquery?
A subquery allows SQL queries to be more modular by handling tasks that would otherwise require multiple separate queries.
Definition and purpose
A SQL subquery is a query nested within another SQL query, used to perform operations that require multiple steps or complex logic. The role of subqueries in SQL include the following:
- Filtering records based on data from related tables.
- Aggregating data and performing calculations dynamically.
- Cross-referencing data between tables to retrieve specific insights.
- Conditionally selecting rows without requiring explicit joins or external code logic.
It sounds like a lot, but it will make sense as we explore these things in the tutorial.
Types of subqueries
It might surprise you to learn that there are different types of subqueries. The different types are grouped based on and suited to different kinds of data retrieval needs. You can choose from the following subqueries depending on the operation you want to perform:
Scalar subqueries
Scalar subqueries return a single value, such as one row and one column. They are often used where a single value is expected, such as in calculations, comparisons, or assignments in SELECT or WHERE clauses.
In the example below, the scalar subquery (SELECT AVG(salary) FROM employees) returns a single value, the average salary, and compares it to each employee's salary.
SELECT employee_name,
salary,
(SELECT AVG(salary) FROM employees) AS average_salary
FROM employees
WHERE salary > (SELECT AVG(salary) FROM employees);
Column subqueries
Column subqueries return a single column but multiple rows. These subqueries are often used with operators like IN or ANY, where the outer query compares values from multiple rows.
For example, the subquery below returns a list of department IDs for departments located in New York, which the main query then uses to filter employees in those departments.
SELECT employee_name
FROM employees
WHERE department_id IN (SELECT department_id FROM departments WHERE location = 'New York');
Row subqueries
Row subqueries return a single row containing multiple columns. These subqueries are typically used with comparison operators that can compare a row of data, such as the = or IN operators, when multiple values are expected.
The following subquery retrieves a manager's department and job title, and the outer query finds employees with matching values.
SELECT employee_name
FROM employees
WHERE (department_id, job_title) = (SELECT department_id, job_title FROM managers WHERE manager_id = 1);
Table subqueries (derived tables)
Table subqueries, or derived tables, return a complete table of multiple rows and columns. These are commonly used in the FROM clause as a temporary table within a query.
For example, the subquery below creates a derived table of average salaries by department, which is then used in the outer query to find departments with an average salary above a specified threshold.
SELECT dept_avg.department_id, dept_avg.avg_salary
FROM
(SELECT department_id, AVG(salary) AS avg_salary FROM employees GROUP BY department_id) AS dept_avg
WHERE dept_avg.avg_salary > 50000;
Understanding SQL Subqueries
From the above examples, we have seen that a subquery is enclosed within parentheses. Let us now explore the mechanics of a subquery, including its syntax and execution order.
Syntax and structure
The syntax of a subquery varies depending on where it is used in the main SQL statement, such as within SELECT, FROM, or WHERE clauses. Subqueries are typically enclosed in parentheses ( ), indicating a separate query.
The following example demonstrates a subquery within a WHERE clause, allowing us to filter data in the main query based on the results of a nested query.
SELECT column_name
FROM table_name
WHERE column_name operator
(SELECT column_name FROM table_name WHERE condition);
Execution order
The execution order for subqueries depends on whether they are correlated or non-correlated.
Non-correlated subqueries are independent of the outer query and execute first. The subquery's result is then passed to the outer query. Non-correlated subqueries are commonly used for scalar or column-level calculations and filters.
The query below follows the execution order:
SELECT employee_name
FROM employees
WHERE salary > (SELECT AVG(salary) FROM employees);
I recommend taking DataCamp’s Introduction to SQL Server course to learn more about grouping and data aggregation, and joining tables.
Correlated subqueries depend on the outer query for some of their data, so they are re-evaluated for each row processed by the outer query.
The following query executes in this order:
-
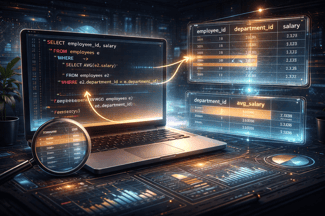
For each row in employees (aliased as e1), the subquery (SELECT AVG(e2.salary) FROM employees e2 WHERE e2.department_id = e1.department_id) calculates the average salary for that specific department.
-
The outer query then compares each employee’s salary with the department’s average salary and includes only those who earn more.
SELECT e1.employee_name
FROM employees e1
WHERE e1.salary > (SELECT AVG(e2.salary) FROM employees e2 WHERE e2.department_id = e1.department_id);
Applications of the SQL Subquery
SQL subqueries are important for data retrieval and transformation, allowing you to write complex queries and handle advanced data analysis tasks. The following are real-world applications of subqueries in database management.
Filtering data
Subqueries are useful when filtering data based on dynamic conditions, especially when filtering requires comparing values across multiple tables or performing calculations.
The following subquery retrieves the category_id of "Product A," and the main query finds all products in that category.
SELECT product_name
FROM products
WHERE category_id = (SELECT category_id FROM products WHERE product_name = 'Product A');
Data aggregation
Subqueries are also used for data aggregation, especially when generating summary statistics or insights for reporting and analysis. The subquery (SELECT department_id, AVG(sales) AS avg_sales FROM sales GROUP BY department_id) calculates the average sales per department. The outer query then filters departments with an average sales above 50,000.
SELECT department_id, avg_sales
FROM (SELECT department_id, AVG(sales) AS avg_sales FROM sales GROUP BY department_id) AS dept_sales
WHERE avg_sales > 50000;
Although subqueries are powerful when writing complex queries, they may impact performance, especially when working with large datasets. It is important to consider the common pitfalls and best practices for improved performance.
Optimizing subquery performance ensures improved query execution time and database responsiveness. The following are ways to optimize the subquery.
-
Index Relevant Columns: To speed up data retrieval, ensure that columns used in WHERE and JOIN clauses and comparison operations are indexed.
-
Limit the Use of Correlated Subqueries: Where possible, use JOIN operations or CTEs instead of correlated subqueries, as they can often process data faster by using set operations rather than row-by-row processing.
-
Limit the Number of Columns in Subqueries: Select only the columns you need in subqueries to minimize data retrieval, reduce memory usage, and allow the database to optimize execution.
-
Use EXISTS instead of IN: If a subquery returns a large dataset, using EXISTS rather than IN can improve performance. The EXISTS operator will stop query processing when it finds a matching row, while the IN operator continues to evaluate the entire subquery result.
Avoiding common pitfalls
When you write subqueries incorrectly, you may encounter problems with executing them. Let us look at how to avoid these pitfalls.
-
Avoid Unnecessary Correlated Subqueries: Correlated subqueries are resource-intensive, so avoid using them when the result can be achieved with a non-correlated subquery or a join.
-
Be Mindful of NULL Values in Subqueries: NULL values can lead to unexpected results, especially in subqueries that use comparison operators like IN or =. To avoid errors, consider using COALESCE to handle nulls or ensuring that columns are not nullable if used for comparisons.
-
Avoid Using SELECT * in Subqueries: Using SELECT * can lead to inefficiencies, as it retrieves all columns, even if you don’t need them. This increases memory usage and can slow query execution, especially with large datasets.
-
Use Meaningful Aliases: Clearly name your tables and subqueries to improve readability.
Try out our SQL Server Developer career track, which will equip you with the skills to write, troubleshoot, and optimize your queries using SQL Server.
More Advanced SQL Subquery Techniques
While subqueries offer an efficient way to write complex queries, advanced methods for handling hierarchical data exist. Let's examine the advanced techniques and strategies for applying SQL subqueries.
Recursive subqueries
Recursive subqueries (also known as recursive common table expressions or CTEs) allow you to retrieve hierarchical data, such as organizational structures, product categories, or graph-based relationships, where each item in the data is linked to another.
Suppose you have a table employees with employee_id, manager_id, and employee_name. You want to retrieve the hierarchy of employees under a specific manager.
WITH RECURSIVE EmployeeHierarchy AS (
SELECT employee_id, manager_id, employee_name, 1 AS level
FROM employees
WHERE manager_id IS NULL
UNION ALL
SELECT e.employee_id, e.manager_id, e.employee_name, eh.level + 1
FROM employees e
INNER JOIN EmployeeHierarchy eh ON e.manager_id = eh.employee_id
)
SELECT * FROM EmployeeHierarchy;
In the above query:
-
What I call the Anchor Query selects the top-level manager (where manager_id is NULL).
-
The Recursive Query joins employees with the CTE itself (EmployeeHierarchy), finding employees who report to each previously retrieved employee.
-
The recursion continues until no more employees are reporting to the ones found.
Combining subqueries with other SQL features
You can integrate subqueries with other SQL features like window functions, CASE statements, and grouping functions. These combinations allow for advanced data manipulation and more comprehensive reporting.
Combining subqueries with window functions
Subqueries can be used to refine the dataset that window functions act on, making them useful for ranking, cumulative totals, and moving averages. Suppose you want to rank products by sales within each region. You can use a subquery to select the relevant data and then apply a window function for ranking.
SELECT region, product_id, sales,
RANK() OVER (PARTITION BY region ORDER BY sales DESC) AS sales_rank
FROM (SELECT region, product_id, SUM(sales) AS sales
FROM sales_data
GROUP BY region, product_id) AS regional_sales;
Using subqueries with CASE statements
Combining subqueries with CASE statements can help you apply complex conditions based on dynamic calculations. The following query classifies products as “High”, “Medium”, or “Low” performers based on their sales relative to the average sales for their category.
SELECT product_id, category_id, sales,
CASE
WHEN sales > (SELECT AVG(sales) FROM products WHERE category_id = p.category_id) THEN 'High'
WHEN sales = (SELECT AVG(sales) FROM products WHERE category_id = p.category_id) THEN 'Medium'
ELSE 'Low'
END AS performance
FROM products AS p;
Subqueries with aggregate functions for conditional aggregation
You can also calculate conditional aggregates using subqueries within aggregate functions. Suppose you want to calculate the total revenue generated only by active customers. In the example below, the subquery retrieves all active customers. The main query then filters orders to include only those placed by active customers, calculating the total revenue from this group.
SELECT SUM(order_total) AS active_customer_revenue
FROM orders
WHERE customer_id IN (
SELECT customer_id
FROM customers
WHERE status = 'Active'
);
When SQL Subqueries are Used
SQL subqueries offer versatile real-world applications for data analysis, which is why they are used so frequently. The following are some industry-specific or mathematical applications of SQL subqueries. To come up with these ideas, I tried to think about data analysis or data engineering jobs that require multiple steps, which is, in my opinion, where subqueries really help.
Industry-specific examples
Subqueries can offer useful solutions in finance, healthcare, and retail industries. Here are some ideas:
-
Risk Assessment for Loan Approvals (Finance): I picture banks juggling metrics like debt-to-income ratios and credit scores. By nesting these metrics in subqueries, analysts can make better sense of complicated financial metrics. Maybe, a subquery can calculate the average loan amount for customers within specific income brackets.
-
Identifying Patterns in Patient Diagnoses (Healthcare): In healthcare, managing patient data can be a big job. Subqueries could help break down this complexity. I imagine using subqueries to track diagnosis frequencies across different age groups or risk factors.
-
Optimizing Product Placement Based on Purchase History (Retail): Retailers thrive on understanding purchasing patterns. Subqueries can show nested purchase data to identify which products are often bought together. This could help in strategically placing complementary items and boosting sales.
Mathematical connections
Subqueries are also used to identify data patterns and trends in mathematical and logical connections. The following are some scenarios where subqueries are applied in mathematics.
-
Moving Averages for Time-Series Analysis: When analyzing trends over time, subqueries simplify calculating moving averages. I see them defining specific time windows within nested queries, making it easier to smooth data and spot trends.
-
Detecting Outliers Using Standard Deviations: Spotting outliers is importing for lots of things, including things like fraud detection. Subqueries make it straightforward to compute computed metrics like standard deviations within nested queries.
-
Using Set Theory Concepts: I find it interesting how subqueries mirror set theory operations like UNION and INTERSECT. This capability is perfect for tasks like customer retention analysis, where understanding overlaps and differences between customer groups can drive smarter marketing strategies.
Conclusion
Mastering SQL subqueries can significantly enhance your ability to manage and analyze data efficiently. By understanding their structure, applications, and best practices, you can optimize your SQL queries for better performance. Also, I want to say that mastering subqueries just makes writing SQL easier, so it's worth learning.
If you are interested in becoming a proficient data analyst, check out our Associate Data Analyst in SQL career track to learn the necessary skills. The Reporting in SQL course is also appropriate if you want to learn how to build professional dashboards using SQL. Finally, I recommend obtaining the SQL Associate Certification to demonstrate your mastery of using SQL for data analysis and stand out among other data professionals.





SQL subqueries are a powerful tool in database management, allowing for more complex and efficient data retrieval. This guide will walk you through the fundamentals of SQL subqueries, offering insights into their practical applications and advanced techniques. Whether you're a beginner or an experienced professional, mastering subqueries can significantly enhance your SQL skills.
For those new to SQL, consider starting with our Intermediate SQL course to build a strong foundation. Also, I find the SQL Basics Cheat Sheet, which you can download, is a helpful reference because it has all the most common SQL functions. Finally, I want to say that subqueries are a common SQL interview question, so if you are preparing for an interview, you've come to the right place for a review.
What is a SQL Subquery?
A subquery allows SQL queries to be more modular by handling tasks that would otherwise require multiple separate queries.
Definition and purpose
A SQL subquery is a query nested within another SQL query, used to perform operations that require multiple steps or complex logic. The role of subqueries in SQL include the following:
It sounds like a lot, but it will make sense as we explore these things in the tutorial.
Types of subqueries
It might surprise you to learn that there are different types of subqueries. The different types are grouped based on and suited to different kinds of data retrieval needs. You can choose from the following subqueries depending on the operation you want to perform:
Scalar subqueries
Scalar subqueries return a single value, such as one row and one column. They are often used where a single value is expected, such as in calculations, comparisons, or assignments in
SELECTorWHEREclauses.In the example below, the scalar subquery
(SELECT AVG(salary) FROM employees)returns a single value, the average salary, and compares it to each employee's salary.Column subqueries
Column subqueries return a single column but multiple rows. These subqueries are often used with operators like
INorANY, where the outer query compares values from multiple rows.For example, the subquery below returns a list of department IDs for departments located in New York, which the main query then uses to filter employees in those departments.
Row subqueries
Row subqueries return a single row containing multiple columns. These subqueries are typically used with comparison operators that can compare a row of data, such as the
=orINoperators, when multiple values are expected.The following subquery retrieves a manager's department and job title, and the outer query finds employees with matching values.
Table subqueries (derived tables)
Table subqueries, or derived tables, return a complete table of multiple rows and columns. These are commonly used in the
FROMclause as a temporary table within a query.For example, the subquery below creates a derived table of average salaries by department, which is then used in the outer query to find departments with an average salary above a specified threshold.
Understanding SQL Subqueries
From the above examples, we have seen that a subquery is enclosed within parentheses. Let us now explore the mechanics of a subquery, including its syntax and execution order.
Syntax and structure
The syntax of a subquery varies depending on where it is used in the main SQL statement, such as within
SELECT,FROM, orWHEREclauses. Subqueries are typically enclosed in parentheses( ), indicating a separate query.The following example demonstrates a subquery within a
WHEREclause, allowing us to filter data in the main query based on the results of a nested query.Execution order
The execution order for subqueries depends on whether they are correlated or non-correlated.
Non-correlated subqueries
Non-correlated subqueries are independent of the outer query and execute first. The subquery's result is then passed to the outer query. Non-correlated subqueries are commonly used for scalar or column-level calculations and filters.
The query below follows the execution order:
The subquery
(SELECT AVG(salary) FROM employees)runs first and calculates the average salary.The outer query then retrieves employees whose salary is greater than this average.
I recommend taking DataCamp’s Introduction to SQL Server course to learn more about grouping and data aggregation, and joining tables.
Correlated subqueries
Correlated subqueries depend on the outer query for some of their data, so they are re-evaluated for each row processed by the outer query.
The following query executes in this order:
For each row in
employees(aliased ase1), the subquery(SELECT AVG(e2.salary) FROM employees e2 WHERE e2.department_id = e1.department_id)calculates the average salary for that specific department.The outer query then compares each employee’s salary with the department’s average salary and includes only those who earn more.
Applications of the SQL Subquery
SQL subqueries are important for data retrieval and transformation, allowing you to write complex queries and handle advanced data analysis tasks. The following are real-world applications of subqueries in database management.
Filtering data
Subqueries are useful when filtering data based on dynamic conditions, especially when filtering requires comparing values across multiple tables or performing calculations.
The following subquery retrieves the
category_idof "Product A," and the main query finds all products in that category.Data aggregation
Subqueries are also used for data aggregation, especially when generating summary statistics or insights for reporting and analysis. The subquery
(SELECT department_id, AVG(sales) AS avg_sales FROM sales GROUP BY department_id)calculates the average sales per department. The outer query then filters departments with an average sales above 50,000.Performance Considerations and Best Practices
Although subqueries are powerful when writing complex queries, they may impact performance, especially when working with large datasets. It is important to consider the common pitfalls and best practices for improved performance.
Optimizing subquery performance
Optimizing subquery performance ensures improved query execution time and database responsiveness. The following are ways to optimize the subquery.
Index Relevant Columns: To speed up data retrieval, ensure that columns used in
WHEREandJOINclauses and comparison operations are indexed.Limit the Use of Correlated Subqueries: Where possible, use JOIN operations or CTEs instead of correlated subqueries, as they can often process data faster by using set operations rather than row-by-row processing.
Limit the Number of Columns in Subqueries: Select only the columns you need in subqueries to minimize data retrieval, reduce memory usage, and allow the database to optimize execution.
Use EXISTS instead of IN: If a subquery returns a large dataset, using
EXISTSrather thanINcan improve performance. TheEXISTSoperator will stop query processing when it finds a matching row, while theINoperator continues to evaluate the entire subquery result.Avoiding common pitfalls
When you write subqueries incorrectly, you may encounter problems with executing them. Let us look at how to avoid these pitfalls.
Avoid Unnecessary Correlated Subqueries: Correlated subqueries are resource-intensive, so avoid using them when the result can be achieved with a non-correlated subquery or a join.
Be Mindful of NULL Values in Subqueries:
NULLvalues can lead to unexpected results, especially in subqueries that use comparison operators likeINor=. To avoid errors, consider usingCOALESCEto handle nulls or ensuring that columns are not nullable if used for comparisons.Avoid Using SELECT * in Subqueries: Using
SELECT *can lead to inefficiencies, as it retrieves all columns, even if you don’t need them. This increases memory usage and can slow query execution, especially with large datasets.Use Meaningful Aliases: Clearly name your tables and subqueries to improve readability.
Try out our SQL Server Developer career track, which will equip you with the skills to write, troubleshoot, and optimize your queries using SQL Server.
More Advanced SQL Subquery Techniques
While subqueries offer an efficient way to write complex queries, advanced methods for handling hierarchical data exist. Let's examine the advanced techniques and strategies for applying SQL subqueries.
Recursive subqueries
Recursive subqueries (also known as recursive common table expressions or CTEs) allow you to retrieve hierarchical data, such as organizational structures, product categories, or graph-based relationships, where each item in the data is linked to another.
Suppose you have a table
employeeswithemployee_id,manager_id, andemployee_name. You want to retrieve the hierarchy of employees under a specific manager.In the above query:
What I call the Anchor Query selects the top-level manager (where
manager_idisNULL).The Recursive Query joins
employeeswith the CTE itself (EmployeeHierarchy), finding employees who report to each previously retrieved employee.The recursion continues until no more employees are reporting to the ones found.
Combining subqueries with other SQL features
You can integrate subqueries with other SQL features like window functions,
CASEstatements, and grouping functions. These combinations allow for advanced data manipulation and more comprehensive reporting.Combining subqueries with window functions
Subqueries can be used to refine the dataset that window functions act on, making them useful for ranking, cumulative totals, and moving averages. Suppose you want to rank products by sales within each region. You can use a subquery to select the relevant data and then apply a window function for ranking.
Using subqueries with CASE statements
Combining subqueries with
CASEstatements can help you apply complex conditions based on dynamic calculations. The following query classifies products as “High”, “Medium”, or “Low” performers based on their sales relative to the average sales for their category.Subqueries with aggregate functions for conditional aggregation
You can also calculate conditional aggregates using subqueries within aggregate functions. Suppose you want to calculate the total revenue generated only by active customers. In the example below, the subquery retrieves all active customers. The main query then filters orders to include only those placed by active customers, calculating the total revenue from this group.
When SQL Subqueries are Used
SQL subqueries offer versatile real-world applications for data analysis, which is why they are used so frequently. The following are some industry-specific or mathematical applications of SQL subqueries. To come up with these ideas, I tried to think about data analysis or data engineering jobs that require multiple steps, which is, in my opinion, where subqueries really help.
Industry-specific examples
Subqueries can offer useful solutions in finance, healthcare, and retail industries. Here are some ideas:
Risk Assessment for Loan Approvals (Finance): I picture banks juggling metrics like debt-to-income ratios and credit scores. By nesting these metrics in subqueries, analysts can make better sense of complicated financial metrics. Maybe, a subquery can calculate the average loan amount for customers within specific income brackets.
Identifying Patterns in Patient Diagnoses (Healthcare): In healthcare, managing patient data can be a big job. Subqueries could help break down this complexity. I imagine using subqueries to track diagnosis frequencies across different age groups or risk factors.
Optimizing Product Placement Based on Purchase History (Retail): Retailers thrive on understanding purchasing patterns. Subqueries can show nested purchase data to identify which products are often bought together. This could help in strategically placing complementary items and boosting sales.
Mathematical connections
Subqueries are also used to identify data patterns and trends in mathematical and logical connections. The following are some scenarios where subqueries are applied in mathematics.
Moving Averages for Time-Series Analysis: When analyzing trends over time, subqueries simplify calculating moving averages. I see them defining specific time windows within nested queries, making it easier to smooth data and spot trends.
Detecting Outliers Using Standard Deviations: Spotting outliers is importing for lots of things, including things like fraud detection. Subqueries make it straightforward to compute computed metrics like standard deviations within nested queries.
Using Set Theory Concepts: I find it interesting how subqueries mirror set theory operations like
UNIONandINTERSECT. This capability is perfect for tasks like customer retention analysis, where understanding overlaps and differences between customer groups can drive smarter marketing strategies.Conclusion
Mastering SQL subqueries can significantly enhance your ability to manage and analyze data efficiently. By understanding their structure, applications, and best practices, you can optimize your SQL queries for better performance. Also, I want to say that mastering subqueries just makes writing SQL easier, so it's worth learning.
If you are interested in becoming a proficient data analyst, check out our Associate Data Analyst in SQL career track to learn the necessary skills. The Reporting in SQL course is also appropriate if you want to learn how to build professional dashboards using SQL. Finally, I recommend obtaining the SQL Associate Certification to demonstrate your mastery of using SQL for data analysis and stand out among other data professionals.