

环境配置
在开始之前,先为本教程配置运行环境。
首先,新建一个 Conda 环境:
$ conda create -n langchain python=3.9 -y
$ conda activate langchain安装 LangChain 的包以及其他必要库:
$ pip install langchain langchain_openai langchain_community langgraph ipykernel python-dotenv将新建的 Conda 环境添加为 Jupyter 的一个内核:
$ ipython kernel install --user --name=langchain创建一个 .env 文件以存储 API 密钥等机密信息:
$ touch .env
$ vim .env # Paste your OPENAI keyOPENAI_API_KEY='YOUR_KEY_HERE'从 .env 文件中读取您的 OpenAI API 密钥:
import os
from dotenv import load_dotenv
load_dotenv()
api_key = os.getenv('OPENAI_API_KEY')通过查询 OpenAI 的 GPT-3.5(默认语言模型)来测试是否一切正常:
from langchain_openai import OpenAI
llm = OpenAI(openai_api_key=api_key)
question = "Is Messi the best footballer of all time?"
output = llm.invoke(question)
print(output[:75])There is no definitive answer to this question, as it is subjective and de好了,现在可以开始了。
什么是 LangChain 代理?
先来思考一下代理框架。我们将重点比较它与传统链式(chain)范式的不同,以及代理由哪些组件构成。理解为何需要采用一种新的应用构建方式,将有助于我们随后的编码实践。
链(Chains)与代理(Agents)
代理的决定性特征,是它能在给定一组工具的前提下,选择解决问题的最佳动作顺序。
例如,假设我们有以下这些工具:
- 天气 API
- 服装推荐的机器学习模型
- 用于骑行路线的 Strava API
- 用户偏好数据库
- 图像识别模型
- 语言模型(文本生成)
传统的解题方式会从列表中选用若干工具组成一条链:
链 1:基于天气的穿搭推荐器
- 调用天气 API
- 将天气数据输入服装 ML 模型
- 生成穿搭建议
- 将结果展示给用户
链 2:基于天气的骑行路线建议器
- 调用天气 API
- 调用 Strava API 获取热门路线
- 根据天气条件筛选路线
- 将合适的路线展示给用户
链 3:穿搭照片分析器
- 接收用户的穿搭照片
- 使用图像识别模型识别服饰单品
- 与用户偏好数据库比对
- 使用文本生成模型生成反馈
- 将分析结果展示给用户
每条链都用预先设定的步骤序列和可用工具子集解决一个特定问题。它们无法超出既定范围进行适配。此外,这意味着需要三条独立的开发分支,既耗时又耗资源。
现在,想象一个可同时访问上述全部工具的代理系统。它将能够:
- 理解用户的查询或问题(通过语言模型进行自然语言理解)
- 判断哪些工具与问题相关(推理)
- 动态创建使用最合适工具的工作流
- 执行该工作流,并在需要时实时调整(行动)
- 评估结果,并从过往交互中学习
例如,如果用户问:“今天骑车该穿什么?”代理可能会先查看天气 API,通过 Strava 分析合适的骑行路线,在结合用户过往偏好后推荐相应穿搭,并生成一条个性化回复。
该代理可以:
- 用同一组工具处理各种不同问题
- 为每个独特情境创建定制工作流
- 根据具体语境与用户需求调整处理方式
- 通过交互学习以提升未来表现
LangChain 的一大用处在于,它能将仅能产出文本的语言模型,转变为能利用可用资源采取恰当行动的推理引擎。简而言之,LangChain 让我们能开发出与外界交互的强大自治代理。
关键组件
一个 LangChain 代理由多个组件组成,如聊天模型、提示模板、外部工具和其他相关结构。要构建成功的代理,我们需要回顾每个组件并理解其用途。
语言与聊天模型
创建 LangChain 代理涉及很多环节。首先也是最显而易见的就是语言模型。
from langchain_openai import OpenAI
llm = OpenAI(api_key=api_key, model="gpt-3.5-turbo-instruct")
question = "What is special about the number 73?"
output = llm.invoke(question)
print(output[:100])1. Prime Number: 73 is a prime number, which means it is only divisible by 1 and itself. This make语言模型(如 OpenAI 的 GPT-3.5 Turbo)以字符串为输入并生成字符串。它们通常较早期,适合回答单次用户查询。
更新、更强大的模型通常是聊天模型,它们以消息序列为输入并返回聊天消息作为输出(而非纯文本):
from langchain_openai import ChatOpenAI
from langchain_core.messages import HumanMessage, AIMessageChunk, SystemMessage
# Initialize the model
chat_model = ChatOpenAI(api_key=api_key, model='gpt-4o-mini')
# Write the messages
messages = [SystemMessage(content='You are a grumpy pirate.'),
HumanMessage(content="What's up?")]
output = chat_model.invoke(messages)换言之,聊天模型允许我们以自然语言进行对话。在上面的示例中,我们用系统消息加上一条用户提问来初始化 GPT-4o-mini。请注意 SystemMessage 和 HumanMessage 这两个类的用法。
上述 output 是一个消息对象,这正是聊天模型的预期行为:
type(output)langchain_core.messages.ai.AIMessageprint(output.content)Arrr, not much but the sound of waves and the creakin' of me ship. What do ye want? Make it quick, I've got treasure to hunt and rum to drink!此外,它们还会返回其他可通过点号访问的有用元数据:
output.dict(){'content': "Arrr, not much but the sound of waves and the creakin' of me ship. What do ye want? Make it quick, I've got treasure to hunt and rum to drink!",
'additional_kwargs': {},
'response_metadata': {'token_usage': {'completion_tokens': 38,
'prompt_tokens': 21,
'total_tokens': 59},
'model_name': 'gpt-4o-mini-2024-07-18',
'system_fingerprint': 'fp_48196bc67a',
'finish_reason': 'stop',
'logprobs': None},
'type': 'ai',
'name': None,
'id': 'run-fde829bf-8f5f-4926-a1ed-ab53609ce03a-0',
'example': False,
'tool_calls': [],
'invalid_tool_calls': [],
'usage_metadata': {'input_tokens': 21,
'output_tokens': 38,
'total_tokens': 59}}大多数代理使用聊天模型,因为它们的知识库更新且具备对话能力。不过,对于不需要记忆的简单代理,GPT-3.5 这类语言模型也足够。
提示模板
查询语言或聊天模型的最高效方式是使用提示模板(prompt templates)。它们能让您以一致的结构组织查询,并动态插入变量,使与模型的交互更灵活、可复用。
在 LangChain 中,提示模板有多种类型,最基础的是 PromptTemplate 类。它可搭配语言(纯文本)模型使用:
from langchain_core.prompts import PromptTemplate
query_template = "Tell me about {book_name} by {author}."
prompt = PromptTemplate(input_variables=["book_name", "author"], template=query_template)
prompt.invoke({"book_name": "Song of Ice and Fire", "author": "GRRM"})StringPromptValue(text='Tell me about Song of Ice and Fire by GRRM.')该类要求您先创建包含变量占位符的字符串(使用花括号语法)。然后将该模板字符串与变量名一起传入 PromptTemplate 类,以构建您的提示。
使用变量值调用 .invoke() 将展示提示实际传给模型的样子。
将该提示模板传给语言模型,需要用管道操作符将其连接起来:
from langchain_openai import OpenAI
llm = OpenAI(api_key=api_key)
# Create a chain
chain = prompt | llm
# Invoke the chain
output = chain.invoke({"book_name": "Deathly Hallows", "author": "J.K. Rowling"})
print(output[:100])Deathly Hallows is the seventh and final book in the popular Harry Potter series, written by J.K. R管道操作符(|)属于 LangChain 表达式语言(LCEL)的一部分,专为将多个 LangChain 组件与工具串联而设计。
type(chain)langchain_core.runnables.base.RunnableSequence当您对 LangChain 对象使用管道操作符时,会创建一个 RunnableSequence 实例。可运行序列代表一串都支持 .invoke() 方法的对象,如提示模板与语言/聊天模型。
接下来,看看用于聊天模型的另一种提示模板类:
from langchain_core.prompts import ChatPromptTemplate我们提到,聊天模型需要一串消息作为输入。最初的输入通常是系统提示,用于告诉聊天模型应如何表现。因此,使用 ChatPromptTemplate 类,我们可以很容易地创建不同“人设”的聊天模型:
chat_model = ChatOpenAI(api_key=api_key, model="gpt-4o-mini")
template = ChatPromptTemplate([
('system', 'You are a helpful AI bot. Your specialty is {specialty}.'),
('human', 'Explain the concept of {concept} based on your expertise.')
])该类需要一组基于角色的消息作为输入。列表中的每个成员都必须是一个(角色,消息)二元组,并在需要的地方定义变量占位符。
准备好后,我们可以用同样的管道操作符创建具有不同行为的聊天模型:
specialties = ["psychology", "economics", "politics"]
concept = "time"
# Call the model with different personalities
for s in specialties:
chain = template | chat_model
output = chain.invoke({"specialty": s, "concept": concept})
print(output.content[:100], end="\n" + "-" * 25 + '\n')Time is a complex and multifaceted concept that has been explored from various perspectives, includi
-------------------------
In economics, the concept of time is multifaceted and plays a crucial role in various theories and m
-------------------------
While my primary focus is on politics, I can provide a brief overview of the concept of time as it m
-------------------------工具(Tools)
上一节提到,代理可以在 LLM 的推理能力支持下,自主选择组合手头的工具来解决具体问题。
LangChain 提供与众多流行 API 与服务的集成,让代理能够与外部世界交互。大多数集成都位于 langchain_community 包中,部分位于 langchain_core 内。
例如,下面演示如何使用 ArXiv 工具检索不同主题的论文摘要:
!pip install -Uq arxiv # Install arXiv Python SDKfrom langchain_community.tools import ArxivQueryRun
tool = ArxivQueryRun()
print(tool.invoke('Photosynthesis')[:250])Published: 2019-08-28
Title: Photosynthesis on Exoplanets and Exomoons from Reflected Light
Authors: Manasvi Lingam, Abraham Loeb
Summary: Photosynthesis offers a convenient means of sustaining biospheres. We
quantify the constraints for photosynthes还有一种不是按类名导入的加载工具方式:
from langchain_community.agent_toolkits.load_tools import load_tools
tools = load_tools(["arxiv", "dalle-image-generator"])上面我们用 load_tools() 函数一次性加载了 arXiv 和 Dall-E 图像生成工具。通过该函数加载的工具,使用语法一致:
# Call arXiv
print(tools[0].invoke("Kaggle")[:150])Published: 2020-06-06
Title: StackOverflow vs Kaggle: A Study of Developer Discussions About Data Science
Authors: David Hin
Summary: Software develop# Generate an image with DallE
output_image_url = tools[1].invoke("A magnificent chain in a cartoon.")
output_image_url'https://oaidalleapiprodscus.blob.core.windows.net/...'
函数 load_tools 要求您知道工具类对应的字符串名称,例如 ArxivQueryRun 对应 “arxiv”。您可以通过运行 get_all_tool_names 函数快速查看任意工具的字符串名称:
from langchain_community.agent_toolkits.load_tools import get_all_tool_names
get_all_tool_names()[:10]['sleep',
'wolfram-alpha',
'google-search',
'google-search-results-json',
'searx-search-results-json',
'bing-search',
'metaphor-search',
'ddg-search',
'google-lens',
'google-serper']请注意,load_tools() 只是一个便捷函数。在构建代理时,推荐使用工具的类构造函数进行加载,以便根据具体行为进行配置。
构建 LangChain 代理的分步流程
最后,本节将基于前文所学,逐步演示如何创建 LangChain 代理。
在接下来的示例中,我们将构建一个能通过三种媒介解释任意主题的代理:文本、图像或视频。更具体地说,代理会根据所提问题决定采用何种格式进行解释。
让我们开始吧。别忘了参考文章开头的环境配置部分。
1. 定义工具
在配置好环境后,第一步是定义要提供给代理的工具。先导入它们:
from langchain_community.tools import WikipediaQueryRun # pip install wikipedia
from langchain_community.utilities import WikipediaAPIWrapper
from langchain_community.tools import YouTubeSearchTool # pip install youtube_search
from langchain_community.tools.openai_dalle_image_generation import (
OpenAIDALLEImageGenerationTool
)
from langchain_community.utilities.dalle_image_generator import DallEAPIWrapper这里我们导入了五个类:
WikipediaAPIWrapper:配置访问 Wikipedia API 的方式WikipediaQueryRun:生成 Wikipedia 页面摘要YouTubeSearchTool:搜索某主题的 YouTube 视频DallEAPIWrapper:配置访问 OpenAI 的 DallE 端点OpenAIDALLEImageGenerationTool:使用提示生成图像
当用户向我们的代理发出查询时,它会决定是用 Wikipedia 文章以文本形式解释,还是用 Dall-E 生成图像以辅助理解,或是推荐 YouTube 视频以更深入地学习。
先从 Wikipedia 工具开始初始化:
wiki_api_wrapper = WikipediaAPIWrapper(top_k_results=1, doc_content_chars_max=250)
wikipedia = WikipediaQueryRun(description="A tool to explain things in text format. Use this tool if you think the user’s asked concept is best explained through text.", api_wrapper=wiki_api_wrapper)
print(wikipedia.invoke("Mobius strip"))Page: Möbius strip
Summary: In mathematics, a Möbius strip, Möbius band, or Möbius loop is a surface that can be formed by attaching the ends of a strip of paper together with a half-twist. As a mathematical object, it was discovered by Johann BenediDallE 图像生成器:
dalle_api_wrapper = DallEAPIWrapper(model="dall-e-3", size="1792x1024")
dalle = OpenAIDALLEImageGenerationTool(
api_wrapper=dalle_api_wrapper, description="A tool to generate images. Use this tool if you think the user’s asked concept is best explained through an image."
)
output = dalle.invoke("A mountain bike illustration.")
print(output)
YouTube 搜索工具:
youtube = YouTubeSearchTool(
description="A tool to search YouTube videos. Use this tool if you think the user’s asked concept can be best explained by watching a video."
)
youtube.run("Oiling a bike's chain")"['https://www.youtube.com/watch?v=X1Vze17bhgk&pp=ygUVT2lsaW5nIGEgYmlrZSdzIGNoYWlu', 'https://www.youtube.com/watch?v=T6xyn1FGHiU&pp=ygUVT2lsaW5nIGEgYmlrZSdzIGNoYWlu']"特别注意工具描述。代理会根据您给出的描述来决定使用哪一个工具。
现在,将这些工具放进一个列表:
tools = [wikipedia, dalle, youtube]无需创建代理,我们已经可以将这组工具绑定到一个聊天模型上:
chat_model = ChatOpenAI(api_key=api_key)
model_with_tools = chat_model.bind_tools(tools)试着用一条简单消息调用该模型:
response = model_with_tools.invoke([HumanMessage("What's up?!")])
print(f"Text response: {response.content}")
print(f"Tools used in the response: {response.tool_calls}")Text response: Hello! How can I assist you today?
Tools used in the response: []输出显示,在生成答案时并未使用任何已绑定的工具。现在问一个更具体的问题,迫使模型超出其训练数据去“看一看”:
response = model_with_tools.invoke([
HumanMessage("Can you generate an image of a mountain bike?")
])
print(f"Text response: {response.content}")
print(f"Tools used in the response: {response.tool_calls}")Text response:
Tools used in the response: [{'name': 'openai_dalle', 'args': {'query': 'mountain bike'}, 'id': 'call_92GBfmsYtPi9TpGuIOFB1pG8', 'type': 'tool_call'}]可以看到没有文本输出,但出现了对 OpenAI 的 DallE 的提及。此时工具并未实际被调用;模型只是建议使用它。若要真正调用——也就是采取行动,我们需要创建一个代理。
2. 创建一个简单代理
在定义好模型与工具后,开始创建代理。LangChain 通过其 langgraph 包提供了一个高级的 create_react_agent() 函数接口,可快速创建 ReAct(推理并行动)代理:
from langgraph.prebuilt import create_react_agent
system_prompt = SystemMessage("You are a helpful bot named Chandler.")
agent = create_react_agent(chat_model, tools, state_modifier=system_prompt)在用聊天模型和工具列表初始化代理的同时,我们传入系统提示,指示模型的一般行为。现在它已经可以接受查询了:
from pprint import pprint
response = agent.invoke({"messages": HumanMessage("What's up?")})
pprint(response["messages"])[HumanMessage(content="What's up?", id='133b9380-cfe1-495a-98f7-b835c874bd57'),
AIMessage(content='Hello! How can I assist you today?', response_metadata={'token_usage': {'completion_tokens': 10, 'prompt_tokens': 112, 'total_tokens': 122}, 'model_name': 'gpt-3.5-turbo-0125', 'system_fingerprint': None, 'finish_reason': 'stop', 'logprobs': None}, id='run-0a920c15-39b4-4857-ab51-6ea905575dba-0', usage_metadata={'input_tokens': 112, 'output_tokens': 10, 'total_tokens': 122})]我们收到了一个合理的回复:简单的文本答案,没有调用工具。现在问得更具体一点:
response = agent.invoke({"messages": [
HumanMessage('Explain how photosynthesis works.')
]})
print(len(response['messages']))4这次有四条消息。我们看看它们的消息类名及内容:
for message in response['messages']:
print(
f"{message.__class__.__name__}: {message.content}"
) # Print message class name and its content
print("-" * 20, end="\n")HumanMessage: Explain how photosynthesis works.
--------------------
AIMessage:
--------------------
ToolMessage: Page: Photosynthesis
Summary: Photosynthesis ( FOH-tə-SINTH-ə-sis) is a system of biological processes by which photosynthetic organisms, such as most plants, algae, and cyanobacteria, convert light energy, typically from sunlight, into the chemical
--------------------
AIMessage: Photosynthesis is a biological process where photosynthetic organisms like plants, algae, and cyanobacteria convert light energy, usually from sunlight, into chemical energy. This process involves capturing light energy through pigments like chlorophyll in plant cells and using it to convert carbon dioxide and water into glucose and oxygen. Glucose serves as a source of energy for the plant, while oxygen is released into the atmosphere as a byproduct. Photosynthesis is crucial for the survival of plants and the balance of oxygen and carbon dioxide in the atmosphere.
--------------------就是它!第三条消息来自工具调用,即关于光合作用的 Wikipedia 页面摘要。最后一条消息由聊天模型生成,并在构建答案时利用了工具调用的内容。
我们快速写一个函数,将刚才的步骤模块化:
def execute(agent, query):
response = agent.invoke({'messages': [HumanMessage(query)]})
for message in response['messages']:
print(
f"{message.__class__.__name__}: {message.content}"
) # Print message class name and its content
print("-" * 20, end="\n")
return response3. 优化系统提示
现在,用更详细的指令更新系统提示,说明代理应如何行为:
system_prompt = SystemMessage(
"""
You are a helpful bot named Chandler. Your task is to explain topics
asked by the user via three mediums: text, image or video.
If the asked topic is best explained in text format, use the Wikipedia tool.
If the topic is best explained by showing a picture of it, generate an image
of the topic using Dall-E image generator and print the image URL.
Finally, if video is the best medium to explain the topic, conduct a YouTube search on it
and return found video links.
"""
)使用新的系统提示,重新创建代理:
agent = create_react_agent(chat_model, tools, state_modifier=system_prompt)
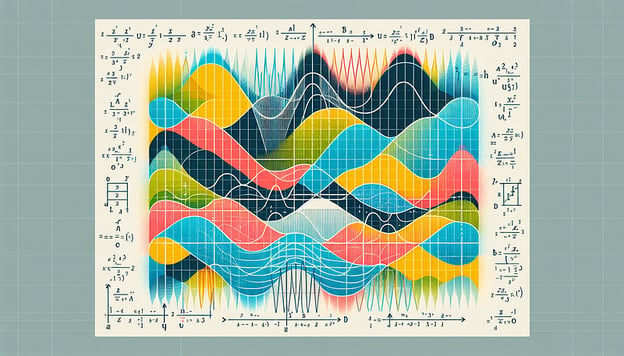
response = execute(agent, query='Explain the Fourier Series visually.')HumanMessage: Explain the Fourier Series visually.
--------------------
AIMessage:
--------------------
ToolMessage: https://oaidalleapiprodscus.blob.core.windows.net/private/org-qRwX4bsgcnaYHHwbxFBdZxUy/user-LOXQPflMtXxamV72hac9oS2O/img-iY3gXXBzWapRWKdmkd9cXEIN.png?st=2024-08-09T18%3A36%3A46Z&se=2024-08-09T20%3A36%3A46Z&sp=r&sv=2024-08-04&sr=b&rscd=inline&rsct=image/png&skoid=d505667d-d6c1-4a0a-bac7-5c84a87759f8&sktid=a48cca56-e6da-484e-a814-9c849652bcb3&skt=2024-08-09T17%3A56%3A46Z&ske=2024-08-10T17%3A56%3A46Z&sks=b&skv=2024-08-04&sig=Ly8F4jvakFeEtpZ/6jMliLq%2BG3Xs%2Bz1AmX1sL06%2BQ3U%3D
--------------------
AIMessage: Here is a visual representation of the Fourier Series:

The Fourier Series is a way to represent a function as the sum of simple sine waves. It is used in many areas of mathematics and physics to analyze and understand periodic phenomena.
--------------------很棒。基于我们的信息(相当明确 :)),代理选择了正确的工具。下面是生成的图像:
4. 为代理添加记忆
目前我们的代理是无状态的,也就是说它不会记住先前的交互:
response = execute(agent, query="What did I ask you in the previous query?")HumanMessage: What did I ask you in the previous query?
--------------------
AIMessage: I'm sorry, I cannot remember the previous query as I don't have access to the conversation history. How can I assist you today?
--------------------为代理添加聊天历史最简单的方式,是使用 langgraph 的 SqliteSaver 类:
from langgraph.checkpoint.sqlite import SqliteSaver
memory = SqliteSaver.from_conn_string(':agent_history:')
agent = create_react_agent(chat_model, tools, checkpointer=memory, state_modifier=system_prompt)我们使用 SqliteSaver 类的 .from_conn_string() 方法初始化内存,这会创建一个数据库文件。然后将 memory 传给 create_react_agent() 的 checkpointer 参数。
接下来,我们需要创建一个配置字典:
config = {'configurable': {'thread_id': 'a1b2c3'}}该字典定义了一个线程 ID,用来区分不同会话,需要在调用代理的 .invoke() 方法时传入。因此我们更新 execute() 函数以包含此行为:
def execute(agent, query, thread_id="a1b2c3"):
config = {"configurable": {"thread_id": thread_id}}
response = agent.invoke({'messages': [HumanMessage(query)]}, config=config)
for message in response["messages"]:
print(
f"{message.__class__.__name__}: {message.content}"
) # Print message class name and its content
print("-" * 20, end="\n")
return response
Let’s test it again:
response = execute(
agent, query="Explain how to oil a bike's chain using a YouTube video", thread_id="123"
)HumanMessage: Explain how to oil a bike's chain using a YouTube video
--------------------
AIMessage:
--------------------
ToolMessage: ['https://www.youtube.com/watch?v=X1Vze17bhgk&pp=ygUXaG93IHRvIG9pbCBhIGJpa2UgY2hhaW4%3D', 'https://www.youtube.com/watch?v=ubKCHtZ20-0&pp=ygUXaG93IHRvIG9pbCBhIGJpa2UgY2hhaW4%3D']
--------------------
AIMessage: I found a couple of YouTube videos that explain how to oil a bike chain:
1. [Video 1: How to oil a bike chain](https://www.youtube.com/watch?v=X1Vze17bhgk&pp=ygUXaG93IHRvIG9pbCBhIGJpa2UgY2hhaW4%3D)
2. [Video 2: Step-by-step guide on oiling a bike chain](https://www.youtube.com/watch?v=ubKCHtZ20-0&pp=ygUXaG93IHRvIG9pbCBhIGJpa2UgY2hhaW4%3D)
You can watch these videos to learn how to oil your bike's chain effectively.
--------------------现在,来向代理询问此前的查询:
response = execute(agent, query='What have I asked you so far?', thread_id='123')
print(response){'messages': [HumanMessage(content="Explain how to oil a bike's chain using a YouTube video", id='8254142b-fb77-4958-8ad9-0a0283c6611a'), ...
]不出所料,代理返回了先前的消息!现在只差一个类似 ChatGPT 的聊天界面,我们就拥有了一个自定义聊天机器人。
未来趋势与发展
在整篇文章中,我们一窥 LangChain 在代理方面的发展方向。直到最近,LangChain 主要使用 AgentExecutor 类,但它正逐步被 langgraph 代理所取代。
纯 LangChain 代理适合入门,但要构建相同的代理,所需代码行数比在 LangGraph 中更多。而且达到一定复杂度后,AgentExecutor 框架将无法提供像 LangGraph 那样,用于构建复杂多工具代理的灵活性。
因此,现在正是顺势而为、 直接上手 LangGraph 的好时机。
我们也强烈建议开始 使用 LangSmith,它已经成为 LangChain 生态中构建生产级 LLM 应用的核心部分。其主要优势包括:
- 调试:LangSmith 提供代理执行的详细追踪,便于定位并修复问题。
- 性能优化:借助 LangSmith,您可以分析 token 使用、延迟及其他性能指标,以优化代理效率。
- 测试与评估:LangSmith 方便创建和管理测试数据集,帮助您在多种场景下严格评估代理表现。
- 监控:在生产环境中,LangSmith 提供实时监控功能,使您能够快速跟踪代理性能并发现异常。
以下是开始使用 LangSmith 的方式:
- 注册一个免费的账户 here。
- 设置环境变量。
export LANGCHAIN_TRACING_V2="true"
export LANGCHAIN_API_KEY="..."
一切就绪!当您开始查询语言/聊天模型时,LangSmith 会开始记录每次运行的各类指标:

结语
本文探讨了是什么让 LangChain 代理有别于链,以及构建它们所用的重要积木。我们首先介绍了什么是代理,以及它们在灵活性与决策能力方面如何区别于更传统的链式结构。
随后,我们了解了构建代理必须掌握的关键组件:聊天模型、工具与提示模板。最后,我们通过两个示例演示了如何构建简单与进阶代理。自然语言处理持续发展,而 LangChain 代理正站在这一进程的前沿,为更智能、更通用的一代 AI 铺路。
以下资源可帮助您进一步提升对 LangChain 的掌握:
- Developing LLM Applications with LangChain 课程
- LangChain 提示工程入门
- 如何用 LangChain 构建 LLM 应用教程
- 使用 LangChain 工具构建具备浏览能力的 GPT 模型
- LangChain 与 LlamaIndex:详细对比
感谢您的阅读!

我是一名数据科学内容创作者,拥有超过 2 年的经验,并在 Medium 上拥有较大的读者群。我喜欢用略带讽刺的笔调撰写有关 AI 和机器学习的深度文章——毕竟总得想点办法让这些内容不那么枯燥。我已发表 130 多篇文章,并制作了一门 DataCamp 课程,另有一门正在筹备中。我的内容已被超过 500 万人次阅读,其中有 2 万人在 Medium 和 LinkedIn 上成为关注者。
LangChain 在 GitHub 上的 9 万星就是最好的背书——它是当前构建基于 LLM 应用最火的框架。其完善的工具与组件集合,几乎可以用任何 LLM 搭建端到端的 AI 解决方案。
也许 LangChain 能力的核心就是 LangChain 代理(agents)。它们是自治或半自治的工具,能够执行任务、做出决策,并与其他工具和 API 交互。这代表着用 LLM 自动化复杂工作流的一大飞跃。
在本文中,您将学习如何构建自己的 LangChain 代理,执行一些当今聊天应用(如 ChatGPT)并不严格支持的任务。