

范围与目标
本文介绍 LangChain Tools 的基础知识以及如何在 Python 中使用它们。我们将使用已安装 openai 和 langchain 库的 Jupyter Notebook。如果您想先了解 LangChain 框架,强烈推荐阅读文章 Introduction to LangChain for Data Engineering & Data Applications。
在本教程中,我们将学习如何利用现有的四个 LangChain 工具,为默认的 GPT 模型提供多种可供查阅的外部来源。具体来说,我们将探索使用以下来源的工具:
- 两个知名搜索引擎:Google SERP 和 DuckDuckGo 搜索。
- Wikipedia,作为一个全面且广为认可的信息数据库。
- YouTube 来源,以便模型提供视频建议。
设置好这些工具后,我们将掌握如何通用地使用任意 LangChain 工具,以及如何将它们组合成一个工具包,为模型提供浏览能力。
LangChain Tools 简介
如前言所述,LangChain Tools 可以通过使模型在回应用户提示时查阅外部来源来增强其能力。这些工具在一种称为 ReAct 提示的技术中非常重要。ReAct 是 Reasoning 和 Acting 的缩写,将模型的处理分为两个阶段:
- 推理阶段:在此阶段,模型会花时间思考获得答案的最佳策略。
- 行动阶段:在这里,模型执行上一阶段制定的计划,以获得实际的答案。
这一过程会生成推理轨迹,能够引导模型本身走向正确的答案。研究显示,该技术有助于大型语言模型(LLM)在知识密集型与决策类任务中获得更准确、可靠的结果,部分原因在于它让模型有了更多“思考时间”。
LangChain Tools 还能通过提供互补的信息来源来进一步增强 ReAct 提示技术。在我们的方案中,推理阶段涉及模型根据用户查询决定使用哪种工具;与此同时,行动阶段将使模型与所选外部来源进行交互以收集补充信息。
如果您想深入了解使用 Langchain 的 ReAct 提示,请阅读文章 ChatGPT ReAct Prompting!
用于 ReAct 提示的 LangChain 组成
在 LangChain 框架中,有两个重要元素可用于这一提示技术:Agents(智能体)和Tools(工具)。
所谓智能体,是负责执行实际推理和行动阶段的实体。它们将结果反馈给模型,使 LLM 能够用自然语言生成包含额外信息的回答。智能体有多种类型,可适配您希望 LLM 执行的不同任务。官方 LangChain 文档的 Agents 中提供了不同类型智能体的详细概述。
工具已经是我们讨论的重点。从技术上讲,工具是智能体可以调用的函数。LangChain 提供了种类繁多的工具,如 Google 实用工具(例如 Search、Drive 和 Scholar)、Wikipedia 搜索、ArXiV 数据库、Shell 扩展以及原生 ChatGPT 插件等。本文将认识其中四个。完整列表请参见官方 LangChain 的Tools。
LangChain Tools 实战
让我们上手实践!
设置 OpenAI 环境
与其他使用 GPT 模型的项目一样,第一步是将 OpenAI API 密钥加载到我们的环境中。为此,我们将使用 os 和 openai 模块。
import openai
import os
os.environ["OPENAI_API_KEY"] = os.getenv("OPENAI_API_KEY")如果您还没有 OpenAI API 密钥,请阅读这篇文章:A Beginner’s Guide to the OpenAI API!
由于我们将使用 LangChain 框架,还需要从 langchain 库加载实际的 gpt 模型:
from langchain.llms.openai import OpenAI
llm = OpenAI(model_name="gpt-3.5-turbo")此处我们使用 gpt-3.5-turbo 作为零成本选项,但您也可以选择其他任意偏好的模型。
接下来的部分,我们将学习如何设置第一个工具。我们以 DuckDuckGo 搜索工具为例,但您会发现所有工具的上手步骤都相同!
设置我们的第一个 LangChain 工具:DuckDuckGo
DuckDuckGo 是一款强调保护用户隐私的搜索引擎。与某些其他搜索引擎不同,DuckDuckGo 不会跟踪用户的搜索历史,这意味着它不会创建或维护用户的个人画像。
它有一个 Python 库,使用该搜索引擎前需先安装。可以通过 pip 安装:
!pip install duckduckgo-search此外,我们需要从 langchain 库中导入 DuckDuckGo 工具:
from langchain.tools import DuckDuckGoSearchRun
ddg_search = DuckDuckGoSearchRun()
DuckDuckGoSearchRun() 方法本身已经可以在不对接任何 LLM 的情况下进行网页浏览。让我们看个简单示例:
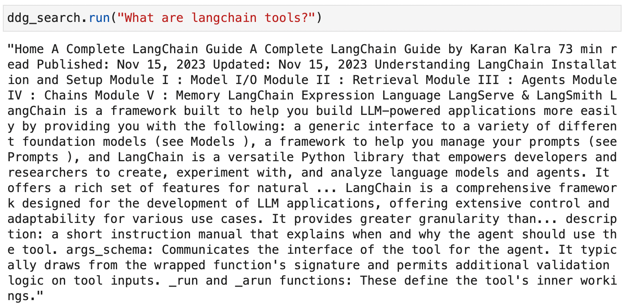
使用 DuckDuckGo 进行网络浏览时 ddg_search.run() 的执行截图
工具背后的理念是将这种浏览能力整合进 LLM 中,这样我们就能获得连贯的自然语言回答,而不是只返回原始信息片段。为此,我们需要将该方法封装到 langchain 的 Tool 类实例中,如下所示:
from langchain.agents import Tool
tools = [
Tool(
name="DuckDuckGo Search",
func=ddg_search.run,
description="Useful to browse information from the Internet.",
)
]
任何工具都需要一个名称(name),LangChain 智能体会用它来引用该工具;一个函数(func),智能体可以调用它来查阅外部来源(如上所示的 ddg_search.run);以及一个描述(description),用于向智能体说明何时使用它。
在此示例中,我们选择了如下描述:“Useful to browse information from the Internet”。工具定义中还有更多可选参数,您可根据需要自定义。
探索其他浏览工具
学会设置第一个工具后,其他工具的配置就很简单了,因为它们都遵循相同的结构。
Google Serper 工具
Google Serper 是一种低成本的 Google Search API,允许我们像使用 DuckDuckGo 一样浏览互联网。
使用该工具需要一个 API 密钥,注册 https://serper.dev/ 的免费账户即可获得。
Google Serper API 主页截图。
进入 Serper 账户后,您应该能在左侧面板看到 API key 选项:
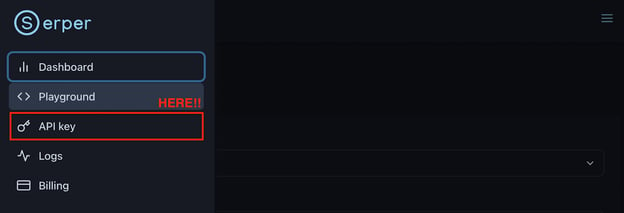
Google Serper API 账户页面截图。左侧面板的 API key 选项。
点击即可获得 API 密钥,方便复制并集成到我们的 Python 脚本中:
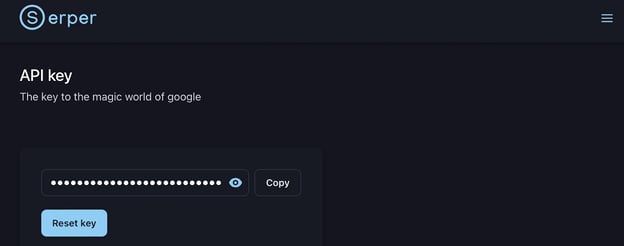
Google Serper 页面生成 API key 的截图。
回到代码,我们可以轻松将密钥导入环境:
serper_api_key = os.environ["SERPER_API_KEY"]要使用 Google Serper API,我们需要先安装所需的 Python 库(pip install google-serp-api)。此外,还需从 langchain 库中导入 GoogleSerper 工具:
from langchain.utilities import GoogleSerperAPIWrapper
google_search = GoogleSerperAPIWrapper()与前面的情况类似,google_search.run() 也是一个可独立进行网页浏览的方法。不过,我们的目标仍是将其集成为一个 LangChain 工具,如下所示:
tools.append(
Tool(
name="Google Search",
func=google_search.run,
description="Useful to search in Google. Use by default.",
)
)
请注意,这里我们向 tools 列表追加了一个新工具。因此,tools 列表现在包含了两个搜索引擎。
Wikipedia 工具
让我们用知名的 Wikipedia 来源来补充工具集,流程与前述工具相同。
第一步是通过 pip 安装 wikipedia Python 库(pip install wikipedia),并从 LangChain 库中加载所需模块。由于 Wikipedia API 的架构,该工具实际上需要两个模块:
from langchain.tools import WikipediaQueryRun
from langchain.utilities import WikipediaAPIWrapper
wikipedia = WikipediaQueryRun(api_wrapper=WikipediaAPIWrapper())最后,我们可以追加一个 Tool 类的新实例,其函数运行 wikipedia.run() 方法:
tools.append(
Tool(
name="Wikipedia Search",
func=wikipedia.run,
description="Useful when users request biographies or historical moments.",
)
)
YouTube 工具
最后,我认为集成 YouTube 来源也很有趣,这样模型除了文本外还能以视频形式进行反馈。按照之前相同的流程:
!pip install youtube
from langchain.tools import YouTubeSearchTool
youtube = YouTubeSearchTool()
tools.append(
Tool(
name="Youtube Search",
func=youtube.run,
description="Useful for when the user explicitly asks you to look on Youtube.",
)
)
现在我们就绪了!
我们构建了一个工具包(tools 列表),其中包含四个为模型提供浏览能力的工具。不过,目前我们还没有与模型交互。
让我们看看它如何使用这些来源!
测试浏览能力
如前所述,所谓的智能体是负责使用工具的实体。因此,我们也需要从 langchain 库中导入它们:
from langchain.agents import initialize_agentinitialize_agent 方法可帮助我们设置智能体:
agent = initialize_agent(
tools, llm, agent="zero-shot-react-description", verbose=True
)
从初始化可以看到,我们需要为智能体提供可用工具列表(tools)、要使用的 LLM(llm)以及智能体的类型(agent="zero-shot-react-description")。在本例中,我们将使用Zero-shot ReAct 智能体类型,作为最通用的行动型智能体。此外,我们将 verbose=True,以观察智能体的推理过程。
初始化智能体后,我们可以使用 agent.run() 方法运行任意用户提示。
示例 1:传记
原则上,一旦我们提交用户提示,智能体会分析工具的描述,并选择最适合该用例的工具。此外,如果使用所选工具未找到合适信息,智能体仍会回退到其他工具。
让我们先运行一个请求传记的测试。在这种情况下,我们为传记与历史事件配置了合适的工具,因此预期智能体会选择相应工具:
agent.run(
"Harry Styles biography"
)
我们可以观察到其推理过程:
> Entering new AgentExecutor chain...
I should look for a biography of the singer
Action: Wikipedia Search
Action Input: Harry Styles biography
Observation:
Page: Harry Styles
Summary: Harry Edward Styles (born 1 February 1994) is an English singer. His musical career began in 2010 as part of One Direction, a boy band formed on the British music competition series The X Factor after each member of the band had been eliminated from the solo contest. They became one of the best-selling boy groups of all time before going on an indefinite hiatus in 2016.
Styles released his self-titled debut solo album through Columbia Records in 2017. It debuted at number one in the UK and the US and was one of the world's top-ten best-selling albums of the year, while its lead single, "Sign of the Times", topped the UK Singles Chart. Styles' second album, Fine Line (2019), debuted atop the US Billboard 200 with the biggest ever first-week sales by an English male artist, and was the most recent album to be included in Rolling Stone's "500 Greatest Albums of All Time" in 2020. Its fourth single, "Watermelon Sugar", topped the US Billboard Hot 100. Styles' third album, Harry's House (2022), broke several records and was widely acclaimed, receiving the Grammy Award for Album of the Year in 2023. Its lead single, "As It Was", became the number-one song of 2022 globally according to Billboard.
Styles has received various accolades, including six Brit Awards, three Grammy Awards, an Ivor Novello Award, and three American Music Awards. His film roles include Dunkirk (2017), Don't Worry Darling (2022), and My Policeman (2022). Aside from music and acting, Styles is known for his flamboyant fashion. He is the first man to appear solo on the cover of Vogue.
Page: Debbie Harry
Summary: Deborah Ann Harry (born Angela Trimble; July 1, 1945) is an American singer, songwriter and actress, best known as the lead vocalist of the band Blondie. Four of her songs with the band reached No. 1 on the US charts between 1979 and 1981.
Born in Miami, Florida, Harry was adopted as an infant and raised in Hawthorne, New Jersey. After college she worked various jobs—as a dancer, a Playboy Bunny, and a secretary (including at the BBC in New York)—before her breakthrough in the music industry. She co-formed Blondie in 1974 in New York City. The band released its eponymous debut studio album in 1976 and released three more studio albums between then and 1979, including Parallel Lines, which spawned six singles, including "Heart of Glass". Their fifth studio album, Autoamerican (1980), spawned such hits as a cover of "The Tide Is High", and "Rapture", which is considered the first rap song to chart at number one in the United States.Harry released her debut solo studio album, KooKoo, in 1981. During a Blondie hiatus, she embarked on an acting career, appearing in lead roles in the neo-noir Union City (1980) and in David Cronenberg's body horror film Videodrome (1983). She released her second solo studio album, 1986's Rockbird, and starred in John Waters's cult dance film Hairspray (1988). She released two more solo albums between then and 1993, before returning to film with roles in a John Carpenter-directed segment of the horror film Body Bags (1993), and in the drama Heavy (1995).
Blondie reunited in the late 1990s, releasing No Exit (1999), followed by The Curse of Blondie (2003). Harry continued to appear in independent films throughout the 2000s, including Deuces Wild (2002), My Life Without Me (2003) and Elegy (2008). With Blondie, she released the group's ninth studio album, Panic of Girls, in 2011, followed by Ghosts of Download (2014). The band's eleventh studio album, 2017's Pollinator, charted at number 4 in the United Kingdom.
Page: Harry Potter
Summary: Harry Potter is a series of seven fantasy novels written by British author J. K. Rowling. The novels chronicle the lives of a young wizard, Harry Potter, and his friends Hermione Granger and Ron Weasley, all of whom are students at Hogwarts School of Witchcraft and Wizardry. The main story arc concerns Harry's conflict with Lord Voldemort, a dark wizard who intends
Thought: I now know the final answer
Final Answer: Harry Styles is an English singer, songwriter and actor. He rose to fame as a member of the boy band One Direction, and later embarked on a solo career. He released his debut solo album, Harry Styles, in 2017, and his second album, Fine Line, in 2019. He has also had success in film, appearing in Dunkirk (2017), Don't Worry Darling (2022) and My Policeman (2022).
> Finished chain.
"Harry Styles is an English singer, songwriter and actor. He rose to fame as a member of the boy band One Direction, and later embarked on a solo career. He released his debut solo album, Harry Styles, in 2017, and his second album, Fine Line, in 2019. He has also had success in film, appearing in Dunkirk (2017), Don't Worry Darling (2022) and My Policeman (2022)."
可以看到,一旦我们执行 .run() 方法,智能体便会处理用户提示并开始推理阶段,其结论为:“I should look for a biography of the singer”。为此,它制定了一个行动计划,即根据我们的工具定义使用 Wikipedia Search 工具,并将“Harry Styles biography”作为输入。随后行动计划启动,智能体从 Wikipedia 数据库检索相关信息,处理结果,并以自然语言生成合适的答案。
示例 2:随机浏览
现在让我们请求一个通用的浏览任务,这样智能体在工具包描述中就没有特定的工具被点名:
agent.run(
"Yesterday's latest news in Spain"
)
让我们观察此例中的推理过程:
> Entering new AgentExecutor chain...
I should look for news from yesterday
Action: Google Search
Action Input: "Yesterday's news in Spain"
Observation: The latest breaking news, comment and features from The Independent. All the latest content about Spain from the BBC. Find all national and international information about spain. Select the subjects you want to know more about on euronews.com. Latest Spain news stories including accidents, crime and policing, politics, and Spanish sport news headlines. Latest news, essential insights and practical guides to life in Spain from The Local, Europe's leading independent voice. Missing: Yesterday's | Show results with:Yesterday's. Stay on top of Spain latest developments on the ground with Al Jazeera's fact-based news, exclusive video footage, photos and updated maps. Missing: Yesterday's | Show results with:Yesterday's. Spain · Shakira due to go on trial in Spain over tax fraud claims · The Observer view on Pedro Sánchez's election deal to take power: it undermines democracy. Missing: Yesterday's | Show results with:Yesterday's. Latest News · Hundreds leave Al-Shifa hospital as Israeli forces take control of facility · F1 fans file class-action suit over being forced to exit Las Vegas ... Missing: Yesterday's | Show results with:Yesterday's. Follow the latest Spain news stories and headlines. Get breaking news alerts when you download the ABC News App and subscribe to Spain notifications. Missing: Yesterday's | Show results with:Yesterday's. Get the latest breaking news and top news headlines at Reuters ... Spain Headlines. Shakira stands trial in Spain for alleged tax fraud. Shakira ... Missing: Yesterday's | Show results with:Yesterday's.
Thought: I found a lot of news sources with yesterday's news, so the final answer should be about that.
Final Answer: The latest news in Spain from yesterday is that Shakira is standing trial in Spain for alleged tax fraud, hundreds of people have left Al-Shifa hospital as Israeli forces take control, and F1 fans have filed a class-action suit over being forced to exit Las Vegas. Other news includes insights and practical guides to life in Spain, Pedro Sánchez's election deal to take power, and the top news headlines from Reuters.
> Finished chain.
"The latest news in Spain from yesterday is that Shakira is standing trial in Spain for alleged tax fraud, hundreds of people have left Al-Shifa hospital as Israeli forces take control, and F1 fans have filed a class-action suit over being forced to exit Las Vegas. Other news includes insights and practical guides to life in Spain, Pedro Sánchez's election deal to take power, and the top news headlines from Reuters."
在此例中,智能体成功回退到默认的 Google Serper 工具,并找到了西班牙的最新新闻。这个浏览示例尤其有趣,因为我们向一个训练数据截止于 2021 年 9 月的 LLM 提出了一个非常时效性的提示,但仍然获得了最新的响应。
示例 3:视频检索
最后,假设我们对某个视频资源感兴趣。看看模型是否真的能为我们指路。我们将关闭 verbose 模式,仅观察模型的实际响应:
agent = initialize_agent(
tools, llm, agent="zero-shot-react-description"
)
agent.run(
"Can you point me to the Procrastination TED talk by Tim Urban?"
)
果不其然,我们成功获得了如下回应:
'The TED Talk "Procrastination" by Tim Urban can be found at
https://www.youtube.com/watch?v=arj7oStGLkU'
有效!通过这三个示例,我们展示了 LLM 可利用的不同来源来满足我们的请求。
如果您有兴趣为我们的工具包加入更多工具,强烈推荐阅读文章 ReAct: 3 LangChain Tools To Enhance the Default GPT Capabilities。
结语
在本教程中,我们学习了如何使用 LangChain Tools 来增强 LLM 的浏览能力。LangChain 的核心优势之一,是其能够简化基于 LLM 的应用的开发,提供一系列强大功能,包括内置记忆、完整的聊天机器人以及本文探讨的工具等。
尽管 OpenAI 正在通过最新 GPT 模型的发布在定制化 AI 领域不断前进,但我认为仍有相当大的发展与创新空间。
在这方面,对于经常通过 Python 和 OpenAI API 与 GPT 模型互动的用户而言,LangChain Tools 在这场技术竞赛中具有显著优势。这与面向非编码人群的 GPTs 形成鲜明对比。GPT 用户可以轻松在 ChatGPT 界面中配置一个专用实例并在需要时访问,虽然更易用,但灵活性有限。
此外,LangChain Tools 能够检索 Google 或 Wikipedia 等外部信息来源,极大提升了模型的知识覆盖面。相比之下,GPTs 虽然支持上传信息,但规模更小。
总之,在我看来,LangChain Tools 是增强模型能力、并利用广泛可用的公共数据自定义我们实例的最强大特性。现在,您能想象将这些工具与我们自己的私有数据库相结合的威力吗?
刚接触 LLM 世界?来看看我们的课程 Large Language Models Concepts,快速入门!

Andrea Valenzuela 目前在瑞士日内瓦的欧洲核子研究中心(CERN)粒子加速器的 CMS 实验工作。她在过去六年深耕数据工程与数据分析,主要职责包括数据分析与软件开发。她现正通过 Medium 出版物 ForCode'Sake 推动数据相关技术的学习大众化。
她拥有加泰罗尼亚理工大学工程物理学学士学位,以及庞培法布拉大学智能交互系统硕士学位。她的研究经历包括基于早期 OpenAI 图像生成算法(如 Normalizing Flows)的专业工作。
我非常欣赏 ChatGPT 的一项新功能:当需要更多信息时,它能够浏览互联网来满足用户的请求。不过,到目前为止我遇到了两个问题:
事实证明,LangChain 通过发布所谓的LangChain Tools很好地解决了这些问题!
在本教程中,我们将学习如何使用 LangChain Tools 构建一个具备浏览能力的 GPT 模型。这里的浏览能力指的是允许模型查阅外部来源以扩展其知识库,从而比仅依赖模型的既有知识更有效地完成用户请求。
更棒的是,LangChain Tools 能与 Python 和 OpenAI API 无缝集成!
让我们开始吧!