

Agentic RAG 项目概览
让我一步步带您了解我们要构建的内容。核心是在如下架构的基础上创建一条 RAG 流水线:
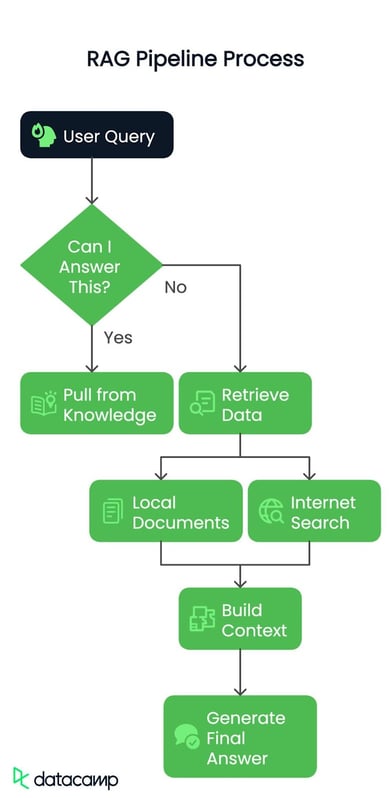
步骤 1:用户查询
无论是简单问题还是复杂难题,一切都从用户的一个问题开始。这是点燃我们流水线的火花。
步骤 2:查询路由
接下来系统会检查:我能回答吗?
如果可以?那就直接从已有知识中提取并立即给出答复。
如果不行?那就该深挖了!查询将被路由到下一步。
步骤 3:检索数据
当答案并不触手可及时,流水线会深入两种可能来源:
- 本地文档:我们会使用一份预处理的 PDF 作为知识库,系统将在其中搜索相关的信息片段。
- 互联网搜索:如果需要更多上下文,流水线可以访问外部来源以抓取最新信息。
步骤 4:构建上下文
无论来自 PDF 还是网络,检索到的数据都会被整理成连贯的“检索上下文”。可以把它理解为先把所有拼图碎片收集起来。
步骤 5:生成最终答案
最后,将该上下文传递给大型语言模型(LLM),生成清晰且准确的答案。它不仅仅是检索数据,更是对数据的理解与最佳呈现。
到这里,我们将拥有一条智能高效的 RAG 流水线,能够基于真实世界的上下文动态响应查询。
本地数据源
首先,我将使用一份真实世界的文档作为我们的本地数据源。我们要处理的文档正是 Generative AI Principles。它信息量丰富,非常适合作为我们流水线的测试用例。您还需要该文件的摘要,我会将其用于路由。您可以从此处获取摘要文件。
下面是逐步入门所需的一切。
先决条件
在开始之前,您需要准备以下几样:
- Groq API 密钥:您需要从 Groq 获取 API 密钥,可在此处获取:Groq API Console
- Gemini API 密钥:在智能体编排时 Gemini 会提供帮助。Groq 的响应非常快,但可能会受到当前速率限制的影响:Gemini API Console
- Serper.dev API 密钥:用于互联网搜索功能,我们将使用 Serper.dev。通过在此注册获取 API 密钥:Serper.dev API Key
安装依赖
先确保安装了正确的工具。打开终端,运行以下命令安装所需的 Python 包:
pip install langchain-groq faiss-cpu crewai serper pypdf2 python-dotenv setuptools sentence-transformers huggingface distutils`环境配置
当您准备好密钥和依赖包后,就可以开始了!我建议将 API 密钥保存在.env 文件中,或在代码库中以安全方式存储。以下是 .env 文件可能的样例:
import os from dotenv
import load_dotenv from langchain.vectorstores
import FAISS from langchain.document_loaders
import PyPDFLoader
from langchain.text_splitter import RecursiveCharacterTextSplitter
from langchain_huggingface.embeddings import HuggingFaceEmbeddings
from langchain_groq import ChatGroq
from crewai_tools import SerperDevTool
from crewai import Agent, Task, Crew, LLM
load_dotenv()
GROQ_API_KEY = os.getenv("GROQ_API_KEY")
SERPER_API_KEY = os.getenv("SERPER_API_KEY")
GEMINI=os.getenv("GEMINI")我加载了环境变量,以便在不硬编码的情况下安全管理 API 密钥和敏感数据。这样可以确保脚本安全,并且如有需要,我只需在一个地方(.env 文件)更改密钥。
简而言之,这些导入的包与函数将发挥以下作用:
- os:提供操作系统接口工具。
- dotenv:从
.env文件加载环境变量。 - FAISS:用于相似度搜索与检索的向量存储。
- PyPDFLoader:从 PDF 文档中抽取文本内容。
- RecursiveCharacterTextSplitter:以递归方式将文本拆分为易处理的片段。
- HuggingFaceEmbeddings:使用 HuggingFace 模型生成文本向量。
- ChatGroq:由 Groq 硬件加速驱动的聊天接口。
- SerperDevTool:执行网页搜索的工具。
- ScrapeWebsiteTool:从网页提取数据。
- Agent:定义具备角色与目标的 AI 实体。
- Task:表示智能体的具体目标或操作。
- Crew:为协同工作流编排智能体与任务。
- LLM:用于生成文本回复的大型语言模型接口。
初始化 LLM
我们先初始化两个语言模型:
llm:用于路由与生成答案等通用任务。我们将使用llama-3.3-70b-specdec模型。crew_llm:专用于网页抓取智能体,它需要略有不同的配置(例如更具创造性的 temperature)。我们将使用gemini/gemini-1.5-flash模型。
# Initialize LLM
llm = ChatGroq(
model="llama-3.3-70b-specdec",
temperature=0,
max_tokens=500,
timeout=None,
max_retries=2,
)
crew_llm = LLM(
model="gemini/gemini-1.5-flash",
api_key=GEMINI,
max_tokens=500,
temperature=0.7
)加入决策器
下面这个 check_local_knowledge() 函数充当决策器。我创建了一个提示词,将用户查询和一些本地上下文(来自 PDF)一并传入。模型会返回“Yes”或“No”,告诉我是否有足够的本地信息来回答该查询。如果不够,我们就转向网页抓取。
def check_local_knowledge(query, context):
"""Router function to determine if we can answer from local knowledge"""
prompt = '''Role: Question-Answering Assistant
Task: Determine whether the system can answer the user's question based on the provided text.
Instructions:
- Analyze the text and identify if it contains the necessary information to answer the user's question.
- Provide a clear and concise response indicating whether the system can answer the question or not.
- Your response should include only a single word. Nothing else, no other text, information, header/footer.
Output Format:
- Answer: Yes/No
Study the below examples and based on that, respond to the last question.
Examples:
Input:
Text: The capital of France is Paris.
User Question: What is the capital of France?
Expected Output:
Answer: Yes
Input:
Text: The population of the United States is over 330 million.
User Question: What is the population of China?
Expected Output:
Answer: No
Input:
User Question: {query}
Text: {text}
'''
formatted_prompt = prompt.format(text=context, query=query)
response = llm.invoke(formatted_prompt)
return response.content.strip().lower() == "yes"网页搜索与抓取智能体
接下来,我们使用crewai 库来设置一个网页搜索与抓取智能体。该智能体使用搜索工具(SerperDevTool)查找与用户查询相关的文章。任务描述确保智能体明确要检索的内容,并对相关网页内容进行总结。相当于派出一位专门的“网络采集员”为我们获取数据。
随后,get_web_content() 函数会运行网页抓取智能体。它将查询作为输入,获取最相关文章的简明摘要。函数返回原始结果;如果路由器判定本地信息不足,这个结果就会成为我们的上下文。
def setup_web_scraping_agent():
"""Setup the web scraping agent and related components"""
search_tool = SerperDevTool() # Tool for performing web searches
scrape_website = ScrapeWebsiteTool() # Tool for extracting data from websites
# Define the web search agent
web_search_agent = Agent(
role="Expert Web Search Agent",
goal="Identify and retrieve relevant web data for user queries",
backstory="An expert in identifying valuable web sources for the user's needs",
allow_delegation=False,
verbose=True,
llm=crew_llm
)
# Define the web scraping agent
web_scraper_agent = Agent(
role="Expert Web Scraper Agent",
goal="Extract and analyze content from specific web pages identified by the search agent",
backstory="A highly skilled web scraper, capable of analyzing and summarizing website content accurately",
allow_delegation=False,
verbose=True,
llm=crew_llm
)
# Define the web search task
search_task = Task(
description=(
"Identify the most relevant web page or article for the topic: '{topic}'. "
"Use all available tools to search for and provide a link to a web page "
"that contains valuable information about the topic. Keep your response concise."
),
expected_output=(
"A concise summary of the most relevant web page or article for '{topic}', "
"including the link to the source and key points from the content."
),
tools=[search_tool],
agent=web_search_agent,
)
# Define the web scraping task
scraping_task = Task(
description=(
"Extract and analyze data from the given web page or website. Focus on the key sections "
"that provide insights into the topic: '{topic}'. Use all available tools to retrieve the content, "
"and summarize the key findings in a concise manner."
),
expected_output=(
"A detailed summary of the content from the given web page or website, highlighting the key insights "
"and explaining their relevance to the topic: '{topic}'. Ensure clarity and conciseness."
),
tools=[scrape_website],
agent=web_scraper_agent,
)
# Define the crew to manage agents and tasks
crew = Crew(
agents=[web_search_agent, web_scraper_agent],
tasks=[search_task, scraping_task],
verbose=1,
memory=False,
)
return crew
def get_web_content(query):
"""Get content from web scraping"""
crew = setup_web_scraping_agent()
result = crew.kickoff(inputs={"topic": query})
return result.raw创建向量数据库
setup_vector_db() 函数会基于一份 PDF 文件创建向量数据库。我分步是这样做的:
- 加载 PDF:使用
PyPDFLoader提取内容。 - 切分文本:使用
RecursiveCharacterTextSplitter将 PDF 内容拆分为较小片段(每段 1000 字符,重叠 50 字符)。这样更易管理与检索。 - 创建向量库:用句向量模型对片段进行向量化,并存入FAISS 向量数据库,从而高效检索相关文本。
随后,get_local_content() 函数会在向量数据库中针对用户查询检索排名前 5 的相关片段,并将这些片段合并为单个上下文字符串。
def setup_vector_db(pdf_path):
"""Setup vector database from PDF"""
# Load and chunk PDF
loader = PyPDFLoader(pdf_path)
documents = loader.load()
text_splitter = RecursiveCharacterTextSplitter(
chunk_size=1000,
chunk_overlap=50
)
chunks = text_splitter.split_documents(documents)
# Create vector database
embeddings = HuggingFaceEmbeddings(
model_name="sentence-transformers/all-mpnet-base-v2"
)
vector_db = FAISS.from_documents(chunks, embeddings)
return vector_db
def get_local_content(vector_db, query):
"""Get content from vector database"""
docs = vector_db.similarity_search(query, k=5)
return " ".join([doc.page_content for doc in docs])生成最终答案
一旦拿到上下文(来自本地文档或网页抓取),我会将其与用户查询一并传递给语言模型。LLM 会结合上下文与查询,以对话形式生成最终答案。
主流程如下:
- 路由:我使用
check_local_knowledge()来判断本地 PDF 内容是否足以回答该查询。 - 如果是“Yes”,我会从向量库中提取相关片段。
- 如果是“No”,我会从网页抓取相关文章。
- 最终答案:拿到上下文后,交由 LLM 生成最终回复。
def generate_final_answer(context, query):
"""Generate final answer using LLM"""
messages = [
(
"system",
"You are a helpful assistant. Use the provided context to answer the query accurately.",
),
("system", f"Context: {context}"),
("human", query),
]
response = llm.invoke(messages)
return response.content
def process_query(query, vector_db, local_context):
"""Main function to process user query"""
print(f"Processing query: {query}")
# Step 1: Check if we can answer from local knowledge
can_answer_locally = check_local_knowledge(query, local_context)
print(f"Can answer locally: {can_answer_locally}")
# Step 2: Get context either from local DB or web
if can_answer_locally:
context = get_local_content(vector_db, query)
print("Retrieved context from local documents")
else:
context = get_web_content(query)
print("Retrieved context from web scraping")
# Step 3: Generate final answer
answer = generate_final_answer(context, query)
return answer最后,我们用 main() 函数把一切串起来:
def main():
# Setup
pdf_path = "genai-principles.pdf"
# Initialize vector database
print("Setting up vector database...")
vector_db = setup_vector_db(pdf_path)
# Get initial context from PDF for routing
local_context = get_local_content(vector_db, "")
# Example usage
query = "What is Agentic RAG?"
result = process_query(query, vector_db, local_context)
print("\nFinal Answer:")
print(result)
if __name__ == "__main__":
main()以上过程中,我们:
- 设置向量数据库:加载并处理 PDF。
- 初始化本地上下文:从 PDF 中抓取了一些通用内容,传递给路由器。
- 运行示例查询:我们运行了一个示例查询(
"What is Agentic RAG?"),并打印出最终答案。
以下是程序输出:
Agentic RAG is a technique for building Large Language Model (LLM) powered applications that incorporates AI agents. It is an extension of the traditional Retrieval-Augmented Generation (RAG) approach, which uses an external knowledge source to provide the LLM with relevant context and reduce hallucinations.
In traditional RAG pipelines, the retrieval component is typically composed of an embedding model and a vector database, and the generative component is an LLM. At inference time, the user query is used to run a similarity search over the indexed documents to retrieve the most similar documents to the query and provide the LLM with additional context.
Agentic RAG, on the other hand, introduces AI agents that are designed to interact with the user query and provide additional context to the LLM. These agents can be thought of as "virtual assistants" that help the LLM to better understand the user's intent and retrieve relevant documents.
The key components of Agentic RAG include:
1. AI agents: These are the virtual assistants that interact with the user query and provide additional context to the LLM.
2. Retrieval component: This is the component that retrieves the most similar documents to the user query.
3. Generative component: This is the component that uses the retrieved documents to generate the final output.
Agentic RAG has several benefits, including:
1. Improved accuracy: By providing additional context to the LLM, Agentic RAG can improve the accuracy of the generated output.
2. Enhanced user experience: Agentic RAG can help to reduce the complexity of the user interface and provide a more natural and intuitive experience.
3. Increased flexibility: Agentic RAG can be easily extended to support new use cases and applications.
However, Agentic RAG also has some limitations, including:
1. Increased complexity: Agentic RAG requires additional components and infrastructure, which can increase the complexity of the system.
2. Higher computational requirements: Agentic RAG requires more computational resources to handle the additional complexity of the AI agents and the retrieval component.
3. Training requirements: Agentic RAG requires more data and training to learn the behaviour of the AI agents and the retrieval component.输出解读
当我提出“What is Agentic RAG?”这一问题时,文档中并未明确给出答案,系统展现出了灵活性与智能性。crewAI 智能体正确地进行了路由,依据路由器的判断需要外部上下文。智能体协作抓取了最相关的网页文章,分析其内容,并生成了信息充分的回答。
系统清晰地解释了 agentic RAG 的概念、其组成部分(AI 智能体、检索与生成模块)、优势(准确性、用户体验与灵活性)以及局限性(复杂度、算力需求与训练要求)。
这凸显了流水线能够动态获取上下文,即便面对超出初始数据集的查询,也能提供准确、精炼且有价值的洞见。
结语
我们构建的这条流水线是一个动态的多步骤流程,通过结合现有与外部知识,高效处理用户查询。
系统能够针对各类查询动态适配,提供准确、友好的答案。借助本地数据、实时互联网搜索与无缝的用户界面集成,这条 RAG 流水线在真实应用场景中表现稳健、实用。下一步,欢迎您基于本文覆盖的工作流,动手构建属于您自己的项目。

您是否常常希望自己的 AI 不仅仅是重复它已经知道的内容?作为一个花了无数时间打磨和调优 AI 系统的人,我可以告诉您,传统模型虽然令人印象深刻,但往往像被困在只限于训练数据的“泡泡”里。这正是Agentic RAG大显身手的地方。
在 agentic RAG 中,agentic AI 的决策能力与检索增强生成(RAG)的适应性相结合。二者共同构成一个能够自主访问、推理并生成相关信息的系统。
我此前写过一篇关于agentic RAG的文章,能从理论层面帮您全面理解它。本文将更偏向实操,我们就聚焦在这上面吧。