
Our biggest-ever sale. 60% off AI & data skills
Buy Now

Öva och håll koll på dina framsteg.
Fortsätt med GoogleGenom att fortsätta godkänner du vår användarvillkor, våra integritetspolicy och att dina uppgifter lagras i USA.LangChain is designed around:
Prompts are the instructions given to the language model to guide its responses. LangChain provides a standardized interface for creating and managing prompts, making it easier to customize and reuse them across different models and applications. You can learn more about prompt engineering with GPT and LangChain in DataCamp’s code-along.
LangChain offers a unified interface for interacting with various large language models (LLMs). This includes models from providers like OpenAI (e.g., GPT-4o), Anthropic (e.g., Claude), and Cohere. The framework simplifies switching between different models by abstracting their differences, allowing for seamless integration.
LangChain’s exceptional feature is its memory management capabilities for LLMs. Unlike typical LLMs that process each query independently, LangChain retains information from previous interactions to enable context-aware and coherent conversations.
It provides various memory implementations, which stores entire conversation histories, and maintains recent by summarizing older interactions while keeping recent ones.
Chains are sequences of operations where the output of one step is used as the input for the next. LangChain provides a robust interface for building and managing chains, along with numerous reusable components. This modular approach allows for the creation of complex workflows that integrate multiple tools and LLM calls.
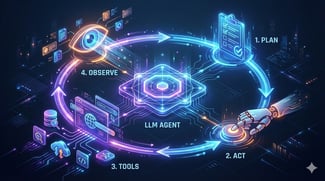
Agents in LangChain are designed to determine and execute actions based on the input provided. They use an LLM to decide the sequence of actions and leverage various tools to accomplish tasks. LangChain includes a variety of pre-built agents that can be used or customized to fit specific application needs.
LangChain uses text embedding models to create embeddings that capture the semantic meaning of texts, improving content discovery and retrieval. It supports over 50 different storage options for embeddings, storage, and retrieval.
In LangChain, an agent acts using natural language instructions and can use tools to answer queries. Based on user input, agents determine which actions to take and in what order. Actions can involve using tools (like a search engine or calculator) and processing their outputs or returning responses to users.
Agents can dynamically call chains based on user input.
LangSmith evaluator suite for testing and optimization of LLM apps. You can get an in-depth look at how to debug and test LLMs in LangSmith with our tutorial.
LangSmith suite includes a variety of evaluators and tools to assess both qualitative and quantitative aspects of LLM performance.
Datasets are central to LangSmith’s evaluation process, serving as collections of examples that the system uses to test and benchmark performance.
The datasets can be manually curated, collected from user feedback, or generated via LLMs, and they form the basis for running experiments and tracking performance over time.
Evaluators measure specific performance metrics:
LangSmith's evaluation can be performed both offline and online: Offline evaluations can be done on reference datasets before deployment, while online evaluations continuously monitor live applications to ensure they meet performance standards and detect issues like drift or regressions.
LangSmith is useful for moving from prototype to production so that applications perform well under real-world conditions.
LangServe is used for the deployment stage of LangChain apps by automating schema inference, providing API endpoints and real-time monitoring.
LangServe can convert any chain into a REST API with:
/invoke, /batch, and /stream, which can handle multiple requests concurrently.Monitoring
LangServe can be integrated with LangSmith tracing for real-time monitoring capabilities such as:
LangServe offers a playground environment for both technical and non-technical users to interact with and test the application: it supports streaming outputs, logs intermediate steps, and configurable options for fine-tuning applications. LangServe also automatically generates API documentation.
Deployment with LangServe can be done with GitHub for one-click deployment and supports various hosting platforms like Google Cloud and Replit.
LlamaIndex equips LLMs with the capability of adding RAG functionality to the system using external knowledge sources, databases, and indexes as query engines for memory purposes.
During this stage, your private data is efficiently converted into a searchable vector index. LlamaIndex can process various data types, including unstructured text documents, structured database records, and knowledge graphs.
The data is transformed into numerical embeddings that capture its semantic meaning, allowing for fast similarity searches later on. This stage ensures that all relevant information is indexed and ready for quick retrieval.
Once you have loaded and indexed data, you will want to store it to avoid the time and cost of re-indexing it. By default, indexed data is stored only in memory, but there are ways to persist it for future use.
The simplest method is using the .persist() method, which writes all the data to disk at a specified location. For example, after creating an index, you can use the .persist() method to save the data to a directory.
To reload the persisted data, you would rebuild the storage context from the saved directory and then load the index using this context. This way, you quickly resume the stored index, saving time and computational resources.
You can learn about how to do this in our full LlamaIndex tutorial.
Vector stores are useful for storing the embeddings created during the indexing process.
LlamaIndex uses the default text-embedding-ada-002 from OpenAI to generate these embeddings. Depending on the LLM in use, different embeddings may be preferable for efficiency and computational cost.
The VectorStoreIndex converts all text into embeddings using an API from the LLM. When querying, the input query is also converted into an embedding and ranked. The index returns the top k most similar embeddings as chunks of text.
A method known as "top-k semantic retrieval," is used for retrieving the most relevant data.
If embeddings are already created and stored, you can load them directly from the vector store, bypassing the need to reload documents or recreate the index.
A summary index is a simpler form of indexing that is best suited for generating summaries from text documents. It stores all documents and returns them to the query engine.
In the query stage, when a user queries the system, the most relevant chunks of information are retrieved from the vector index based on the query's semantic similarity. Retrieved snippets, along with the original query, are then passed to the large language model, which generates a final response.
The system retrieves the most relevant information from stored indexes and feeds it to the LLM, which responds with up-to-date and contextually relevant information.
This step follows retrieval. During this stage, the retrieved document segments, or nodes, may be reranked, transformed, or filtered. The nodes contain specific metadata or keywords, which refine the relevance and accuracy of the data processing.
Response Synthesis is the final stage where the query, the most relevant data, and the initial prompt are combined and sent to the LLM to generate a response.
LlamaHub contains a variety of data loaders designed to integrate multiple data sources into application workflow or simply used for data ingestion from different formats and repositories.
For example, the Google Docs Reader can be initialized and used to load data from Google Docs. The same pattern applies to other connectors available within LlamaHub.
One of the built-in connectors is the SimpleDirectoryReader, which supports a wide range of file types, including markdown files (.md), PDFs, images (.jpg, .png), Word documents (.docx), and even audio and video files. The connector is directly available as part of LlamaIndex and can be used to load data from a specified directory.
LlamaIndex is primarily designed for search and retrieval tasks. It excels at indexing large datasets and retrieving relevant information quickly and accurately. LangChain, on the other hand, provides a modular and adaptable framework for building a variety of NLP applications, including chatbots, content generation tools, and complex workflow automation systems.
LlamaIndex transforms various types of data, such as unstructured text documents and structured database records, into numerical embeddings that capture their semantic meaning.
LangChain provides a modular and customizable approach to data indexing with complex chains of operations, integrating multiple tools and LLM calls.
LlamaIndex is optimized for retrieval, using algorithms to rank documents based on their semantic similarity to perform a query.
LangChain integrates retrieval algorithms with LLMs to produce context-aware outputs. LangChain can dynamically retrieve and process relevant information based on the context of the user’s input, which is useful for interactive applications like chatbots.
LlamaIndex offers limited customization focused on indexing and retrieval tasks. Its design is optimized for these specific functions, providing high accuracy. LangChain, however, provides extensive customization options. It supports the creation of complex workflows for highly tailored applications with specific requirements.
LlamaIndex provides basic context retention capabilities suitable for simple search and retrieval tasks. It can manage the context of queries to some extent but is not designed to maintain long interactions.
LangChain excels in context retention, which is crucial for applications where retaining information from previous interactions and coherent and contextually relevant responses over long conversations are crucial.
LlamaIndex is ideal for internal search systems, knowledge management, and enterprise solutions where accurate information retrieval is critical.
LangChain is better suited for applications requiring complex interaction and content generation, such as customer support, code documentation, and various NLP tasks.
LlamaIndex is optimized for speed and accuracy; the fast retrieval of relevant information. Optimization is crucial for handling large volumes of data and quick responses.
LangChain is efficient in handling complex data structures that can operate inside its modular architecture for sophisticated workflows.
LlamaIndex integrates with debugging and monitoring tools to facilitate lifecycle management. Integration helps tracking the performance and reliability of applications by providing insights and tools for troubleshooting.
LangChain offers evaluation suite, LangSmith, tools for testing, debugging, and optimizing LLM applications, ensuring that applications perform well under real-world conditions.
While both frameworks support integration with external tools and services, their primary focus areas set them apart.
LangChain is highly modular and flexible, focusing on creating and managing complex sequences of operations through its use of chains, prompts, models, memory, and agents.
LangChain is perfect for applications that require intricate interaction patterns and context retention, such as chatbots and automated customer support systems.
LlamaIndex is a tool of choice for systems that need fast and precise document retrieval based on semantic relevance.
LangChain’s integrations, such as LangSmith for evaluation and LangServe for deployment, enhance the development lifecycle by providing tools for streamlined deployment processes and optimization.
On the other hand, LlamaIndex integrates external knowledge sources and databases as query engines for memory purposes for RAG-based apps. LlamaHub extends LlamaIndex’s capabilities with data loaders for the integration of various data sources.
Here's a comparative table to summarize the key differences:
|
Feature |
LlamaIndex |
LangChain |
|
Primary Focus |
Search and retrieval |
Flexible LLM-powered application development |
|
Data Indexing |
Highly efficient |
Modular and customizable |
|
Retrieval Algorithms |
Advanced and optimized |
Integrated with LLMs for context-aware outputs |
|
User Interface |
Simple and user-friendly |
Comprehensive and adaptable |
|
Integration |
Multiple data sources, seamless platform integration |
Supports diverse AI technologies and services |
|
Customization |
Limited, focused on indexing and retrieval |
Extensive, supports complex workflows |
|
Context Retention |
Basic |
Advanced, crucial for chatbots and long interactions |
|
Use Cases |
Internal search, knowledge management, enterprise solutions |
Customer support, content generation, code documentation |
|
Performance |
Optimized for speed and accuracy |
Efficient in handling complex data structures |
|
Lifecycle Management |
Integrates with debugging and monitoring tools |
Comprehensive evaluation suite (LangSmith) |
Both frameworks offer powerful capabilities, and choosing between them should be based on your specific project needs and goals.
For some projects, combining the strengths of both LlamaIndex and LangChain might provide the best results.
If you’re curious to learn more about these tools, there are several resources available:

I am a linguist and author who became an ML engineer specializing in vector search and information retrieval. I have experience in NLP research and the development of RAG systems, LLMs, transformers, and deep learning/neural networks in general. I am passionate about coding in Python and Rust and writing technical and educational materials, including scientific articles, documentation, white papers, blog posts, tutorials, and courses. I conduct research, experiment with frameworks, models, and tools, and create high-quality, engaging content.
blogg
 Tim Lu• 13 min

blogg
Tim Lu• 15 min
Handledning
 Vaibhav Mehra• 15 min
Keep Learning With DataCamp
Kurs
Bygg en kundsupportassistent steg för steg med Googles Agent Development Kit (ADK).
Kurs
Lär dig grunderna i AI-agenter, deras komponenter och verklig användning – ingen kodning krävs.
Öva och håll koll på dina framsteg.
Fortsätt med GoogleGenom att fortsätta godkänner du vår användarvillkor, våra integritetspolicy och att dina uppgifter lagras i USA.



LlamaIndex and LangChain are both robust frameworks designed for developing applications powered by large language models, each with distinct strengths and areas of focus.
LangChain vs LlamaIndex: A Basic Overview
LlamaIndex excels in search and retrieval tasks. It’s a powerful tool for data indexing and querying and a great choice for projects that require advanced search. LlamaIndex enables the handling of large datasets, resulting in quick and accurate information retrieval.
LangChain is a framework with a modular and flexible set of tools for building a wide range of NLP applications. It offers a standard interface for constructing chains, extensive integrations with various tools, and complete end-to-end chains for common application scenarios.
Let’s look at each in more detail. You can also read our full LlamaIndex tutorial and LangChain tutorial to learn more.