Picture a ship navigating through fog. Its GPS is noisy, the ocean current is unknown, and the exact position can't be measured directly. It can only be approximated from sensor readings. State space models were built for exactly this kind of problem: systems where the thing you care about is hidden, and all you have access to are imperfect measurements of it.
This article covers the structure of state space models, how to estimate hidden states through filtering and smoothing, where the Kalman filter fits in, and how to implement these models in Python and R.
What Is a State Space Model?
A state space model is a mathematical framework for describing a system that changes over time through states you can't directly observe. Two quantities are at play: the state, which is the true underlying information describing the system at any moment, and the observation, which is the noisy, indirect measurement you actually get.
The model specifies two things: how the hidden state evolves from one time step to the next, and how that hidden state produces the observations you see. That separation is what makes the framework so general. It shows up across signal processing, econometrics, control systems, and machine learning. This happens often without anyone realizing they're all working within the same formal structure.
How State Space Models Work
The core logic follows a simple sequence at each time step:
Previous state → Current state → Observation
The system moves from its previous hidden state to a new one. This transition can include randomness, since real systems aren't perfectly predictable. The new state then generates an observable measurement, which comes with its own noise. You never see the state directly; you see what it produces, imperfectly.
What you can do is use each new observation to update your best estimate of the hidden state. That's the inference problem, and it's what most of the algorithmic machinery around state space models is designed to solve.
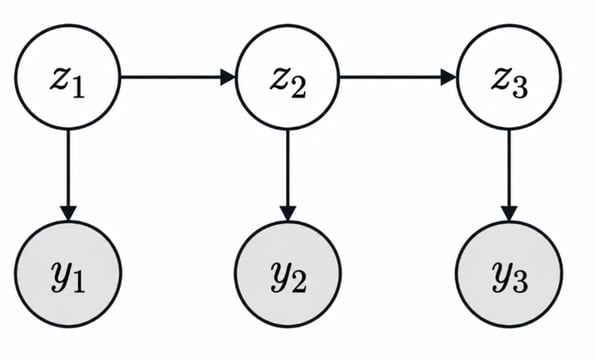
Hidden states generate noisy observations over time. Image by Author.
State and Observation Equations
The model's structure comes down to two equations. One for how the state moves, one for what you can measure.
State equation
The state equation describes how the hidden state evolves. In scalar form:
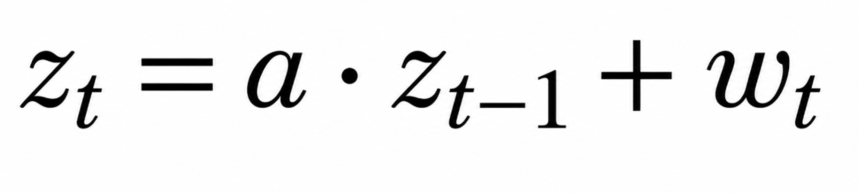
Here, zₜ is the current hidden state, a captures the transition dynamics (how strongly the previous state carries forward), and wₜ is process noise — the randomness in how the system moves. In the matrix formulation for multivariate systems, a becomes a transition matrix, but the idea is identical.
Observation equation
The observation equation connects the hidden state to what you measure:
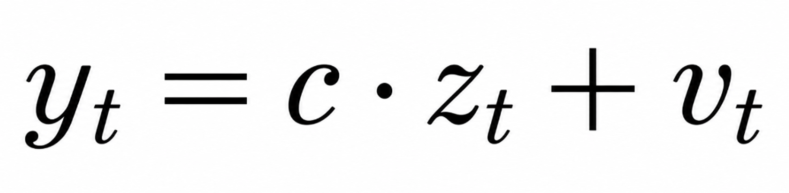
yₜ is the observed measurement, c defines the observation relationship, and vₜ is measurement noise. Start with scalar versions like these before worrying about the general matrix form. The matrices add generality, not new ideas.
A Simple State Space Model Example
Think of a car moving along a road. Its true position and velocity are the hidden state. You can't observe them directly. What you have is a GPS reading, which is noisy. The state equation models how position and velocity change between time steps (the car keeps moving at roughly the same speed). The observation equation connects the true position to the GPS reading, which might be off by several meters.
A good visualization of this shows three lines: the true position (smooth), the GPS readings (scattered around the truth), and the estimated position from the model (close to the truth, somewhat smoother than the raw GPS). Getting that third line is the model's whole job.
How States Are Estimated
Defining the model is only half the problem. You also need to infer the hidden states from the observations you actually have. Three tasks cover the space:
Filtering estimates the current state using only observations up to right now — real-time inference, useful for tracking and control. Smoothing goes back and revises those estimates using observations from both before and after a given point — generally more accurate, but it requires the full sequence. Prediction extrapolates forward to estimate future states before observations arrive.
Most applications use filtering. Smoothing comes up when you're doing retrospective analysis and accuracy matters more than speed.
Kalman Filtering and State Space Models
The Kalman filter is the algorithm for filtering in linear Gaussian state space models. Worth being precise here: the state space model is the model; the Kalman filter is one inference method that applies to a specific class of those models.
The filter works in two alternating steps. In the prediction step, it uses the state equation to project the current estimate forward in time, along with a measure of how uncertain that estimate is. In the update step, a new observation arrives and the estimate is corrected. How much it shifts depends on the relative uncertainty of the prediction versus the measurement. If the model's prediction is reliable, the observation has less influence. If the GPS signal is clean and the model is uncertain, the observation dominates. That uncertainty-weighted blending is what makes the Kalman filter work in practice.
Extensions exist for nonlinear or non-Gaussian settings: the extended Kalman filter linearizes the dynamics, the unscented Kalman filter uses a smarter approximation, and particle filters handle the fully general case by sampling. Those are different articles.
Types of State Space Models
The framework covers a range of settings depending on what you're willing to assume about the dynamics and noise.
Linear Gaussian state space models are the classical setting: linear transition and observation equations, Gaussian noise. Kalman filtering applies directly and exact inference is tractable.
Nonlinear state space models arise when the state transition or observation relationship isn't linear — think a pendulum, or a model where price effects taper off. Exact inference is no longer available.
Non-Gaussian state space models drop the assumption that noise follows a normal distribution. Count data, binary outcomes, and heavy-tailed processes all fall here.
A few comparisons worth making explicit, since the boundaries here are blurrier than they first appear.
State space models vs. ARIMA
ARIMA models the observed values and their past errors directly, without introducing any hidden state. State space models bring in latent states explicitly. That said, ARIMA models can be reformulated in state space form — so the two aren't as separate as they first appear, and software often uses state space representations internally to fit ARIMA anyway.
State space models vs. hidden Markov models
Both involve hidden states. Classical HMMs use discrete latent states (the system is in one of k modes), while most state space models use continuous ones. For speech recognition, discrete modes make sense; for tracking a physical object, continuous states are the natural choice.
State space models vs. structural time-series models
Structural time-series models (which decompose a series into trend, seasonality, and irregular components) are typically formulated as state space models rather than competing with them. They're a specific use case of the framework.
State Space Models in Python and R
The workflow is similar in both languages — define the model, fit it, and pull out the hidden state estimates.
State space models in Python
The statsmodels library offers a clean interface for fitting state space models. Here's a local level model (the simplest structural model, with a random walk state and noisy observations) fit to some time-series data:
import statsmodels.api as sm
model = sm.tsa.UnobservedComponents(time_series, level='local level')
result = model.fit(disp=False)
print(result.filtered_state[0])
forecast = result.forecast(10)
The filtered state gives you the model's best estimate of the hidden level at each point in time. That's the main output you care about, not the parameters themselves.
State space models in R
In R, the KFAS package handles Gaussian state space models and is worth knowing if you work in this space regularly. The workflow mirrors Python: define a model object, fit it, and extract the smoothed or filtered states. Interpret the hidden state estimates, not just the fit statistics.
library(KFAS)
model <- SSModel(time_series ~ SSMtrend(1, Q = NA), H = NA)
fit <- fitSSM(model, inits = c(log(1), log(1)))
out <- KFS(fit$model)
out$att
predict(fit$model, n.ahead = 10)
Advantages and Limitations of State Space Models
Like most modeling frameworks, the strengths and the weaknesses come from the same place: you have to commit to a structure upfront.
Advantages: They represent hidden processes explicitly rather than papering over them. They naturally handle systems that change over time. Measurement uncertainty is built into the model, not treated as an afterthought. And the same framework supports filtering, smoothing, and forecasting without changing the model structure.
Limitations: Specifying the model can be hard. You need to decide what the hidden state means and how it evolves, which requires real domain judgment. For nonlinear or non-Gaussian systems, inference gets expensive. And if your assumptions about the dynamics or noise are wrong, the estimates will be wrong in ways that aren't always obvious.
Conclusion
A state space model describes two things: how an unobserved state evolves over time, and how that state produces the observations you can measure. Those are the state equation and the observation equation. Everything else (Kalman filtering, smoothing, prediction) is about inferring the hidden state from the data the model generates.
What I find useful about this framework is that it forces you to be explicit about what you don't know. Rather than modeling the observations directly (as ARIMA does), you're forced to commit to a story about the underlying process. That's a constraint, but it's also a clarification. Once you've written down what you think the hidden state is and how it moves, the inference problem becomes mechanical. The hard part was already the modeling.
If you're coming from classical time-series methods, state space models are worth understanding on their own terms rather than as a generalization of what you already know. Our Time Series with Python course covers the broader toolkit, and if hidden Markov models or Kalman filtering are your next stop, the conceptual foundation here transfers directly.




Picture a ship navigating through fog. Its GPS is noisy, the ocean current is unknown, and the exact position can't be measured directly. It can only be approximated from sensor readings. State space models were built for exactly this kind of problem: systems where the thing you care about is hidden, and all you have access to are imperfect measurements of it.
This article covers the structure of state space models, how to estimate hidden states through filtering and smoothing, where the Kalman filter fits in, and how to implement these models in Python and R.
What Is a State Space Model?
A state space model is a mathematical framework for describing a system that changes over time through states you can't directly observe. Two quantities are at play: the state, which is the true underlying information describing the system at any moment, and the observation, which is the noisy, indirect measurement you actually get.
The model specifies two things: how the hidden state evolves from one time step to the next, and how that hidden state produces the observations you see. That separation is what makes the framework so general. It shows up across signal processing, econometrics, control systems, and machine learning. This happens often without anyone realizing they're all working within the same formal structure.
How State Space Models Work
The core logic follows a simple sequence at each time step:
Previous state → Current state → Observation
The system moves from its previous hidden state to a new one. This transition can include randomness, since real systems aren't perfectly predictable. The new state then generates an observable measurement, which comes with its own noise. You never see the state directly; you see what it produces, imperfectly.
What you can do is use each new observation to update your best estimate of the hidden state. That's the inference problem, and it's what most of the algorithmic machinery around state space models is designed to solve.
Hidden states generate noisy observations over time. Image by Author.
State and Observation Equations
The model's structure comes down to two equations. One for how the state moves, one for what you can measure.
State equation
The state equation describes how the hidden state evolves. In scalar form:
Here, zₜ is the current hidden state, a captures the transition dynamics (how strongly the previous state carries forward), and wₜ is process noise — the randomness in how the system moves. In the matrix formulation for multivariate systems, a becomes a transition matrix, but the idea is identical.
Observation equation
The observation equation connects the hidden state to what you measure:
yₜ is the observed measurement, c defines the observation relationship, and vₜ is measurement noise. Start with scalar versions like these before worrying about the general matrix form. The matrices add generality, not new ideas.
A Simple State Space Model Example
Think of a car moving along a road. Its true position and velocity are the hidden state. You can't observe them directly. What you have is a GPS reading, which is noisy. The state equation models how position and velocity change between time steps (the car keeps moving at roughly the same speed). The observation equation connects the true position to the GPS reading, which might be off by several meters.
A good visualization of this shows three lines: the true position (smooth), the GPS readings (scattered around the truth), and the estimated position from the model (close to the truth, somewhat smoother than the raw GPS). Getting that third line is the model's whole job.
How States Are Estimated
Defining the model is only half the problem. You also need to infer the hidden states from the observations you actually have. Three tasks cover the space:
Filtering estimates the current state using only observations up to right now — real-time inference, useful for tracking and control. Smoothing goes back and revises those estimates using observations from both before and after a given point — generally more accurate, but it requires the full sequence. Prediction extrapolates forward to estimate future states before observations arrive.
Most applications use filtering. Smoothing comes up when you're doing retrospective analysis and accuracy matters more than speed.
Kalman Filtering and State Space Models
The Kalman filter is the algorithm for filtering in linear Gaussian state space models. Worth being precise here: the state space model is the model; the Kalman filter is one inference method that applies to a specific class of those models.
The filter works in two alternating steps. In the prediction step, it uses the state equation to project the current estimate forward in time, along with a measure of how uncertain that estimate is. In the update step, a new observation arrives and the estimate is corrected. How much it shifts depends on the relative uncertainty of the prediction versus the measurement. If the model's prediction is reliable, the observation has less influence. If the GPS signal is clean and the model is uncertain, the observation dominates. That uncertainty-weighted blending is what makes the Kalman filter work in practice.
Extensions exist for nonlinear or non-Gaussian settings: the extended Kalman filter linearizes the dynamics, the unscented Kalman filter uses a smarter approximation, and particle filters handle the fully general case by sampling. Those are different articles.
Types of State Space Models
The framework covers a range of settings depending on what you're willing to assume about the dynamics and noise.
Linear Gaussian state space models are the classical setting: linear transition and observation equations, Gaussian noise. Kalman filtering applies directly and exact inference is tractable.
Nonlinear state space models arise when the state transition or observation relationship isn't linear — think a pendulum, or a model where price effects taper off. Exact inference is no longer available.
Non-Gaussian state space models drop the assumption that noise follows a normal distribution. Count data, binary outcomes, and heavy-tailed processes all fall here.
State Space Models vs. Related Time-Series Models
A few comparisons worth making explicit, since the boundaries here are blurrier than they first appear.
State space models vs. ARIMA
ARIMA models the observed values and their past errors directly, without introducing any hidden state. State space models bring in latent states explicitly. That said, ARIMA models can be reformulated in state space form — so the two aren't as separate as they first appear, and software often uses state space representations internally to fit ARIMA anyway.
State space models vs. hidden Markov models
Both involve hidden states. Classical HMMs use discrete latent states (the system is in one of k modes), while most state space models use continuous ones. For speech recognition, discrete modes make sense; for tracking a physical object, continuous states are the natural choice.
State space models vs. structural time-series models
Structural time-series models (which decompose a series into trend, seasonality, and irregular components) are typically formulated as state space models rather than competing with them. They're a specific use case of the framework.
State Space Models in Python and R
The workflow is similar in both languages — define the model, fit it, and pull out the hidden state estimates.
State space models in Python
The
statsmodelslibrary offers a clean interface for fitting state space models. Here's a local level model (the simplest structural model, with a random walk state and noisy observations) fit to some time-series data:The filtered state gives you the model's best estimate of the hidden level at each point in time. That's the main output you care about, not the parameters themselves.
State space models in R
In R, the
KFASpackage handles Gaussian state space models and is worth knowing if you work in this space regularly. The workflow mirrors Python: define a model object, fit it, and extract the smoothed or filtered states. Interpret the hidden state estimates, not just the fit statistics.Advantages and Limitations of State Space Models
Like most modeling frameworks, the strengths and the weaknesses come from the same place: you have to commit to a structure upfront.
Advantages: They represent hidden processes explicitly rather than papering over them. They naturally handle systems that change over time. Measurement uncertainty is built into the model, not treated as an afterthought. And the same framework supports filtering, smoothing, and forecasting without changing the model structure.
Limitations: Specifying the model can be hard. You need to decide what the hidden state means and how it evolves, which requires real domain judgment. For nonlinear or non-Gaussian systems, inference gets expensive. And if your assumptions about the dynamics or noise are wrong, the estimates will be wrong in ways that aren't always obvious.
Conclusion
A state space model describes two things: how an unobserved state evolves over time, and how that state produces the observations you can measure. Those are the state equation and the observation equation. Everything else (Kalman filtering, smoothing, prediction) is about inferring the hidden state from the data the model generates.
What I find useful about this framework is that it forces you to be explicit about what you don't know. Rather than modeling the observations directly (as ARIMA does), you're forced to commit to a story about the underlying process. That's a constraint, but it's also a clarification. Once you've written down what you think the hidden state is and how it moves, the inference problem becomes mechanical. The hard part was already the modeling.
If you're coming from classical time-series methods, state space models are worth understanding on their own terms rather than as a generalization of what you already know. Our Time Series with Python course covers the broader toolkit, and if hidden Markov models or Kalman filtering are your next stop, the conceptual foundation here transfers directly.