
{count, plural, other {课程}}
使用 OpenAI API
{hours} 小时
181.3K
在开始微调 GPT-4o Mini 模型之前,我们建议先了解提示工程、提示链以及函数调用,以便自定义模型回复并获得特定领域的答案。
当您需要调整风格、语气或格式时,微调就变得必要。它用于提升可靠性与准确性、处理复杂提示,或执行提示工程无法实现的新任务。
在本教程中,我们将微调 GPT-4o Mini 模型,将文本分类为“有压力”和“无压力”标签。随后,我们将通过 OpenAI API 和 OpenAI Playground 访问该微调模型。最后,我们将使用多种分类指标,对比微调前后的性能,对微调模型进行评估。
作者制图
GPT-4o Mini 是目前最具性价比的通用大语言模型。它在 MMLU 上得分 82%,并且在 LMSYS 排行榜的聊天偏好上目前优于Claude 3.5 Sonnet。其价格为每百万输入 Token 0.15 美元、每百万输出 Token 0.60 美元,比 GPT-3.5 Turbo 便宜 60%。
GPT-4o mini 目前支持文本和图像输入。模型的上下文窗口为 128K Token,每次请求最多支持 16K 输出 Token,知识截至 2023 年 10 月。由于使用 GPT-4o 的分词器,GPT-4o Mini 也能处理非英语文本。我们以低成本兼得两全之利。
要了解 GPT-4o Mini 的使用场景、聊天补全 API 与详细基准测试,请阅读我们的博客什么是 GPT-4o Mini?
前往OpenAI 网站并创建账户。微调成本较高,通过 API 使用 GPT-4o Mini 需要在账户中绑定支付方式。为避免中断,请在尝试微调模型之前,确保账户中至少有 10 美元的余额。
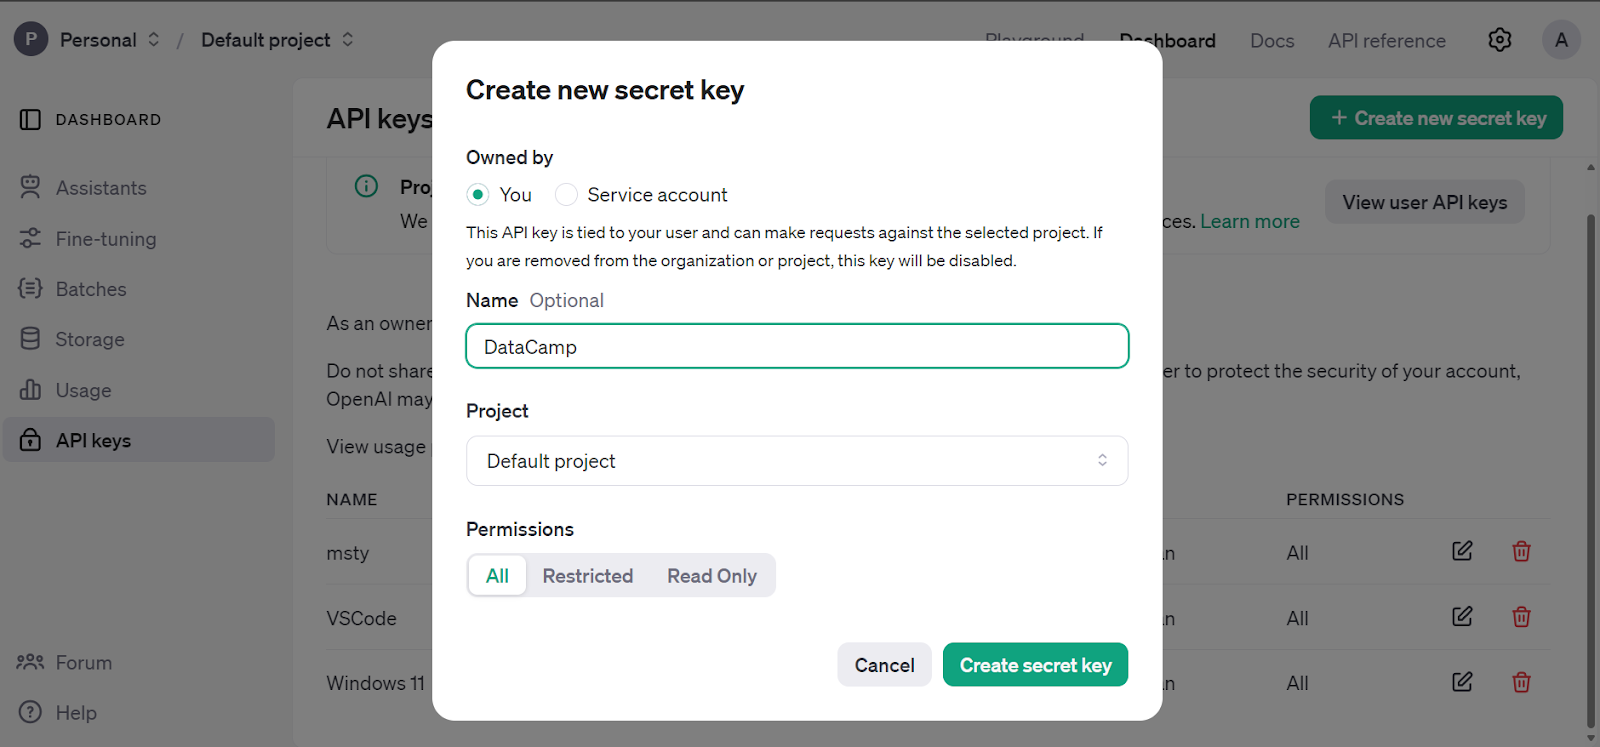
进入主控制台,点击“API keys”选项卡,生成 OpenAI API 密钥。
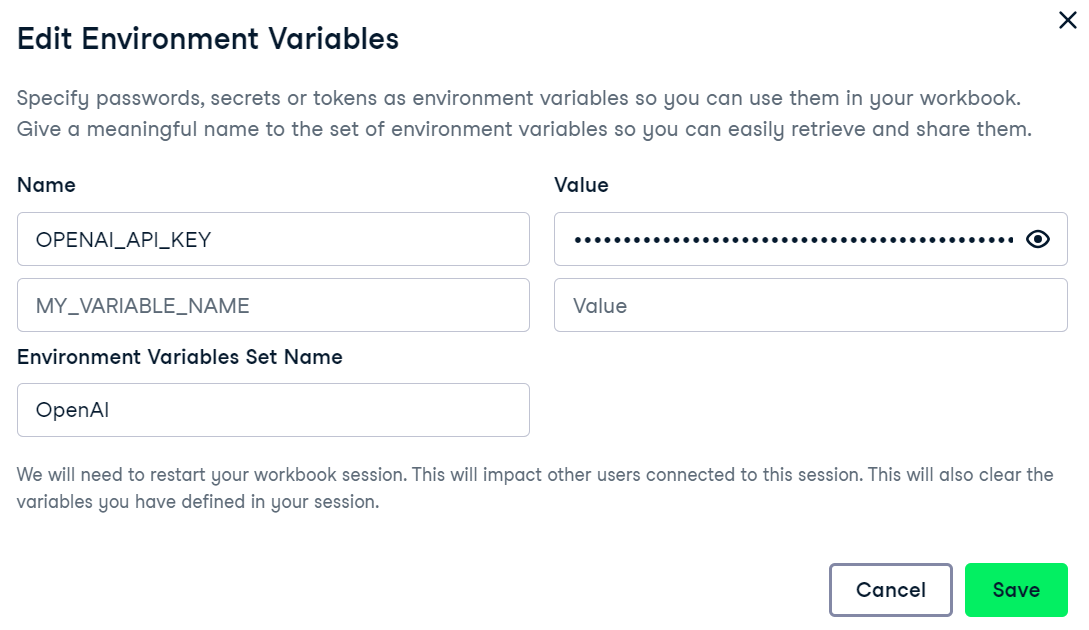
我们使用 DataCamp 的DataLab 作为代码编辑器。要设置 OpenAI API 密钥的环境变量,请进入 Environment 选项卡并点击环境变量选项。然后添加用于保存 API Key 的环境变量并按下图所示启用。
安装 OpenAI 的 Python 包以访问 GPT-4o Mini。
%%capture
%pip install openai
使用 OpenAI API 密钥创建客户端,并用示例提示生成回复。聊天补全函数需要提供模型名称和以字典列表形式组织的消息。
from IPython.display import Markdown, display
from openai import OpenAI
import os

openai_api_key = os.environ["OPENAI_API_KEY"]

client = OpenAI(api_key=openai_api_key)

response = client.chat.completions.create(
  model="gpt-4o-mini",
  messages=[
    {"role": "system", "content": "You are a great philosopher."},
    {"role": "user", "content": "What is the meaning of life?"}
  ]
)
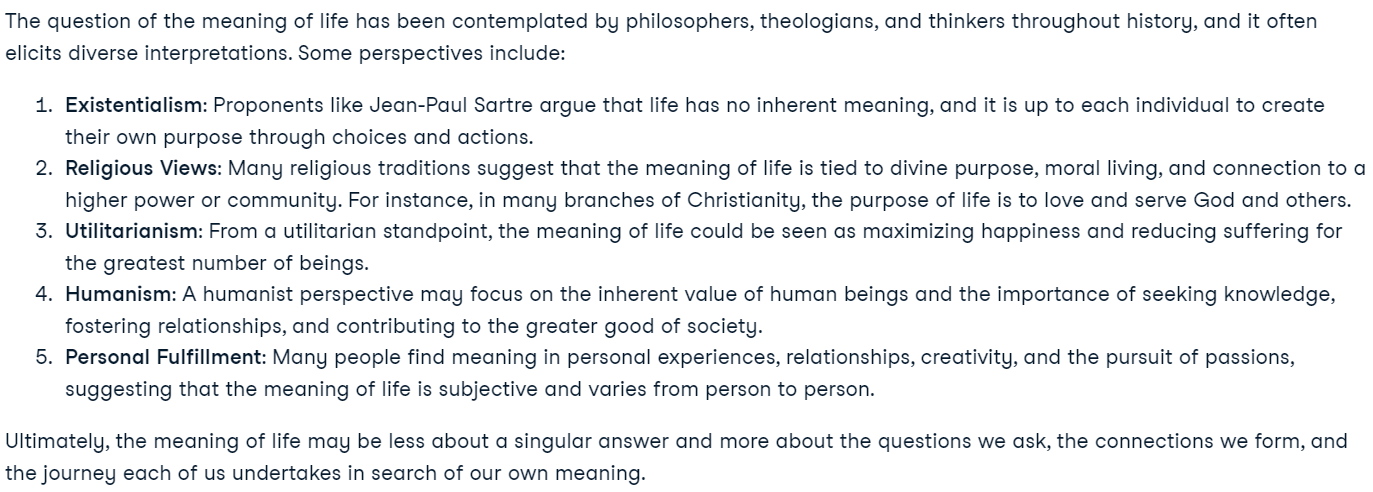
display(Markdown(response.choices[0].message.content))
OpenAI API 已全部就绪,我们可以开始发起微调任务。
刚接触 OpenAI 的 API?您可以参考这篇简单且详细的教程GPT-4o API 教程:OpenAI API 入门,了解如何用几行代码访问最前沿的模型。
本节中,我们将基于 Kaggle 的Stress Detection from the Social Media Articles 数据集来微调 GPT-4o Mini。该数据集包含来自 Reddit 和 Twitter 的帖子,并将其分类为有压力与无压力两类。
现在我们来加载并处理数据集。
注意:请确保数据集格式正确,应包含系统提示、用户查询与响应。响应即为标签。
import pandas as pd
import json
from sklearn.model_selection import train_test_split

# Load the CSV file with the correct delimiter
file_path = 'Reddit_Title.csv'  # Change this to your local path
data = pd.read_csv(file_path, sep=';')

# Clean up and drop unnecessary columns, and select the top 200 rows
data_cleaned = data[['title', 'label']].head(200)

# Mapping the 'label' column to more human-readable text
label_mapping = {0: "non-stress", 1: "stress"}
data_cleaned['label'] = data_cleaned['label'].map(label_mapping)

# Split the data into training and validation sets (80% train, 20% validation)
train_data, validation_data = train_test_split(data_cleaned, test_size=0.2, random_state=42)

def save_to_jsonl(data, output_file_path):
    jsonl_data = []
    for index, row in data.iterrows():
        jsonl_data.append({
            "messages": [
                {"role": "system", "content": "Given a social media post, classify whether it indicates 'stress' or 'non-stress'."},
                {"role": "user", "content": row['title']},
                {"role": "assistant", "content": f"\"{row['label']}\""}
            ]
        })

    # Save to JSONL format
    with open(output_file_path, 'w') as f:
        for item in jsonl_data:
            f.write(json.dumps(item) + '\n')

# Save the training and validation sets to separate JSONL files
train_output_file_path = 'stress_detection_train.jsonl'
validation_output_file_path = 'stress_detection_validation.jsonl'

save_to_jsonl(train_data, train_output_file_path)
save_to_jsonl(validation_data, validation_output_file_path)

print(f"Training dataset save to {train_output_file_path}")
print(f"Validation dataset save to {validation_output_file_path}")输出:
Training dataset save to stress_detection_train.jsonl
Validation dataset save to stress_detection_validation.jsonl接下来,我们将使用 OpenAI 客户端上传训练集与验证集,以用于微调。
train_file = client.files.create(
  file=open(train_output_file_path, "rb"),
  purpose="fine-tune"
)

valid_file = client.files.create(
  file=open(validation_output_file_path, "rb"),
  purpose="fine-tune"
)

print(f"Training file Info: {train_file}")
print(f"Validation file Info: {valid_file}")
OpenAI API 会先验证数据集,然后上传并生成用于微调模型的元数据。
Training file Info: FileObject(id='file-b2lo2chod6xuMhYg9JcEsnp6', bytes=48563, created_at=1727133513, filename='stress_detection_train.jsonl', object='file', purpose='fine-tune', status='processed', status_details=None)
Validation file Info: FileObject(id='file-Fae0AVSUhTGr49qhQz8d2yyp', bytes=12284, created_at=1727133514, filename='stress_detection_validation.jsonl', object='file', purpose='fine-tune', status='processed', status_details=None)
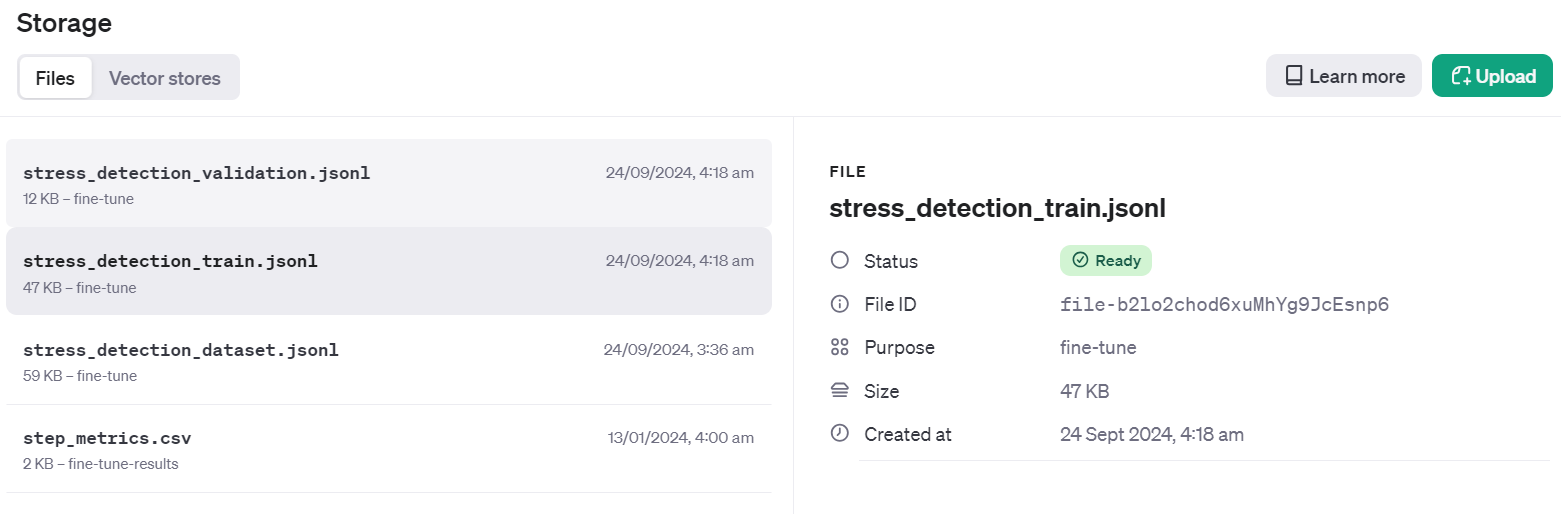
要检查数据集是否已成功推送到云端,请进入控制台并点击“Storage”选项卡。您将看到两个文件,已准备就绪可供使用。
使用客户端 API 创建微调任务。微调函数需要训练数据集文件 ID、验证数据集文件 ID、模型名称和超参数。我们将训练 3 个 epoch。若要进一步提升性能,您可以使用完整数据集并至少训练 5 个 epoch。
model = client.fine_tuning.jobs.create(
  training_file=train_file.id,
  validation_file=valid_file.id,
  model="gpt-4o-mini-2024-07-18",
  hyperparameters={
    "n_epochs": 3,
	"batch_size": 3,
	"learning_rate_multiplier": 0.3
  }
)
job_id = model.id
status = model.status

print(f'Fine-tuning model with jobID: {job_id}.')
print(f"Training Response: {model}")
print(f"Training Status: {status}")
运行该函数后,微调任务将启动并显示日志。
Fine-tuning model with jobID: ftjob-rgIMFxZSsWDqCNfOev54e4Jq.
Training Response: FineTuningJob(id='ftjob-rgIMFxZSsWDqCNfOev54e4Jq', created_at=1727135628, error=Error(code=None, message=None, param=None), fine_tuned_model=None, finished_at=None, hyperparameters=Hyperparameters(n_epochs=3, batch_size=3, learning_rate_multiplier=0.3), model='gpt-4o-mini-2024-07-18', object='fine_tuning.job', organization_id='org-jLXWbL5JssIxj9KNgoFBK7Qi', result_files=[], seed=748607710, status='validating_files', trained_tokens=None, training_file='file-b2lo2chod6xuMhYg9JcEsnp6', validation_file='file-Fae0AVSUhTGr49qhQz8d2yyp', estimated_finish=None, integrations=[], user_provided_suffix=None)
Training Status: validating_files
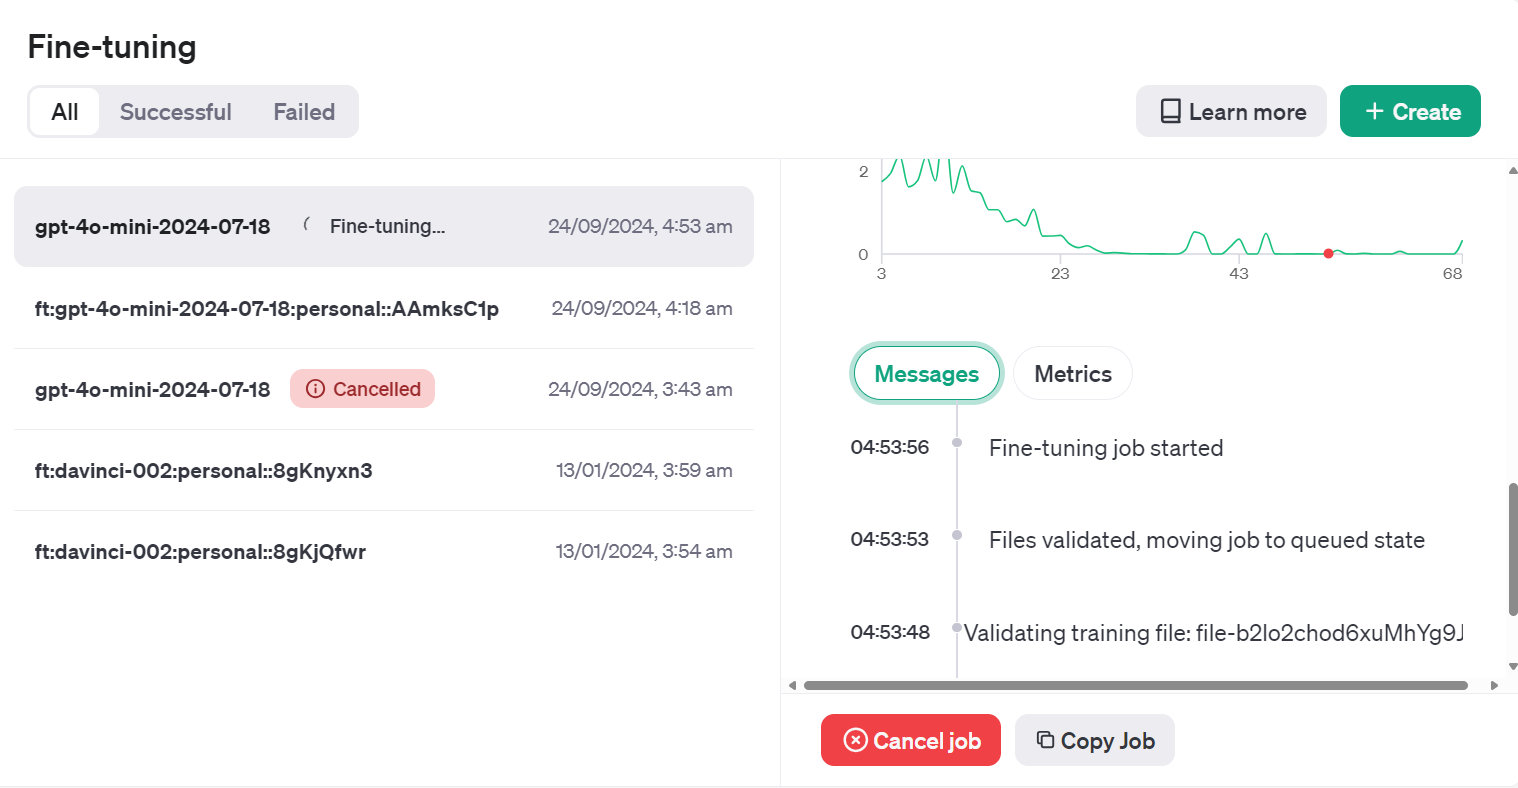
我们可以在控制台查看微调任务状态:点击“Fine-tuning”选项卡并进入对应的 Job ID。
也可以使用 jobs.retrieve 函数检查微调任务状态。
# Retrieve the state of a fine-tune
client.fine_tuning.jobs.retrieve(job_id)
输出:
FineTuningJob(id='ftjob-rgIMFxZSsWDqCNfOev54e4Jq', created_at=1727135628, error=Error(code=None, message=None, param=None), fine_tuned_model=None, finished_at=None, hyperparameters=Hyperparameters(n_epochs=3, batch_size=3, learning_rate_multiplier=0.3), model='gpt-4o-mini-2024-07-18', object='fine_tuning.job', organization_id='org-jLXWbL5JssIxj9KNgoFBK7Qi', result_files=[], seed=748607710, status='running', trained_tokens=None, training_file='file-b2lo2chod6xuMhYg9JcEsnp6', validation_file='file-Fae0AVSUhTGr49qhQz8d2yyp', estimated_finish=1727135943, integrations=[], user_provided_suffix=None)如果您发现损失没有下降,可以使用 jobs.cancel 函数取消任务。
# Cancel a job
client.fine_tuning.jobs.cancel(job_id)
当微调任务完成后,您将收到一封电子邮件,通知微调模型已可以使用。
要访问微调模型,我们需要获得其名称。为此,我们将获取所有微调任务的信息,选择最新的一个,然后取出模型名称。
result = client.fine_tuning.jobs.list()

# Retrieve the fine tuned model
fine_tuned_model = result.data[0].fine_tuned_model
print(fine_tuned_model)
这是我们的微调模型名称。
ft:gpt-4o-mini-2024-07-18:personal::AAnFfX5q通过向聊天补全函数提供微调模型名称、包含正确系统提示的消息以及数据集中的一个样本来生成回复。
completion = client.chat.completions.create(
  model = fine_tuned_model,
  messages=[
    {"role": "system", "content": "Given a social media post, classify whether it indicates 'stress' or 'non-stress'."},
    {"role": "user", "content": "Just went to my first homecoming, and they played a song I've always wanted to dance to at an official dance. Sorry for the terrible quality, but my happiness in this moment couldn't be exaggerated!"}
  ]
)
print(completion.choices[0].message.content)
成功!我正确预测出了标签。
"non-stress"如果您对模型不满意,可以使用以下命令删除它。我们暂时不会删除,因为还需要进行额外的模型评估。
# Delete a fine-tuned model (must be an owner of the org the model was created in)
client.models.delete(fine_tuned_model)还有一种方式可以访问微调模型,并更高效地在各种提示上进行测试。
前往 OpenAI 控制台,点击“Fine-tuning”选项卡,选择最近运行的任务,然后点击右下角的“Playground”按钮。
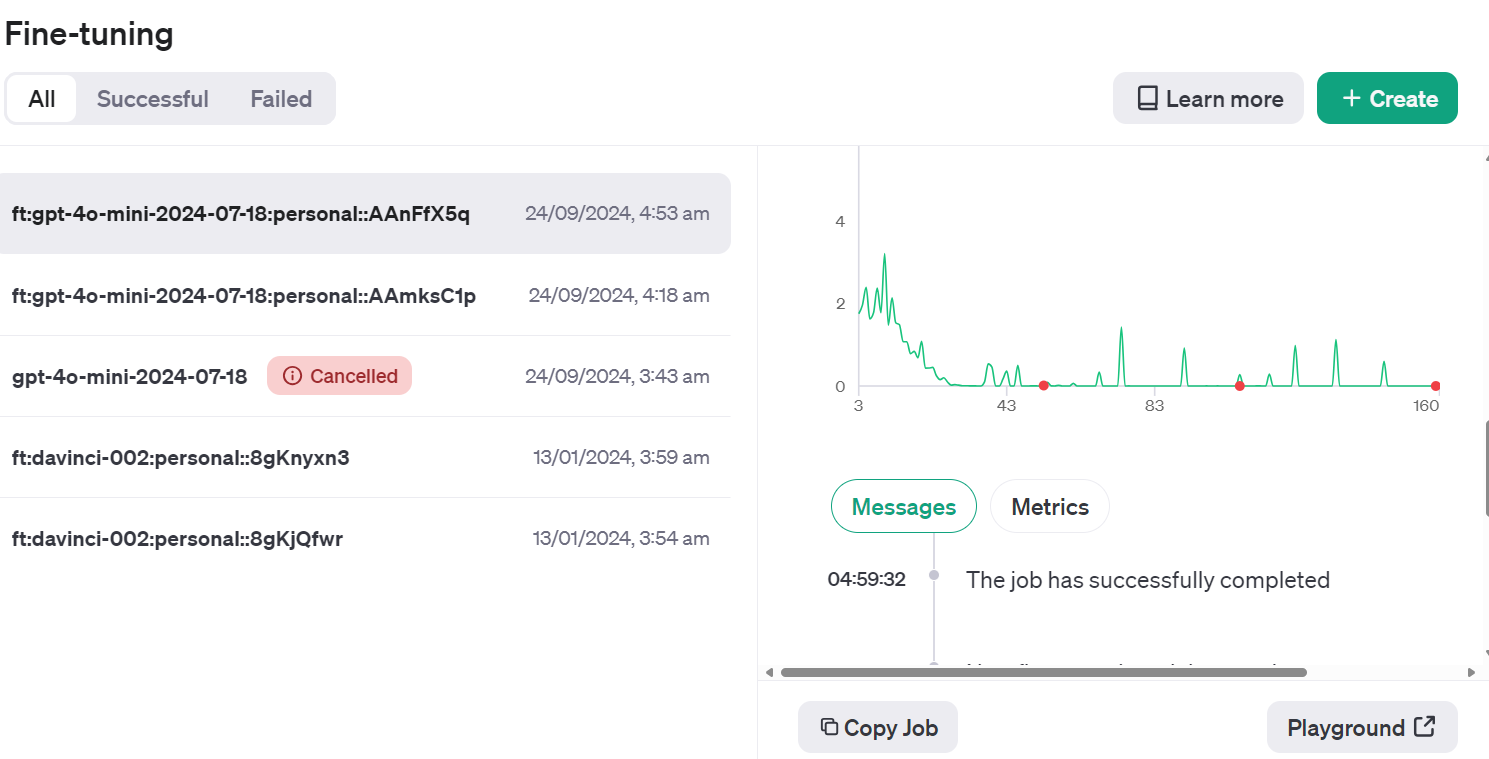
它将带您进入聊天机器人应用。在那里,您可以提供系统提示并开始输入样例 Reddit 帖子。
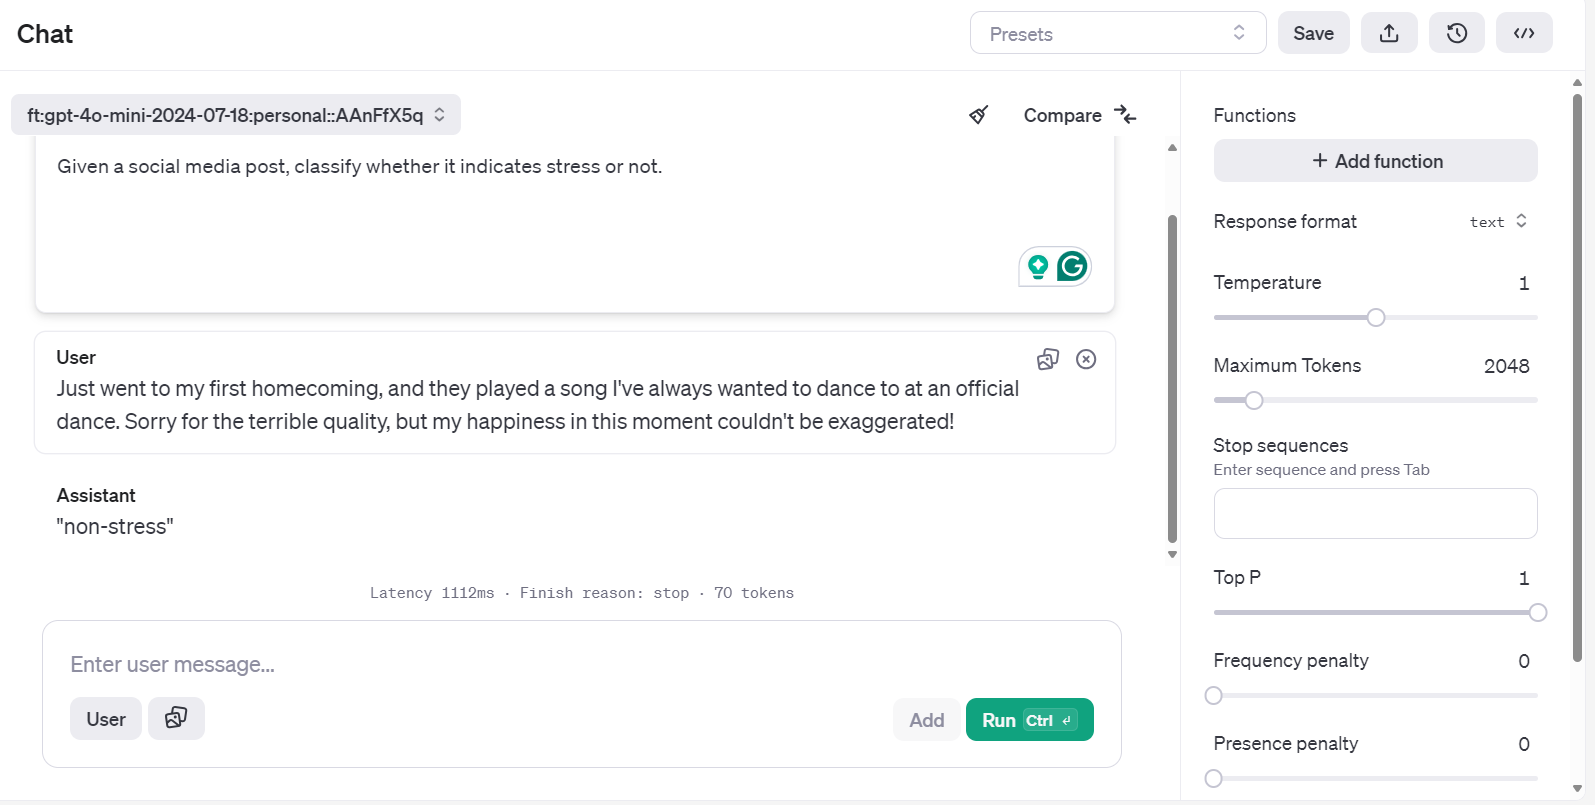
您甚至可以运行相同的提示,并与另一模型进行对比分析。
我们已经完成了模型微调,并认为效果不错。但您是否考虑过,基础模型一开始是否就已经更好?我们尚未做详细的前后对比。
本节中,我们将使用验证数据分别用基础模型与微调模型进行标签预测。我们将基于准确率、分类报告与混淆矩阵对两种模型进行比较。
创建一个 predict 函数,输入数据集与模型名称,生成预测标签列表。它使用相同的系统消息与数据集中的帖子标题。
def predict(test, model):
    y_pred = []
    categories = ["non-stress", "stress"]

    for index, row in test.iterrows():
        response = client.chat.completions.create(
            model=model,
            messages=[
                {
                    "role": "system",
                    "content": "Given a social media post, classify whether it indicates 'stress' or 'non-stress'.",
                },
                {"role": "user", "content": row["title"]},
            ],
        )

        answer = response.choices[0].message.content

        # Determine the predicted category

        for category in categories:
            if category.lower() in answer.lower():
                y_pred.append(category)
                break
        else:
            y_pred.append("none")
    return y_pred
随后,我们将创建 evaluate 函数,利用预测标签与真实标签生成准确率、分类报告与混淆矩阵。
from sklearn.metrics import accuracy_score, classification_report, confusion_matrix
import numpy as np


def evaluate(y_true, y_pred):
    labels = ["non-stress", "stress"]
    mapping = {label: idx for idx, label in enumerate(labels)}

    def map_func(x):
        return mapping.get(
            x, -1
        )  # Map to -1 if not found, but should not occur with correct data

    y_true_mapped = np.vectorize(map_func)(y_true)
    y_pred_mapped = np.vectorize(map_func)(y_pred)

    # Calculate accuracy

    accuracy = accuracy_score(y_true=y_true_mapped, y_pred=y_pred_mapped)
    print(f"Accuracy: {accuracy:.3f}")

    # Generate accuracy report

    unique_labels = set(y_true_mapped)  # Get unique labels

    for label in unique_labels:
        label_indices = [
            i for i in range(len(y_true_mapped)) if y_true_mapped[i] == label
        ]
        label_y_true = [y_true_mapped[i] for i in label_indices]
        label_y_pred = [y_pred_mapped[i] for i in label_indices]
        label_accuracy = accuracy_score(label_y_true, label_y_pred)
        print(f"Accuracy for label {labels[label]}: {label_accuracy:.3f}")
    # Generate classification report

    class_report = classification_report(
        y_true=y_true_mapped,
        y_pred=y_pred_mapped,
        target_names=labels,
        labels=list(range(len(labels))),
    )
    print("\nClassification Report:")
    print(class_report)

    # Generate confusion matrix

    conf_matrix = confusion_matrix(
        y_true=y_true_mapped, y_pred=y_pred_mapped, labels=list(range(len(labels)))
    )
    print("\nConfusion Matrix:")
    print(conf_matrix)
将验证数据集与基础模型名称传入 predict 函数。然后将预测标签与真实标签传入 evaluate 函数,生成模型评估报告。
y_pred = predict(validation_data, "gpt-4o-mini-2024-07-18")
y_true = validation_data["label"]
evaluate(y_true, y_pred)
我们的基础模型在文本分类方面表现相当不错,达到了 92.5% 的准确率。
Accuracy: 0.925
Accuracy for label non-stress: 0.947
Accuracy for label stress: 0.905

Classification Report:
              precision    recall  f1-score   support

  non-stress       0.90      0.95      0.92        19
      stress       0.95      0.90      0.93        21

    accuracy                           0.93        40
   macro avg       0.93      0.93      0.92        40
weighted avg       0.93      0.93      0.93        40


Confusion Matrix:
[[18  1]
[ 2 19]]让我们用微调模型名称调用 predict 函数生成压力标签。随后使用预测与真实标签生成详细的模型评估报告。
fine_tuned_model = "ft:gpt-4o-mini-2024-07-18:personal::AAnFfX5q"

y_pred = predict(validation_data,fine_tuned_model)
evaluate(y_true, y_pred)
我们的模型性能有所提升。准确率达到 97.5%,提升显著。
Accuracy: 0.975
Accuracy for label non-stress: 1.000
Accuracy for label stress: 0.952

Classification Report:
              precision    recall  f1-score   support

  non-stress       0.95      1.00      0.97        19
      stress       1.00      0.95      0.98        21

    accuracy                           0.97        40
   macro avg       0.97      0.98      0.97        40
weighted avg       0.98      0.97      0.98        40


Confusion Matrix:
[[19  0]
 [ 1 20]]
针对特定任务进行微调可以显著提升准确率。以上只是一个示例测试,但在真实项目中,微调通常能提升模型在分类任务、风格化与结构化输出方面的准确性与表现。
如果您在运行上述代码时遇到问题,请参考 DataLab 工作区:微调 GPT-4 Mini。
您的下一步是使用该微调模型创建一款完整的 AI 应用。您可以通过以下代码练习来学习:使用 GPT-4o 创建 AI 助手。
在本教程中,我们成功地微调了 GPT-4o Mini 模型,将文本分类为“有压力”和“无压力”标签。随后,我们通过 OpenAI API 和 OpenAI Playground 访问该微调模型,便于实践应用与进一步测试。
对微调模型的评估带来了有价值的结果:与基础模型相比,各项指标均显示出分类性能的提升。这一过程凸显了微调在实现更可靠、更准确输出方面的价值,尤其是在文本分类等任务中。
如果您正在寻找免费、开源的模型,我们还有一篇非常不错的教程:微调 Llama 3.2 并在本地使用:一步步指南。在该指南中,我们将向您展示如何微调最新的 Llama 模型,并将其转换为 GGUF 格式,以便在您的笔记本电脑上本地运行。
DataCamp OpenAI 精品课程
{count, plural, other {课程}}
{count, plural, other {课程}}
{count, plural, other {课程}}