

检索增强生成(RAG)如何工作?
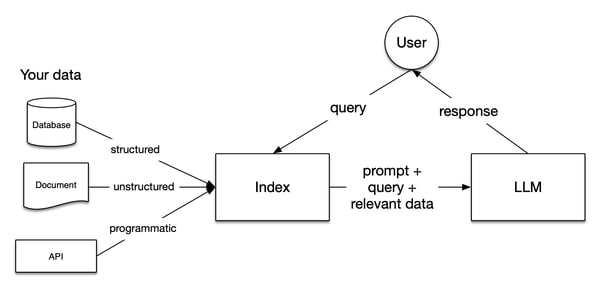
图片来源:LlamaIndex 文档
检索增强生成(RAG)流水线通常包含三个步骤:索引、检索与生成。
索引
要让 LLM 产出准确且具备上下文意识的答案,索引是基础。首先,需要从不同文件格式(如 Word 文档、PDF、HTML)中抽取并清洗数据。完成清洗后,将其转换为标准的纯文本。为缓解 LLM 的上下文长度限制,会把文本切分为更小的片段(Chunking)。随后,使用嵌入模型将每个片段转换为数值向量(embedding)。最后,构建索引,以键值对的形式存储片段及其对应的向量。
检索
在检索阶段,用户查询同样会用相同的嵌入模型转换为向量表示。然后计算查询向量与各片段向量之间的相似度分数,系统检索与用户查询最相似的前 K 个片段。
生成
将用户查询与检索到的片段填入提示模板。上述步骤得到的增强提示最终作为输入送入 LLM。
RAG 的局限性
在构建 RAG 系统时,前述三个步骤都可能遇到显著挑战,例如:
- 索引:RAG 的效果高度依赖数据质量。如果外部数据源噪声多于信息量,LLM 生成的回答将乏善可陈。
- 检索:取决于您的文件类型与 RAG 系统设置,系统未必总能检索到有助于回答用户问题的片段。
- 生成:即使 RAG 设置合理,LLM 仍可能基于“想象事实”生成不正确答案。
下面我们将探讨规避这些局限性的策略。本文将讨论三大方向:分块(Chunking)、重排序(Re-Ranking)与查询变换(Query Transformations)。此外,我们将通过使用 LlamaIndex 与 OpenAI API 构建一个针对维基百科条目的问答 RAG 系统,展示这些策略如何帮助提升 RAG 表现。一起深入了解!
搭建基线 RAG 系统
在探索改进 RAG 系统表现的技巧之前,我们需要先建立一个简单的 RAG 流水线作为基线。先安装 llama-index 与 openai 包。
!pip install llama-index
!pip install openaiLlamaIndex 是一个面向大型语言模型(LLM)应用的数据框架。它支持摄取多种外部数据源、构建检索增强生成(RAG)系统,并将与其他 LLM 的集成抽象为少量代码。此外,它还提供多种技术来帮助使用 LLM 生成更准确的输出。
默认情况下,它使用 OpenAI 的 gpt-3.5-turbo 模型进行文本生成,使用 text-embedding-ada-002 模型进行检索与嵌入。要使用这些模型,需在 OpenAI 平台创建免费账户并获取 OpenAI API 密钥。获取方式请参见OpenAI API 文档。
import os
os.environ["OPENAI_API_KEY"] = "YOUR_OPENAI_API_KEY"现在我们已经安装好相关包,将构建一个基于 Emma Stone、Ryan Gosling 与《爱乐之城》维基百科页面进行问答的 RAG 系统。首先,安装用于抽取维基百科页面的 wikipedia 库:
!pip install wikipedia然后,便可轻松从维基百科下载数据:
# Import packages
from llama_index.core import (VectorStoreIndex,ServiceContext, download_loader)
# Download the documents from Wikipedia and load them
WikipediaReader = download_loader("WikipediaReader")
loader = WikipediaReader()
pages = ['Emma_Stone', 'La_La_Land', 'Ryan_Gosling']
documents = loader.load_data(pages=pages, auto_suggest=False, redirect = False)数据抽取完成后,我们将文档按 256 个字符、无重叠进行切分。随后,这些片段会通过嵌入模型转换为数值向量,并在向量存储中建立索引。
# Initialize the gpt3.5 model
gpt3 = OpenAI(temperature=0, model="gpt-3.5-turbo-instruct", api_key=OPENAI_API_KEY)
# Initialize the embedding model
embed_model = OpenAIEmbedding(model= OpenAIEmbeddingModelType.TEXT_EMBED_ADA_002, api_key=OPENAI_API_KEY)
# Transform chunks into numerical vectors using the embedding model
service_context_gpt3 = ServiceContext.from_defaults(llm=gpt3, chunk_size = 256, chunk_overlap=0, embed_model=embed_model)
index = VectorStoreIndex.from_documents(documents, service_context=service_context_gpt3)
retriever = index.as_retriever(similarity_top_k=3)为降低幻觉风险,我们使用 PromptTemplate 模块,确保 LLM 的回答仅基于所提供的上下文。
from llama_index.core.prompts import PromptTemplate
# Build a prompt template to only provide answers based on the loaded documents
template = (
"We have provided context information below. \n"
"---------------------\n"
"{context_str}"
"\n---------------------\n"
"Given this information, please answer the question: {query_str}\n"
"Don't give an answer unless it is supported by the context above.\n"
)
qa_template = PromptTemplate(template)现在我们已经搭建好 RAG 系统,可以基于检索的文档进行提问测试。开始验证吧!
查询 1:“让 Emma Stone 首次赢得奥斯卡奖的那部电影的剧情是什么?”
这个问题具有挑战性,因为它要求模型关注多条信息:
- 让 Emma Stone 首次赢得奥斯卡奖的电影名称(此处为《爱乐之城》)
- 该电影的剧情。
# Create a prompt for the model
question = "What is the plot of the film that led Emma Stone to win her first Academy Award?"
# Retrieve the context from the model
contexts = retriever.retrieve(question)
context_list = [n.get_content() for n in contexts]
prompt = qa_template.format(context_str="\n\n".join(context_list), query_str=question)
# Generate the response
response = gpt3.complete(prompt)
print(str(response))输出:
The plot of the film that made Emma Stone win her first Academy Award is not explicitly mentioned in the provided context.查询 2:“比较 Emma Stone 与 Ryan Gosling 的家庭”
这一问题比上一个更难,因为它要求选择与两位演员家庭相关的片段。
# Create a prompt for the model
question = "Compare the families of Emma Stone and Ryan Gosling"
# Retrieve the context from the model
contexts = retriever.retrieve(question)
context_list = [n.get_content() for n in contexts]
prompt = qa_template.format(context_str="\n\n".join(context_list), query_str=question)
# Generate the response
response = gpt3.complete(prompt)
print(str(response))我们得到如下输出:
Based on the context provided, it is not possible to compare the families of Emma Stone and Ryan Gosling as the information focuses on their professional collaboration and experiences while working on the film "La La Land." There is no mention of their personal family backgrounds or relationships in the context provided.如您所见,这两次回答的质量都不理想。接下来,我们来看看如何提升该 RAG 系统的表现!
通过调整分块大小提升 RAG 表现
我们可以先自定义分块大小与分块重叠。如前所述,文档会被切分成带有特定重叠的片段。LlamaIndex 默认使用 1024 作为分块大小、20 作为分块重叠。此外,系统默认检索前 2 个片段。
例如,我们可以将分块大小设为 512、分块重叠设为 50,并增加检索的片段数量:
# modify default values of chunk size and chunk overlap
service_context_gpt3 = ServiceContext.from_defaults(llm=gpt3, chunk_size = 512, chunk_overlap=50, embed_model=embed_model)
# build index
index = VectorStoreIndex.from_documents(
documents, service_context=service_context_gpt3
)
# returns the engine for the index
query_engine = index.as_query_engine(similarity_top_k=4)查询 1:“让 Emma Stone 首次赢得奥斯卡奖的那部电影的剧情是什么?”
# generate the response
response = query_engine.query("What is the plot of the film that led Emma Stone to win her first Academy Award?")
print(response)输出:
The film that made Emma Stone win her first Academy Award is a romantic musical called La La Land.相较之前回答,这次略有改进。它正确识别出《爱乐之城》是让 Emma Stone 首获奥斯卡的电影,但仍未描述其剧情。
查询 2:“比较 Emma Stone 与 Ryan Gosling 的家庭”
# generate the response
response = query_engine.query("Compare the families of Emma Stone and Ryan Gosling")
print(response)输出:
Emma Stone has expressed her close relationship with her family and mentioned being blessed with great family and people around her. She has also shared about her mother's battle with breast cancer and their celebration by getting matching tattoos. On the other hand, there is no specific information provided about Ryan Gosling's family or his personal relationships in the context.同样,RAG 流水线的输出有所改进,但仍未覆盖 Ryan Gosling 家庭的相关信息。
通过重排序提升 RAG 表现
随着数据集规模与复杂度增长,为复杂查询筛选并返回相关信息变得尤为关键。为此,可以使用一类称为“重排序”的技术来判断文本中哪些片段更重要。它们会对文档进行重排与过滤,将最相关的排在前面。
重排序的两种主要方法:
- 使用重排序模型替代嵌入模型:它们以查询与上下文为输入,返回相似度分数而非嵌入向量
- 使用 LLM更高效地捕捉文档中的语义信息。
在应用这些重排序方法前,我们先评估一下基线 RAG 系统在第二个查询下返回的前三个片段:
# Retrieve the top three chunks for the second query
retriever = index.as_retriever(similarity_top_k=3)
query = "Compare the families of Emma Stone and Ryan Gosling"
nodes = retriever.retrieve(query)
# Print the chunks
for node in nodes:
print('----------------------------------------------------')
display_source_node(node, source_length = 500)这是重排序前的输出;每个片段都有一个带相似度分数的 Node ID。
Node ID: 9b3817fe-3a3f-4417-83d2-2e2996c8b468
Similarity: 0.8415899563985404
Text: Emily Jean "Emma" Stone (born November 6, 1988) is an American actress and producer. She is the recipient of various accolades, including two Academy Awards, two British Academy Film Awards, and two Golden Globe Awards. In 2017, she was the world's highest-paid actress and named by Time magazine as one of the 100 most influential people in the world. Born and raised in Scottsdale, Arizona, Stone began acting as a child in a theater production of The Wind in the Willows in 2000. As a teenager,...
----------------------------------------------------
Node ID: 1bef0308-8b0f-4f7e-9cd6-92ce5acf811f
Similarity: 0.831147173341674
Text: Coincidentally, Gosling turned down the Beast role in Beauty and the Beast in favor of La La Land. Chazelle subsequently decided to make his characters somewhat older, with experience in struggling to make their dreams, rather than younger newcomers just arriving in Los Angeles. Emma Stone plays Mia, an aspiring actress in Los Angeles. Stone has loved musicals since she saw Les Misérables when she was eight years old. She said "bursting into song has always been a real dream of mine", and her ...
----------------------------------------------------
Node ID: 576ae445-b12e-4d20-99b7-5e5a91ee7d74
Similarity: 0.8289486590392277
Text: Stone was named the best-dressed woman of 2012 by Vogue and was included on similar listings by Glamour in 2013 and 2015, and People in 2014.
== Personal life == Stone moved from Los Angeles to Greenwich Village, New York, in 2009. In 2016, she moved back to Los Angeles. Despite significant media attention, she refuses to publicly discuss her personal life. Concerned with living a normal life, Stone has said she dislikes receiving paparazzi attention outside her home. She has expressed her ...使用 FlagEmbeddingReranker 进行重排序
为检索到更相关的片段,我们可以使用来自Hugging Face的开源重排序模型——bge-ranker-base 模型。
与 OpenAI API 类似,使用 Hugging Face 需要获取用户访问令牌。您可以按照此文档在 Hugging Face 创建用户访问令牌。
HF_TOKEN = userdata.get('HF_TOKEN')
os.environ['HF_TOKEN'] = HF_TOKEN继续之前,还需安装使用该重排序模型所需的库:
%pip install llama-index-postprocessor-flag-embedding-reranker
!pip install git+https://github.com/FlagOpen/FlagEmbedding.git最后,使用 bge-ranker-base 模型返回最相关的片段。
# Import packages
from llama_index.postprocessor.flag_embedding_reranker import FlagEmbeddingReranker
from llama_index.core.schema import QueryBundle
# Re-Rank chunks based on the bge-reranker-base-model
reranker = FlagEmbeddingReranker(
top_n = 3,
model = "BAAI/bge-reranker-base",
)
# Return the updated chunks
query_bundle = QueryBundle(query_str=query)
ranked_nodes = reranker._postprocess_nodes(nodes, query_bundle = query_bundle)
for ranked_node in ranked_nodes:
print('----------------------------------------------------')
display_source_node(ranked_node, source_length = 500)这是重排序后的结果:
Node ID: 9b3817fe-3a3f-4417-83d2-2e2996c8b468
Similarity: 3.0143558979034424
Text: Emily Jean "Emma" Stone (born November 6, 1988) is an American actress and producer. She is the recipient of various accolades, including two Academy Awards, two British Academy Film Awards, and two Golden Globe Awards. In 2017, she was the world's highest-paid actress and named by Time magazine as one of the 100 most influential people in the world. Born and raised in Scottsdale, Arizona, Stone began acting as a child in a theater production of The Wind in the Willows in 2000. As a teenager,...
----------------------------------------------------
Node ID: 576ae445-b12e-4d20-99b7-5e5a91ee7d74
Similarity: 2.2117154598236084
Text: Stone was named the best-dressed woman of 2012 by Vogue and was included on similar listings by Glamour in 2013 and 2015, and People in 2014.
== Personal life == Stone moved from Los Angeles to Greenwich Village, New York, in 2009. In 2016, she moved back to Los Angeles. Despite significant media attention, she refuses to publicly discuss her personal life. Concerned with living a normal life, Stone has said she dislikes receiving paparazzi attention outside her home. She has expressed her ...
----------------------------------------------------
Node ID: 1bef0308-8b0f-4f7e-9cd6-92ce5acf811f
Similarity: 1.6185210943222046
Text: Coincidentally, Gosling turned down the Beast role in Beauty and the Beast in favor of La La Land. Chazelle subsequently decided to make his characters somewhat older, with experience in struggling to make their dreams, rather than younger newcomers just arriving in Los Angeles.Emma Stone plays Mia, an aspiring actress in Los Angeles. Stone has loved musicals since she saw Les Misérables when she was eight years old. She said "bursting into song has always been a real dream of mine", and her ...从输出可见,ID 为 1bef0308-8b0f-4f7e-9cd6-92ce5acf811f 的节点从第二位降至第三位。此外,相似度分数的离散度更大。
现在我们已经进行了重排序,来看看原始查询的 RAG 回答有何变化:
# Initialize the query engine with Re-Ranking
query_engine = index.as_query_engine(
similarity_top_k = 3,
node_postprocessors=[reranker]
)
# Print the response from the model
response = query_engine.query("Compare the families of Emma Stone and Ryan Gosling")
print(response)应用重排序模型后的回答如下:
Both Emma Stone and Ryan Gosling have close relationships with their families. Stone has expressed her gratitude for having a great family and people around her who keep her grounded. Gosling, on the other hand, has drawn from his own experiences as an aspiring artist, indicating a connection to his personal background.与早先的回答相比有明显改进,但仍不完整。我们再评估一下基于 LLM 的重排序方法如何进一步提升表现。
使用 RankGPTRerank 进行重排序
这一次,我们使用 LLM 作为一种重排序器。这里采用 RankGPT 模块,利用 GPT 模型的能力在 RAG 系统中对文档进行排序。首先安装依赖包:
%pip install llama-index-postprocessor-rankgpt-rerank我们使用 RankGPTRerank 函数,并调用 gpt-3.5-turbo-0125 模型对片段进行重排序。
# Import packages
from llama_index.postprocessor.rankgpt_rerank import RankGPTRerank
# Re-Rank the top 3 chunks based on the gpt-3.5-turbo-0125 model
reranker = RankGPTRerank(
top_n = 3,
llm = OpenAI(model="gpt-3.5-turbo-0125"),
)
# Display the top 3 chunks based on RankGPT
query_bundle = QueryBundle(query_str=query)
ranked_nodes = reranker._postprocess_nodes(nodes, query_bundle = query_bundle)
for ranked_node in ranked_nodes:
print('----------------------------------------------------')
display_source_node(ranked_node, source_length = 500)使用 RankGPT 后,我们得到如下片段:
----------------------------------------------------
Node ID: 1bef0308-8b0f-4f7e-9cd6-92ce5acf811f
Similarity: 1.6185210943222046
Text: Coincidentally, Gosling turned down the Beast role in Beauty and the Beast in favor of La La Land. Chazelle subsequently decided to make his characters somewhat older, with experience in struggling to make their dreams, rather than younger newcomers just arriving in Los Angeles.Emma Stone plays Mia, an aspiring actress in Los Angeles. Stone has loved musicals since she saw Les Misérables when she was eight years old. She said "bursting into song has always been a real dream of mine", and her ...
----------------------------------------------------
Node ID: 9b3817fe-3a3f-4417-83d2-2e2996c8b468
Similarity: 3.0143558979034424
Text: Emily Jean "Emma" Stone (born November 6, 1988) is an American actress and producer. She is the recipient of various accolades, including two Academy Awards, two British Academy Film Awards, and two Golden Globe Awards. In 2017, she was the world's highest-paid actress and named by Time magazine as one of the 100 most influential people in the world. Born and raised in Scottsdale, Arizona, Stone began acting as a child in a theater production of The Wind in the Willows in 2000. As a teenager,...
----------------------------------------------------
Node ID: 576ae445-b12e-4d20-99b7-5e5a91ee7d74
Similarity: 2.2117154598236084
Text: Stone was named the best-dressed woman of 2012 by Vogue and was included on similar listings by Glamour in 2013 and 2015, and People in 2014.
== Personal life == Stone moved from Los Angeles to Greenwich Village, New York, in 2009. In 2016, she moved back to Los Angeles. Despite significant media attention, she refuses to publicly discuss her personal life. Concerned with living a normal life, Stone has said she dislikes receiving paparazzi attention outside her home. She has expressed her ...由于 RankGPT 不会根据相似度分数对段落排序,因此输出中的分数未更新。从结果看,被认为最相关的首个节点同时提到 Emma Stone 与 Ryan Gosling,而其余节点更多涉及 Emma Stone 的生平细节。
现在,如果我们打印采用该重排序方法后的模型回答,将得到以下输出:
Both Emma Stone and Ryan Gosling have close relationships with their families. Stone has expressed gratitude for having a great family and supportive people around her, while Gosling has drawn from his own experiences as an aspiring artist, indicating a connection to his family as well. Stone's family has played a significant role in her life, supporting her career pursuits and celebrating important milestones with her. Similarly, Gosling's experiences as an actor have likely been influenced by his family dynamics and relationships.该回答比之前的重排序技术更长、更详尽。
通过查询变换提升 RAG 表现
查询变换(也称查询重写)是一种将原始查询转换为另一个查询的做法,而不是直接用原始查询去检索前 k 个片段。我们将探讨以下技术:
- HyDE:将用户查询及其假设答案转换为嵌入,以在向量空间中检索最接近的文档。
- 多步查询变换:将复杂的用户查询分解为一系列可顺序处理的子问题。
使用 HyDE 提升 RAG 表现
HyDE 是“假设性文档嵌入”(Hypothetical Document Embeddings)的缩写,包含两步:首先针对用户查询生成一个假设答案/文档;随后将该答案与查询一并转换为嵌入,再在向量空间中检索与嵌入最接近的文档。来看实际效果:
# Import packages
from llama_index.core.indices.query.query_transform import HyDEQueryTransform
from llama_index.core.query_engine.transform_query_engine import (
TransformQueryEngine,
)
# build index and query engine for the index
index = VectorStoreIndex.from_documents(documents, service_context=service_context_gpt3)
query_engine = index.as_query_engine(similarity_top_k=4)
# HyDE setup
hyde = HyDEQueryTransform(include_original=True)
# Transform the query engine using HyDE
hyde_query_engine = TransformQueryEngine(query_engine, hyde)
# Print the response from the model
response = hyde_query_engine.query("Compare the families of Emma Stone and Ryan Gosling")
print(response)输出如下:
Both Emma Stone and Ryan Gosling come from diverse family backgrounds. Ryan Gosling's parents were of part French Canadian descent, along with some German, English, Scottish, and Irish. He grew up in a family that practiced the Church of Jesus Christ of Latter-day Saints. On the other hand, Emma Stone was born and raised in Scottsdale, Arizona, without specific details provided about her family's ethnic background or religious affiliation.相较重排序方法,我们看到一定改进。先前输出更偏向二者与家庭的关系,如今更关注其出身背景。
使用多步查询变换提升 RAG 表现
多步查询变换会将用户的查询拆分为一系列顺序子问题。当处理复杂问题时,这种方法尤为实用。
如我们所见,LLM 在对比两项事实时往往吃力,即便在只涉及单一主题的问题上可以作答准确。下面看看多步查询变换的实际效果。
# Multi-step query setup
step_decompose_transform_gpt3 = StepDecomposeQueryTransform(gpt3, verbose=True)
index_summary = "Breaks down the initial query"
# Return query engine for the index
multi_step_query_engine = MultiStepQueryEngine(
query_engine=query_engine,
query_transform=step_decompose_transform_gpt3,
index_summary=index_summary
)
# print the response from the model
response = multi_step_query_engine.query("Compare the families of Emma Stone and Ryan Gosling")我们可以看到促成最终输出的中间问题:
> Current query: Compare the families of Emma Stone and Ryan Gosling
> New query: What is the family background of Emma Stone and Ryan Gosling?
> Current query: Compare the families of Emma Stone and Ryan Gosling
> New query: What is the specific family background of Emma Stone?
> Current query: Compare the families of Emma Stone and Ryan Gosling
> New query: What is Emma Stone's relationship with her family like?对用户查询的最终回答如下:
Both Ryan Gosling and Emma Stone have strong family connections, with Emma Stone emphasizing the importance of her family in keeping her grounded. Ryan Gosling's family background includes a mix of French Canadian, German, English, Scottish, and Irish heritage.在这个案例中,使用多步查询变换来比较 Emma Stone 与 Ryan Gosling 的家庭确有帮助。
结语
本文介绍了多种提升 RAG 表现的技术。无论是分块、重排序,还是查询变换,最佳方案往往取决于具体用例以及您对某个查询所期望的输出。
如果您希望进一步深入了解 RAG,推荐观看我们的代码演练:使用 LlamaIndex 的检索增强生成以及使用 GPT 和 Milvus 的检索增强生成。这些视频展示了如何在不同用例中将 LLM 与向量数据库结合使用检索增强生成。

数据科学家 - CRIF
检索增强生成(RAG)是提升大型语言模型(LLM)准确性与可靠性的最常用技术之一。其原理是在生成时引入外部数据源的额外信息,从而让答案能够贴合特定语境,并且无需微调或重新训练即可更新。
尽管 RAG 很受欢迎,但并非在所有场景都表现理想。本文将循序渐进讲解如何高效构建 RAG 流水线,探讨 RAG 的局限性以及应对方法。让我们开始吧!