

Kurs
Arbeiten mit der OpenAI-API
3 Std.
183.4K
Üben und Lernpfad deinen Fortschritt.
Weiter Mit GoogleOpenAI hat still und leise GPT-5.1-Codex auf der Developer-Plattform veröffentlicht, und Entwickler nennen es schon jetzt das beste Coding-Modell derzeit. Anders als frühere Codex-Versionen ist GPT-5.1-Codex auf echte Software-Engineering-Aufgaben, langes Reasoning und toolnutzende Agenten ausgelegt.
In diesem Tutorial bauen wir einen vollständigen GitHub-Issue-Analyzer-Agenten mit OpenAI Agents und GPT-5.1 Codex.
Unser Agent wird:
Dieser Agent arbeitet wie eine Senior Engineerin: recherchiert, liest, denkt nach und plant, bevor er irgendetwas schreibt. Schau dir auch unseren separaten Guide zu GPT-5.1 an, um zu sehen, was es sonst noch Neues gibt.
GPT-5.1 Codex ist eine spezialisierte Version von GPT-5.1, entwickelt für langlaufende, agentische Coding-Aufgaben statt nur Snippet-Autovervollständigung. Es ist für echtes Software Engineering und agentische Workflows gebaut – perfekt als Motor hinter unserem Issue-to-Plan-Workflow.
Im Gegensatz zu allgemeinen Modellen versteht Codex Codebasen wie eine erfahrene Entwicklerin: Es liest Issues, denkt über die Architektur nach, identifiziert die richtigen Verzeichnisse und inspiziert nur die Dateien, die wirklich zählen. Das macht den Agenten schneller, intelligenter und deutlich kosteneffizienter.
Codex ist auf langlaufende, agentische Coding-Aufgaben optimiert. Es integriert sich nahtlos mit Entwickler-Tools wie der GitHub CLI und der Firecrawl API. So kann unser Agent Issues abrufen, Projektstrukturen online erkunden, gezielt Dateien lesen und bei Bedarf Dokumentation sammeln. Es folgt Anweisungen genau, liefert saubere, verlässliche Analysen und passt seinen Reasoning-Aufwand an – flott bei einfachen Tasks, tiefgehend bei komplexen.
Durch die Kombination aus starkem Codeverständnis und toolbewusstem Reasoning verwandelt GPT-5.1 Codex ein GitHub-Issue in einen präzisen, umsetzbaren Engineering-Plan – ohne das ganze Repo zu scannen oder Code zu halluzinieren. Es ist das Rückgrat des Workflows, weil es die nötige Engineering-Intuition, Struktur und Präzision mitbringt.
Bevor wir loslegen, stell sicher, dass deine Umgebung bereit ist. Du brauchst Git auf deinem Rechner. Wenn du unsicher bist, führe git --version aus, um das zu prüfen. Außerdem benötigst du ein Konto auf der OpenAI Developer Platform mit mindestens 6 $ Guthaben, damit die API-Calls ohne Unterbrechung laufen.
Als Nächstes hol dir ein kostenloses Firecrawl-Konto und setze deine API-Keys als Umgebungsvariablen. Darüber kommuniziert dein Analyzer mit OpenAI und Firecrawl:
export OPENAI_API_KEY=sk-...
export FIRECRAWL_API_KEY="fc-..."
Wenn das steht, installiere die Python-Pakete für den Workflow. Das erste, openai-agents, ist ein leichtgewichtiges Framework, mit dem sich Multi-Agent-Pipelines erstaunlich einfach bauen lassen. Das zweite, firecrawl-py, crawlt Repos oder Dokus und extrahiert nützliche Informationen.
pip install openai-agents
pip install firecrawl-py
Zum Schluss stelle sicher, dass deine GitHub CLI installiert und eingerichtet ist. Mit dem folgenden Befehl meldest du dich bei GitHub an.
gh auth login
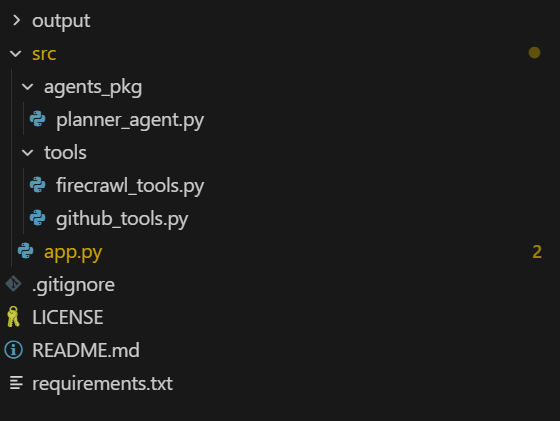
Wir erstellen einen Ordner „src“, der alle Code-Dateien enthält. Der Ordner „agents_pkg“ hält alle Agenten-Dateien, während „tools“ die Tool-Dateien enthält.
Die Hauptanwendung „app.py“ bietet eine Kommandozeilenoberfläche (CLI), die die Planungsagenten nutzt, um basierend auf Eingaben einen GitHub-Issue-Report zu erzeugen.
So sollte dein Projektverzeichnis aussehen:
Zuerst erstellen wir eine Datei mit agentischen Tools, mit der der Agent über einfache Python-Funktionen auf die GitHub- und Firecrawl-API zugreifen kann.
Wir starten mit den Tools. Erstelle eine Datei namens firecrawl_tools.py im Verzeichnis src/tools und füge den folgenden Code ein.
1. Erstellt und gibt einen Firecrawl-Client zurück, der den FIRECRAWL_API_KEY aus deiner Umgebung verwendet, und wirft einen Fehler, wenn der Schlüssel fehlt.
import json
import os

from agents import function_tool
from firecrawl import firecrawl


def _get_firecrawl_client():
    api_key = os.getenv("FIRECRAWL_API_KEY")
    if not api_key:
        raise RuntimeError("FIRECRAWL_API_KEY is not set")
    return firecrawl(api_key=api_key)
2. Führt mit Firecrawl eine fokussierte Websuche (z. B. Dokus, Blogposts, Fehlermeldungen) aus und gibt die Ergebnisse als JSON zurück, damit der Agent sie als externen Kontext nutzen kann.
@function_tool
def firecrawl_search(query: str, limit: int = 3) -> str:
    """
    Run a Firecrawl search for docs related to the issue or tech stack.

    Args:
        query: Search query (usually based on issue title / framework / error message).
        limit: Max number of results to return.

    Returns:
        JSON string of Firecrawl search results.
    """
    client = _get_firecrawl_client()
    results = client.search(query=query, limit=limit)
    return json.dumps(results)
3. Crawlt eine einzelne URL mit Firecrawl (im Markdown-Format) und liefert den strukturierten Seiteninhalt als JSON für tiefere technische Recherchen.
@function_tool
def firecrawl_scrape(url: str) -> str:
    """
    Scrape a single URL using Firecrawl for deeper research.

    Args:
        url: URL to scrape (docs, blog, README in another repo, etc.).

    Returns:
        JSON (markdown/structured) content from Firecrawl scrape.
    """
    client = _get_firecrawl_client()
    result = client.scrape(url=url, params={"formats": ["markdown"]})
return json.dumps(result)Dann erstellen wir eine Datei namens github_tools.py im Verzeichnis src/tools und fügen folgenden Code hinzu.
1. Ruft ein bestimmtes GitHub-Issue über die GitHub CLI ab und gibt die Details als JSON zurück, damit der Agent sie lesen kann.
import base64
import json
import subprocess
from typing import List, Optional

from agents import function_tool


@function_tool
def get_github_issue(repo: str, issue_number: int) -> str:
    """
    Fetch a GitHub issue using the GitHub CLI.

    Args:
        repo: Repository in 'owner/name' format.
        issue_number: The issue number to fetch.

    Returns:
        A JSON string containing the issue fields (title, body, labels, URL, etc.),
        or an error payload if the command fails.
    """
    try:
        result = subprocess.run(
            [
                "gh",
                "issue",
                "view",
                str(issue_number),
                "--repo",
                repo,
                "--json",
                "number,title,body,labels,url,author,createdAt,state,assignees",
            ],
            capture_output=True,
            text=True,
            check=True,
        )
        return result.stdout
    except subprocess.CalledProcessError as e:
        return json.dumps(
            {
                "error": "Failed to fetch issue via GitHub CLI",
                "stderr": e.stderr,
                "repo": repo,
                "issue_number": issue_number,
            }
        )
2. Listet nur die relevanten Dateien in einem Remote-GitHub-Repo auf (optional gefiltert nach Pfad und Extension), damit der Agent nicht das ganze Projekt scannt.
@function_tool
def list_repo_files_gh(
    repo: str,
    max_files: int = 80,
    extensions: Optional[List[str]] = None,
    path_prefixes: Optional[List[str]] = None,
) -> str:
    """
    List *relevant* files in the remote repo using GitHub CLI.

    Uses:
        gh api repos/{repo}/git/trees/HEAD?recursive=1

    The agent is expected to reason first which areas of the codebase are likely relevant
    (e.g. 'src/', 'app/', 'backend/api/', 'cli/'), and then call this tool with a small
    set of path_prefixes instead of scanning the entire project.

    Args:
        repo: Repository in 'owner/name' format (e.g. openai/openai-agents-python).
        max_files: Max number of files to return.
        extensions: Optional list of file extensions to keep (e.g. [".py", ".ts"]).
        path_prefixes: Optional list of path prefixes to include (e.g. ["src/", "app/api/"]).

    Returns:
        JSON string with file paths and filters applied.
    """
    try:
        result = subprocess.run(
            [
                "gh",
                "api",
                f"repos/{repo}/git/trees/HEAD?recursive=1",
            ],
            capture_output=True,
            text=True,
            check=True,
        )
    except subprocess.CalledProcessError as e:
        return json.dumps(
            {
                "error": "Failed to list repo files via GitHub CLI",
                "stderr": e.stderr,
                "repo": repo,
            }
        )

    try:
        data = json.loads(result.stdout)
    except json.JSONDecodeError:
        return json.dumps(
            {
                "error": "Failed to parse JSON from gh api",
                "raw": result.stdout[:2000],
                "repo": repo,
            }
        )

    tree = data.get("tree", [])

    if extensions is not None and not isinstance(extensions, list):
        extensions = [str(extensions)]
    exts = [e.lower() for e in (extensions or [])]

    if path_prefixes is not None and not isinstance(path_prefixes, list):
        path_prefixes = [str(path_prefixes)]
    prefixes = [p.strip() for p in (path_prefixes or []) if p.strip()]

    paths: List[str] = []
    for entry in tree:
        if entry.get("type") != "blob":
            continue  # only files
        path = entry.get("path", "")
        if not path:
            continue

        # If prefixes are provided, only keep files under those subtrees
        if prefixes and not any(path.startswith(pref) for pref in prefixes):
            continue

        if exts:
            suffix = "." + path.split(".")[-1].lower() if "." in path else ""
            if suffix not in exts:
                continue

        paths.append(path)
        if len(paths) >= max_files:
            break

    return json.dumps(
        {
            "repo": repo,
            "count": len(paths),
            "files": paths,
            "filtered_by_extensions": bool(exts),
            "filtered_by_prefixes": bool(prefixes),
        }
    )
3. Lädt den Inhalt einer einzelnen Datei über die GitHub CLI herunter und dekodiert ihn, gibt den Text (bei Bedarf gekürzt) als JSON zurück.
@function_tool
def get_repo_file_gh(
    repo: str,
    path: str,
    ref: str = "",
    max_chars: int = 8000,
) -> str:
    """
    Read a file's contents from the remote repo using GitHub CLI.

    Uses:
        gh api repos/{repo}/contents/{path} [ -F ref=<branch> ]

    Args:
        repo: Repository in 'owner/name' format.
        path: File path in the repo (e.g. 'src/main.py').
        ref: Optional branch / commit / tag ref (default: repo's default branch).
        max_chars: Max characters of decoded content to return.

    Returns:
        JSON with file metadata and decoded content (truncated if needed),
        or an error payload if anything fails.
    """
    cmd = ["gh", "api", f"repos/{repo}/contents/{path}"]
    # Only add ref when explicitly set (GitHub default branch otherwise)
    if ref:
        cmd += ["-F", f"ref={ref}"]

    try:
        result = subprocess.run(
            cmd,
            capture_output=True,
            text=True,
            check=True,
        )
    except subprocess.CalledProcessError as e:
        return json.dumps(
            {
                "error": "Failed to fetch file via GitHub CLI",
                "stderr": e.stderr,
                "repo": repo,
                "path": path,
                "ref": ref or "DEFAULT_BRANCH",
            }
        )

    try:
        data = json.loads(result.stdout)
    except json.JSONDecodeError:
        return json.dumps(
            {
                "error": "Failed to parse JSON from gh api (contents)",
                "raw": result.stdout[:2000],
                "repo": repo,
                "path": path,
            }
        )

    if data.get("type") != "file":
        return json.dumps(
            {
                "error": "Path is not a file",
                "repo": repo,
                "path": path,
                "data_type": data.get("type"),
            }
        )

    encoding = data.get("encoding")
    content_b64 = data.get("content", "")

    if encoding != "base64":
        return json.dumps(
            {
                "error": "Unexpected encoding",
                "repo": repo,
                "path": path,
                "encoding": encoding,
            }
        )

    try:
        # GitHub often includes newlines in base64 payload
        raw_bytes = base64.b64decode(content_b64)
        text = raw_bytes.decode("utf-8", errors="replace")
    except Exception as e:  # noqa: BLE001
        return json.dumps(
            {
                "error": f"Failed to decode file content: {e}",
                "repo": repo,
                "path": path,
                "encoding": encoding,
            }
        )

    truncated = text[:max_chars]
    return json.dumps(
        {
            "repo": repo,
            "path": path,
            "ref": ref or "DEFAULT_BRANCH",
            "truncated": len(text) > max_chars,
            "content": truncated,
        }
)Hier definieren wir einen Issue Planner, der Folgendes kann:
Wir verdrahten die GitHub- und Firecrawl-Tools, geben dem Agenten klare Anweisungen für kosteneffizientes Arbeiten und setzen das Modell auf gpt-5.1-codex.
Erstelle die Datei planner_agent.py im Verzeichnis src/agents_pkg und füge folgenden Code ein:
from agents import Agent

from tools.github_tools import (
    get_github_issue,
    list_repo_files_gh,
    get_repo_file_gh,
)
from tools.firecrawl_tools import (
    firecrawl_search,
    firecrawl_scrape,
)


def build_planner_agent() -> Agent:
    """
    Issue Planner agent that:
    - Reads the GitHub issue
    - Reasons about which parts of the repo are relevant
    - Uses GitHub CLI to inspect a *small* set of files online
    - Uses Firecrawl for external research
    - Outputs a concrete, step-by-step execution plan
    """
    return Agent(
        name="Issue Planner",
        instructions=(
            "You are a senior software engineer.\n"
            "Goal: Given a GitHub issue and the online repo (structure + files), plus optional "
            "external research, produce a clear, step-by-step execution plan to resolve the issue.\n\n"
            "CONTEXT:\n"
            "- All repository interaction must be done *online* via GitHub CLI tools.\n"
            "- You have tools to: read the issue, list files under certain paths, read specific files, "
            "  and call Firecrawl search/scrape for docs.\n\n"
            "IMPORTANT STRATEGY (BE SMART):\n"
            "- Be selective and cost-aware. Do NOT scan the whole project.\n"
            "- First, deeply read the issue and infer which part of the system it affects:\n"
            "  routing layer, CLI, API handlers, DB layer, tests, etc.\n"
            "- Based on this reasoning, decide a small list of path prefixes and file types.\n\n"
            "RECOMMENDED WORKFLOW:\n"
            "1. Call get_github_issue(repo, issue_number) to fully understand the problem.\n"
            "2. From the issue, infer a small list of path prefixes where relevant code likely lives,\n"
            "   e.g. ['src/', 'app/', 'backend/api/', 'cli/'] depending on the project style.\n"
            "3. Call list_repo_files_gh with:\n"
            "   - extensions like ['.py', '.ts', '.js', '.tsx', '.jsx']\n"
            "   - path_prefixes set to that small, targeted list\n"
            "   This keeps the search focused instead of scanning the entire project.\n"
            "4. From the returned file list, pick at most ~5-15 key files that are most likely related\n"
            "   (entrypoints, routers, handlers, services, tests).\n"
            "5. Call get_repo_file_gh(repo, path=...) only on those selected files to inspect the "
            "   actual implementation.\n"
            "6. If you need framework or library context (FastAPI, Click, React, etc.), use\n"
            "   firecrawl_search and firecrawl_scrape to pull official docs or good examples.\n\n"
            "OUTPUT FORMAT (execution plan):\n"
            "After you have enough context from the issue + targeted code inspection (+ optional research), "
            "output a concise but concrete plan with sections:\n"
            "   - Issue summary\n"
            "   - Project/codebase understanding (where this issue lives in the architecture)\n"
            "   - Key files / components to touch (with file paths)\n"
            "   - Step-by-step implementation plan (Step 1, Step 2, ...)\n"
            "   - Testing strategy (unit / integration / manual)\n"
            "   - Edge cases, risks, and any open questions\n\n"
            "The plan must be actionable for a mid-level developer. Avoid generic advice; tie your steps "
            "to the actual files and modules you inspected.\n"
        ),
        tools=[
            get_github_issue,
            list_repo_files_gh,
            get_repo_file_gh,
            firecrawl_search,
            firecrawl_scrape,
        ],
        model="gpt-5.1-codex",
)Das ist die zentrale Python-Datei mit der Kommandozeilenoberfläche (CLI). Sie führt Logik, Callbacks und Fehlerbehandlung in einer Datei zusammen und nutzt effizient Tools und Agenten aus anderen Dateien.
1. Zuerst richten wir alles ein, was die CLI braucht. Wir binden Standardbibliotheken ein, sorgen unter Windows für korrektes Unicode-Output (Emojis, Symbole) und importieren den OpenAI-Runner sowie unseren Planner-Agenten.
2. Dann definieren wir die Kommandozeilenoptionen, damit du beim Start ein GitHub-Repository und eine Issue-Nummer übergeben kannst.
src/app.py:
import argparse
import asyncio
import json
import os
import pathlib
import sys
from datetime import datetime

# Set UTF-8 encoding for stdout to handle Unicode characters
if sys.platform == "win32":
    import codecs
    sys.stdout = codecs.getwriter("utf-8")(sys.stdout.detach())
    sys.stderr = codecs.getwriter("utf-8")(sys.stderr.detach())

from agents import Runner, ItemHelpers
from openai.types.responses import ResponseTextDeltaEvent

from agents_pkg.planner_agent import build_planner_agent


def parse_args() -> argparse.Namespace:
    parser = argparse.ArgumentParser(
        description=(
            "Issue Planner: GPT-5.1-Codex + OpenAI Agents + GitHub CLI + Firecrawl\n"        )
    )
    parser.add_argument(
        "--repo",
        help="GitHub repo in 'owner/name' format (e.g. openai/openai-agents-python).",
    )
    parser.add_argument(
        "--issue",
        type=int,
        help="Issue number to plan for.",
    )
    return parser.parse_args()
3. Danach sammeln wir Eingaben und bereiten den Kontext vor. Wir lesen Repo und Issue aus den Argumenten, prüfen den OpenAI-API-Key, bauen einen klaren Prompt für die schrittweise Analyse und legen eine Markdown-Datei mit Zeitstempel an, in der der finale Plan gespeichert wird.
def get_user_input(args: argparse.Namespace) -> tuple[str, int]:
    """Get repository and issue number from arguments or user input."""
    repo = args.repo or input("GitHub repo (owner/name): ").strip()
    issue_number = args.issue or int(input("Issue number: ").strip())
    return repo, issue_number


def validate_environment() -> None:
    """Validate that required environment variables are set."""
    if not os.getenv("OPENAI_API_KEY"):
        raise RuntimeError("OPENAI_API_KEY is not set")


def build_user_prompt(repo: str, issue_number: int) -> str:
    """Build the user prompt for the agent."""
    return (
        f"You are helping me plan how to implement GitHub issue #{issue_number} "
        f"in repo '{repo}'.\n\n"
        "Be selective and cost-aware:\n"
        "1. Use get_github_issue(repo, issue_number) to understand the problem.\n"
        "2. Based on the issue text, first reason about which directories and components "
        "   are likely relevant.\n"
        "3. Call list_repo_files_gh(repo, extensions=['.py', '.ts', '.js', '.tsx', '.jsx'], "
        "   path_prefixes=[<your inferred prefixes>]) to only explore those areas.\n"
        "4. From those results, choose a small set of the most relevant files and call "
        "   get_repo_file_gh(repo, path=...) on them.\n"
        "5. Optionally, use firecrawl_search and firecrawl_scrape if you need external docs.\n"
        "6. Finally, generate the execution plan in the structured format from your instructions."
    )


def setup_output_file(repo: str, issue_number: int) -> pathlib.Path:
    """Create output directory and return the markdown file path."""
    output_dir = pathlib.Path("output")
    output_dir.mkdir(exist_ok=True)
    timestamp = datetime.now().strftime("%Y%m%d_%H%M%S")
    markdown_file = output_dir / f"execution_plan_{repo.replace('/', '_')}_issue_{issue_number}_{timestamp}.md"
    return markdown_file
4. Als Nächstes machen wir das Denken des Agenten sichtbar. Wir ziehen aus jedem Event einen kompakten Reasoning-Schnipsel und drucken eine kurze „💭 Reasoning…“-Zeile, sodass du statt Rohdaten eine menschlich lesbare Einordnung bekommst, woran das Modell gerade arbeitet.
def extract_reasoning_text(event_item) -> str | None:
    """Extract reasoning text from a reasoning event item."""
    reasoning_text = None

    if hasattr(event_item, 'raw_item'):
        raw = event_item.raw_item
        # Try multiple attribute names
        for attr_name in ['content', 'text', 'reasoning', 'message', 'delta']:
            if hasattr(raw, attr_name):
                val = getattr(raw, attr_name)
                if val and str(val).strip() and str(val) != 'None':
                    reasoning_text = str(val)
                    break

        # If still not found, try to access as dict-like
        if not reasoning_text:
            try:
                if hasattr(raw, '__dict__'):
                    for key, val in raw.__dict__.items():
                        if val and str(val).strip() and str(val) != 'None' and key in ['content', 'text', 'reasoning', 'message', 'delta']:
                            reasoning_text = str(val)
                            break
            except:
                pass

    # Also try direct attributes on event.item
    if not reasoning_text:
        for attr_name in ['content', 'text', 'reasoning', 'message']:
            if hasattr(event_item, attr_name):
                val = getattr(event_item, attr_name)
                if val and str(val).strip() and str(val) != 'None':
                    reasoning_text = str(val)
                    break

    return reasoning_text


def handle_reasoning_event(event_item) -> None:
    """Handle and display reasoning events."""
    reasoning_text = extract_reasoning_text(event_item)

    if reasoning_text and reasoning_text.strip():
        # Show first line or first 100 chars
        first_line = reasoning_text.split('\n')[0].strip()[:100]
        if len(reasoning_text.split('\n')[0].strip()) > 100:
            first_line += "..."
        print(f"\n💭 Reasoning: {first_line}", flush=True)
    else:
        # Don't show "None" - just show that reasoning is happening
        print(f"\n💭 Reasoning...", flush=True)
5. Danach kümmern wir uns um Tool-Calls und Tracking. Wir erkennen, welches Tool der Agent nutzt, formatieren die Argumente (z. B. Repo, Pfad oder Query) kompakt, drucken eine „🔧 Calling…“-Meldung und führen intern eine Liste aktiver Tools, um sie bei Abschluss zu markieren und am Ende zusammenzufassen.
def extract_tool_info(event_item) -> tuple[str | None, str | None]:
    """Extract tool name and ID from a tool call event item."""
    tool_name = None
    tool_id = None

    # First try raw_item which contains the actual tool call data
    if hasattr(event_item, 'raw_item'):
        raw = event_item.raw_item
        # Try accessing tool_call through various paths
        tool_call = None
        if hasattr(raw, 'tool_call'):
            tool_call = raw.tool_call
        elif hasattr(raw, 'function_call'):
            tool_call = raw.function_call

        if tool_call:
            # Try to get name from tool_call
            if hasattr(tool_call, 'name'):
                tool_name = tool_call.name
            elif hasattr(tool_call, 'function') and hasattr(tool_call.function, 'name'):
                tool_name = tool_call.function.name
            # Try to get ID
            if hasattr(tool_call, 'id'):
                tool_id = tool_call.id
            elif hasattr(tool_call, 'tool_call_id'):
                tool_id = tool_call.tool_call_id

        # Fallback: try direct attributes on raw
        if not tool_name:
            if hasattr(raw, 'name'):
                tool_name = getattr(raw, 'name')
            elif hasattr(raw, 'function') and hasattr(raw.function, 'name'):
                tool_name = raw.function.name
            # Try using getattr with different possible attribute names
            for attr_name in ['tool_name', 'function_name', 'name']:
                if hasattr(raw, attr_name):
                    tool_name = getattr(raw, attr_name, None)
                    if tool_name:
                        break

    # Fallback to direct attributes
    if not tool_name and hasattr(event_item, 'tool_call'):
        tool_call = event_item.tool_call
        if hasattr(tool_call, 'name'):
            tool_name = tool_call.name
        if hasattr(tool_call, 'id'):
            tool_id = tool_call.id
        elif hasattr(tool_call, 'function') and hasattr(tool_call.function, 'name'):
            tool_name = tool_call.function.name
    if not tool_name and hasattr(event_item, 'name'):
        tool_name = event_item.name
    if not tool_name and hasattr(event_item, 'function'):
        func = event_item.function
        if hasattr(func, 'name'):
            tool_name = func.name

    return tool_name, tool_id


def format_tool_arguments(tool_call_obj) -> str:
    """Format tool arguments for display."""
    if not tool_call_obj or not hasattr(tool_call_obj, 'arguments'):
        return ""

    try:
        args_dict = json.loads(tool_call_obj.arguments) if isinstance(tool_call_obj.arguments, str) else tool_call_obj.arguments
        if 'repo' in args_dict:
            tool_args = f" → {args_dict['repo']}"
            if 'issue_number' in args_dict:
                tool_args += f"#{args_dict['issue_number']}"
            return tool_args
        elif 'path' in args_dict:
            return f" → {args_dict['path']}"
        elif 'query' in args_dict:
            q = str(args_dict['query'])
            return f" → {q[:40]}..." if len(q) > 40 else f" → {q}"
        elif 'url' in args_dict:
            return f" → {args_dict['url']}"
        elif 'extensions' in args_dict or 'path_prefixes' in args_dict:
            parts = []
            if 'extensions' in args_dict:
                parts.append(f"ext={args_dict['extensions']}")
            if 'path_prefixes' in args_dict:
                parts.append(f"paths={args_dict['path_prefixes']}")
            return f" → {', '.join(parts)}"
    except:
        pass

    return ""


def handle_tool_call_event(event_item, active_tools: dict, tool_counter: int) -> tuple[int, bool]:
    """Handle tool call events and return updated tool_counter and whether event was handled."""
    tool_name, tool_id = extract_tool_info(event_item)

    if tool_name:
        tool_counter += 1
        tool_id = tool_id or f"tool_{tool_counter}"
        active_tools[tool_id] = tool_name

        # Get tool arguments if available
        tool_call_obj = None
        if hasattr(event_item, 'raw_item') and hasattr(event_item.raw_item, 'tool_call'):
            tool_call_obj = event_item.raw_item.tool_call
        elif hasattr(event_item, 'tool_call'):
            tool_call_obj = event_item.tool_call

        tool_args = format_tool_arguments(tool_call_obj)
        print(f"\n[{tool_counter}] 🔧 Calling: {tool_name}{tool_args}...", flush=True)
        return tool_counter, True
    else:
        # Still couldn't extract - try to inspect raw_item structure
        if hasattr(event_item, 'raw_item'):
            raw = event_item.raw_item
            try:
                raw_attrs = [attr for attr in dir(raw) if not attr.startswith('_')]
                # Look for attributes that might contain the tool name
                for attr in raw_attrs:
                    try:
                        val = getattr(raw, attr)
                        if isinstance(val, str) and ('get_github' in val.lower() or 'list_repo' in val.lower() or 'firecrawl' in val.lower()):
                            tool_name = val
                            break
                        # Check if it's a dict-like object with name
                        if hasattr(val, 'name'):
                            tool_name = val.name
                            break
                    except:
                        continue

                if tool_name:
                    tool_counter += 1
                    tool_id = tool_id or f"tool_{tool_counter}"
                    active_tools[tool_id] = tool_name
                    print(f"\n[{tool_counter}] 🔧 Calling: {tool_name}...", flush=True)
                    return tool_counter, True
                else:
                    # Print raw_item structure for debugging
                    print(f"\n[DEBUG] raw_item attrs: {raw_attrs[:10]}", flush=True)
            except Exception as e:
                print(f"\n[DEBUG] Error inspecting raw_item: {e}", flush=True)

    return tool_counter, False


def handle_tool_output_event(event_item, active_tools: dict, completed_tools: list) -> None:
    """Handle and display reasoning events."""
    tool_id = None

    # Try raw_item first
    if hasattr(event_item, 'raw_item') and hasattr(event_item.raw_item, 'tool_call_id'):
        tool_id = event_item.raw_item.tool_call_id
    elif hasattr(event_item, 'tool_call_id'):
        tool_id = event_item.tool_call_id
    elif hasattr(event_item, 'raw_item') and hasattr(event_item.raw_item, 'tool_call'):
        if hasattr(event_item.raw_item.tool_call, 'id'):
            tool_id = event_item.raw_item.tool_call.id
    elif hasattr(event_item, 'tool_call'):
        if hasattr(event_item.tool_call, 'id'):
            tool_id = event_item.tool_call.id
        elif hasattr(event_item.tool_call, 'function') and hasattr(event_item.tool_call.function, 'name'):
            # Try to match by name if ID not available
            tool_name_match = event_item.tool_call.function.name
            for tid, tname in active_tools.items():
                if tname == tool_name_match:
                    tool_id = tid
                    break

    if tool_id and tool_id in active_tools:
        tool_name = active_tools.pop(tool_id)
        completed_tools.append(tool_name)
    elif active_tools:
        # Fallback: use the first active tool
        tool_id, tool_name = next(iter(active_tools.items()))
        active_tools.pop(tool_id)
        completed_tools.append(tool_name)
6. Jetzt verdrahten wir Streaming-Loop und Persistenz. Wir verarbeiten Streaming-Events des Agenten, drucken Tokens in Echtzeit, zeigen Reasoning und Tool-Calls live an, fallen bei Problemen elegant auf einen nicht-streamenden Lauf zurück und schreiben den kompletten Umsetzungsplan mit nützlichen Metadaten in eine Markdown-Datei.
async def process_streaming_events(result, repo: str, issue_number: int) -> str:
    """Process streaming events from the agent execution."""
    final_output = ""
    active_tools = {}  # Track active tool calls by ID
    tool_counter = 0
    completed_tools = []
    first_event_received = False

    # Stream the events as they come in
    async for event in result.stream_events():
        # Handle raw response events (token-by-token streaming) - print immediately
        if event.type == "raw_response_event" and isinstance(event.data, ResponseTextDeltaEvent):
            if not first_event_received:
                first_event_received = True
            delta = event.data.delta
            print(delta, end="", flush=True)
            final_output += delta
        # Handle run item events (higher level updates)
        elif event.type == "run_item_stream_event":
            item_type = getattr(event.item, 'type', 'unknown')

            # Show reasoning events
            if item_type == "reasoning_item":
                handle_reasoning_event(event.item)
            elif item_type == "tool_call_item":
                tool_counter, handled = handle_tool_call_event(event.item, active_tools, tool_counter)
                if handled:
                    first_event_received = True
            elif item_type == "tool_call_output_item":
                handle_tool_output_event(event.item, active_tools, completed_tools)
            elif item_type == "message_output_item":
                message_text = ItemHelpers.text_message_output(event.item)
                if message_text and (not final_output or message_text not in final_output):
                    print(f"\n{message_text}", flush=True)
                    final_output += message_text

    print()  # Add newline after streaming

    # Show summary of tools used
    if completed_tools:
        print(f"---\n\n📊 Tools used ({len(completed_tools)}): {', '.join(completed_tools)}", flush=True)

    # If no streaming events occurred, fall back to final output
    if not final_output:
        final_output = result.final_output
        if final_output:
            print(final_output, flush=True)

    return final_output

async def run_agent_with_streaming(agent, user_prompt: str, repo: str, issue_number: int) -> str:
    """Run the agent with streaming support and fallback handling."""
    try:
        # Run agent with streaming (run_streamed is synchronous, returns immediately)
        result = Runner.run_streamed(
            agent,
            input=user_prompt,
            context={"repo": repo, "issue_number": issue_number},
        )

        return await process_streaming_events(result, repo, issue_number)

    except Exception as e:
        print(f"⚠️  Error: {e}", flush=True)
        # Fallback to standard async run
        result = await Runner.run(
            agent,
            input=user_prompt,
            context={"repo": repo, "issue_number": issue_number},
        )
        print(result.final_output, flush=True)
        return result.final_output

def save_output_to_file(markdown_file: pathlib.Path, repo: str, issue_number: int, final_output: str) -> None:
    """Save the final output to a markdown file."""
    with open(markdown_file, 'w', encoding='utf-8') as f:
        f.write(f"# GitHub Issue Analysis: {repo}#{issue_number}\n\n")
        f.write(f"**Generated on:** {datetime.now().strftime('%Y-%m-%d %H:%M:%S')}\n\n")
        f.write(f"**Repository:** {repo}\n")
        f.write(f"**Issue Number:** {issue_number}\n\n")
        f.write("---\n\n")
        f.write(final_output)

    print(f"---\n\n✅ Saved: {markdown_file}", flush=True)
7. Zum Schluss verbinden wir alles im Programmeinstiegspunkt. Wir parsen die Argumente, holen Repo und Issue, validieren die Umgebung, bauen Agent und Prompt, starten den Planner mit Streaming (und bei Bedarf Fallback) und speichern das Ergebnis.
async def main() -> None:
    """Main entry point for the application."""
    args = parse_args()
    repo, issue_number = get_user_input(args)
    validate_environment()

    agent = build_planner_agent()
    user_prompt = build_user_prompt(repo, issue_number)
    markdown_file = setup_output_file(repo, issue_number)

    print(f"\n🔍 Analyzing {repo}#{issue_number}...\n")

    # Run the agent with streaming support
    try:
        final_output = await run_agent_with_streaming(agent, user_prompt, repo, issue_number)
    except Exception as e:
        print(f"⚠️  Error: {e}", flush=True)
        # Final fallback to standard sync run
        result = Runner.run_sync(
            agent,
            input=user_prompt,
            context={"repo": repo, "issue_number": issue_number},
        )
        print(result.final_output, flush=True)
        final_output = result.final_output

    # Save output to file
    save_output_to_file(markdown_file, repo, issue_number, final_output)


if __name__ == "__main__":
    asyncio.run(main())
Hinweis: Quellcode, Konfiguration und Dokumentation findest du im GitHub-Repository: kingabzpro/Issue-Analyzer. Sieh es dir an und nutze es als Leitfaden, wenn du die Ergebnisse reproduzierst.
Es gibt zwei Modi für unsere CLI-App: den Interaktivmodus, bei dem dich die App nacheinander nach Repository und Issue-Nummer fragt, und den CLI-Modus, bei dem du alle Infos direkt beim Start mitgibst.
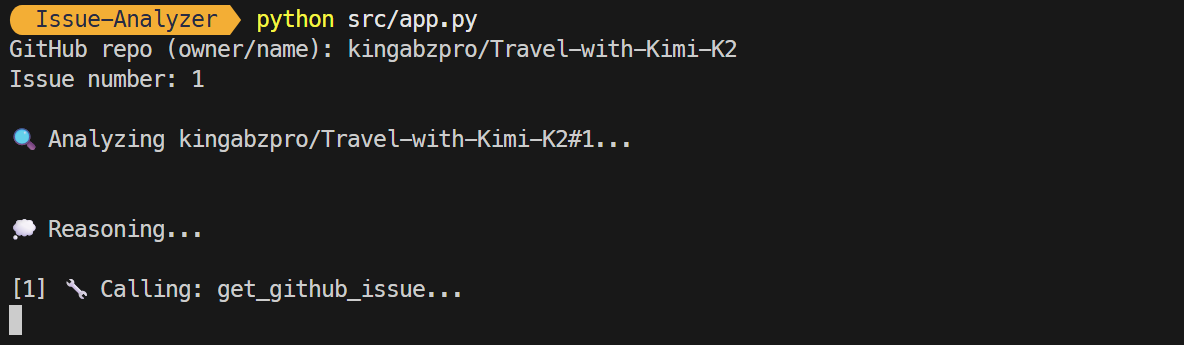
Um den Interaktivmodus zu starten, gib folgenden Befehl ein:
python src/app.pyNach dem Start wirst du nach Repository-Name und Issue-Nummer gefragt, und die App beginnt mit Tools und Reasoning, um dich zu unterstützen.
Innerhalb weniger Sekunden erhältst du eine Zusammenfassung des Issues und Wege zur Lösung. Die Zusammenfassung zeigt auch, welche Tools genutzt wurden, und wo die Markdown-Datei mit allen Infos gespeichert ist.
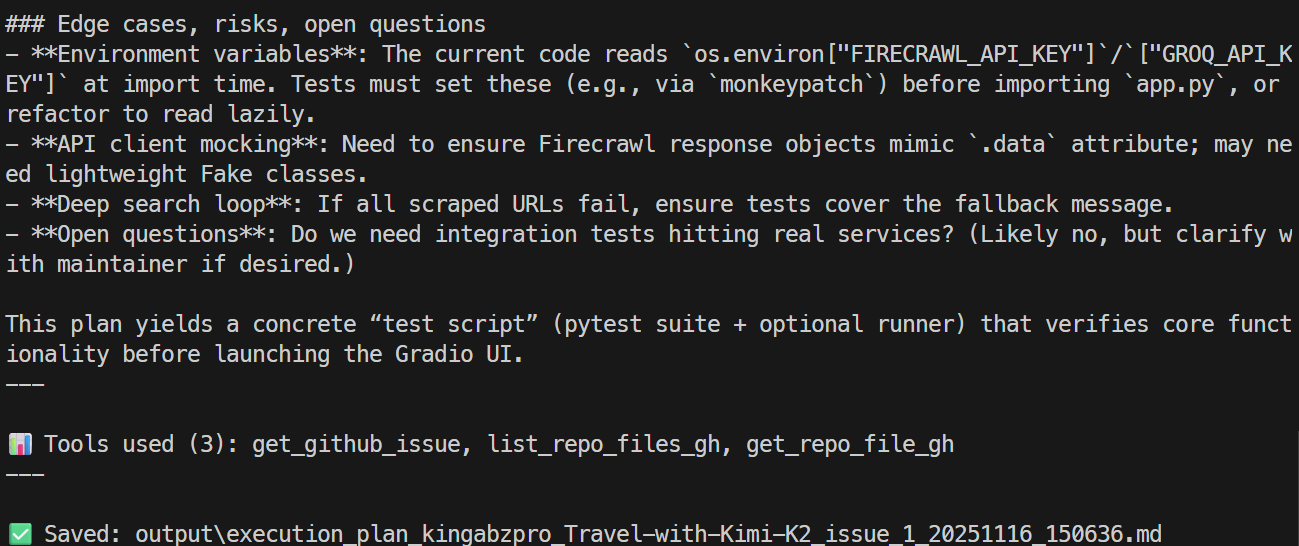
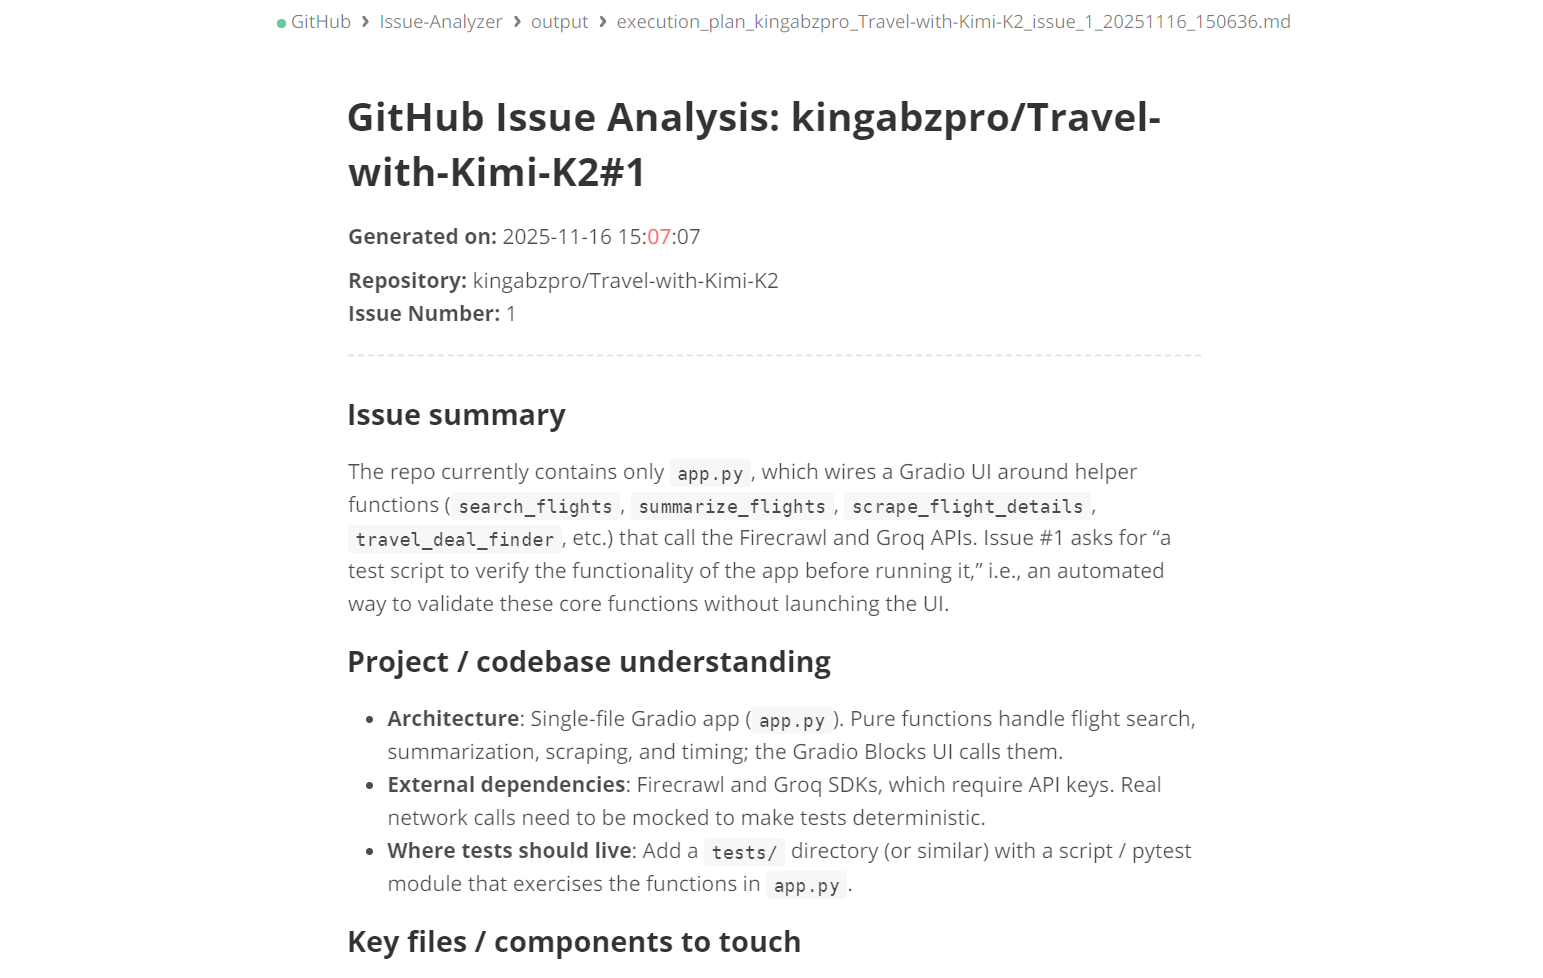
Du kannst die Markdown-Datei öffnen, um den detaillierten Issue-Plan zu prüfen.
Im CLI-Modus musst du Repository und Issue in den Befehl aufnehmen, wie hier gezeigt:
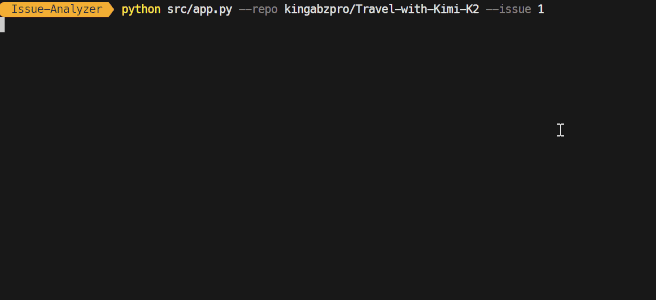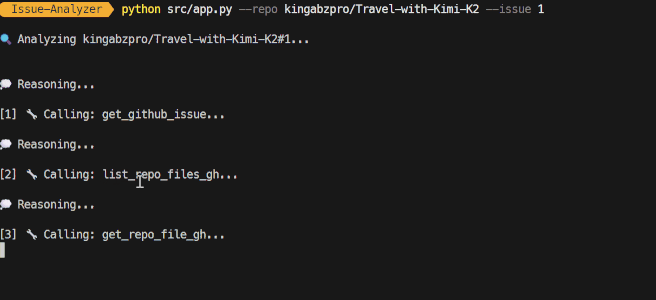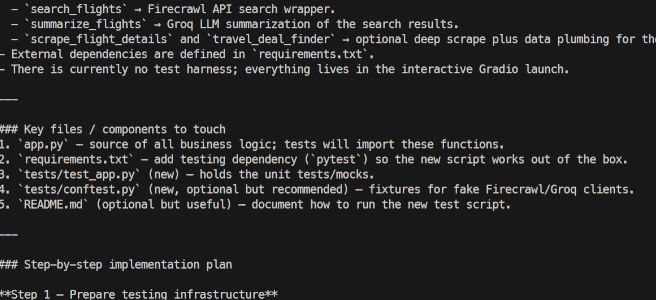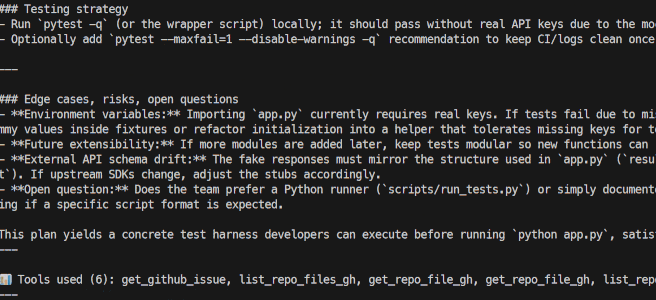
python src/app.py --repo kingabzpro/Travel-with-Kimi-K2 --issue 1Der gesamte Prozess wird gestreamt. Du siehst also, welche Tools der Agent nutzt und wie er denkt. Am Ende wird auch die Antwort live gestreamt.
Die aktuelle Version des GitHub-Issue-Analyzers ist darauf ausgelegt, Issues zu verstehen und präzise Umsetzungspläne zu erstellen.
Das wahre Potenzial agentischer Workflows liegt jedoch darin, alle Schritte nach der Planerstellung zu automatisieren. Hier sind größere Upgrades, die du umsetzen kannst:
Ziel ist es, einen Plan automatisch in einen funktionierenden Pull Request zu überführen. Das verschlankt den Entwicklungsprozess und beschleunigt den Workflow.
Dazu gehört, dass der Agent eigenständig einen neuen Branch anlegt, Änderungen gemäß Plan vornimmt und GitHub-CLI-Workflows wie gh pr create und gh pr view ausführt.
Außerdem generiert das System automatisch PR-Beschreibungen, Changelogs und verknüpfte Issue-Referenzen. Labels werden intelligent vergeben – etwa Bugfix, Enhancement oder Refactor.
Unterm Strich wird der Agent so zu einem vollständig autonomen „Issue to Pull Request“-Automationssystem – mit deutlich mehr Produktivität und Konsistenz im Entwicklungszyklus.
Dieses Upgrade erweitert die Issue-Analyse um Batch-Fähigkeiten. Statt einzelne Probleme zu betrachten, können Teams mehrere Issues parallel oder sequenziell scannen. So lassen sich große Backlogs effizienter bearbeiten.
Zudem erleichtert es das Erkennen doppelter oder verwandter Issues und verbessert die Organisation. Issues können etwa nach Komplexität, Subsystem oder Impact klassifiziert werden.
Um Abläufe weiter zu straffen, lassen sich GitHub- oder Firecrawl-Tools im Batch-Modus ausführen. Am Ende reicht ein einziger Befehl, um Dutzende oder gar Hunderte Issues automatisch zu triagieren.
Bevor ein Pull Request (PR) erstellt wird, sollte der Agent die vorgeschlagenen Änderungen gründlich validieren – nicht nur generieren. Geplante Features umfassen das Ausführen von Unit-Tests über GitHub Actions oder lokale Testrunner, um das erwartete Verhalten sicherzustellen.
Auch die Prüfung von Abhängigkeiten ist entscheidend: Imports verifizieren, fehlende Module erkennen, Versionskonflikte beheben. Zusätzlich sichern Linting, Formatierung und Typprüfungen die Codequalität.
Wichtig ist zudem, bestehende Build-Pipelines nicht zu brechen und Breaking Changes oder Regressionen zu erkennen. So bleibt der PR sauber, sicher und produktionsreif.
Komplexe, mehrstufige Agenten mit GPT-5.1 Codex und openai-agents zu bauen, ist überraschend einfach. Du musst im Kern nur eigene Tools definieren und dem Modell klar sagen, wann und wie es sie nutzen soll.
In diesem Tutorial habe ich die GitHub CLI genutzt, weil sie schnell, intuitiv und leicht integrierbar ist. Genauso gut könntest du das GitHub-Python-SDK, direkte API-Calls oder andere CLI-/Bash-Tools verwenden. Die Flexibilität ist hier der eigentliche Hebel.
Du kannst dieses Setup beliebig erweitern.
Zum Beispiel könntest du bauen:
Ziel dieses Tutorials war zu zeigen, was GPT-5.1 Codex wirklich kann: Es ruft Tools mühelos auf, versteht große Codebasen, denkt strukturiert und kann lange Automationsketten ohne ständige Nutzereingaben ausführen.
Wenn du mehr über den Aufbau von KI-Agenten lernen willst, schau dir unseren AI Agents with Google ADK Kurs an – und unsere Liste mit spannenden KI-Agent-Projekten zum Nachbauen.
Top-DataCamp-Kurse
Kurs
Kurs
Üben und Lernpfad deinen Fortschritt.
Weiter Mit GoogleBlog
Blog
Hesam Sheikh Hassani
15 Min.
Tutorial
Matt Crabtree
5 Min.
Tutorial
Kurtis Pykes
15 Min.
Tutorial
Mark Pedigo
10 Min.
Tutorial
DataCamp Team
5 Min.


