Anthropic just shipped Claude Opus 5.5, and the story is all about economics and safety. The model costs 40% less to run than Opus 5 (which itself was released at the same price as its predecessor Opus 4.6, 4.7, and 4.8), generates output over 30% faster, and posts the best scores Anthropic has measured on its internal alignment suite. Performance-wise, it lands close to Claude Fable 5.1 on most tasks, but at a fraction of the price.
We had been expecting a release this week and were watching the news closely. This is the first release since Anthropic CEO Dario Amodei's publically call to "pace the frontier," by which he meant keeping safety work ahead of capability gains rather than racing to ship the most powerful model possible. It might seem contradictory, hypocritical or inconsistent at first glance to release a new model one week after calling for a slowdown in AI. But it's maybe not so inconsistent after all. Opus 5.5 is not about raw intelligence. It's about the same performance but cheaper and with tighter alignment.
Within hours, OpenAI responded with their new Sol and Luna models. Read about it in our GPT-6 Sol and Luna guide and our hands-on comparison of GPT-6 Sol versus Claude Opus 5.5.
What Is Claude Opus 5.5?
Claude Opus 5.5 is the first release in Anthropic's new "5.5" generation. It now sits at the top of Anthropic's model lineup. Sonnet and Haiku versions are expected to follow in the coming days or weeks.
Opus 5.5 is built for the same kind of demanding jobs Opus models have always targeted: long, agentic coding runs, complex research and analysis, and multi-step workflows that need to hold up over many hours without drifting.
Where it's different this time around: Opus 5.5 is a leaner, more efficient version of what Opus 5 already did, which is doing comparable work with fewer tokens per task, which is where most of the cost and speed gains come from.
What's New with Claude Opus 5.5?
Let's start with cost since it's really the headline claim.
Meaningfully cheaper and faster
Cache reads, which Anthropic says make up most agentic and coding costs, drop 60%, from $0.50 to $0.20 per million tokens. Input and output tokens are also down 20%, and the model generates output more than 30% faster than Opus 5. Also in the release but not as highlighted: Anthropic is loosening five-hour usage limits on Pro, Max, and Team plans, and giving subscribers a bankable rate-limit reset they can save and reuse.
Anthropic says the biggest gains show up on sprawling, real-world tasks rather than short benchmark problems. One early tester reportedly completed a 680,000-line code migration in under a day — work that would otherwise have taken an engineering team weeks.
In an internal test where Opus 5.5 was asked to cut load times across every page of a web app, it succeeded 39 out of 40 times, which shows that the model is consistent, too.
Better communication
Anthropic singles out writing style as a fix for one of the most common complaints about Opus 5: verbosity and jargon. Opus 5.5 is described as leading with the most important information, using less idiosyncratic phrasing, and sticking closer to whatever house style it's given. The release includes a side-by-side bug-explanation example, and the Opus 5.5 version is noticeably shorter and front-loads the actual root cause instead of building up to it.
Claude Opus 5.5 Benchmark Results
Here's how Opus 5.5 stacks up against Fable 5.1, Opus 5, and the competition, per Anthropic's own release.
| | Opus 5.5 | Fable 5.1 | Opus 5 | GPT-6 Astra | GPT-5.6 Sol |
|---|
| Agentic coding — Terminal-Bench 4.0 | 66.4% | 55.8% | 52.3% | 57.9% | 37.3% |
| Agentic coding — FrontierCode v1.1 (Main) | 54.4% | 50.3% | 48.0% | 53.3% | 47.5% |
| Agentic coding — CursorBench 4.0 | 57.8% | 51.8% | 46.6% | — | 41.7% |
| Knowledge work — GDPval-AA v2.1 | 1846 | 1735 | 1708 | 1542 | 1588 |
| Business workflows — AutomationBench | 40.0% | 31.4% | 26.9% | 41.4% | 28.8% |
| Multidisciplinary reasoning — Humanity's Last Exam (with tools) | 67.7% | 65.6% | 63.6% | 57.2% | — |
| Agentic scientific research — Terminal-Bench-Science 0.1 | 58.7% | 52.6% | 29.0% | 64.6% | 22.4% |
| Computer use — OSWorld 2.0 (partial) | 81.8% | 80.7% | 74.0% | — | — |
| Visual chart recognition — Chartography (with tools) | 89.0% | 88.4% | 83.4% | — | — |
A few things stand out. Opus 5.5 beats Fable 5.1 on every benchmark shown here, which is notable given that Anthropic has been pitching 5.5 as "Fable-level performance, cheaper" rather than a straight upgrade. I think Anthropic is not calling this out because they want to protect their tier structure. What I mean is: Anthropic sells Fable at a premium as the top of the lineup. If Opus 5.5 is known to much as beating Fable - well, that's an awkward question for anyone paying Fable prices.
On agentic coding specifically, the gap over Opus 5 is big across all three benchmarks. The CursorBench jump is the largest single-benchmark improvement in the table.
The exceptions are worth flagging too. GPT-6 Astra edges out Opus 5.5 on both AutomationBench (business workflows) and Terminal-Bench-Science (agentic scientific research), and by a fairly clear margin on the second one. So you could say that Opus 5.5 is still behind on some real-world workflow and science-research tasks.
Wait, What About "Pacing the Frontier"?
The optics did look strange at first. Days after Amodei called for slowing AI progress down, Anthropic shipped a new flagship.
A cynical read is that "pacing the frontier" was never really about safety at all. It's easier to call for the industry to slow down when you're in the lead and, by revenue, Anthropic is in the lead.
But to take another interpretation, "pacing the frontier" might never have been an argument against releasing models, but more like an argument about what kind of models you would release. By that interpretation, Opus 5.5 fits the message.
Anthropic says Opus 5.5 performs roughly at the level of Fable 5.1, a model that already existed. The capability ceiling didn't move. What changed is that the same tier of work now costs 40% less and runs over 30% faster. It also has better internal alignment scores.
Claude Opus 5.5 Pricing
| Per 1M tokens | Opus 5.5 | Opus 5 |
|---|
| Input | $4 | $5 |
| Output | $20 | $25 |
| Cache reads | $0.20 | $0.50 |
| Cache writes | $5 | $6.25 |
Fast mode — running at up to 2.5x speed — is available in Claude Code and the Claude Platform at $8 per million input tokens and $40 per million output tokens.
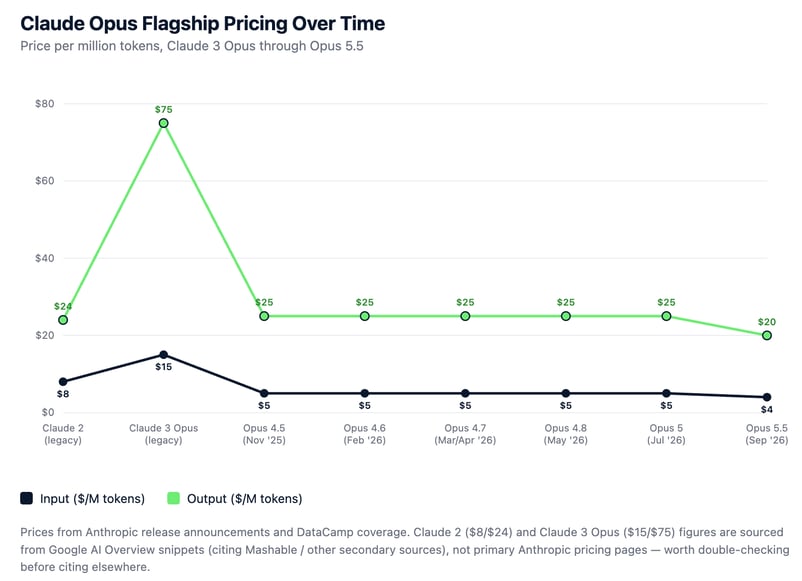
I created a chart so we can see Claude Opus pricing over time. It has gotten less expensive over time.
What We Know About How the New Safeguards Work
Here's what we know from the release notes:
Opus 5.5 gets the same class of protective measures Anthropic reserves for Fable 5.1 in three flagged areas: cybersecurity, biology, and distillation.
Anthropic doesn't detail the detection mechanism itself, but the outcome is a screening step that runs on incoming requests: something in the prompt gets flagged as falling into one of those three categories, and instead of the request going to Opus 5.5, it gets handed off before it's answered. For example, a cybersecurity-flagged prompt drops down to the older Opus 4.8, while a biology-related prompt gets bumped up to Opus 5 instead. So the safeguard isn't a filter on the output — it's a routing decision made before generation starts, and which model catches the request depends on which category tripped it.
Anthropic also had the model externally evaluated by METR and Frontier Design before release (details on what those organizations are in the FAQs), giving its safety claims an outside check rather than just Anthropic's own word for it.
Claude Opus 5.5 Availability
Claude Opus 5.5 is live now across Anthropic's own platforms as well as Amazon Web Services, Google Cloud, and Microsoft Azure. Developers on the Claude Platform can access it directly as claude-opus-5-5.
Conclusion
Claude Opus 5.5 is a win for users. It's cheaper, faster, and safer than its predecessor.
The safety angle is the more interesting story long-term. Coming right after Amodei's "pacing the frontier" speeches, the optics could have been bad — a new flagship model, a week after a public call to slow down. But the release, deliberately or not, threads that needle: no capability ceiling was raised, and Opus 5.5 comes with the same tier of safeguards previously reserved for Fable, and a meaningfully lower rate of sandbox-escape attempts in testing. I don't know if that's "pacing the frontier" in practice or just good timing. But it's at least consistent with the argument Amodei made.


Anthropic just shipped Claude Opus 5.5, and the story is all about economics and safety. The model costs 40% less to run than Opus 5 (which itself was released at the same price as its predecessor Opus 4.6, 4.7, and 4.8), generates output over 30% faster, and posts the best scores Anthropic has measured on its internal alignment suite. Performance-wise, it lands close to Claude Fable 5.1 on most tasks, but at a fraction of the price.
We had been expecting a release this week and were watching the news closely. This is the first release since Anthropic CEO Dario Amodei's publically call to "pace the frontier," by which he meant keeping safety work ahead of capability gains rather than racing to ship the most powerful model possible. It might seem contradictory, hypocritical or inconsistent at first glance to release a new model one week after calling for a slowdown in AI. But it's maybe not so inconsistent after all. Opus 5.5 is not about raw intelligence. It's about the same performance but cheaper and with tighter alignment.
Within hours, OpenAI responded with their new Sol and Luna models. Read about it in our GPT-6 Sol and Luna guide and our hands-on comparison of GPT-6 Sol versus Claude Opus 5.5.
What Is Claude Opus 5.5?
Claude Opus 5.5 is the first release in Anthropic's new "5.5" generation. It now sits at the top of Anthropic's model lineup. Sonnet and Haiku versions are expected to follow in the coming days or weeks.
Opus 5.5 is built for the same kind of demanding jobs Opus models have always targeted: long, agentic coding runs, complex research and analysis, and multi-step workflows that need to hold up over many hours without drifting.
Where it's different this time around: Opus 5.5 is a leaner, more efficient version of what Opus 5 already did, which is doing comparable work with fewer tokens per task, which is where most of the cost and speed gains come from.
What's New with Claude Opus 5.5?
Let's start with cost since it's really the headline claim.
Meaningfully cheaper and faster
Cache reads, which Anthropic says make up most agentic and coding costs, drop 60%, from $0.50 to $0.20 per million tokens. Input and output tokens are also down 20%, and the model generates output more than 30% faster than Opus 5. Also in the release but not as highlighted: Anthropic is loosening five-hour usage limits on Pro, Max, and Team plans, and giving subscribers a bankable rate-limit reset they can save and reuse.
Performance that shows up most on long, messy jobs
Anthropic says the biggest gains show up on sprawling, real-world tasks rather than short benchmark problems. One early tester reportedly completed a 680,000-line code migration in under a day — work that would otherwise have taken an engineering team weeks.
In an internal test where Opus 5.5 was asked to cut load times across every page of a web app, it succeeded 39 out of 40 times, which shows that the model is consistent, too.
Better communication
Anthropic singles out writing style as a fix for one of the most common complaints about Opus 5: verbosity and jargon. Opus 5.5 is described as leading with the most important information, using less idiosyncratic phrasing, and sticking closer to whatever house style it's given. The release includes a side-by-side bug-explanation example, and the Opus 5.5 version is noticeably shorter and front-loads the actual root cause instead of building up to it.
Claude Opus 5.5 Benchmark Results
Here's how Opus 5.5 stacks up against Fable 5.1, Opus 5, and the competition, per Anthropic's own release.
A few things stand out. Opus 5.5 beats Fable 5.1 on every benchmark shown here, which is notable given that Anthropic has been pitching 5.5 as "Fable-level performance, cheaper" rather than a straight upgrade. I think Anthropic is not calling this out because they want to protect their tier structure. What I mean is: Anthropic sells Fable at a premium as the top of the lineup. If Opus 5.5 is known to much as beating Fable - well, that's an awkward question for anyone paying Fable prices.
On agentic coding specifically, the gap over Opus 5 is big across all three benchmarks. The CursorBench jump is the largest single-benchmark improvement in the table.
The exceptions are worth flagging too. GPT-6 Astra edges out Opus 5.5 on both AutomationBench (business workflows) and Terminal-Bench-Science (agentic scientific research), and by a fairly clear margin on the second one. So you could say that Opus 5.5 is still behind on some real-world workflow and science-research tasks.
Wait, What About "Pacing the Frontier"?
The optics did look strange at first. Days after Amodei called for slowing AI progress down, Anthropic shipped a new flagship.
A cynical read is that "pacing the frontier" was never really about safety at all. It's easier to call for the industry to slow down when you're in the lead and, by revenue, Anthropic is in the lead.
But to take another interpretation, "pacing the frontier" might never have been an argument against releasing models, but more like an argument about what kind of models you would release. By that interpretation, Opus 5.5 fits the message.
Anthropic says Opus 5.5 performs roughly at the level of Fable 5.1, a model that already existed. The capability ceiling didn't move. What changed is that the same tier of work now costs 40% less and runs over 30% faster. It also has better internal alignment scores.
Claude Opus 5.5 Pricing
Fast mode — running at up to 2.5x speed — is available in Claude Code and the Claude Platform at $8 per million input tokens and $40 per million output tokens.
I created a chart so we can see Claude Opus pricing over time. It has gotten less expensive over time.
What We Know About How the New Safeguards Work
Here's what we know from the release notes:
Opus 5.5 gets the same class of protective measures Anthropic reserves for Fable 5.1 in three flagged areas: cybersecurity, biology, and distillation.
Anthropic doesn't detail the detection mechanism itself, but the outcome is a screening step that runs on incoming requests: something in the prompt gets flagged as falling into one of those three categories, and instead of the request going to Opus 5.5, it gets handed off before it's answered. For example, a cybersecurity-flagged prompt drops down to the older Opus 4.8, while a biology-related prompt gets bumped up to Opus 5 instead. So the safeguard isn't a filter on the output — it's a routing decision made before generation starts, and which model catches the request depends on which category tripped it.
Anthropic also had the model externally evaluated by METR and Frontier Design before release (details on what those organizations are in the FAQs), giving its safety claims an outside check rather than just Anthropic's own word for it.
Claude Opus 5.5 Availability
Claude Opus 5.5 is live now across Anthropic's own platforms as well as Amazon Web Services, Google Cloud, and Microsoft Azure. Developers on the Claude Platform can access it directly as
claude-opus-5-5.Conclusion
Claude Opus 5.5 is a win for users. It's cheaper, faster, and safer than its predecessor.
The safety angle is the more interesting story long-term. Coming right after Amodei's "pacing the frontier" speeches, the optics could have been bad — a new flagship model, a week after a public call to slow down. But the release, deliberately or not, threads that needle: no capability ceiling was raised, and Opus 5.5 comes with the same tier of safeguards previously reserved for Fable, and a meaningfully lower rate of sandbox-escape attempts in testing. I don't know if that's "pacing the frontier" in practice or just good timing. But it's at least consistent with the argument Amodei made.