Say you're building a pipeline that needs to handle complex multi-step code reasoning and client-facing document summarization. Which model do you reach for? That's the kind of question that makes this comparison useful, not as a benchmark exercise, but as a practical decision that shapes what your system can actually do.
Here's how DeepSeek and Claude differ in architecture, performance, and pricing, so you can choose based on your actual workload.
If you're interested in up-to-date AI models, make sure to also check out our guide on Meta's Muse Spark.
What Is DeepSeek?
DeepSeek is an AI model family developed by the Chinese research company Hangzhou DeepSeek Artificial Intelligence, built around advanced reasoning, coding, and logic-heavy tasks. Most of its models are freely available as open weights under the MIT License, which is part of why the January 2025 release of DeepSeek-R1 was such a big deal. It matched the reasoning quality of leading proprietary models at a fraction of the training cost.
The lineup has evolved quickly. DeepSeek-V3 (December 2024) established a solid general-purpose baseline, while R1 introduced a dedicated reasoning model trained with reinforcement learning, designed to work through problems step by step before responding. DeepSeek-V3.1 followed with a hybrid architecture that switches between "thinking" and "non-thinking" modes in a single deployment. DeepSeek V4 is widely anticipated as the next major release, with early reports pointing to stronger coding, long-context software engineering, and native multimodal support.
DeepSeek's strengths are logic chains, structured reasoning precision, and fast inference. It's a natural fit for developers working on analytical or code-heavy tasks.
What Is Claude?
Claude is Anthropic's AI model family, built around a core philosophy of aligned reasoning: making models that are capable, consistent, honest, and less likely to go off-track. The current Claude 4 family includes Haiku 4.5 (fast and lightweight), Sonnet 4.6 (the everyday workhorse), and Opus 4.6 (the flagship for complex reasoning and long-context tasks).
What sets Claude apart is its conversational fluency, nuanced instruction following, and safety-oriented behavior. Claude models are multimodal, handling text, images, and documents. Opus 4.6 and Sonnet 4.6 both support a 1 million token context window, one of the largest available in 2026. For teams building client-facing tools or enterprise workflows where reliability matters, those design priorities translate into real, practical benefits.
DeepSeek vs. Claude: Core Architectural Differences
Foundational philosophy and training emphasis
DeepSeek approaches intelligence from a reasoning-first angle. Its R1 lineage was trained with reinforcement learning to develop explicit chain-of-thought reasoning, so the model works through problems methodically before answering. You can see this clearly in math, logic, and code: structured, step-by-step solutions that are easy to audit.
Claude is trained with Constitutional AI, Anthropic's alignment technique, which shapes its reasoning toward safety, coherence, and honest response generation. The result is a generalist that's broadly capable rather than narrowly specialized. This difference also shows up with ambiguous prompts. DeepSeek tends to need more precise prompt engineering in open-ended scenarios, while Claude handles conversational drift well and usually infers intent without much hand-holding.
Context window, multimodal support, and inference style
Claude Opus 4.6 and Sonnet 4.6 support 1M token windows at standard pricing. DeepSeek-V3.1 supports up to 128K tokens. On inference, DeepSeek's Mixture-of-Experts architecture (671B total parameters, 37B activated per token) keeps costs low by only activating part of the network per request. Claude's architecture is proprietary, but its performance across reasoning, coding, and multimodal tasks is well-established in independent evaluations.
Performance differences are real, but they're task-dependent. Neither model leads across the board.
Reasoning and logic tasks
DeepSeek is highly specialized here. Its R1 model was built to show its reasoning steps, making it well-suited for problems where you need to verify the path, not just the answer: algorithms, proofs, formal math. Claude approaches reasoning through a generalist lens, making it stronger for synthesis and judgment-based tasks that mix evidence, context, and nuance. If the problem has a formal structure, DeepSeek's chain-of-thought output is often easier to audit. If it requires weighing perspectives, Claude tends to do better.
Coding and developer workflows
DeepSeek is specifically tailored for code reasoning, with strong results on algorithmic challenges and isolated coding tasks. Claude tends to pull ahead in broader software engineering work: understanding multi-file architecture, refactoring across a large project, reasoning about system design across many turns. For quick scripts or debugging a specific function, DeepSeek is a solid choice. For code review or complex project-level work, Claude's long-context coherence becomes a real advantage.
Text generation and summarization
Claude is widely recognized for its natural language fluency. Its training explicitly rewards coherent, well-structured prose, making it the stronger choice for client-facing content, polished summaries, or anything where tone matters. DeepSeek handles text generation well, but output quality is more task-dependent and tends toward terseness on open-ended prompts.
Understanding complex instructions
Claude tracks multi-part instructions reliably across long conversations, even when prompts evolve or carry multiple constraints simultaneously. DeepSeek handles complex prompts too, but benefits from more explicit structuring, especially in conversational or multi-turn settings.
Handling long contexts
Claude Opus 4.6 and Sonnet 4.6 support 1M token windows with strong retrieval accuracy across lengthy text. DeepSeek processes long contexts well within its 128K window. For most workloads, both are capable; the gap matters most at very large context sizes or when precise needle-in-a-haystack retrieval is a priority.
A note on benchmarks
Published benchmark scores shift between model updates and vary significantly by task and prompt style. Treat any specific comparison as a directional signal, not a verdict. The most reliable test is running both models on your actual use case.
Use Cases: When to Use DeepSeek vs. Claude
Best for complex reasoning and code
DeepSeek's explicit chain-of-thought training makes it a strong choice for algorithmic challenges, mathematical proofs, and code debugging where you need the model to show its work. Developers who want a capable model at low cost for analytical tasks will find the DeepSeek API very competitive.
Best for conversational and general NLP
Claude is the better fit when you need natural, fluent text: summarizing research, drafting client communications, or generating reports that non-technical readers will consume. Its conversational coherence across multi-turn interactions also makes it well-suited for building assistants or chatbots.
Best for safety-sensitive applications
Claude's Constitutional AI training reduces the likelihood of harmful, biased, or off-target outputs. Teams in healthcare, education, or legal tech, where model behavior in edge cases carries real risk, should weigh Claude's safety design seriously. DeepSeek's open nature gives you more control over fine-tuning and deployment, but it also places more responsibility on your team to manage output safety.
Best for rapid prototyping or low-cost inference
DeepSeek's efficient architecture makes inference remarkably affordable. Its MIT-licensed weights can be downloaded and run locally. For high-volume tasks, budget-constrained projects, or teams that want to self-host, DeepSeek's pricing and deployment flexibility are hard to beat.
DeepSeek vs. Claude in Developer Workflows
Both models support code completion and generation across popular languages, but their strengths diverge at the task level. DeepSeek performs well on focused generation: writing a specific function, implementing an algorithm, or generating unit tests. Claude tends to be stronger on refactoring tasks that require understanding broader architectural context, like renaming patterns consistently, identifying design issues, or explaining why a particular structure will cause downstream problems.
For API integration, Claude has deep support across AWS Bedrock, Google Vertex AI, and Microsoft Foundry. Opus 4.6 is designed for long-horizon, multi-step agent tasks. DeepSeek is accessible via platform.deepseek.com and through a growing ecosystem of third-party providers; its open weights make it a popular choice for teams building self-hosted inference stacks.
DeepSeek vs. Claude in Language Reasoning
Claude handles summarization and open-ended Q&A well. Responses are organized, contextually aware, and easy to read, and it naturally synthesizes multiple sources into a coherent response. On complex instruction following, Claude tracks all requirements reliably across long outputs. DeepSeek performs competitively on structured Q&A and factual retrieval, though it benefits from more explicit step-by-step structuring in the prompt.
On hallucinations: Claude's safety-aligned training makes it more likely to hedge or decline when uncertain, which cuts confident errors but can occasionally produce overly cautious responses. DeepSeek's reasoning models are generally more reliable on tasks with verifiable answers, but can still produce confident errors outside their training data. Neither is immune, and both benefit from retrieval-augmented setups when factual accuracy is critical.
Pricing & Accessibility: DeepSeek vs. Claude
Claude is a fully proprietary model accessible via Anthropic's subscription tiers (free, Pro, and Max) and a token-based API spanning Haiku 4.5, Sonnet 4.6, and Opus 4.6. Business access comes via Team and Enterprise plans. All access is cloud-based through Anthropic or partner providers; there are no open weights.
DeepSeek offers model weights freely under the MIT License, making self-hosted deployments viable for teams with GPU infrastructure. It also provides a hosted API at platform.deepseek.com with pay-per-token pricing, including significant savings through prompt caching, making it appealing for high-volume workloads.
For most teams, the decision comes down to deployment needs and workload type. DeepSeek's low per-token cost and self-hosting option work well for budget-constrained or privacy-first environments. Claude's deep cloud integrations make more sense when you're operating within an existing enterprise stack or need guaranteed uptime SLAs.
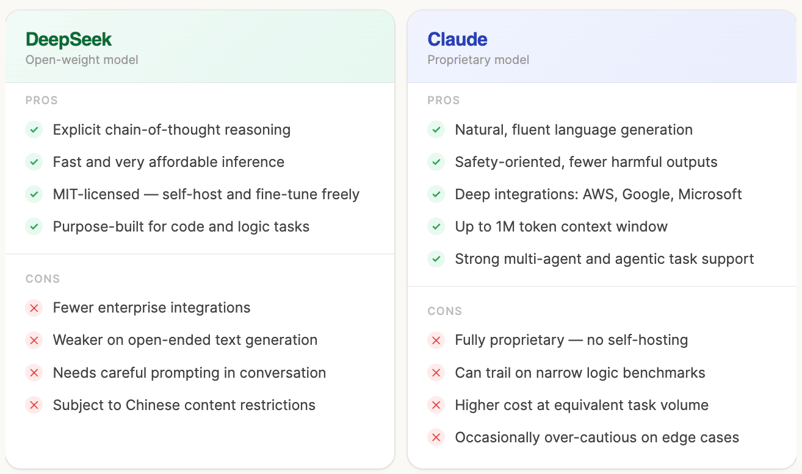
Pros and Cons: DeepSeek vs. Claude
Conclusion
Both are capable, well-supported models that serve meaningfully different needs. DeepSeek's open licensing, fast inference, and reasoning precision make it a strong fit for developers working on code-heavy or logic-intensive tasks who need low-cost, self-hostable infrastructure. Claude's alignment philosophy, language fluency, and enterprise ecosystem make it the better choice for client-facing applications, safety-sensitive workflows, or anywhere that natural language quality and predictable behavior carry real weight.
The more useful question isn't which model is better: it's what your workload actually demands. In many real-world architectures, there's a solid case for using both, routing tasks by type rather than committing exclusively to one provider.


 Khalid Abdelaty• 12 นาที
 Tom Farnschläder• 12 นาที

 Vinod Chugani• 9 นาที



Say you're building a pipeline that needs to handle complex multi-step code reasoning and client-facing document summarization. Which model do you reach for? That's the kind of question that makes this comparison useful, not as a benchmark exercise, but as a practical decision that shapes what your system can actually do.
Here's how DeepSeek and Claude differ in architecture, performance, and pricing, so you can choose based on your actual workload.
If you're interested in up-to-date AI models, make sure to also check out our guide on Meta's Muse Spark.
What Is DeepSeek?
DeepSeek is an AI model family developed by the Chinese research company Hangzhou DeepSeek Artificial Intelligence, built around advanced reasoning, coding, and logic-heavy tasks. Most of its models are freely available as open weights under the MIT License, which is part of why the January 2025 release of DeepSeek-R1 was such a big deal. It matched the reasoning quality of leading proprietary models at a fraction of the training cost.
The lineup has evolved quickly. DeepSeek-V3 (December 2024) established a solid general-purpose baseline, while R1 introduced a dedicated reasoning model trained with reinforcement learning, designed to work through problems step by step before responding. DeepSeek-V3.1 followed with a hybrid architecture that switches between "thinking" and "non-thinking" modes in a single deployment. DeepSeek V4 is widely anticipated as the next major release, with early reports pointing to stronger coding, long-context software engineering, and native multimodal support.
DeepSeek's strengths are logic chains, structured reasoning precision, and fast inference. It's a natural fit for developers working on analytical or code-heavy tasks.
What Is Claude?
Claude is Anthropic's AI model family, built around a core philosophy of aligned reasoning: making models that are capable, consistent, honest, and less likely to go off-track. The current Claude 4 family includes Haiku 4.5 (fast and lightweight), Sonnet 4.6 (the everyday workhorse), and Opus 4.6 (the flagship for complex reasoning and long-context tasks).
What sets Claude apart is its conversational fluency, nuanced instruction following, and safety-oriented behavior. Claude models are multimodal, handling text, images, and documents. Opus 4.6 and Sonnet 4.6 both support a 1 million token context window, one of the largest available in 2026. For teams building client-facing tools or enterprise workflows where reliability matters, those design priorities translate into real, practical benefits.
DeepSeek vs. Claude: Core Architectural Differences
Foundational philosophy and training emphasis
DeepSeek approaches intelligence from a reasoning-first angle. Its R1 lineage was trained with reinforcement learning to develop explicit chain-of-thought reasoning, so the model works through problems methodically before answering. You can see this clearly in math, logic, and code: structured, step-by-step solutions that are easy to audit.
Claude is trained with Constitutional AI, Anthropic's alignment technique, which shapes its reasoning toward safety, coherence, and honest response generation. The result is a generalist that's broadly capable rather than narrowly specialized. This difference also shows up with ambiguous prompts. DeepSeek tends to need more precise prompt engineering in open-ended scenarios, while Claude handles conversational drift well and usually infers intent without much hand-holding.
Context window, multimodal support, and inference style
Claude Opus 4.6 and Sonnet 4.6 support 1M token windows at standard pricing. DeepSeek-V3.1 supports up to 128K tokens. On inference, DeepSeek's Mixture-of-Experts architecture (671B total parameters, 37B activated per token) keeps costs low by only activating part of the network per request. Claude's architecture is proprietary, but its performance across reasoning, coding, and multimodal tasks is well-established in independent evaluations.
DeepSeek vs. Claude: Performance Comparison
Performance differences are real, but they're task-dependent. Neither model leads across the board.
Reasoning and logic tasks
DeepSeek is highly specialized here. Its R1 model was built to show its reasoning steps, making it well-suited for problems where you need to verify the path, not just the answer: algorithms, proofs, formal math. Claude approaches reasoning through a generalist lens, making it stronger for synthesis and judgment-based tasks that mix evidence, context, and nuance. If the problem has a formal structure, DeepSeek's chain-of-thought output is often easier to audit. If it requires weighing perspectives, Claude tends to do better.
Coding and developer workflows
DeepSeek is specifically tailored for code reasoning, with strong results on algorithmic challenges and isolated coding tasks. Claude tends to pull ahead in broader software engineering work: understanding multi-file architecture, refactoring across a large project, reasoning about system design across many turns. For quick scripts or debugging a specific function, DeepSeek is a solid choice. For code review or complex project-level work, Claude's long-context coherence becomes a real advantage.
Text generation and summarization
Claude is widely recognized for its natural language fluency. Its training explicitly rewards coherent, well-structured prose, making it the stronger choice for client-facing content, polished summaries, or anything where tone matters. DeepSeek handles text generation well, but output quality is more task-dependent and tends toward terseness on open-ended prompts.
Understanding complex instructions
Claude tracks multi-part instructions reliably across long conversations, even when prompts evolve or carry multiple constraints simultaneously. DeepSeek handles complex prompts too, but benefits from more explicit structuring, especially in conversational or multi-turn settings.
Handling long contexts
Claude Opus 4.6 and Sonnet 4.6 support 1M token windows with strong retrieval accuracy across lengthy text. DeepSeek processes long contexts well within its 128K window. For most workloads, both are capable; the gap matters most at very large context sizes or when precise needle-in-a-haystack retrieval is a priority.
A note on benchmarks
Published benchmark scores shift between model updates and vary significantly by task and prompt style. Treat any specific comparison as a directional signal, not a verdict. The most reliable test is running both models on your actual use case.
Use Cases: When to Use DeepSeek vs. Claude
Best for complex reasoning and code
DeepSeek's explicit chain-of-thought training makes it a strong choice for algorithmic challenges, mathematical proofs, and code debugging where you need the model to show its work. Developers who want a capable model at low cost for analytical tasks will find the DeepSeek API very competitive.
Best for conversational and general NLP
Claude is the better fit when you need natural, fluent text: summarizing research, drafting client communications, or generating reports that non-technical readers will consume. Its conversational coherence across multi-turn interactions also makes it well-suited for building assistants or chatbots.
Best for safety-sensitive applications
Claude's Constitutional AI training reduces the likelihood of harmful, biased, or off-target outputs. Teams in healthcare, education, or legal tech, where model behavior in edge cases carries real risk, should weigh Claude's safety design seriously. DeepSeek's open nature gives you more control over fine-tuning and deployment, but it also places more responsibility on your team to manage output safety.
Best for rapid prototyping or low-cost inference
DeepSeek's efficient architecture makes inference remarkably affordable. Its MIT-licensed weights can be downloaded and run locally. For high-volume tasks, budget-constrained projects, or teams that want to self-host, DeepSeek's pricing and deployment flexibility are hard to beat.
DeepSeek vs. Claude in Developer Workflows
Both models support code completion and generation across popular languages, but their strengths diverge at the task level. DeepSeek performs well on focused generation: writing a specific function, implementing an algorithm, or generating unit tests. Claude tends to be stronger on refactoring tasks that require understanding broader architectural context, like renaming patterns consistently, identifying design issues, or explaining why a particular structure will cause downstream problems.
For API integration, Claude has deep support across AWS Bedrock, Google Vertex AI, and Microsoft Foundry. Opus 4.6 is designed for long-horizon, multi-step agent tasks. DeepSeek is accessible via platform.deepseek.com and through a growing ecosystem of third-party providers; its open weights make it a popular choice for teams building self-hosted inference stacks.
DeepSeek vs. Claude in Language Reasoning
Claude handles summarization and open-ended Q&A well. Responses are organized, contextually aware, and easy to read, and it naturally synthesizes multiple sources into a coherent response. On complex instruction following, Claude tracks all requirements reliably across long outputs. DeepSeek performs competitively on structured Q&A and factual retrieval, though it benefits from more explicit step-by-step structuring in the prompt.
On hallucinations: Claude's safety-aligned training makes it more likely to hedge or decline when uncertain, which cuts confident errors but can occasionally produce overly cautious responses. DeepSeek's reasoning models are generally more reliable on tasks with verifiable answers, but can still produce confident errors outside their training data. Neither is immune, and both benefit from retrieval-augmented setups when factual accuracy is critical.
Pricing & Accessibility: DeepSeek vs. Claude
Claude is a fully proprietary model accessible via Anthropic's subscription tiers (free, Pro, and Max) and a token-based API spanning Haiku 4.5, Sonnet 4.6, and Opus 4.6. Business access comes via Team and Enterprise plans. All access is cloud-based through Anthropic or partner providers; there are no open weights.
DeepSeek offers model weights freely under the MIT License, making self-hosted deployments viable for teams with GPU infrastructure. It also provides a hosted API at platform.deepseek.com with pay-per-token pricing, including significant savings through prompt caching, making it appealing for high-volume workloads.
For most teams, the decision comes down to deployment needs and workload type. DeepSeek's low per-token cost and self-hosting option work well for budget-constrained or privacy-first environments. Claude's deep cloud integrations make more sense when you're operating within an existing enterprise stack or need guaranteed uptime SLAs.
Pros and Cons: DeepSeek vs. Claude
Conclusion
Both are capable, well-supported models that serve meaningfully different needs. DeepSeek's open licensing, fast inference, and reasoning precision make it a strong fit for developers working on code-heavy or logic-intensive tasks who need low-cost, self-hostable infrastructure. Claude's alignment philosophy, language fluency, and enterprise ecosystem make it the better choice for client-facing applications, safety-sensitive workflows, or anywhere that natural language quality and predictable behavior carry real weight.
The more useful question isn't which model is better: it's what your workload actually demands. In many real-world architectures, there's a solid case for using both, routing tasks by type rather than committing exclusively to one provider.