You've fit a regression model, the R² looks decent, and the coefficients make intuitive sense. But a good-looking summary table can hide a badly misspecified model. One scatter plot often catches what the numbers miss: the residual plot.
This article covers what residual plots are, how to read them, the patterns worth knowing, and how to create one in both Python and R. Most beginners skip the diagnostic step entirely. By the end, you won't.
What Is a Residual Plot?
A residual is the gap between what your model predicted and what actually happened: residual = observed − predicted. A residual plot puts those gaps on display. The x-axis shows either the predicted (fitted) values or an explanatory variable; the y-axis shows the residuals. A horizontal reference line sits at zero, representing perfect prediction.
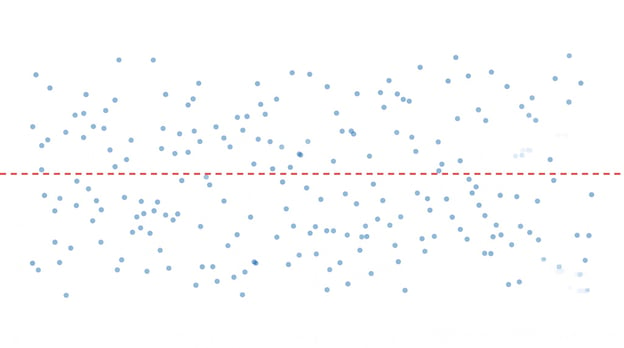
Random scatter plot around zero: a healthy residual plot. Image by Author.
The central idea: if your model has captured the relationship well, the residuals should look like noise. Scattered randomly around zero, no obvious pattern. The moment a shape appears, your model is telling you something it couldn't say through coefficients alone.
How to Interpret a Residual Plot
Look for patterns. Ideally, there shouldn't be an obvious one. That's the whole rule. What the location, spread, and shape of the residuals reveal is where things get interesting.
Location: Is the scatter centered on zero?
Residuals that sit above zero in some regions of fitted values and below in others mean the model is biased. It's consistently over- or under-predicting in certain regions. This often points to a missing variable or a nonlinear relationship that a straight-line model can't capture.
Spread: Does the variance stay roughly constant?
Scan left to right. If the spread of residuals is roughly the same across all fitted values, that's a good sign. If the points fan outward as fitted values increase, the variance is changing. This is called heteroscedasticity. It doesn't break the coefficient estimates, but it makes standard errors unreliable, which matters if you're doing any hypothesis testing.
Shape: Is there a curve or trend?
Flat and patternless is what you want. A U-shape or arch says the model is missing a nonlinear term. Clusters or bands suggest subgroups the model is treating as one. A single point sitting far from everything else is worth investigating.
Common Residual Plot Patterns and What They Mean
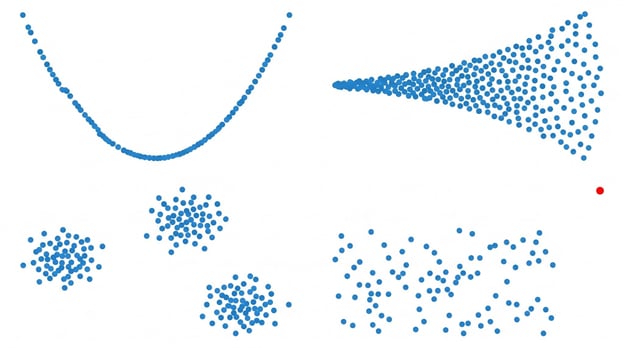
Four residual plot patterns that signal model problems. Image by Author.
Random scatter around zero
The good outcome. Points distributed roughly evenly above and below the zero line, no discernible trend, generally indicates the model is capturing the relationship reasonably well. Some randomness is expected.
Curved pattern
A curved or arch-shaped pattern usually means an unmodeled nonlinear relationship. The model is fitting a straight line through data that bends. The fix is typically adding a polynomial term (like x²) or applying a transformation to the predictor. This is one of the more common patterns in practice, especially when modeling things like housing prices or biological growth.
Funnel or fan shape
Residuals spreading wider as fitted values increase: that's heteroscedasticity, the variance isn't constant. Common in financial data, where prediction errors naturally scale with the magnitude of the outcome. A log transformation of the response variable is often a reasonable first step; weighted least squares is another option.
Clusters or groups
Distinct groups in the residual plot usually mean the data contains subpopulations the model isn't accounting for. There's probably a categorical variable (region, treatment group, product type) that belongs in the model. If you see two or three tight bands of points, start there.
Large isolated residuals
A single point sitting far from the rest deserves a look. It might be a genuine outlier, a data entry error, or an observation with unusual characteristics. Don't delete it automatically. Understand it first. Whether to keep or remove it depends on context, not convenience.
For each of these patterns, the residual plot identifies a symptom, not a diagnosis. It tells you something is off; you still need to figure out why.
What Regression Assumptions Can Residual Plots Check?
With the patterns in mind, it's worth being clear about which regression assumptions a residual plot can and cannot assess.
- Linearity: If the relationship between predictors and the outcome is truly linear, residuals should show no trend when plotted against fitted values. A curve or arc is a direct visual sign that linearity isn't holding.
- Constant variance: The funnel pattern is exactly what heteroscedasticity looks like. If spread increases with fitted values, equal variance is violated. The residuals-vs-fitted plot is probably the most common tool for catching this.
- Independence: If your observations have some natural order (time, space, subject clusters) you can plot residuals against that order to check for patterns. Trending residuals in a time-ordered plot suggest autocorrelation. A plain residuals-vs-fitted plot won't always reveal this though; you sometimes need a dedicated residuals-vs-order plot.
- Outliers and influential observations: Large isolated residuals flag observations the model predicts poorly. For influence specifically, observations that disproportionately pull the regression line, the Residuals vs. Leverage plot is more informative than the basic residual plot.
One thing residual plots cannot reliably assess is normality. A flat residuals-vs-fitted plot doesn't confirm that errors are normally distributed. For that, you need a Q-Q plot. This is a common source of confusion and worth keeping straight.
How to Create a Residual Plot in Python
The standard workflow uses scikit-learn to fit the model and calculate residuals, then matplotlib to visualize them. Here's a complete example using simple linear regression on housing data:
import numpy as np
import matplotlib.pyplot as plt
from sklearn.linear_model import LinearRegression
sqft = np.array([800, 1000, 1200, 1500, 1800, 2000, 2200, 2500, 3000, 3500])
price = np.array([150, 180, 210, 260, 300, 330, 370, 420, 500, 560])
X = sqft.reshape(-1, 1)
model = LinearRegression()
model.fit(X, price)
predicted = model.predict(X)
residuals = price - predicted
plt.figure(figsize=(8, 5))
plt.scatter(predicted, residuals, color='steelblue', edgecolors='white', s=80)
plt.axhline(y=0, color='red', linestyle='--', linewidth=1.2)
plt.xlabel('Fitted Values')
plt.ylabel('Residuals')
plt.title('Residual Plot')
plt.tight_layout()
plt.show()
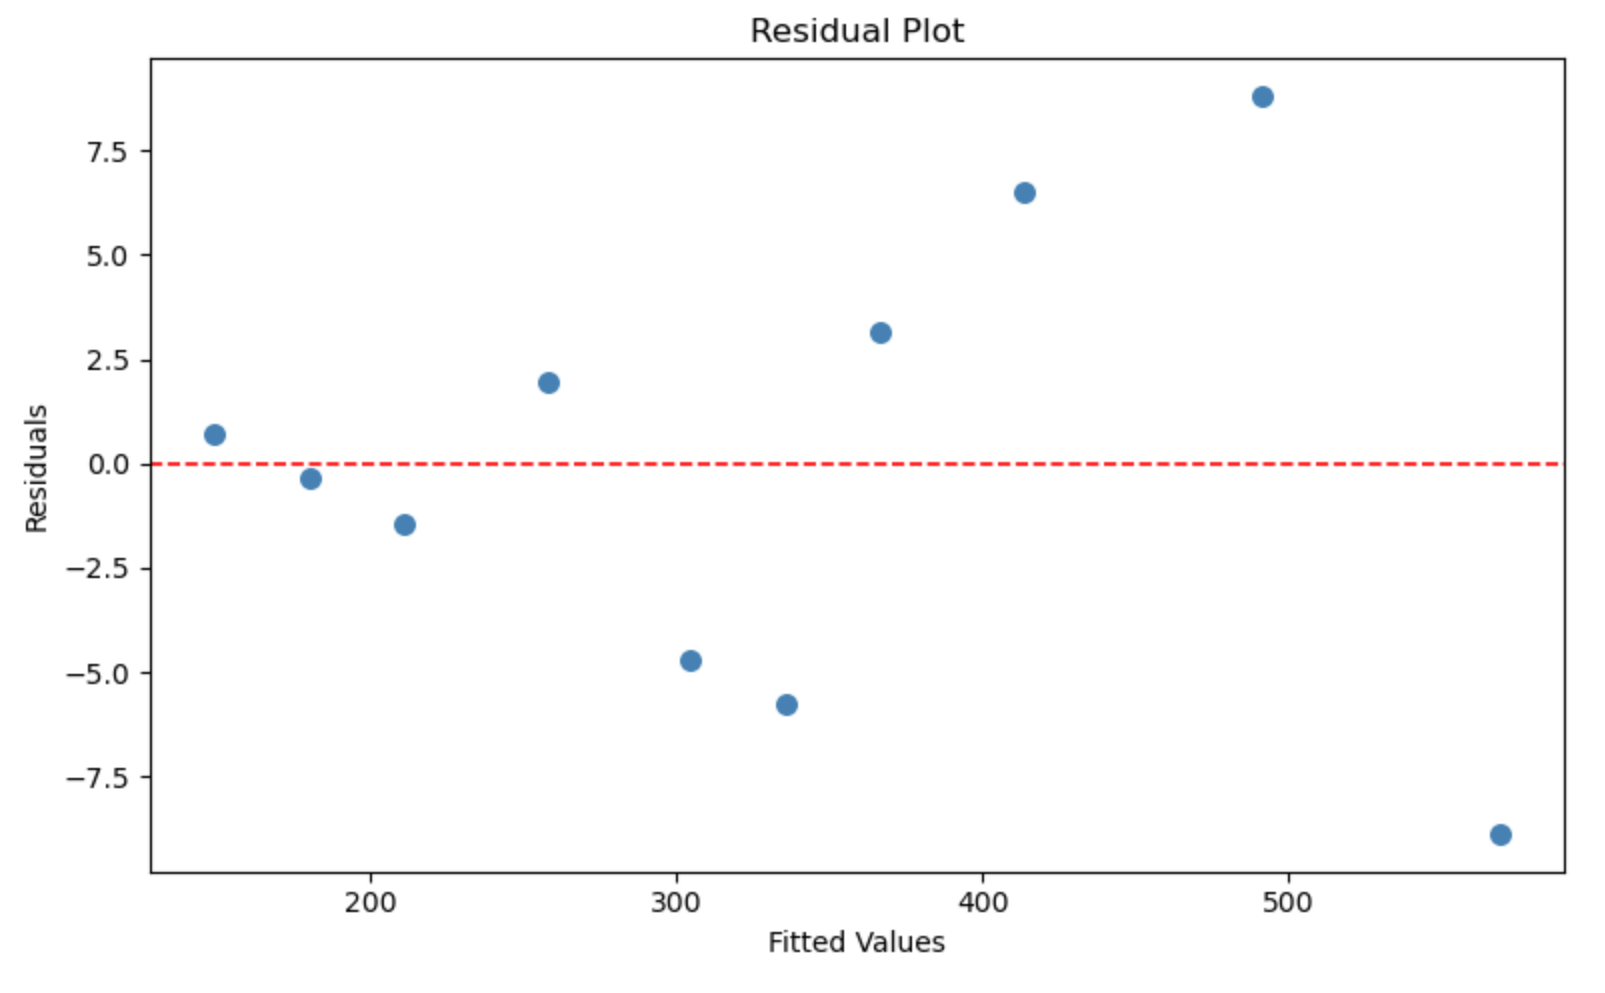
The key line is residuals = price - predicted. The axhline() call adds the zero reference line; without it, the plot is much harder to read. If this output looks roughly patternless, you're in reasonable shape. Notice the residuals grow larger at higher fitted values. With only 10 points it's hard to be sure, but this hints at the kind of fan shape we discussed earlier.
For a deeper look at regression in Python, our Introduction to Regression with statsmodels in Python course walks through model fitting, assumption checking, and interpretation in detail.
How to Create a Residual Plot in R
R makes this slightly easier out of the box. Once you've fit a model with lm(), the built-in plot() function produces a full diagnostic panel, including a residuals-vs-fitted plot, automatically.
sqft <- c(800, 1000, 1200, 1500, 1800, 2000, 2200, 2500, 3000, 3500)
price <- c(150, 180, 210, 260, 300, 330, 370, 420, 500, 560)
housing_model <- lm(price ~ sqft)
plot(housing_model, which = 1)
The which = 1 argument pulls just the residuals-vs-fitted plot. Leave it out, and you get all four standard diagnostic plots: residuals vs. fitted, Q-Q, scale-location, and residuals vs. leverage. Useful when you want a complete picture quickly. R also annotates the three most extreme points by index, which saves you from hunting for outliers manually.
For a full walkthrough of regression in R, our Introduction to Regression in R course covers model building and diagnostics from the ground up.
Residual Plots vs. Other Regression Diagnostic Plots
The residuals-vs-fitted plot is the starting point, not the complete picture. A few related plots answer different questions.
Residual plot vs. Q-Q plot
The residuals-vs-fitted plot checks linearity and constant variance. The Q-Q plot checks normality, whether the residuals follow a normal distribution. These are separate questions. A residual plot that looks clean doesn't guarantee normality, and a Q-Q plot won't tell you anything about variance. You generally want both.
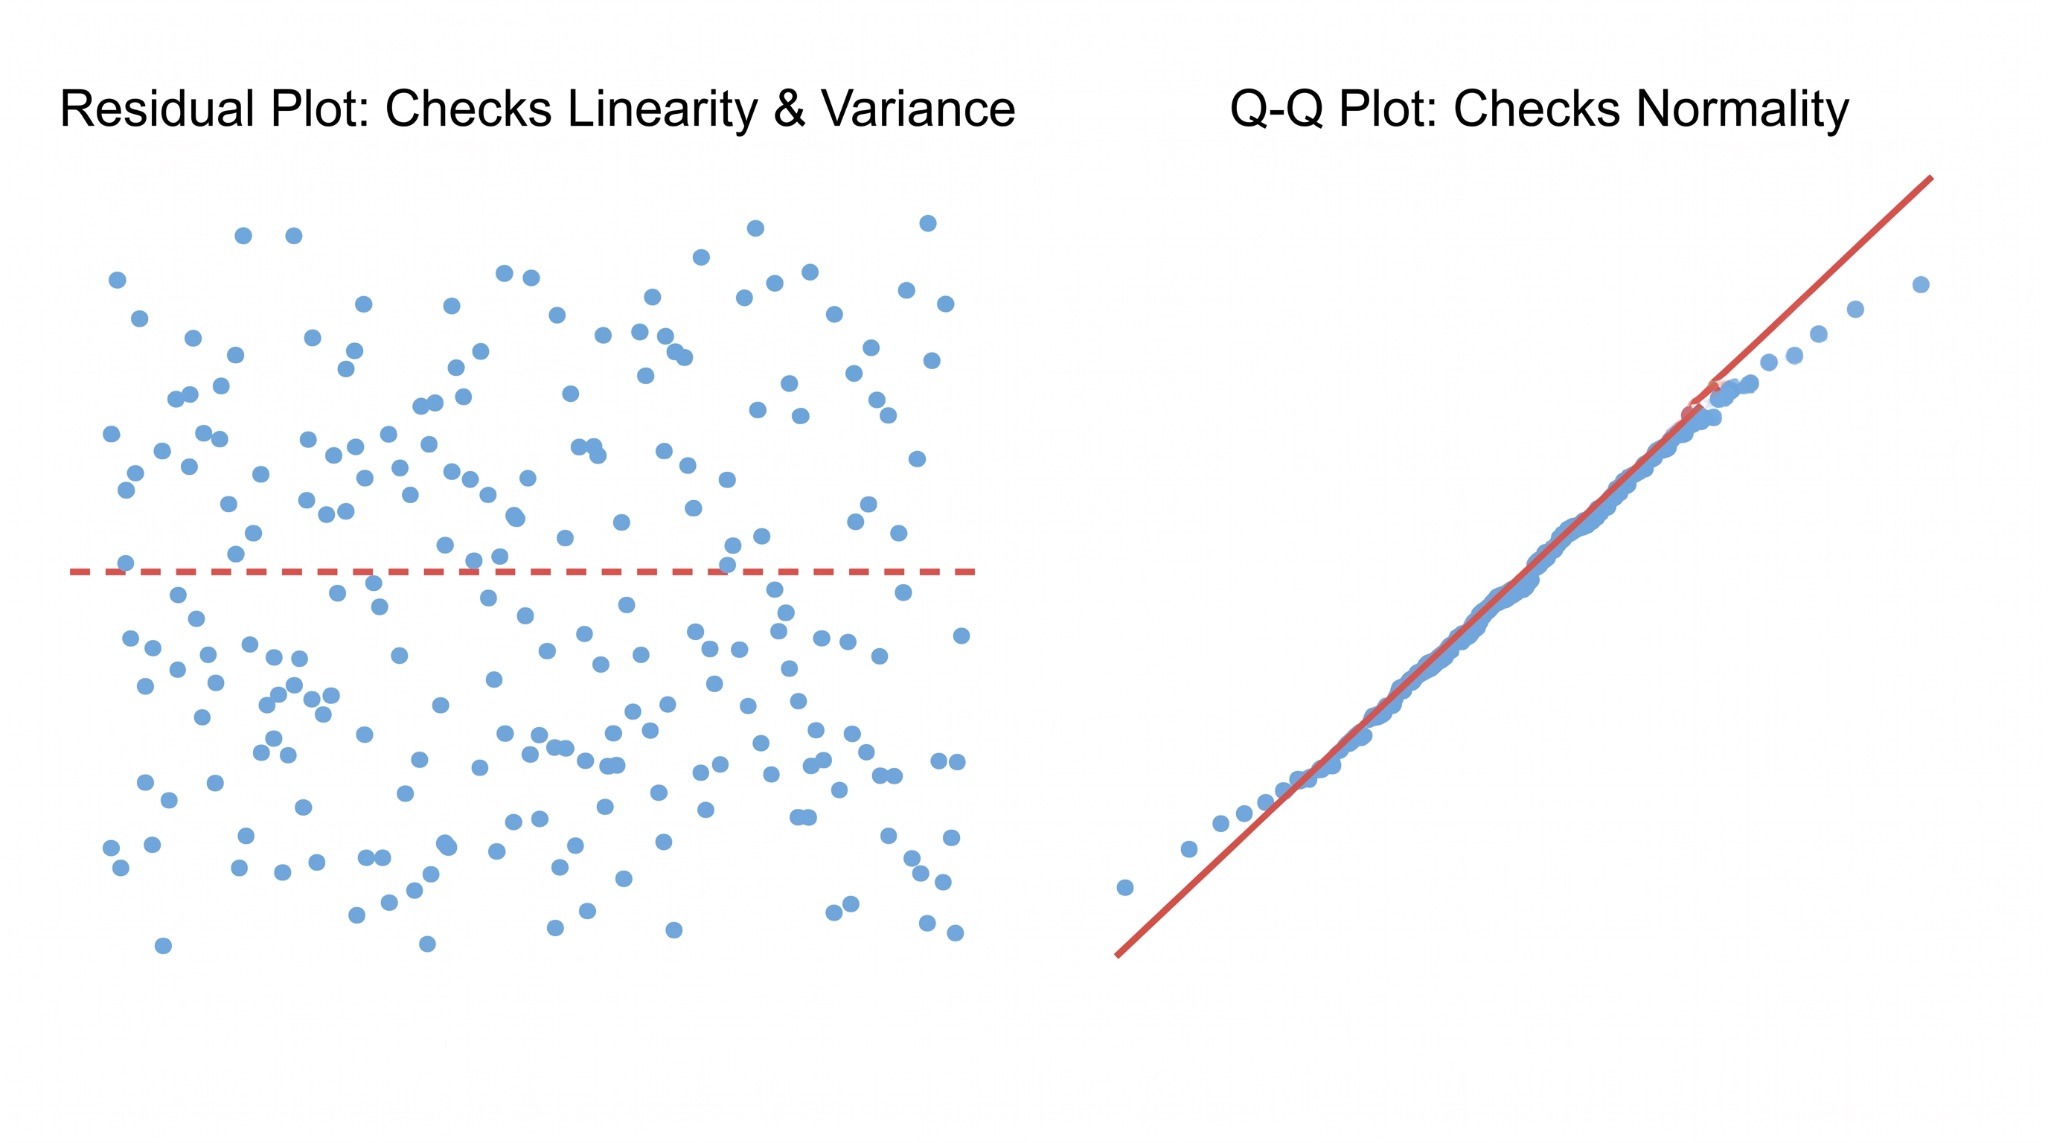
Two different plots, two different questions about your model. Image by Author.
Residual plot vs. scale-location plot
The scale-location plot (also called spread-location) plots the square root of the absolute standardized residuals against fitted values. It's designed to detect heteroscedasticity and often makes the funnel pattern easier to spot than the raw residual plot, because it removes the sign of the residuals and focuses entirely on spread.
Residual plot vs. residuals vs. leverage plot
Leverage measures how unusual an observation's predictor values are, not how badly the model predicts it. High leverage combined with a large residual is a potentially influential observation. The residuals-vs-leverage plot identifies these combinations and usually highlights the most problematic points by name. If you're worried about influential observations distorting your model, check this one.
What to Do When a Residual Plot Shows a Problem
A residual plot is a diagnostic, not a verdict. Seeing a pattern doesn't mean the model is useless. Here's how the common patterns map to next steps:
- Curved pattern: Consider adding a polynomial term or transforming a predictor. A log transformation of x or an x² term often straightens things out.
- Funnel shape: Try a log or square root transformation of the response variable. If that doesn't work, weighted least squares assigns less influence to noisier observations.
- Large isolated residuals: Investigate the observation. Check for data entry errors first. If the point is legitimate, consider whether your model needs to account for whatever makes it unusual.
- Clusters or groups: Look for a categorical variable you haven't included. Separate subgroup models are sometimes the right answer.
The residual plot shows symptoms. It doesn't tell you the exact cause, and a single pattern can sometimes have multiple explanations. Use it as a prompt to ask better questions.
Common Mistakes When Reading Residual Plots
- Expecting a perfectly random plot: Real data is messy. A few nonconforming points, minor asymmetry, some clustering at the extremes: this is normal. The question isn't whether the plot is perfectly random; it's whether there's a systematic pattern that a better model would eliminate.
- Treating every outlier as bad data: A large residual means the model predicted that observation poorly. It doesn't mean the observation is wrong. Sometimes the outlier is the most interesting data point in the dataset. Delete it only after you understand what it is.
- Assuming a residual plot proves normality: It doesn't. A clean residuals-vs-fitted plot tells you about linearity and constant variance. Normality requires a Q-Q plot. These two diagnostics are complementary, not interchangeable.
- Looking at the plot without considering context: A residual plot from a time series model needs to be read differently than one from a cross-sectional dataset. What counts as a concerning pattern depends on data structure, sample size, and what the model is being used for. A pattern worth fixing in a forecasting model might be ignorable in an exploratory analysis.
Conclusion
Fit a model, check the summary, feel good about the R²: this is where most people stop. The residual plot is what you look at after that, and it frequently tells a different story. Random scatter around zero is what you want. Curves, funnels, clusters, and extreme, isolated points each suggest something the model hasn't accounted for.
No single plot gives you the full picture. Pair the residuals-vs-fitted plot with a Q-Q plot for normality, a scale-location plot for variance, and a leverage plot if influential observations are a concern. Each one answers a different question.
If you want to go further, our Intermediate Regression with statsmodels in Python course covers assumption checking in depth, including how to respond when diagnostics flag a problem.


You've fit a regression model, the R² looks decent, and the coefficients make intuitive sense. But a good-looking summary table can hide a badly misspecified model. One scatter plot often catches what the numbers miss: the residual plot.
This article covers what residual plots are, how to read them, the patterns worth knowing, and how to create one in both Python and R. Most beginners skip the diagnostic step entirely. By the end, you won't.
What Is a Residual Plot?
A residual is the gap between what your model predicted and what actually happened: residual = observed − predicted. A residual plot puts those gaps on display. The x-axis shows either the predicted (fitted) values or an explanatory variable; the y-axis shows the residuals. A horizontal reference line sits at zero, representing perfect prediction.
Random scatter plot around zero: a healthy residual plot. Image by Author.
The central idea: if your model has captured the relationship well, the residuals should look like noise. Scattered randomly around zero, no obvious pattern. The moment a shape appears, your model is telling you something it couldn't say through coefficients alone.
How to Interpret a Residual Plot
Look for patterns. Ideally, there shouldn't be an obvious one. That's the whole rule. What the location, spread, and shape of the residuals reveal is where things get interesting.
Location: Is the scatter centered on zero?
Residuals that sit above zero in some regions of fitted values and below in others mean the model is biased. It's consistently over- or under-predicting in certain regions. This often points to a missing variable or a nonlinear relationship that a straight-line model can't capture.
Spread: Does the variance stay roughly constant?
Scan left to right. If the spread of residuals is roughly the same across all fitted values, that's a good sign. If the points fan outward as fitted values increase, the variance is changing. This is called heteroscedasticity. It doesn't break the coefficient estimates, but it makes standard errors unreliable, which matters if you're doing any hypothesis testing.
Shape: Is there a curve or trend?
Flat and patternless is what you want. A U-shape or arch says the model is missing a nonlinear term. Clusters or bands suggest subgroups the model is treating as one. A single point sitting far from everything else is worth investigating.
Common Residual Plot Patterns and What They Mean
Four residual plot patterns that signal model problems. Image by Author.
Random scatter around zero
The good outcome. Points distributed roughly evenly above and below the zero line, no discernible trend, generally indicates the model is capturing the relationship reasonably well. Some randomness is expected.
Curved pattern
A curved or arch-shaped pattern usually means an unmodeled nonlinear relationship. The model is fitting a straight line through data that bends. The fix is typically adding a polynomial term (like x²) or applying a transformation to the predictor. This is one of the more common patterns in practice, especially when modeling things like housing prices or biological growth.
Funnel or fan shape
Residuals spreading wider as fitted values increase: that's heteroscedasticity, the variance isn't constant. Common in financial data, where prediction errors naturally scale with the magnitude of the outcome. A log transformation of the response variable is often a reasonable first step; weighted least squares is another option.
Clusters or groups
Distinct groups in the residual plot usually mean the data contains subpopulations the model isn't accounting for. There's probably a categorical variable (region, treatment group, product type) that belongs in the model. If you see two or three tight bands of points, start there.
Large isolated residuals
A single point sitting far from the rest deserves a look. It might be a genuine outlier, a data entry error, or an observation with unusual characteristics. Don't delete it automatically. Understand it first. Whether to keep or remove it depends on context, not convenience.
For each of these patterns, the residual plot identifies a symptom, not a diagnosis. It tells you something is off; you still need to figure out why.
What Regression Assumptions Can Residual Plots Check?
With the patterns in mind, it's worth being clear about which regression assumptions a residual plot can and cannot assess.
One thing residual plots cannot reliably assess is normality. A flat residuals-vs-fitted plot doesn't confirm that errors are normally distributed. For that, you need a Q-Q plot. This is a common source of confusion and worth keeping straight.
How to Create a Residual Plot in Python
The standard workflow uses scikit-learn to fit the model and calculate residuals, then matplotlib to visualize them. Here's a complete example using simple linear regression on housing data:
The key line is
residuals = price - predicted. Theaxhline()call adds the zero reference line; without it, the plot is much harder to read. If this output looks roughly patternless, you're in reasonable shape. Notice the residuals grow larger at higher fitted values. With only 10 points it's hard to be sure, but this hints at the kind of fan shape we discussed earlier.For a deeper look at regression in Python, our Introduction to Regression with statsmodels in Python course walks through model fitting, assumption checking, and interpretation in detail.
How to Create a Residual Plot in R
R makes this slightly easier out of the box. Once you've fit a model with
lm(), the built-inplot()function produces a full diagnostic panel, including a residuals-vs-fitted plot, automatically.The
which = 1argument pulls just the residuals-vs-fitted plot. Leave it out, and you get all four standard diagnostic plots: residuals vs. fitted, Q-Q, scale-location, and residuals vs. leverage. Useful when you want a complete picture quickly. R also annotates the three most extreme points by index, which saves you from hunting for outliers manually.For a full walkthrough of regression in R, our Introduction to Regression in R course covers model building and diagnostics from the ground up.
Residual Plots vs. Other Regression Diagnostic Plots
The residuals-vs-fitted plot is the starting point, not the complete picture. A few related plots answer different questions.
Residual plot vs. Q-Q plot
The residuals-vs-fitted plot checks linearity and constant variance. The Q-Q plot checks normality, whether the residuals follow a normal distribution. These are separate questions. A residual plot that looks clean doesn't guarantee normality, and a Q-Q plot won't tell you anything about variance. You generally want both.
Two different plots, two different questions about your model. Image by Author.
Residual plot vs. scale-location plot
The scale-location plot (also called spread-location) plots the square root of the absolute standardized residuals against fitted values. It's designed to detect heteroscedasticity and often makes the funnel pattern easier to spot than the raw residual plot, because it removes the sign of the residuals and focuses entirely on spread.
Residual plot vs. residuals vs. leverage plot
Leverage measures how unusual an observation's predictor values are, not how badly the model predicts it. High leverage combined with a large residual is a potentially influential observation. The residuals-vs-leverage plot identifies these combinations and usually highlights the most problematic points by name. If you're worried about influential observations distorting your model, check this one.
What to Do When a Residual Plot Shows a Problem
A residual plot is a diagnostic, not a verdict. Seeing a pattern doesn't mean the model is useless. Here's how the common patterns map to next steps:
The residual plot shows symptoms. It doesn't tell you the exact cause, and a single pattern can sometimes have multiple explanations. Use it as a prompt to ask better questions.
Common Mistakes When Reading Residual Plots
Conclusion
Fit a model, check the summary, feel good about the R²: this is where most people stop. The residual plot is what you look at after that, and it frequently tells a different story. Random scatter around zero is what you want. Curves, funnels, clusters, and extreme, isolated points each suggest something the model hasn't accounted for.
No single plot gives you the full picture. Pair the residuals-vs-fitted plot with a Q-Q plot for normality, a scale-location plot for variance, and a leverage plot if influential observations are a concern. Each one answers a different question.
If you want to go further, our Intermediate Regression with statsmodels in Python course covers assumption checking in depth, including how to respond when diagnostics flag a problem.