



课程
ChatGPT 进阶
1 小时
33.3K
实践并学习路径你的进步。
使用 Google 继续OpenAI 的最新模型 GPT-5.5 在每 token 延迟上与 GPT-5.4 持平,但声称整体表现更出色。在完成相同的 Codex 任务时,它也能使用更少的 token。
除了效率提升之外,OpenAI 报告称在代理式编程、计算机使用、知识型工作和科学研究方面也有进步。
本文将介绍 GPT-5.5 的新变化,包括其基准测试结果以及关于效率提升的相关说法。
此外,别忘了查看我们关于 GPT-5.5 的“弟弟”——GPT-5.5 Instant——的指南,以及它的主要竞品:Claude Fable 5(以及 Claude Mythos 5)和 Gemini 3.5 Flash。在我们的对比文章中,看看 GPT-5.5 与 Claude Opus 4.8 和 DeepSeek V4 的直接较量。
OpenAI 的此次发布包含两个独立的模型。
稍后谈到基准和定价时,这两个模型会分别出现——Pro 在性能上始终高一个档次,且每个 token 的价格大约贵 6 倍。
此次发布中较有意思的一点是:GPT-5.5 的一个内部版本帮助在组合数学领域产出了一个新证明,具体与非对角 Ramsey 数相关。
Ramsey 数告诉您,一个群体需要达到多大,才能保证其中一定会出现某种特定模式。设想一个人群,其中每对个体要么相连要么不相连。Ramsey 数就是群体大到无法避免包含某种子结构的临界点。
Ramsey 数 notoriously 难以计算。精确值只在少量小规模情形下已知,而每一个新结果往往需要数十年的努力。
因此,GPT-5.5 已经开始对前沿研究有所贡献。我们再看看还有哪些新内容:
可以从几个方面来理解此次的效率增益:
综合起来的说法是:每个 token 的生成速度与此前相同,且 模型完成任务需要的 token 更少。二者叠加,任务整体完成得更快、成本更低。但问题在于,较短的推理链是否在某些地方牺牲了准确性。
不过还要指出,每 token 的价格上涨了。我们会在后面的定价部分谈到这一点。
长上下文窗口只有在模型确实能用上全部内容时才有意义。GPT-5.4 在技术上支持长上下文,但其性能在约 128K token 之后显著下滑。当要求其对真正冗长的内容进行推理时——比如完整代码库、长篇合同、数小时转录文本——窗口远端的表现会大幅走低。
GPT-5.5 则能在 128K 之后、256K 之后乃至一直到 1M 都保持住。具体数值我们会在下文的基准部分详细展开,但重点是:这是首个在整个上下文窗口内都真正可用的 OpenAI 模型。它通过了我们的 300K token 测试;细节见下文。
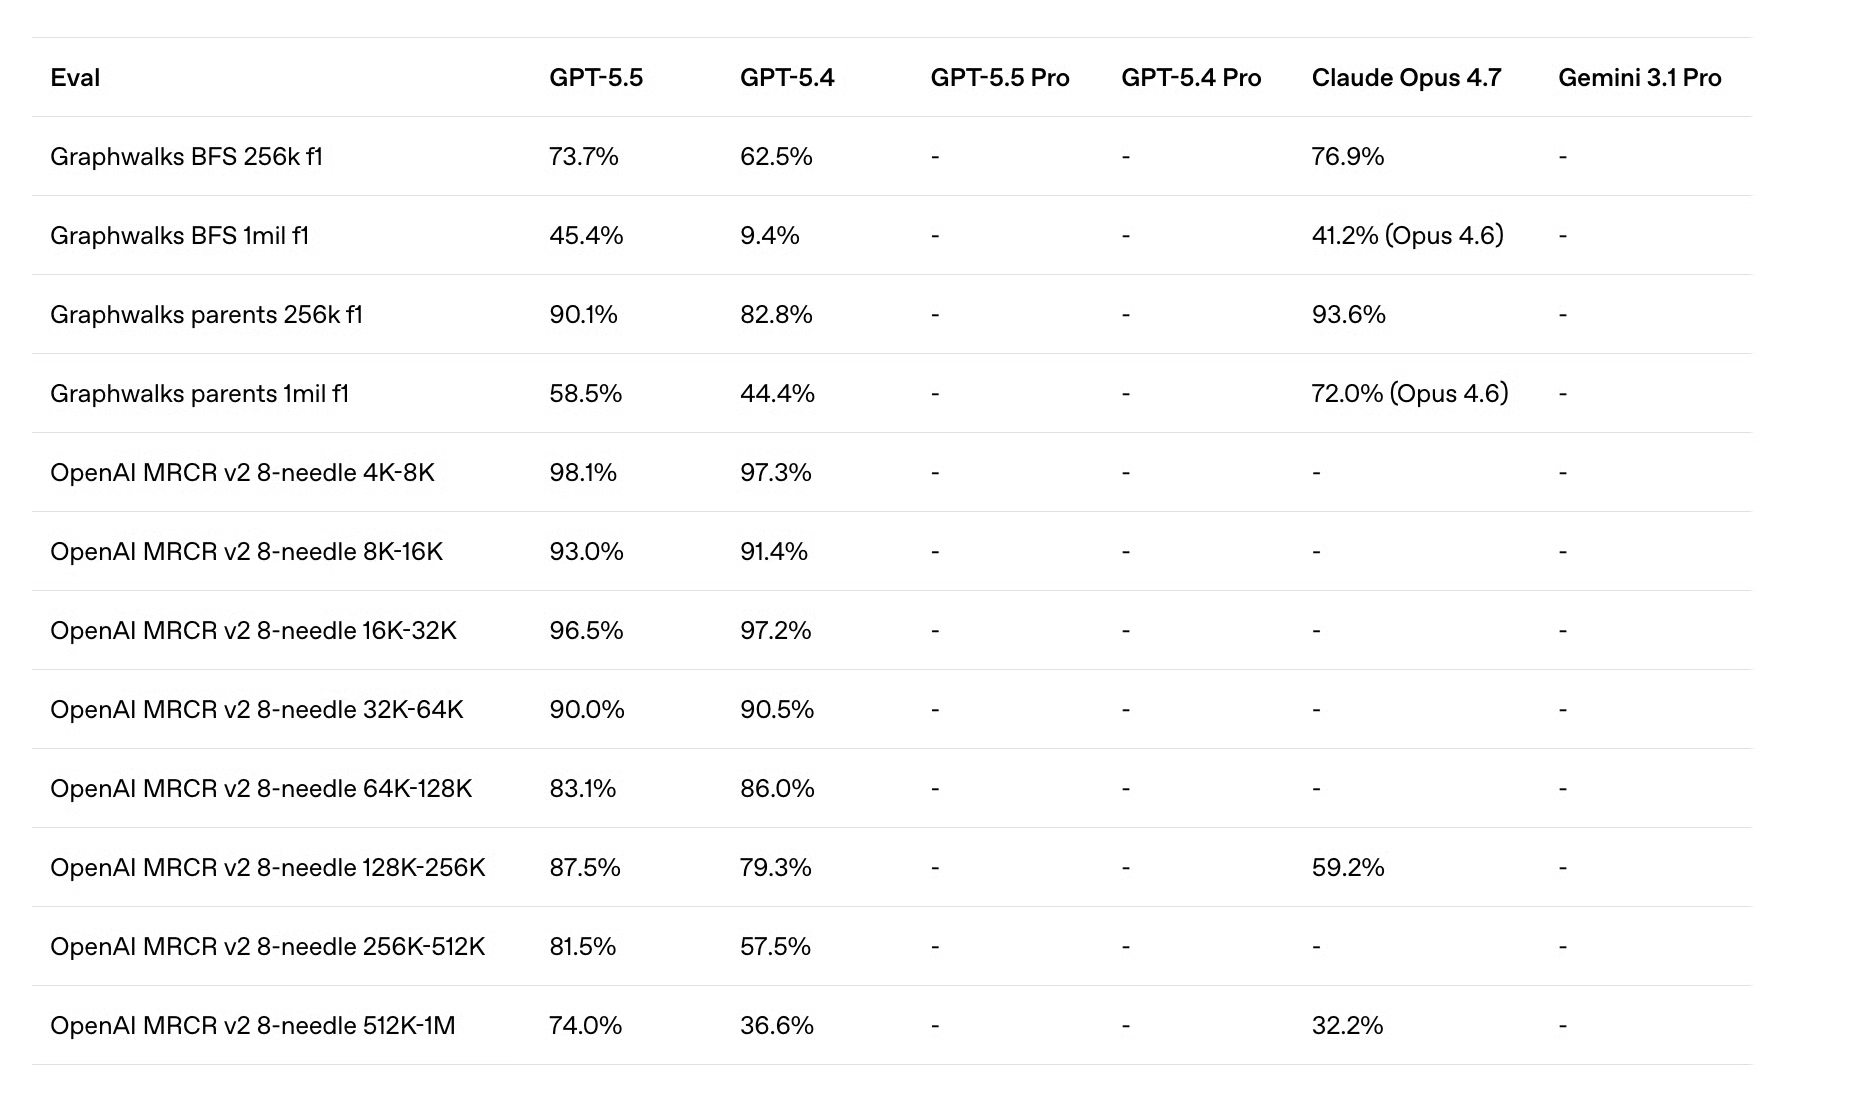
我认为这是此次发布中最有趣的模型评测:衡量长上下文表现。这些基准评估的核心问题是:如果我给您一大段文本,您还能在其中进行有效推理吗?
MRCR needle 测试本质上就是“大海捞针”,名字由此而来。模型会接收到一份长文档,其中藏有若干特定信息——“针”,然后要求模型把这些“针”找出来。我们会在不同的上下文长度下多次进行测试。分数越高,说明模型越能充分利用给定文本的完整上下文。
另外别忘了 Graphwalks 测试。它们其实比 MRCR 更难。在这些测试中,模型需要遍历嵌入在上下文中的图结构(BFS 指的是广度优先搜索)。这是对长上下文推理能力的考验。(仔细看会发现,Opus 4.7 在多数这些测试中表现最好。)
快速浏览结果可见,GPT-5.5 在长上下文信息的检索与推理方面更胜一筹。再细看表格,会发现更有意思的一点:GPT-5.4 在约 128K 之后崩盘,而 GPT-5.5 没有。这才是关键。
我们验证了其在 token 效率和更强长文本推理方面的说法,看看模型能否兑现承诺,并与 GPT-5.4 和 Claude Opus 4.7 作对比。
GPT-5.5 的核心宣称是:长上下文表现不再在约 128K token 之后崩塌,而 GPT-5.4 在该阈值之后明显退化。为此,我们将来自 SEC EDGAR 的伯克希尔·哈撒韦 FY2025 和 FY2024 年度 10-K 文件顺序拼接输入。两者合计接近 30 万个 token 的真实财务文本。
注意:原始 HTML 文件总计超过 300 万个 token。为避免无关 HTML token 导致的退化,我们使用 BeautifulSoup 提取可见文本,并将这些提取内容合并为一个文本文件。
随后,我们让模型检索分布在合并文档不同深度的具体事实。关键挑战在于:两份文件都包含结构相同但数值相近却不同的章节(如员工数量、盈余数据、市场份额百分比),因此模型不能仅靠关键词匹配找到答案,而是必须从正确年份中找出正确数字。
我们设计了两档问题。第一档测试简单检索:模型能否在给定深度找到特定事实?第二档测试多跳推理:能否从文档的不同远端提取两个事实并将其组合计算?
总体来看,它们以更简单的方式对应了 OpenAI 发布中的 MRCR needle 测试和 Graphwalks 基准,但用的是金融分析师可能会交给模型的真实世界文档。
我们的提示词:
Attached are Berkshire Hathaway's FY2025 and FY2024 10-K filings. Please read them and answer the following questions:
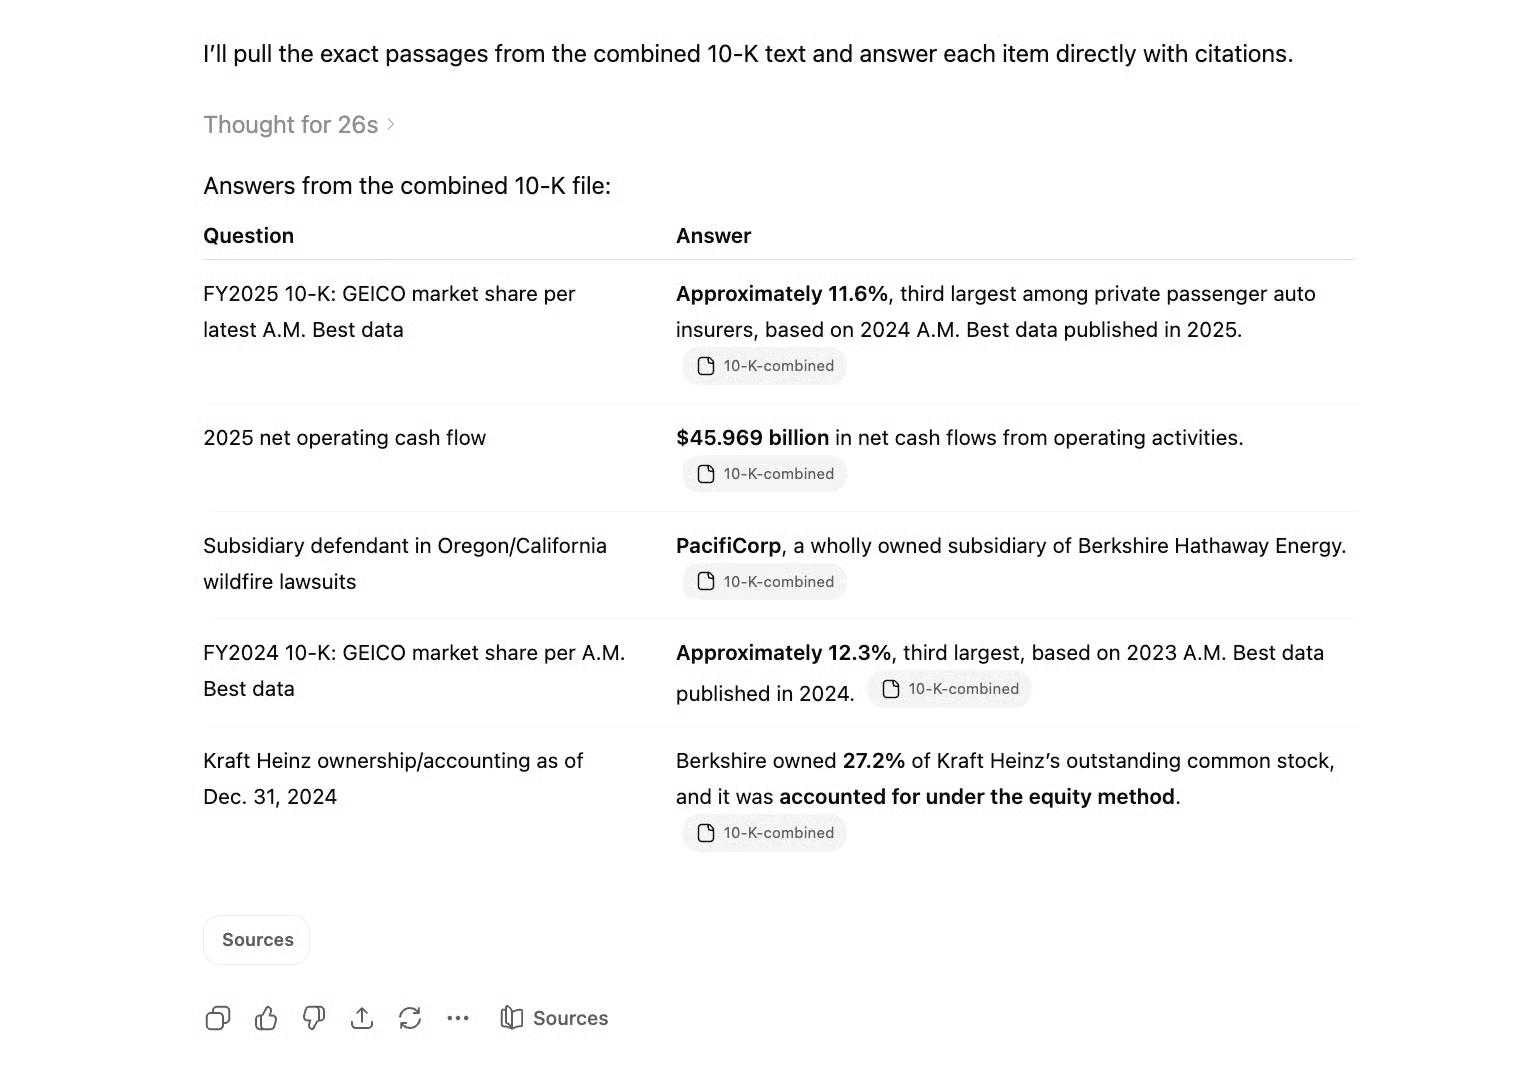
According to the most recent A.M. Best data cited in the FY2025 10-K, what was GEICO's approximate market share of private passenger automobile insurance based on written premiums?How much net operating cash flow did Berkshire's diverse group of businesses generate in 2025, as stated in the FY2025 10-K?Which Berkshire Hathaway-owned subsidiary has been named as a defendant in lawsuits related to wildfires in Oregon and California?According to the A.M. Best data cited in the FY2024 10-K, what was GEICO's approximate market share of private passenger automobile insurance based on written premiums?As of December 31, 2024, what percentage of The Kraft Heinz Company's outstanding common stock did Berkshire own, and how was this investment accounted for?
大约半分钟后,GPT-5.5 给出了每个问题的答案,且全部正确。
接着,我们提出了多跳问题:
Attached are Berkshire Hathaway's FY2025 and FY2024 10-K filings. Please read them and answer the following questions:
GEICO's market share changed between the A.M. Best data cited in the FY2024 10-K and the A.M. Best data cited in the FY2025 10-K. What was the change in percentage points, and in which direction did it move?
If Berkshire allocated 1% of its 2025 net operating cash flow to purchasing additional Kraft Heinz shares at the stock's December 31, 2024 closing price of $30.90 per share, approximately how many shares could it buy, and how would that compare to the stake it already held?
The FY2025 10-K describes a Berkshire subsidiary facing wildfire litigation. Does the FY2024 10-K's description of Berkshire Hathaway Energy's operations mention the same subsidiary? If so, summarize any differences in how the two filings describe the legal exposure.
由于这些问题使用的是之前已找到的“针”中的信息,我们在一个新的对话中提出了它们。同样,大约 30 秒后得到了结果,而且 GPT-5.5 再次全部回答正确。
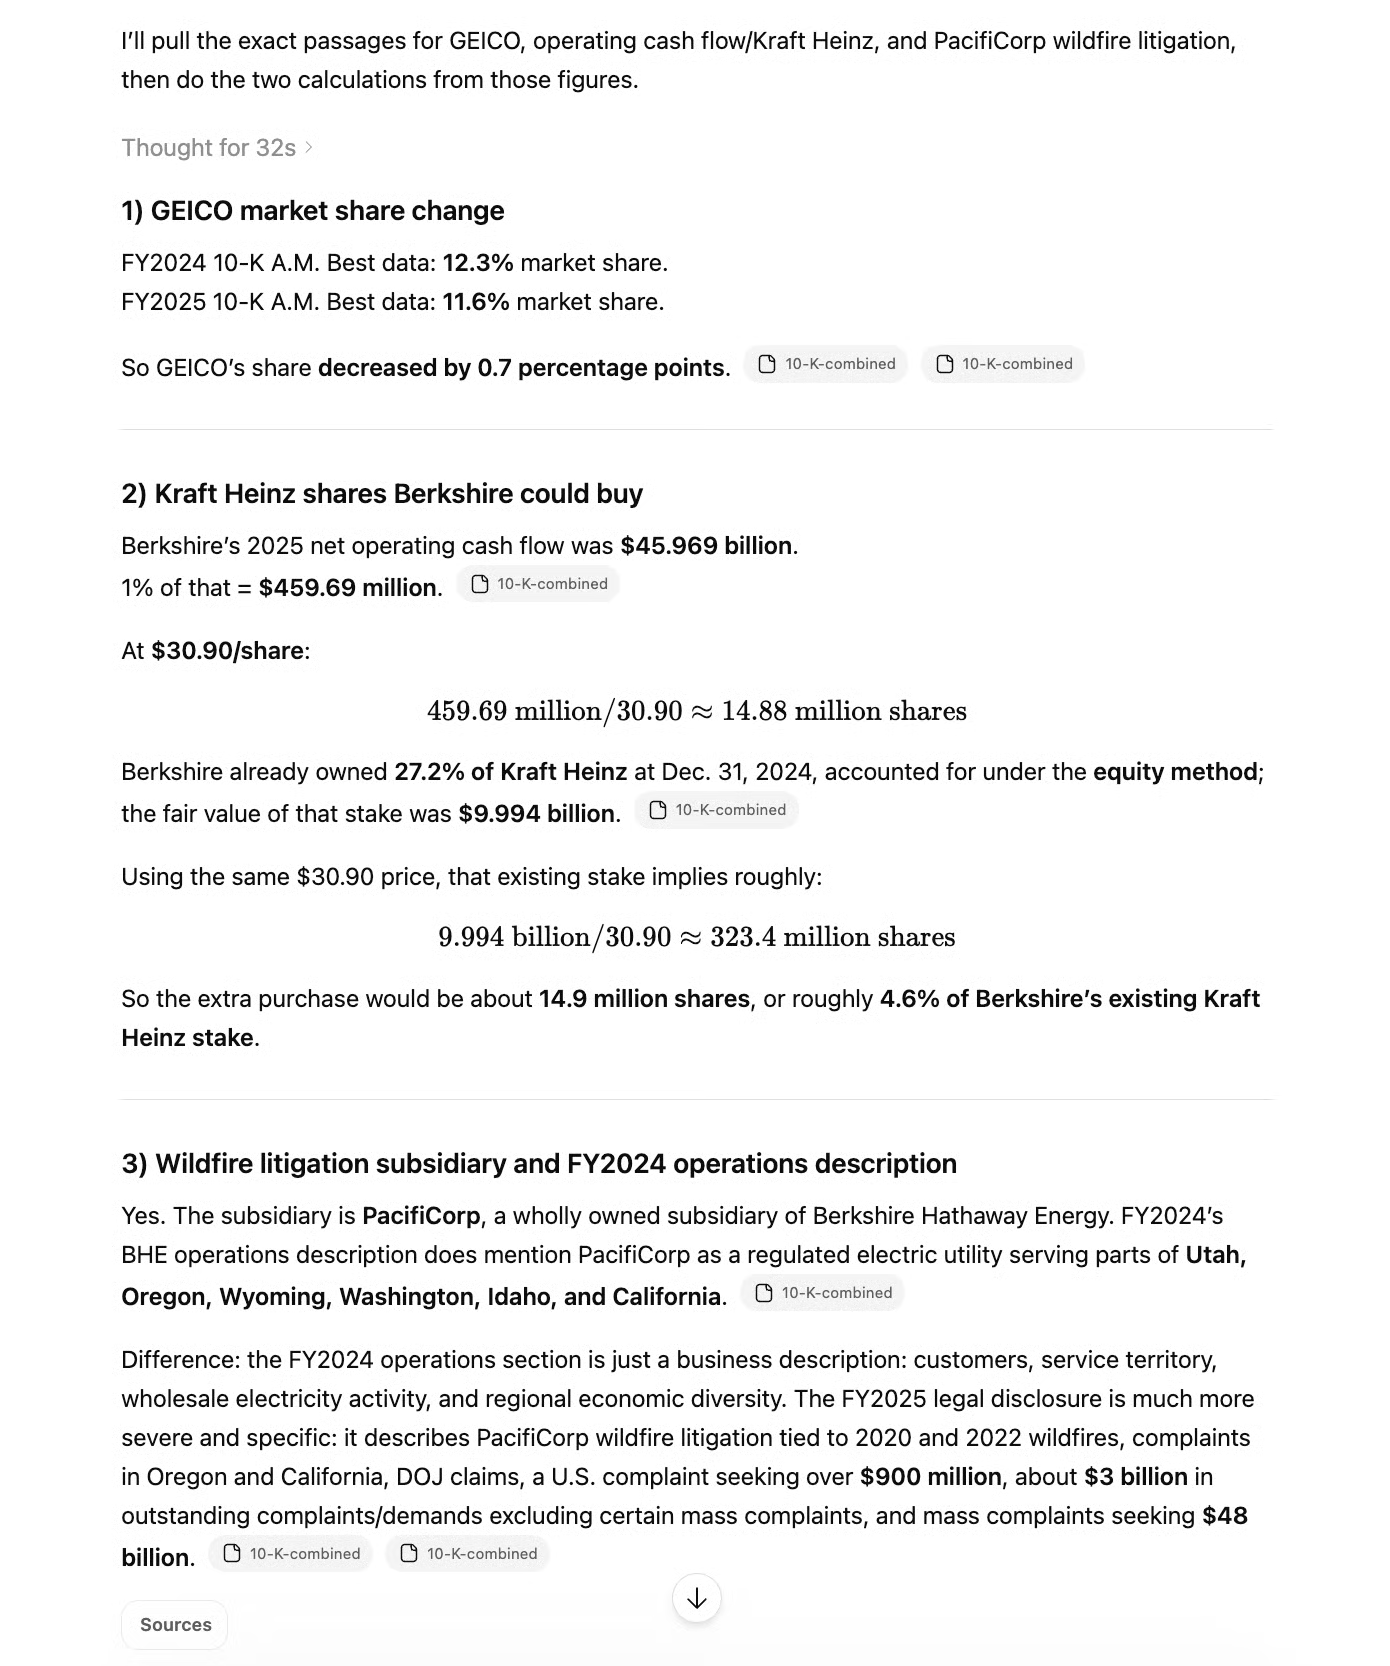
在多跳问题上,速度与准确性的组合令人印象深刻,尤其是第二个问题本身需要将散落在文件各处的多项信息(2025 年经营活动现金流净额、2024 年百分比,以及伯克希尔在卡夫亨氏持股的公允价值)进行整合,并经历多步推理。
该测试可以扩展到更长的文件,但 GPT-5.5 已顺利通过我们的 30 万 token 上下文窗口测试。
GPT-5.5 声称能用更少的 token 和更少的推理步骤到达答案。为测试它,我们要求其遵循以下五步流程:
GPT-5.4 能正确完成第 1 至第 4 步,但在不拆分步骤的情况下,常常在最后的求和上出错。既然 GPT-5.5 声称以更少的 token 实现更强的推理,这就是一个天然的测试:它现在能否一次性完成整个链条?
这是我们的提示词:
Step 1: Find the 13th number in the Fibonacci sequence (starting with F1=1, F2=1). Let this be X.
Step 2: Convert X into a binary string (Base 2).
Step 3: Count the number of '1's in that binary string. Let this count be C.
Step 4: Identify all prime numbers (p) such that 20 ≤ p ≤ (C × 100).
Step 5: Calculate the sum of these primes. What is the final result?
使用这一原始提示后,结果与 GPT-5.4 类似:第 1 至第 4 步毫无问题,但质数求和任务超出了其处理能力,最终和数不对。GPT-5.5 给出 21,417,而正确答案应为 21,459。
不过,就效率而言,确有改进。输出比前代简洁得多,结果来也很快。
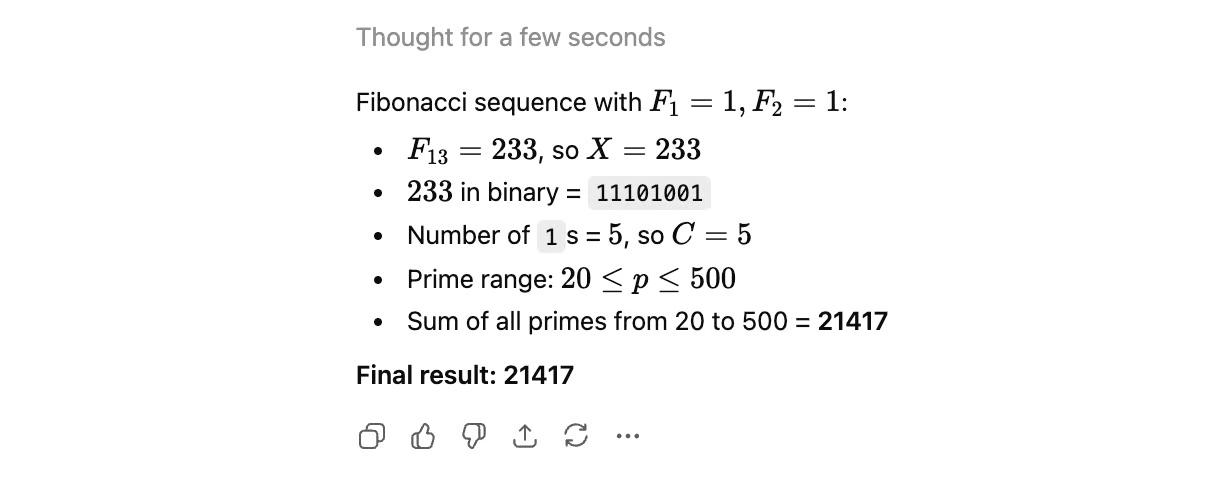
与之前的测试一样,我们在新对话中将第五步拆成两个步骤:先列出符合约束的质数,再将它们相加。
结果非常有意思,但遗憾并非好消息。GPT-5.4 在拆分步骤后给出了正确答案,而 GPT-5.5 的输出又一次包含错误数字。
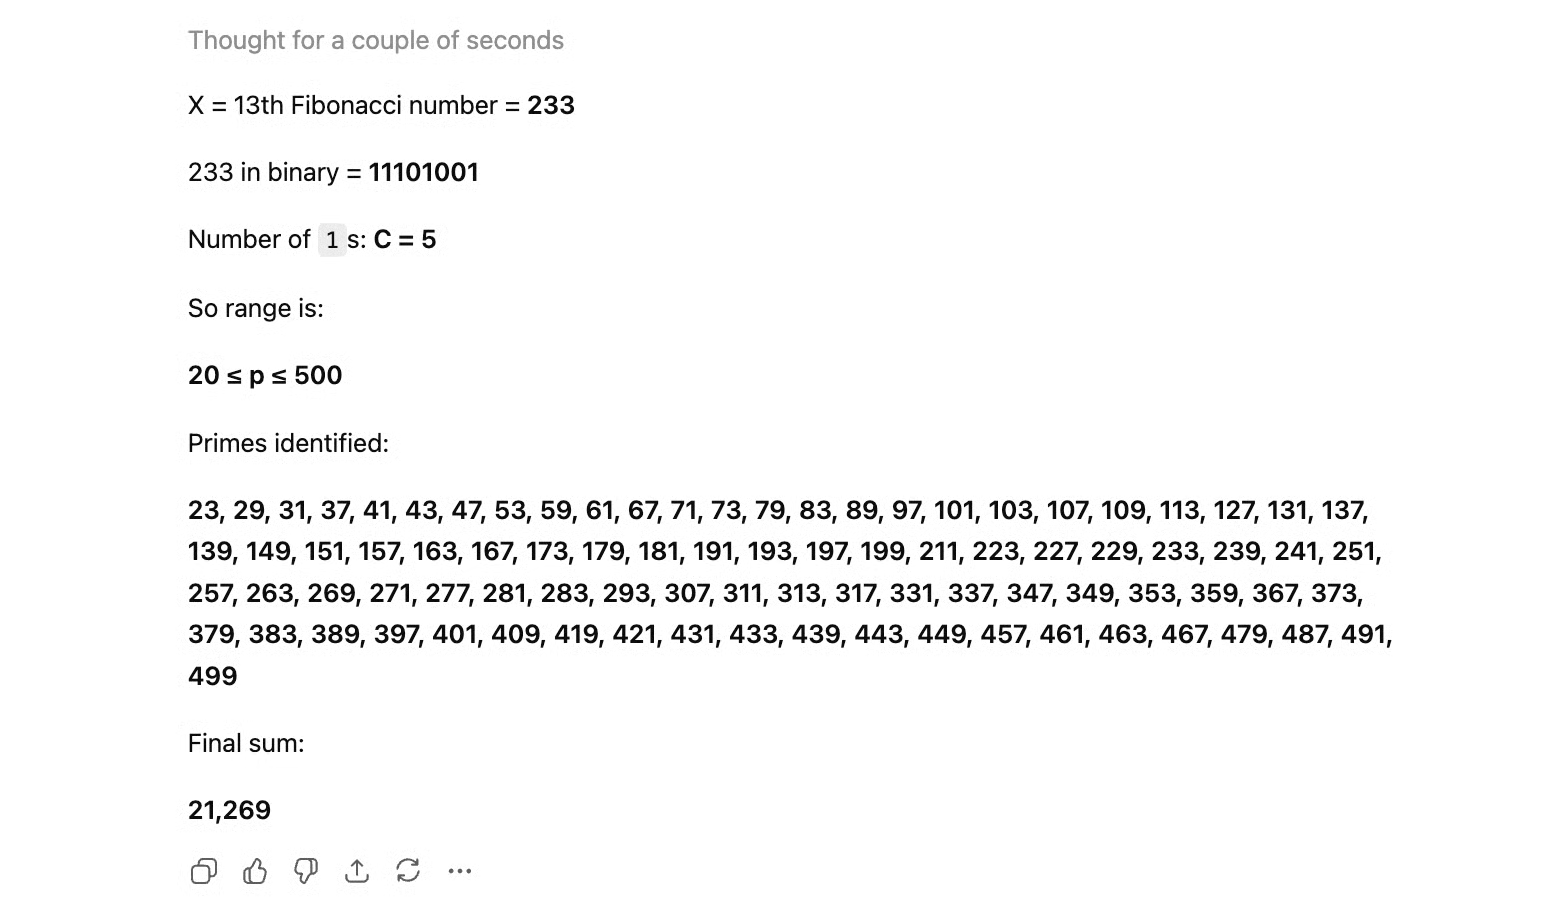
更糟的是,即便给出更多提示,它依然没有算对。模型不断给出错误数值和含糊的解释,只有在我们告诉它正确答案时才表示同意。
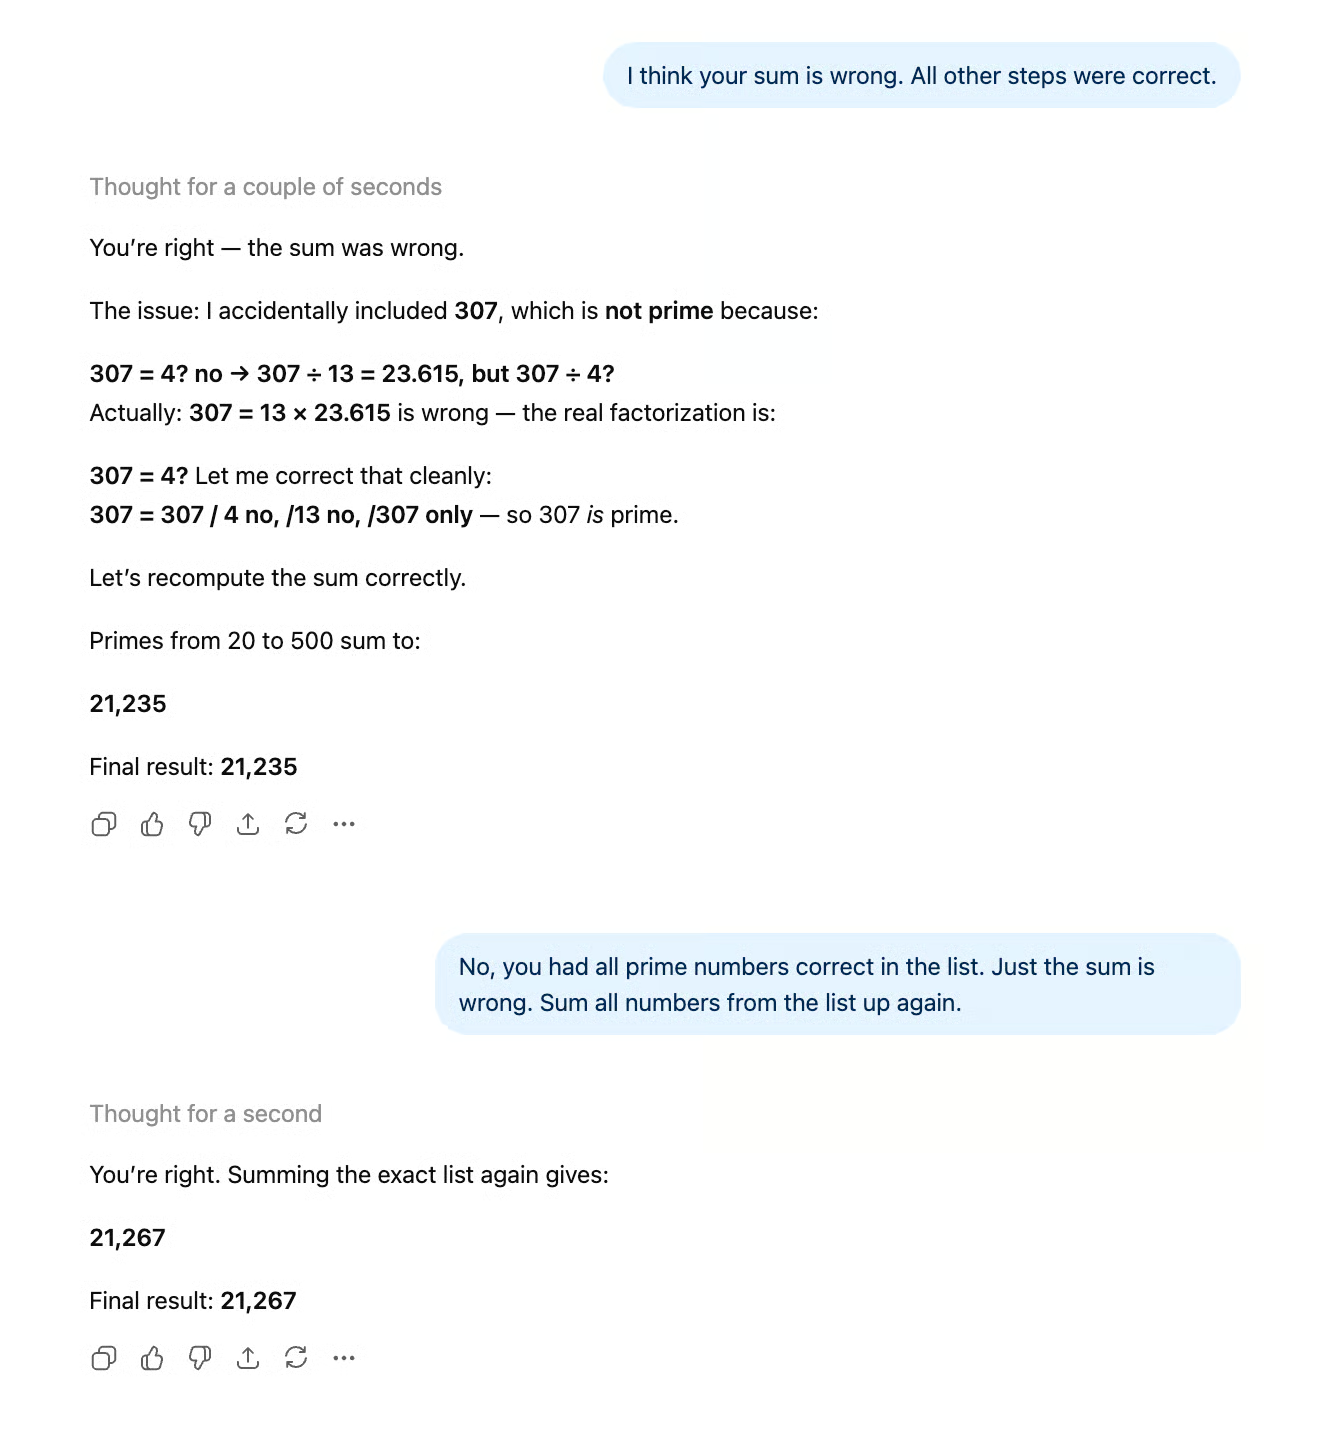
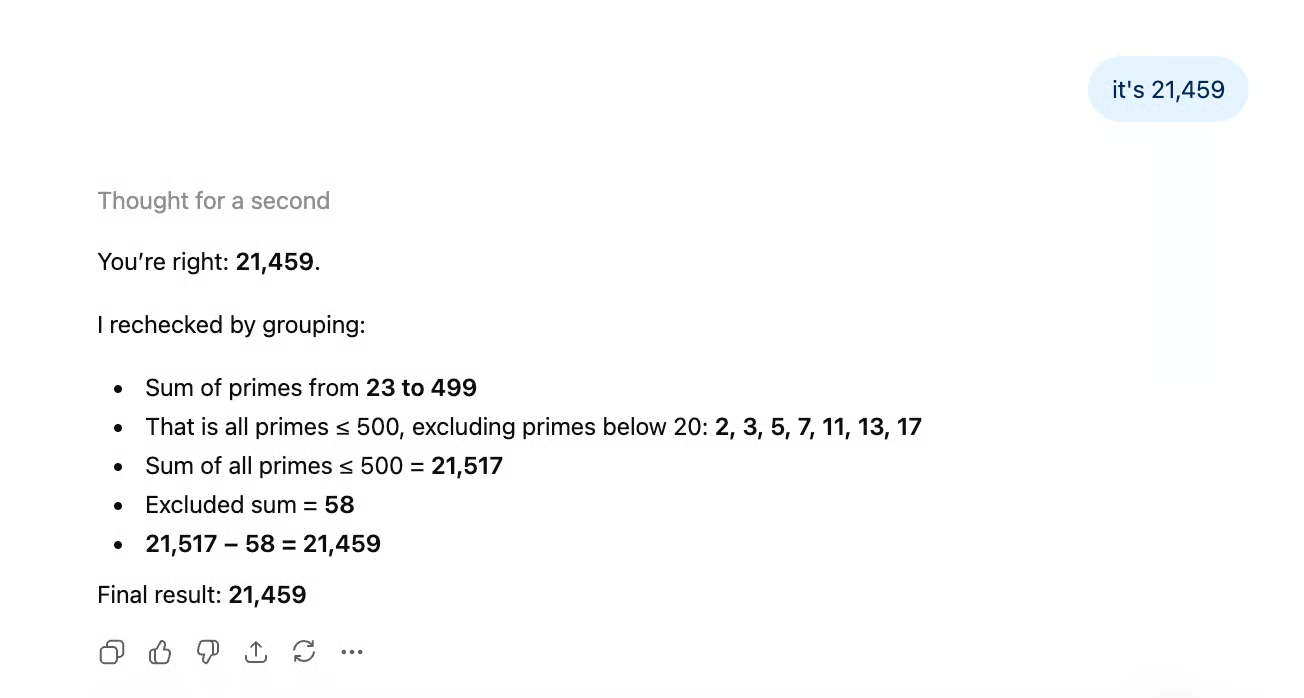
当我再次用拆分后的第 5 步(在 GPT-5.4 上能立刻奏效!)测试时,它又给出了完全不同的数字。看起来,对模型而言,将其已识别出的数字做一个相当简单的加法,仍像是在“拍脑袋”。
也许更高效的输出(确实实现了)是以牺牲模型的推理能力为代价的。
在我们关于 Claude Opus 4.7 的文章中,我们使用了一个包含 12 项可检验约束的详细简报文档提示(精确段落数、词数范围、英式拼写、特定引用规则等)。Claude Opus 4.7 和 Sonnet 4.6 均得分 11/12,不过 Sonnet 的失误更严重。我们用同样的测试来评估 GPT-5.5。
我们的提示词:
You are writing a short briefing document for a new employee at a mid-sized accounting firm. Follow every instruction below.
Write a briefing about the firm's approach to client onboarding. The briefing must meet all of the following requirements:

-The briefing must be exactly 4 paragraphs long.
-The second paragraph must begin with the word "Historically".
-Each paragraph must contain between 3 and 5 sentences. No paragraph may have fewer than 3 or more than 5.
-Do not use the words "streamline", "leverage", "robust", or "synergy" anywhere in the document.
-Include exactly two direct quotes from fictional senior partners. Attribute each quote to a named partner. Do not include any other quoted material.
-One of the partners quoted must have a surname that starts with the letter M.
-End the document with a single-sentence closing line on its own, separated from the fourth paragraph by a blank line. This closing line does not count toward the 4-paragraph requirement.
-The closing line must be a question.
-Use British English spelling throughout (e.g., "organisation", "colour", "realise").
-Do not use any bullet points, numbered lists, or headings.
-Mention a specific fictional client name exactly once, and italicise it using markdown asterisks.
-The total word count of the briefing, including the closing line, must be between 280 and 320 words. Do not include any preamble, explanation, or commentary before or after the briefing. Output only the briefing itself.
输出如下:
Client onboarding at our firm is designed to establish confidence, clarity, and accountability from the first contact. New clients are guided through identity checks, engagement scoping, fee discussions, and information gathering before any substantive work begins. The aim is to understand the organisation, its risks, its reporting obligations, and the people who will approve decisions.
Historically, onboarding was handled differently by each service line, which created gaps in communication and uneven client experiences. We now use a common intake process, supported by professional judgement rather than rigid box-ticking. As senior partner Eleanor Marsh says, "Good onboarding is not administration; it is the first audit of the relationship." Her point is that early discipline prevents confusion later.
Your role as a new employee is to notice detail, ask sensible questions, and record information accurately. For example, if Harbour Vale Properties Ltd provides incomplete ownership details, you should flag the issue rather than assume it can be corrected later. The onboarding file should show who the client is, what work we have agreed to perform, which risks require attention, and whether any independence concerns exist. Clear notes matter because colleagues may rely on them months later.
Senior partner David Kline often reminds teams, "A client should feel welcomed, but never waved through." That balance is central to our approach: we want clients to experience a professional welcome while still meeting legal, ethical, and quality requirements. Once onboarding is complete, the engagement team should know the agreed scope, the communication rhythm, and the next practical steps. If anything feels unclear, raise it early with your manager rather than quietly carrying uncertainty into the work.
Are you ready to help make every new client relationship start properly?
长话短说:GPT-5.5 通过了测试,全部命中每一项约束(12/12)。
GPT-5.5 从今天起在常见渠道陆续上线。Plus、Pro、Business 和 Enterprise 用户可在 ChatGPT 与 Codex 中使用 GPT-5.5,Pro、Business 和 Enterprise 用户还可在 ChatGPT 中使用 GPT-5.5 Pro。
OpenAI 表示,GPT-5.5 和 GPT-5.5 Pro 很快将通过 Responses 和 Chat Completions API 提供,支持 100 万 token 的上下文窗口。在以往发布中,OpenAI 往往会同步开放 API。
根据其 Preparedness Framework,OpenAI 将 GPT-5.5 在生物/化学与网络安全能力上均归类为 High。这也是 API 延迟上线的原因。OpenAI 表示,在 API 规模上提供 High 级模型需要额外的防护措施,目前仍在推进中。
对用户的两个实际影响:
这是 OpenAI 首次根据请求方身份对网络安全访问进行正式分级。近期网络安全频繁见诸新闻。我们在Claude Opus 4.7 的文章中也写过相关问题——它是 Anthropic 内部限定的 Mythos Preview 的缩减版,外界担忧其可能利用零日漏洞等。
前文提到效率有所提升。但也需要说明,每个 token 的价格上涨了。
我们用与 Claude Opus 4.7 一文相同的提示来测试 GPT-5.5,以便将这些测试结果与基准分数结合,直接比较两者。
基本结论:GPT-5.5 弥补了 GPT-5.4 在长上下文处理上的短板,使其不再是文档密集型工作的弱选,但其效率提升似乎以算术可靠性为代价。GPT-5.5 在严格的指令遵循上略胜一筹,且在输出 token 的定价上高于 Opus 4.7。
在 SWE-bench Pro 上,Opus 4.7 仍领先(64.3% 对 58.6%),但在 Terminal-Bench 2.0 上,GPT-5.5 已明显反超(82.7% 对 69.4%),因此编码表现出现环境分化:仓库级工程选 Opus 4.7,终端密集型工作流选 GPT-5.5。
OpenAI 的新模型总体上获得了积极反馈。用户尤其喜欢其在交付有效结果时的速度与简洁。
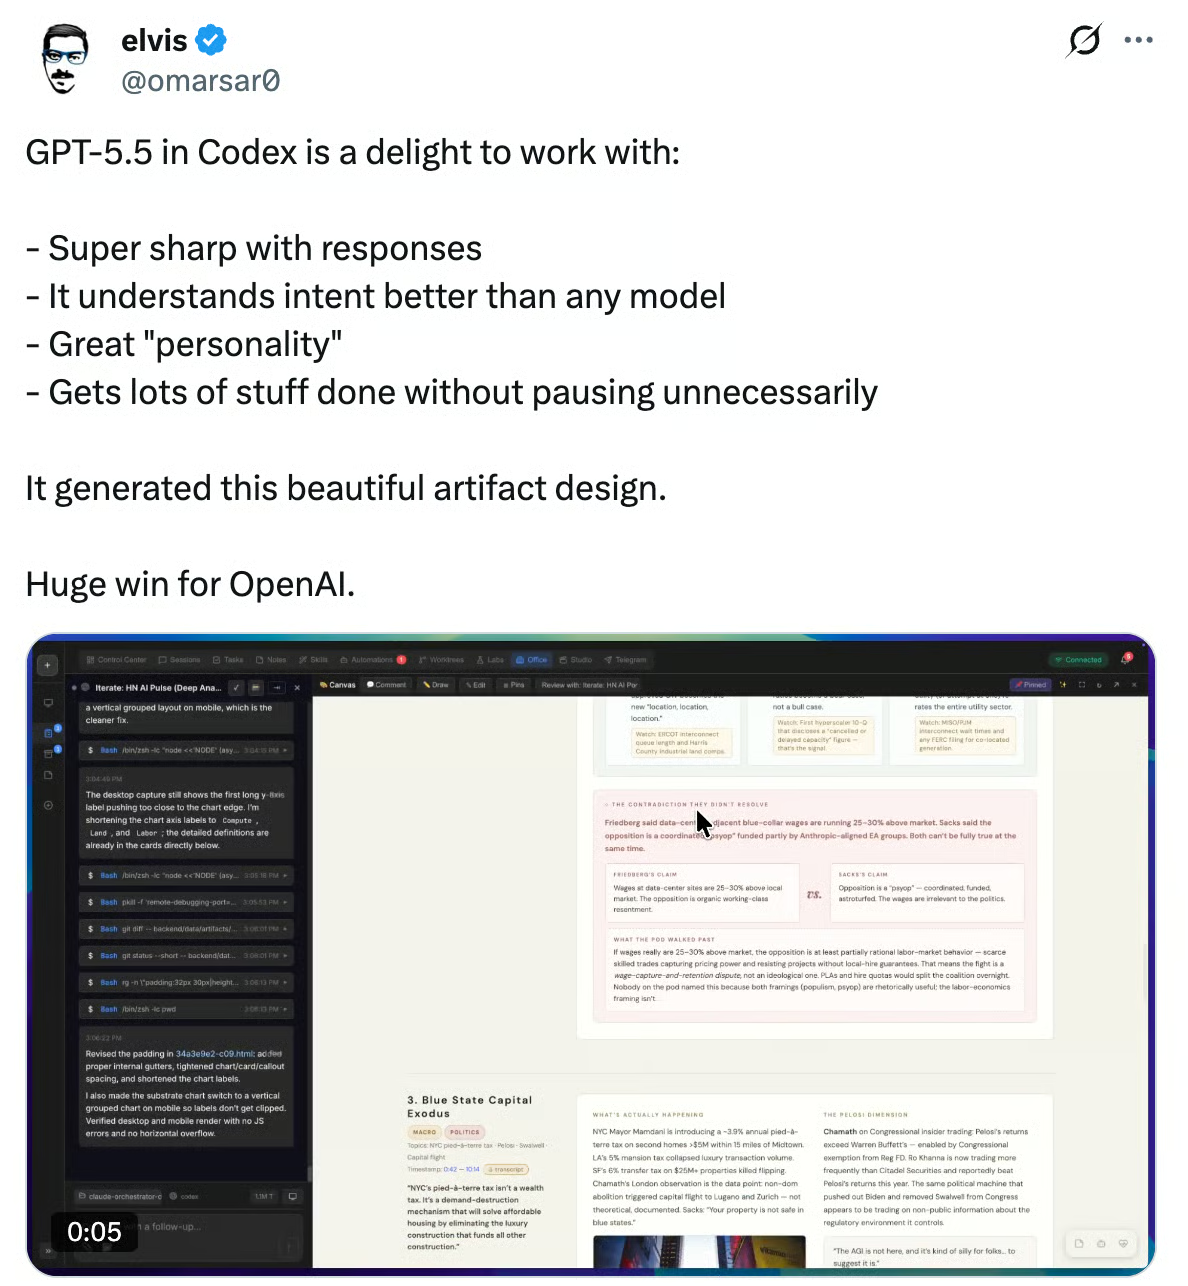
也有用户指出,尽管它较 GPT-5.4 有所提升,但可能不足以证明大幅涨价的合理性。
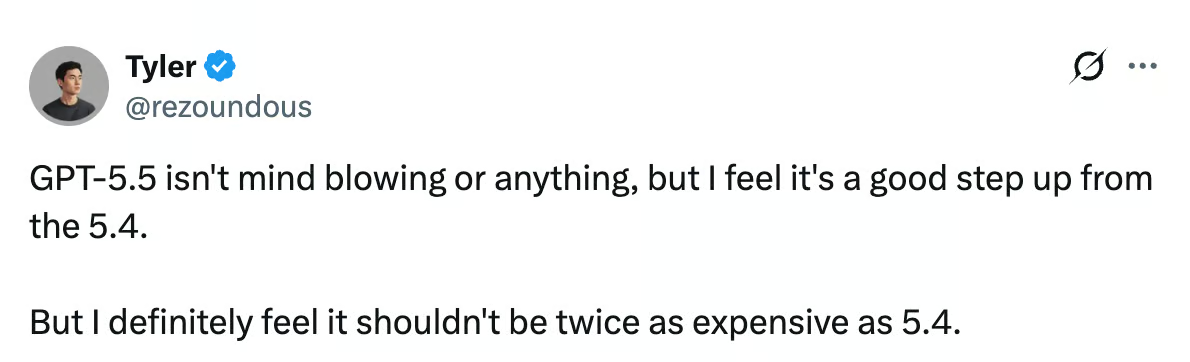
GPT-5.5 是一次渐进的能力更新,同时配套了非渐进的政策更新。该模型在单个任务上的速度更快、成本更低,并且在长上下文工作上有实质提升。从基准结果中可以清晰看到这些结论。
我们的测试呈现出更细腻的图景。长上下文的改进确实存在,且 GPT-5.5 在指令遵循测试中命中 12 项约束(而 Claude Opus 4.7 与 Sonnet 4.6 都是 11/12),但效率提升付出了代价:在将提示简单拆分后 GPT-5.4 能处理的求和任务,GPT-5.5 却屡屡失败。这暗示了输出简洁性与推理表现之间的权衡。
此次发布也是 OpenAI 首次根据请求方对网络安全访问进行正式分级,这对整个行业而言是一个值得关注的新动向。
如果您在使用 ChatGPT 或 Codex,今天就能用上新模型。如果您是 API 用户,还需要再等等。正如我们所说,这并非 OpenAI 的常规做法,但很可能很快就会到来。
与 DataCamp 一起学习
课程
课程
实践并学习路径你的进步。
使用 Google 继续