What is a Bootstrap?
Bootstrap is a method of inference about a population using sample data. Bradley Efron first introduced it in this paper in 1979. Bootstrap relies on sampling with replacement from sample data. This technique can be used to estimate the standard error of any statistic and to obtain a confidence interval (CI) for it. Bootstrap is especially useful when CI doesn't have a closed form, or it has a very complicated one.
Suppose we have a sample of n elements: X = {x1, x2, …, xn} and we are interested in CI for some statistic T = t(X). Bootstrap framework is straightforward. We just repeat R times the following scheme: For i-th repetition, sample with replacement n elements from the available sample (some of them will be picked more than once). Call this new sample i-th bootstrap sample, Xi, and calculate desired statistic Ti = t(Xi).
As a result, we'll get R values of our statistic: T1, T2, …, TR. We call them bootstrap realizations of T or a bootstrap distribution of T. Based on it, we can calculate CI for T. There are several ways of doing this. Taking percentiles seems to be the easiest one.
Bootstrap in Action
Let's use (once again) well-known iris dataset. Take a look at a first few rows:
Suppose we want to find CIs for median Sepal.Length, median Sepal.Width and Spearman's rank correlation coefficient between these two. We'll use R's boot package and a function called... boot. To use its power we have to create a function that calculates our statistic(s) out of resampled data. It should have at least two arguments: a dataset and a vector containing indices of elements from a dataset that were picked to create a bootstrap sample.
If we wish to calculate CIs for more than one statistic at once, our function has to return them as a single vector.
For our example, it may look like this:
 library(boot)

foo <- function(data, indices){
  dt<-data[indices,]
  c(
    cor(dt[,1], dt[,2], method='s'),
    median(dt[,1]),
    median(dt[,2])
  )
}
foo chooses desired elements (which numbers are stored in indices) from data and computes correlation coefficient of first two columns (method='s' is used to choose Spearman's rank coefficient, method='p' will result with Pearson's coefficient) and their medians.
We can also add some extra arguments, eg. let user choose type od correlation coefficient:
 foo <- function(data, indices, cor.type){
  dt<-data[indices,]
  c(
    cor(dt[,1], dt[,2], method=cor.type),
    median(dt[,1]),
    median(dt[,2])
  )
}
To make this tutorial more general, I'll use the latter version of foo.
Now, we can use the boot function. We have to supply it with a name od dataset, function that we've just created, number of repetitions (R) and any additional arguments of our function (like cor.type). Below, I use set.seed for reproducibility of this example.
 set.seed(12345)
myBootstrap <- boot(iris, foo, R=1000, cor.type='s')
boot function returns an object of the class called... (yes, you're right!) boot. It has two interesting elements. $t contains R values of our statistic(s) generated by the bootstrap procedure (bootstrap realizations of T):
$t0 contains values of our statistic(s) in original, full, dataset:
Printing boot object to the console gives some further information:
original is the same as $t0. bias is a difference between the mean of bootstrap realizations (those from $t), called a bootstrap estimate of T and value in original dataset (the one from $t0).
colMeans(myBootstrap$t)-myBootstrap$t0
std. error is a standard error of bootstrap estimate, which equals standard deviation of bootstrap realizations.
apply(myBootstrap$t,2,sd)
Different Types of Bootstrap CIs
Before we start with CI, it's always worth to take a look at the distribution of bootstrap realizations. We can use plot function, with index telling at which of statistics computed in foo we wish to look. Here index=1 is a Spearman's correlation coefficient between sepal length and width, index=2 is a median od sepal length, and index=3is a median od sepal width.
plot(myBootstrap, index=1)
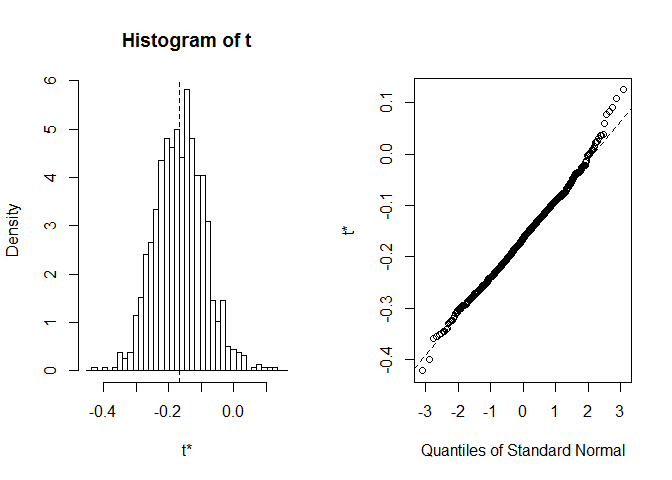
Distribution of bootstrap correlation coefficients seems quite normal-like. Let's find CI for it. We can use boot.ci. It defaults to 95-percent CIs, but it can be changed with the conf parameter.
boot.ci(myBootstrap, index=1)
boot.ci provides 5 types of bootstrap CIs. One of them, studentized interval, is unique. It needs an estimate of bootstrap variance. We didn't provide it, so R prints a warning: bootstrap variances needed for studentized intervals. Variance estimates can be obtained with second-level bootstrap or (easier) with jackknife technique. This is somehow beyond the scope of this tutorial, so let's focus on the remaining four types of bootstrap CIs.
If we don't want to see them all, we can pick relevant ones in type argument. Possible values are norm, basic, stud, perc, bca or a vector of these.
boot.ci(myBootstrap, index=1, type=c('basic','perc'))
The boot.ci function creates object of class... (yes, you've guessed!) bootci. Its elements are called just like types of CI used in type argument. $norm is a 3-element vector that contains confidence level and CI bounds.
boot.ci(myBootstrap, index=1, type='norm')$norm
$basic, $stud, $perc and $bca are 5-element vectors containing also percentiles used to compute CI (we'll come back to this later):
boot.ci(myBootstrap, index=1, type='basic')$basic
A bit of notation (Sorry!)
To get a feeling of what different types of CI are, we need to introduce some notation. So, let:
- t⋆ be the bootstrap estimate (mean of bootstrap realizations),
- t0 be a value of our statistic in the original dataset,
- se⋆ be a standard error of the bootstrap estimate,
- b be a bias of the bootstrap estimate b = t⋆ − t0
- α be a confidence level, typically α = 0.95,
- zα be a $1-\frac \alpha 2$-quantile of standard normal distribution,
- θα be an α-percentile of distribution of bootstrap realizations.
Percentile CI
With above notation, percentile CI is:
(θ(1 − α)/2, θ1 − (1 − α)/2)
so this just takes relevant percentiles. Nothing more.
Normal CI
A typical Wald CI would be:
t0 ± zα ⋅ se⋆
but in bootstrap case, we should correct it for bias. So it becomes:
$$ t_0 - b \pm z_\alpha \cdot se^\star \\ 2t_0 - t^\star \pm z_\alpha \cdot se^\star$$
Basic CI
Percentile CI is generally not recommended because it performs poorly when it comes to weird-tailed distributions. Basic CI (also called pivotal or empirical CI) is much more robust to this. The rationale behind it is to compute differences between each bootstrap replication and t0 and use percentiles of their distribution. Full details can be found, e.g. in L. Wasserman's All of Statistics
Final formula for basic CI is:
(2t0 − θ1 − (1 − α)/2, 2t0 − θ(1 − α)/2)
BCα CI
BCα comes from bias-corrected, accelerated. The formula for it is not very complicated but somewhat unintuitive, so I'll skip it. See article by Thomas J. DiCiccio and Bradley Efron if you're interested in details.
Acceleration mentioned in method's name requires using specific percentiles of bootstrap realizations. Sometimes it may happen that these would be some extreme percentiles, possibly outliers. BCα may be unstable in such cases.
Let's look at BCα CI for petal width median. In original dataset, this median equals precisely 3.
boot.ci(myBootstrap, index=3)
We get BCα CI (2.9, 2.9). That's weird, but luckily R warned us that extreme order statistics used as endpoints. Let's see what exactly happened here:
plot(myBootstrap, index=3)
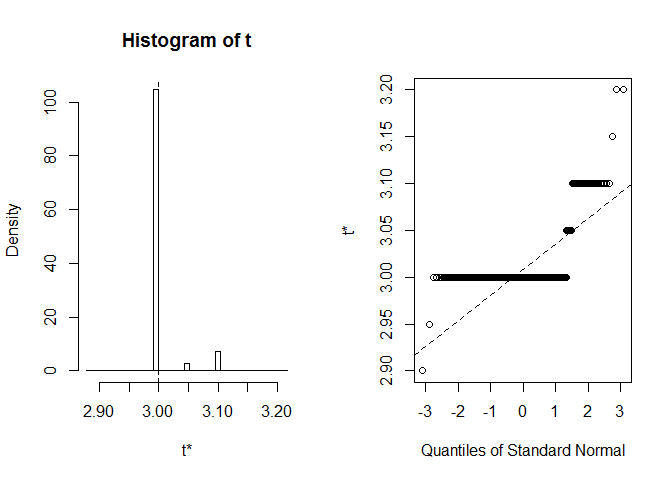
Distribution of bootstrap realizations is unusual. A vast majority of them (over 90%) are 3s.
In such a situation, "acceleration" in BCα method easily "jumps" to extreme values. Here, percentile CI, which forms a basis for BCα CI is (3, 3.1). Now, when we expand it "to the left" we have to use 0.002-percentile. The expansion "to the right" also goes to extremes: 0.997-percentile.
Replication of Results
Sometimes, we need to recreate bootstrap replications. If we can use R for it, this is not a problem. set.seed function solves the problem. Recreating bootstrap replications in other software would be much more complicated. What is more, for large R, recalculation in R can also not be an option (due to lack of time, for instance).
We can deal with this problem, saving indices of elements of the original dataset, that formed each bootstrap sample. This is what boot.array function (with indices=T argument) does.
tableOfIndices<-boot.array(myBootstrap, indices=T)
Each row is one bootstrap sample. Eg., our first sample contains the following elements:
Setting indices=F (a default), we'll get an answer to the question "How many times each element of original dataset appeared in each bootstrap sample?". For example, in the first sample: the 1st element of dataset appeared once, 2nd element didn't appear at all, 3rd element appeared once, 4th twice and so on.
tableOfAppearances<-boot.array(myBootstrap)
tableOfAppearances[1,]
A table like this allows us to recreate bootstrap realization outside R. Or in R itself when we don't want to use set.seed and do all the computation once again.
onceAgain<-apply(tableOfIndices, 1, foo, data=iris, cor.type='s')
Let's check if results are the same:
head(t(onceAgain))
head(myBootstrap$t)
all(t(onceAgain)==myBootstrap$t)
Yes, they are!
If you would like to learn more about Machine Learning in R, take DataCamp's Machine Learning Toolbox course and check out the Machine Learning in R for beginners tutorial.


 Josef Waples · 12 min

 Karlijn Willems · 15 min

 DataCamp Team · 4 min


What is a Bootstrap?
Bootstrap is a method of inference about a population using sample data. Bradley Efron first introduced it in this paper in 1979. Bootstrap relies on sampling with replacement from sample data. This technique can be used to estimate the standard error of any statistic and to obtain a confidence interval (CI) for it. Bootstrap is especially useful when CI doesn't have a closed form, or it has a very complicated one.
Suppose we have a sample of n elements: X = {x1, x2, …, xn} and we are interested in CI for some statistic T = t(X). Bootstrap framework is straightforward. We just repeat R times the following scheme: For i-th repetition, sample with replacement n elements from the available sample (some of them will be picked more than once). Call this new sample i-th bootstrap sample, Xi, and calculate desired statistic Ti = t(Xi).
As a result, we'll get R values of our statistic: T1, T2, …, TR. We call them bootstrap realizations of T or a bootstrap distribution of T. Based on it, we can calculate CI for T. There are several ways of doing this. Taking percentiles seems to be the easiest one.
Bootstrap in Action
Let's use (once again) well-known
irisdataset. Take a look at a first few rows:Suppose we want to find CIs for median
Sepal.Length, medianSepal.Widthand Spearman's rank correlation coefficient between these two. We'll useR'sbootpackage and a function called...boot. To use its power we have to create a function that calculates our statistic(s) out of resampled data. It should have at least two arguments: adatasetand a vector containingindicesof elements from a dataset that were picked to create a bootstrap sample.If we wish to calculate CIs for more than one statistic at once, our function has to return them as a single vector.
For our example, it may look like this:
foochooses desired elements (which numbers are stored inindices) fromdataand computes correlation coefficient of first two columns (method='s'is used to choose Spearman's rank coefficient,method='p'will result with Pearson's coefficient) and their medians.We can also add some extra arguments, eg. let user choose type od correlation coefficient:
To make this tutorial more general, I'll use the latter version of
foo.Now, we can use the
bootfunction. We have to supply it with a name od dataset, function that we've just created, number of repetitions (R) and any additional arguments of our function (likecor.type). Below, I useset.seedfor reproducibility of this example.bootfunction returns an object of the class called... (yes, you're right!)boot. It has two interesting elements.$tcontains R values of our statistic(s) generated by the bootstrap procedure (bootstrap realizations of T):$t0contains values of our statistic(s) in original, full, dataset:Printing
bootobject to the console gives some further information:originalis the same as$t0.biasis a difference between the mean of bootstrap realizations (those from$t), called a bootstrap estimate of T and value in original dataset (the one from$t0).std. erroris a standard error of bootstrap estimate, which equals standard deviation of bootstrap realizations.Different Types of Bootstrap CIs
Before we start with CI, it's always worth to take a look at the distribution of bootstrap realizations. We can use
plotfunction, withindextelling at which of statistics computed infoowe wish to look. Hereindex=1is a Spearman's correlation coefficient between sepal length and width,index=2is a median od sepal length, andindex=3is a median od sepal width.Distribution of bootstrap correlation coefficients seems quite normal-like. Let's find CI for it. We can use
boot.ci. It defaults to 95-percent CIs, but it can be changed with theconfparameter.boot.ciprovides 5 types of bootstrap CIs. One of them, studentized interval, is unique. It needs an estimate of bootstrap variance. We didn't provide it, soRprints a warning:bootstrap variances needed for studentized intervals. Variance estimates can be obtained with second-level bootstrap or (easier) with jackknife technique. This is somehow beyond the scope of this tutorial, so let's focus on the remaining four types of bootstrap CIs.If we don't want to see them all, we can pick relevant ones in
typeargument. Possible values arenorm,basic,stud,perc,bcaor a vector of these.The
boot.cifunction creates object of class... (yes, you've guessed!)bootci. Its elements are called just like types of CI used intypeargument.$normis a 3-element vector that contains confidence level and CI bounds.$basic,$stud,$percand$bcaare 5-element vectors containing also percentiles used to compute CI (we'll come back to this later):A bit of notation (Sorry!)
To get a feeling of what different types of CI are, we need to introduce some notation. So, let:
Percentile CI
With above notation, percentile CI is:
so this just takes relevant percentiles. Nothing more.
Normal CI
A typical Wald CI would be:
but in bootstrap case, we should correct it for bias. So it becomes:
$$ t_0 - b \pm z_\alpha \cdot se^\star \\ 2t_0 - t^\star \pm z_\alpha \cdot se^\star$$
Basic CI
Percentile CI is generally not recommended because it performs poorly when it comes to weird-tailed distributions. Basic CI (also called pivotal or empirical CI) is much more robust to this. The rationale behind it is to compute differences between each bootstrap replication and t0 and use percentiles of their distribution. Full details can be found, e.g. in L. Wasserman's All of Statistics
Final formula for basic CI is:
BCα CI
BCα comes from bias-corrected, accelerated. The formula for it is not very complicated but somewhat unintuitive, so I'll skip it. See article by Thomas J. DiCiccio and Bradley Efron if you're interested in details.
Acceleration mentioned in method's name requires using specific percentiles of bootstrap realizations. Sometimes it may happen that these would be some extreme percentiles, possibly outliers. BCα may be unstable in such cases.
Let's look at BCα CI for petal width median. In original dataset, this median equals precisely 3.
We get BCα CI (2.9, 2.9). That's weird, but luckily
Rwarned us thatextreme order statistics used as endpoints. Let's see what exactly happened here:Distribution of bootstrap realizations is unusual. A vast majority of them (over 90%) are 3s.
In such a situation, "acceleration" in BCα method easily "jumps" to extreme values. Here, percentile CI, which forms a basis for BCα CI is (3, 3.1). Now, when we expand it "to the left" we have to use 0.002-percentile. The expansion "to the right" also goes to extremes: 0.997-percentile.
Replication of Results
Sometimes, we need to recreate bootstrap replications. If we can use
Rfor it, this is not a problem.set.seedfunction solves the problem. Recreating bootstrap replications in other software would be much more complicated. What is more, for large R, recalculation inRcan also not be an option (due to lack of time, for instance).We can deal with this problem, saving indices of elements of the original dataset, that formed each bootstrap sample. This is what
boot.arrayfunction (withindices=Targument) does.Each row is one bootstrap sample. Eg., our first sample contains the following elements:
Setting
indices=F(a default), we'll get an answer to the question "How many times each element of original dataset appeared in each bootstrap sample?". For example, in the first sample: the 1st element of dataset appeared once, 2nd element didn't appear at all, 3rd element appeared once, 4th twice and so on.A table like this allows us to recreate bootstrap realization outside
R. Or inRitself when we don't want to useset.seedand do all the computation once again.Let's check if results are the same:
Yes, they are!
If you would like to learn more about Machine Learning in R, take DataCamp's Machine Learning Toolbox course and check out the Machine Learning in R for beginners tutorial.