
Last chance! 50% off DataCamp Premium
Sale ends in
OpenAI ने चुपचाप GPT-5.1-Codex को डेवलपर प्लेटफ़ॉर्म पर जारी किया है, और डेवलपर्स पहले से ही इसे आज के सबसे बेहतरीन कोडिंग मॉडल के रूप में सराह रहे हैं। पिछले Codex संस्करणों से अलग, GPT-5.1-Codex वास्तविक सॉफ्टवेयर इंजीनियरिंग, लंबे समय तक चलने वाली रीजनिंग, और टूल-उपयोगी एजेंट्स के लिए इंजीनियर किया गया है।
इस ट्यूटोरियल में, हम GitHub Issue Analyzer एजेंट को OpenAI Agents और GPT-5.1 Codex का उपयोग करके पूरी तरह बनाएंगे।
हमारा एजेंट यह करेगा:
यह एजेंट एक वरिष्ठ इंजीनियर की तरह व्यवहार करता है—कुछ लिखने से पहले रिसर्च करता है, पढ़ता है, तर्क करता है, और योजना बनाता है। आप हमारे अलग GPT-5.1 गाइड को भी देख सकते हैं कि और क्या नया है।
GPT-5.1 Codex, GPT-5.1 का एक विशेष संस्करण है जो केवल स्निपेट ऑटो-कम्प्लीशन के बजाय लंबे समय तक चलने वाले, एजेंटिक कोडिंग कार्यों के लिए बनाया गया है। यह वास्तविक सॉफ्टवेयर इंजीनियरिंग और एजेंटिक वर्कफ़्लोज़ के लिए पर्पस-बिल्ट है, जो इसे हमारे Issue-to-Plan ऑटोमेशन वर्कफ़्लो के लिए एकदम उपयुक्त इंजन बनाता है।
सामान्य मॉडलों के विपरीत, Codex कोडबेस को उसी तरह समझता है जैसे कोई वरिष्ठ इंजीनियर—यह इश्यूज़ पढ़ता है, आर्किटेक्चर पर विचार करता है, सही डायरेक्टरी की पहचान करता है, और केवल उन्हीं फाइलों का निरीक्षण करता है जो वास्तव में मायने रखती हैं। इससे एजेंट तेज, स्मार्ट और कहीं अधिक किफायती बनता है।
Codex लंबे समय तक चलने वाले, एजेंटिक कोडिंग कार्यों के लिए ऑप्टिमाइज़्ड है। यह GitHub CLI और Firecrawl API जैसे डेवलपर टूल्स के साथ स्वाभाविक रूप से इंटीग्रेट होता है, जिससे हमारा एजेंट इश्यूज़ फ़ेच कर सकता है, प्रोजेक्ट स्ट्रक्चर ऑनलाइन एक्सप्लोर कर सकता है, विशिष्ट फाइलें पढ़ सकता है, और आवश्यकता पड़ने पर डॉक्यूमेंटेशन जुटा सकता है। यह निर्देशों का बारीकी से पालन करता है, साफ़ और विश्वसनीय विश्लेषण देता है, और अपनी तर्क-शक्ति का प्रयास स्थिति के अनुसार ढालता है—सरल कार्यों पर तेज़ी से आगे बढ़ते हुए जटिल कार्यों पर गहराई में जाता है।
मजबूत कोड समझ और टूल-अवेयर रीजनिंग को मिलाकर, GPT-5.1 Codex हमारे एजेंट को यह क्षमता देता है कि वह किसी GitHub इश्यू को बिना पूरे रेपो को स्कैन किए या काल्पनिक कोड गढ़े, एक सटीक, क्रियान्वयन योग्य इंजीनियरिंग योजना में बदल सके। यही इस वर्कफ़्लो की रीढ़ है, क्योंकि यह वही इंजीनियरिंग अंतर्दृष्टि, संरचना, और शुद्धता लाता है जिस पर प्रोजेक्ट निर्भर करता है।
प्रोजेक्ट में जाने से पहले, सुनिश्चित करें कि आपका वातावरण तैयार है। आपके मशीन पर Git इंस्टॉल होना चाहिए। यदि आप सुनिश्चित नहीं हैं, तो पुष्टि करने के लिए git --version चलाएँ। आपको एक OpenAI डेवलपर प्लेटफ़ॉर्म खाता भी चाहिए, जिसमें कम से कम $6 का क्रेडिट हो ताकि API कॉल बिना बाधा के चल सकें।
अगला, निःशुल्क Firecrawl खाता प्राप्त करें और अपनी API कुंजियों को environment variables के रूप में सेट करें। इन्हीं के ज़रिए आपका analyzer OpenAI और Firecrawl से संवाद करेगा:
export OPENAI_API_KEY=sk-...
export FIRECRAWL_API_KEY="fc-..."
एक बार यह सेट हो जाए, उस वर्कफ़्लो को पावर देने वाले Python पैकेज इंस्टॉल करें। पहला, openai-agents, एक हल्का फ्रेमवर्क है जो मल्टी-एजेंट पाइपलाइंस बनाना आश्चर्यजनक रूप से आसान बनाता है। दूसरा, firecrawl-py, आपकी रिपॉज़िटरीज़ या डॉक्यूमेंटेशन से उपयोगी जानकारी क्रॉल कर निकालता है।
pip install openai-agents
pip install firecrawl-py
अंत में, सुनिश्चित करें कि आपका GitHub CLI इंस्टॉल और सेटअप है। निम्नलिखित कमांड आपको अपने GitHub खाते में लॉगिन करने में मदद करेगा।
gh auth login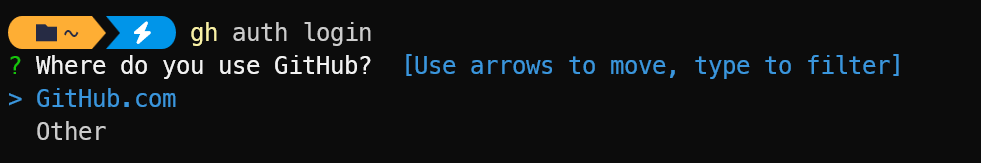
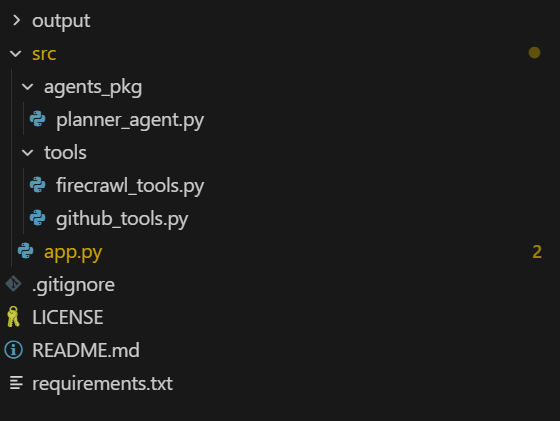
हम "src" नाम का एक फ़ोल्डर बनाएँगे जिसमें सभी कोड फाइलें होंगी। "agents_pkg" फ़ोल्डर में सभी एजेंट फाइलें होंगी, जबकि "tools" फ़ोल्डर में सभी टूल फाइलें होंगी।
मुख्य एप्लिकेशन, "app.py," में एक कमांड-लाइन इंटरफ़ेस (CLI) है जो उपयोगकर्ता इनपुट के आधार पर GitHub इश्यू रिपोर्ट तैयार करने के लिए प्लानिंग एजेंट्स का उपयोग करता है।
आपकी प्रोजेक्ट डायरेक्टरी इस तरह दिखनी चाहिए:
सबसे पहले, हम एक एजेंटिक टूल्स फाइल बनाएँगे जो एजेंट को सरल Python फ़ंक्शंस के जरिए GitHub और Firecrawl API तक पहुँचने में मदद करेगी।
हम टूल्स से शुरू करेंगे। src/tools डायरेक्टरी में firecrawl_tools.py नाम की फाइल बनाएँ और निम्न कोड जोड़ें।
1. अपने environment से FIRECRAWL_API_KEY का उपयोग कर Firecrawl क्लाइंट बनाना और लौटाना, और यदि कुंजी अनुपस्थित हो तो त्रुटि उठाना।
import json
import os

from agents import function_tool
from firecrawl import firecrawl


def _get_firecrawl_client():
    api_key = os.getenv("FIRECRAWL_API_KEY")
    if not api_key:
        raise RuntimeError("FIRECRAWL_API_KEY is not set")
    return firecrawl(api_key=api_key)
2. Firecrawl का उपयोग कर एक केंद्रित वेब सर्च चलाना (जैसे, डॉक्यूमेंटेशन, ब्लॉग पोस्ट्स, एरर) और परिणामों को JSON के रूप में लौटाना ताकि एजेंट उन्हें बाहरी संदर्भ के रूप में उपयोग कर सके।
@function_tool
def firecrawl_search(query: str, limit: int = 3) -> str:
    """
    Run a Firecrawl search for docs related to the issue or tech stack.

    Args:
        query: Search query (usually based on issue title / framework / error message).
        limit: Max number of results to return.

    Returns:
        JSON string of Firecrawl search results.
    """
    client = _get_firecrawl_client()
    results = client.search(query=query, limit=limit)
    return json.dumps(results)
3. Firecrawl के साथ एकल URL को स्क्रैप करना (markdown फॉर्मेट में) और गहन तकनीकी रिसर्च के लिए संरचित पेज सामग्री को JSON के रूप में लौटाना।
@function_tool
def firecrawl_scrape(url: str) -> str:
    """
    Scrape a single URL using Firecrawl for deeper research.

    Args:
        url: URL to scrape (docs, blog, README in another repo, etc.).

    Returns:
        JSON (markdown/structured) content from Firecrawl scrape.
    """
    client = _get_firecrawl_client()
    result = client.scrape(url=url, params={"formats": ["markdown"]})
return json.dumps(result)इसके बाद, हम src/tools डायरेक्टरी में github_tools.py नाम की फाइल बनाएँगे और निम्न कोड जोड़ेंगे।
1. GitHub CLI के माध्यम से किसी विशिष्ट GitHub इश्यू को फ़ेच करना और उसके विवरण को एजेंट के पढ़ने के लिए JSON के रूप में लौटाना।
import base64
import json
import subprocess
from typing import List, Optional

from agents import function_tool


@function_tool
def get_github_issue(repo: str, issue_number: int) -> str:
    """
    Fetch a GitHub issue using the GitHub CLI.

    Args:
        repo: Repository in 'owner/name' format.
        issue_number: The issue number to fetch.

    Returns:
        A JSON string containing the issue fields (title, body, labels, URL, etc.),
        or an error payload if the command fails.
    """
    try:
        result = subprocess.run(
            [
                "gh",
                "issue",
                "view",
                str(issue_number),
                "--repo",
                repo,
                "--json",
                "number,title,body,labels,url,author,createdAt,state,assignees",
            ],
            capture_output=True,
            text=True,
            check=True,
        )
        return result.stdout
    except subprocess.CalledProcessError as e:
        return json.dumps(
            {
                "error": "Failed to fetch issue via GitHub CLI",
                "stderr": e.stderr,
                "repo": repo,
                "issue_number": issue_number,
            }
        )
2. किसी रिमोट GitHub रेपो में केवल प्रासंगिक फाइलों की सूची बनाना (वैकल्पिक रूप से path और extension द्वारा फ़िल्टर किया गया) ताकि एजेंट पूरे प्रोजेक्ट को स्कैन न करे।
@function_tool
def list_repo_files_gh(
    repo: str,
    max_files: int = 80,
    extensions: Optional[List[str]] = None,
    path_prefixes: Optional[List[str]] = None,
) -> str:
    """
    List *relevant* files in the remote repo using GitHub CLI.

    Uses:
        gh api repos/{repo}/git/trees/HEAD?recursive=1

    The agent is expected to reason first which areas of the codebase are likely relevant
    (e.g. 'src/', 'app/', 'backend/api/', 'cli/'), and then call this tool with a small
    set of path_prefixes instead of scanning the entire project.

    Args:
        repo: Repository in 'owner/name' format (e.g. openai/openai-agents-python).
        max_files: Max number of files to return.
        extensions: Optional list of file extensions to keep (e.g. [".py", ".ts"]).
        path_prefixes: Optional list of path prefixes to include (e.g. ["src/", "app/api/"]).

    Returns:
        JSON string with file paths and filters applied.
    """
    try:
        result = subprocess.run(
            [
                "gh",
                "api",
                f"repos/{repo}/git/trees/HEAD?recursive=1",
            ],
            capture_output=True,
            text=True,
            check=True,
        )
    except subprocess.CalledProcessError as e:
        return json.dumps(
            {
                "error": "Failed to list repo files via GitHub CLI",
                "stderr": e.stderr,
                "repo": repo,
            }
        )

    try:
        data = json.loads(result.stdout)
    except json.JSONDecodeError:
        return json.dumps(
            {
                "error": "Failed to parse JSON from gh api",
                "raw": result.stdout[:2000],
                "repo": repo,
            }
        )

    tree = data.get("tree", [])

    if extensions is not None and not isinstance(extensions, list):
        extensions = [str(extensions)]
    exts = [e.lower() for e in (extensions or [])]

    if path_prefixes is not None and not isinstance(path_prefixes, list):
        path_prefixes = [str(path_prefixes)]
    prefixes = [p.strip() for p in (path_prefixes or []) if p.strip()]

    paths: List[str] = []
    for entry in tree:
        if entry.get("type") != "blob":
            continue  # only files
        path = entry.get("path", "")
        if not path:
            continue

        # If prefixes are provided, only keep files under those subtrees
        if prefixes and not any(path.startswith(pref) for pref in prefixes):
            continue

        if exts:
            suffix = "." + path.split(".")[-1].lower() if "." in path else ""
            if suffix not in exts:
                continue

        paths.append(path)
        if len(paths) >= max_files:
            break

    return json.dumps(
        {
            "repo": repo,
            "count": len(paths),
            "files": paths,
            "filtered_by_extensions": bool(exts),
            "filtered_by_prefixes": bool(prefixes),
        }
    )
3. GitHub CLI का उपयोग करते हुए रेपो से एकल फ़ाइल की सामग्री डाउनलोड और डिकोड करना, और आवश्यक होने पर ट्रंकेट किए गए टेक्स्ट को JSON के रूप में लौटाना।
@function_tool
def get_repo_file_gh(
    repo: str,
    path: str,
    ref: str = "",
    max_chars: int = 8000,
) -> str:
    """
    Read a file's contents from the remote repo using GitHub CLI.

    Uses:
        gh api repos/{repo}/contents/{path} [ -F ref=<branch> ]

    Args:
        repo: Repository in 'owner/name' format.
        path: File path in the repo (e.g. 'src/main.py').
        ref: Optional branch / commit / tag ref (default: repo's default branch).
        max_chars: Max characters of decoded content to return.

    Returns:
        JSON with file metadata and decoded content (truncated if needed),
        or an error payload if anything fails.
    """
    cmd = ["gh", "api", f"repos/{repo}/contents/{path}"]
    # Only add ref when explicitly set (GitHub default branch otherwise)
    if ref:
        cmd += ["-F", f"ref={ref}"]

    try:
        result = subprocess.run(
            cmd,
            capture_output=True,
            text=True,
            check=True,
        )
    except subprocess.CalledProcessError as e:
        return json.dumps(
            {
                "error": "Failed to fetch file via GitHub CLI",
                "stderr": e.stderr,
                "repo": repo,
                "path": path,
                "ref": ref or "DEFAULT_BRANCH",
            }
        )

    try:
        data = json.loads(result.stdout)
    except json.JSONDecodeError:
        return json.dumps(
            {
                "error": "Failed to parse JSON from gh api (contents)",
                "raw": result.stdout[:2000],
                "repo": repo,
                "path": path,
            }
        )

    if data.get("type") != "file":
        return json.dumps(
            {
                "error": "Path is not a file",
                "repo": repo,
                "path": path,
                "data_type": data.get("type"),
            }
        )

    encoding = data.get("encoding")
    content_b64 = data.get("content", "")

    if encoding != "base64":
        return json.dumps(
            {
                "error": "Unexpected encoding",
                "repo": repo,
                "path": path,
                "encoding": encoding,
            }
        )

    try:
        # GitHub often includes newlines in base64 payload
        raw_bytes = base64.b64decode(content_b64)
        text = raw_bytes.decode("utf-8", errors="replace")
    except Exception as e:  # noqa: BLE001
        return json.dumps(
            {
                "error": f"Failed to decode file content: {e}",
                "repo": repo,
                "path": path,
                "encoding": encoding,
            }
        )

    truncated = text[:max_chars]
    return json.dumps(
        {
            "repo": repo,
            "path": path,
            "ref": ref or "DEFAULT_BRANCH",
            "truncated": len(text) > max_chars,
            "content": truncated,
        }
)यहाँ, हम एक Issue Planner एजेंट परिभाषित करते हैं जो यह जानता है कि कैसे:
हम GitHub और Firecrawl टूल्स को वायर-इन करते हैं, एजेंट को लागत-सचेत तरीके से काम करने के लिए विस्तृत निर्देश देते हैं, और उसे gpt-5.1-codex मॉडल पर चलने को कहते हैं।
src/agents_pkg डायरेक्टरी में planner_agent.py फाइल बनाएँ और निम्न कोड जोड़ें:
from agents import Agent

from tools.github_tools import (
    get_github_issue,
    list_repo_files_gh,
    get_repo_file_gh,
)
from tools.firecrawl_tools import (
    firecrawl_search,
    firecrawl_scrape,
)


def build_planner_agent() -> Agent:
    """
    Issue Planner agent that:
    - Reads the GitHub issue
    - Reasons about which parts of the repo are relevant
    - Uses GitHub CLI to inspect a *small* set of files online
    - Uses Firecrawl for external research
    - Outputs a concrete, step-by-step execution plan
    """
    return Agent(
        name="Issue Planner",
        instructions=(
            "You are a senior software engineer.\n"
            "Goal: Given a GitHub issue and the online repo (structure + files), plus optional "
            "external research, produce a clear, step-by-step execution plan to resolve the issue.\n\n"
            "CONTEXT:\n"
            "- All repository interaction must be done *online* via GitHub CLI tools.\n"
            "- You have tools to: read the issue, list files under certain paths, read specific files, "
            "  and call Firecrawl search/scrape for docs.\n\n"
            "IMPORTANT STRATEGY (BE SMART):\n"
            "- Be selective and cost-aware. Do NOT scan the whole project.\n"
            "- First, deeply read the issue and infer which part of the system it affects:\n"
            "  routing layer, CLI, API handlers, DB layer, tests, etc.\n"
            "- Based on this reasoning, decide a small list of path prefixes and file types.\n\n"
            "RECOMMENDED WORKFLOW:\n"
            "1. Call get_github_issue(repo, issue_number) to fully understand the problem.\n"
            "2. From the issue, infer a small list of path prefixes where relevant code likely lives,\n"
            "   e.g. ['src/', 'app/', 'backend/api/', 'cli/'] depending on the project style.\n"
            "3. Call list_repo_files_gh with:\n"
            "   - extensions like ['.py', '.ts', '.js', '.tsx', '.jsx']\n"
            "   - path_prefixes set to that small, targeted list\n"
            "   This keeps the search focused instead of scanning the entire project.\n"
            "4. From the returned file list, pick at most ~5-15 key files that are most likely related\n"
            "   (entrypoints, routers, handlers, services, tests).\n"
            "5. Call get_repo_file_gh(repo, path=...) only on those selected files to inspect the "
            "   actual implementation.\n"
            "6. If you need framework or library context (FastAPI, Click, React, etc.), use\n"
            "   firecrawl_search and firecrawl_scrape to pull official docs or good examples.\n\n"
            "OUTPUT FORMAT (execution plan):\n"
            "After you have enough context from the issue + targeted code inspection (+ optional research), "
            "output a concise but concrete plan with sections:\n"
            "   - Issue summary\n"
            "   - Project/codebase understanding (where this issue lives in the architecture)\n"
            "   - Key files / components to touch (with file paths)\n"
            "   - Step-by-step implementation plan (Step 1, Step 2, ...)\n"
            "   - Testing strategy (unit / integration / manual)\n"
            "   - Edge cases, risks, and any open questions\n\n"
            "The plan must be actionable for a mid-level developer. Avoid generic advice; tie your steps "
            "to the actual files and modules you inspected.\n"
        ),
        tools=[
            get_github_issue,
            list_repo_files_gh,
            get_repo_file_gh,
            firecrawl_search,
            firecrawl_scrape,
        ],
        model="gpt-5.1-codex",
)यह मुख्य Python फाइल है जो एक कमांड-लाइन इंटरफ़ेस (CLI) प्रदान करती है और सारी लॉजिक, कॉलबैक्स, और एरर हैंडलिंग को एक संपूर्ण फाइल में समेटती है। यह अन्य फाइलों के टूल्स और एजेंट्स का कुशलतापूर्वक उपयोग करती है।
1. पहले, हम CLI के लिए आवश्यक सब कुछ सेटअप और इम्पोर्ट करते हैं। हम स्टैंडर्ड लाइब्रेरीज़ शामिल करते हैं, Windows पर सही Unicode आउटपुट सुनिश्चित करते हैं ताकि इमोजी और सिंबल्स सही प्रिंट हों, और OpenAI रनर के साथ हमारे प्लानर एजेंट को इम्पोर्ट करते हैं।
2. अगला, हम कमांड-लाइन विकल्प परिभाषित करते हैं, जिससे आप टूल चलाते समय GitHub रिपॉज़िटरी और इश्यू नंबर पास कर सकें।
src/app.py:
import argparse
import asyncio
import json
import os
import pathlib
import sys
from datetime import datetime

# Set UTF-8 encoding for stdout to handle Unicode characters
if sys.platform == "win32":
    import codecs
    sys.stdout = codecs.getwriter("utf-8")(sys.stdout.detach())
    sys.stderr = codecs.getwriter("utf-8")(sys.stderr.detach())

from agents import Runner, ItemHelpers
from openai.types.responses import ResponseTextDeltaEvent

from agents_pkg.planner_agent import build_planner_agent


def parse_args() -> argparse.Namespace:
    parser = argparse.ArgumentParser(
        description=(
            "Issue Planner: GPT-5.1-Codex + OpenAI Agents + GitHub CLI + Firecrawl\n"        )
    )
    parser.add_argument(
        "--repo",
        help="GitHub repo in 'owner/name' format (e.g. openai/openai-agents-python).",
    )
    parser.add_argument(
        "--issue",
        type=int,
        help="Issue number to plan for.",
    )
    return parser.parse_args()
3. फिर, हम इनपुट्स इकट्ठे करते हैं और संदर्भ तैयार करते हैं। हम आर्ग्युमेंट्स से रेपो और इश्यू पढ़ते हैं, सुनिश्चित करते हैं कि OpenAI API कुंजी सेट हो, एक स्पष्ट प्रॉम्प्ट बनाते हैं जो एजेंट को चरण-दर-चरण इश्यू का विश्लेषण करने को कहता है, और एक टाइमस्टैम्प वाला markdown फाइल बनाते हैं जहाँ अंतिम योजना सेव होगी।
def get_user_input(args: argparse.Namespace) -> tuple[str, int]:
    """Get repository and issue number from arguments or user input."""
    repo = args.repo or input("GitHub repo (owner/name): ").strip()
    issue_number = args.issue or int(input("Issue number: ").strip())
    return repo, issue_number


def validate_environment() -> None:
    """Validate that required environment variables are set."""
    if not os.getenv("OPENAI_API_KEY"):
        raise RuntimeError("OPENAI_API_KEY is not set")


def build_user_prompt(repo: str, issue_number: int) -> str:
    """Build the user prompt for the agent."""
    return (
        f"You are helping me plan how to implement GitHub issue #{issue_number} "
        f"in repo '{repo}'.\n\n"
        "Be selective and cost-aware:\n"
        "1. Use get_github_issue(repo, issue_number) to understand the problem.\n"
        "2. Based on the issue text, first reason about which directories and components "
        "   are likely relevant.\n"
        "3. Call list_repo_files_gh(repo, extensions=['.py', '.ts', '.js', '.tsx', '.jsx'], "
        "   path_prefixes=[<your inferred prefixes>]) to only explore those areas.\n"
        "4. From those results, choose a small set of the most relevant files and call "
        "   get_repo_file_gh(repo, path=...) on them.\n"
        "5. Optionally, use firecrawl_search and firecrawl_scrape if you need external docs.\n"
        "6. Finally, generate the execution plan in the structured format from your instructions."
    )


def setup_output_file(repo: str, issue_number: int) -> pathlib.Path:
    """Create output directory and return the markdown file path."""
    output_dir = pathlib.Path("output")
    output_dir.mkdir(exist_ok=True)
    timestamp = datetime.now().strftime("%Y%m%d_%H%M%S")
    markdown_file = output_dir / f"execution_plan_{repo.replace('/', '_')}_issue_{issue_number}_{timestamp}.md"
    return markdown_file
4. इसके बाद, हम एजेंट की सोच को दृश्य बनाते हैं। हम प्रत्येक इवेंट से एक साफ़ reasoning स्निपेट निकालने की कोशिश करते हैं और एक छोटा “💭 Reasoning…” लाइन प्रिंट करते हैं, ताकि रॉ इंटरनल्स की जगह आपको बैकग्राउंड में मॉडल क्या कर रहा है, उसका मानव-पठनीय संकेत दिखे।
def extract_reasoning_text(event_item) -> str | None:
    """Extract reasoning text from a reasoning event item."""
    reasoning_text = None

    if hasattr(event_item, 'raw_item'):
        raw = event_item.raw_item
        # Try multiple attribute names
        for attr_name in ['content', 'text', 'reasoning', 'message', 'delta']:
            if hasattr(raw, attr_name):
                val = getattr(raw, attr_name)
                if val and str(val).strip() and str(val) != 'None':
                    reasoning_text = str(val)
                    break

        # If still not found, try to access as dict-like
        if not reasoning_text:
            try:
                if hasattr(raw, '__dict__'):
                    for key, val in raw.__dict__.items():
                        if val and str(val).strip() and str(val) != 'None' and key in ['content', 'text', 'reasoning', 'message', 'delta']:
                            reasoning_text = str(val)
                            break
            except:
                pass

    # Also try direct attributes on event.item
    if not reasoning_text:
        for attr_name in ['content', 'text', 'reasoning', 'message']:
            if hasattr(event_item, attr_name):
                val = getattr(event_item, attr_name)
                if val and str(val).strip() and str(val) != 'None':
                    reasoning_text = str(val)
                    break

    return reasoning_text


def handle_reasoning_event(event_item) -> None:
    """Handle and display reasoning events."""
    reasoning_text = extract_reasoning_text(event_item)

    if reasoning_text and reasoning_text.strip():
        # Show first line or first 100 chars
        first_line = reasoning_text.split('\n')[0].strip()[:100]
        if len(reasoning_text.split('\n')[0].strip()) > 100:
            first_line += "..."
        print(f"\n💭 Reasoning: {first_line}", flush=True)
    else:
        # Don't show "None" - just show that reasoning is happening
        print(f"\n💭 Reasoning...", flush=True)
5. उसके बाद, हम टूल कॉल्स और ट्रैकिंग को हैंडल करते हैं। हम पता लगाते हैं कि एजेंट कौन सा टूल उपयोग कर रहा है, उसके आर्ग्युमेंट्स (जैसे रेपो, पाथ, या क्वेरी) को कॉम्पैक्ट स्ट्रिंग में फॉर्मैट करते हैं, “🔧 Calling…” संदेश प्रिंट करते हैं, और सक्रिय टूल्स का एक आंतरिक मैप रखते हैं ताकि उन्हें पूरा होने पर मार्क कर सकें और बाद में जो कुछ चला उसका सारांश दे सकें।
def extract_tool_info(event_item) -> tuple[str | None, str | None]:
    """Extract tool name and ID from a tool call event item."""
    tool_name = None
    tool_id = None

    # First try raw_item which contains the actual tool call data
    if hasattr(event_item, 'raw_item'):
        raw = event_item.raw_item
        # Try accessing tool_call through various paths
        tool_call = None
        if hasattr(raw, 'tool_call'):
            tool_call = raw.tool_call
        elif hasattr(raw, 'function_call'):
            tool_call = raw.function_call

        if tool_call:
            # Try to get name from tool_call
            if hasattr(tool_call, 'name'):
                tool_name = tool_call.name
            elif hasattr(tool_call, 'function') and hasattr(tool_call.function, 'name'):
                tool_name = tool_call.function.name
            # Try to get ID
            if hasattr(tool_call, 'id'):
                tool_id = tool_call.id
            elif hasattr(tool_call, 'tool_call_id'):
                tool_id = tool_call.tool_call_id

        # Fallback: try direct attributes on raw
        if not tool_name:
            if hasattr(raw, 'name'):
                tool_name = getattr(raw, 'name')
            elif hasattr(raw, 'function') and hasattr(raw.function, 'name'):
                tool_name = raw.function.name
            # Try using getattr with different possible attribute names
            for attr_name in ['tool_name', 'function_name', 'name']:
                if hasattr(raw, attr_name):
                    tool_name = getattr(raw, attr_name, None)
                    if tool_name:
                        break

    # Fallback to direct attributes
    if not tool_name and hasattr(event_item, 'tool_call'):
        tool_call = event_item.tool_call
        if hasattr(tool_call, 'name'):
            tool_name = tool_call.name
        if hasattr(tool_call, 'id'):
            tool_id = tool_call.id
        elif hasattr(tool_call, 'function') and hasattr(tool_call.function, 'name'):
            tool_name = tool_call.function.name
    if not tool_name and hasattr(event_item, 'name'):
        tool_name = event_item.name
    if not tool_name and hasattr(event_item, 'function'):
        func = event_item.function
        if hasattr(func, 'name'):
            tool_name = func.name

    return tool_name, tool_id


def format_tool_arguments(tool_call_obj) -> str:
    """Format tool arguments for display."""
    if not tool_call_obj or not hasattr(tool_call_obj, 'arguments'):
        return ""

    try:
        args_dict = json.loads(tool_call_obj.arguments) if isinstance(tool_call_obj.arguments, str) else tool_call_obj.arguments
        if 'repo' in args_dict:
            tool_args = f" → {args_dict['repo']}"
            if 'issue_number' in args_dict:
                tool_args += f"#{args_dict['issue_number']}"
            return tool_args
        elif 'path' in args_dict:
            return f" → {args_dict['path']}"
        elif 'query' in args_dict:
            q = str(args_dict['query'])
            return f" → {q[:40]}..." if len(q) > 40 else f" → {q}"
        elif 'url' in args_dict:
            return f" → {args_dict['url']}"
        elif 'extensions' in args_dict or 'path_prefixes' in args_dict:
            parts = []
            if 'extensions' in args_dict:
                parts.append(f"ext={args_dict['extensions']}")
            if 'path_prefixes' in args_dict:
                parts.append(f"paths={args_dict['path_prefixes']}")
            return f" → {', '.join(parts)}"
    except:
        pass

    return ""


def handle_tool_call_event(event_item, active_tools: dict, tool_counter: int) -> tuple[int, bool]:
    """Handle tool call events and return updated tool_counter and whether event was handled."""
    tool_name, tool_id = extract_tool_info(event_item)

    if tool_name:
        tool_counter += 1
        tool_id = tool_id or f"tool_{tool_counter}"
        active_tools[tool_id] = tool_name

        # Get tool arguments if available
        tool_call_obj = None
        if hasattr(event_item, 'raw_item') and hasattr(event_item.raw_item, 'tool_call'):
            tool_call_obj = event_item.raw_item.tool_call
        elif hasattr(event_item, 'tool_call'):
            tool_call_obj = event_item.tool_call

        tool_args = format_tool_arguments(tool_call_obj)
        print(f"\n[{tool_counter}] 🔧 Calling: {tool_name}{tool_args}...", flush=True)
        return tool_counter, True
    else:
        # Still couldn't extract - try to inspect raw_item structure
        if hasattr(event_item, 'raw_item'):
            raw = event_item.raw_item
            try:
                raw_attrs = [attr for attr in dir(raw) if not attr.startswith('_')]
                # Look for attributes that might contain the tool name
                for attr in raw_attrs:
                    try:
                        val = getattr(raw, attr)
                        if isinstance(val, str) and ('get_github' in val.lower() or 'list_repo' in val.lower() or 'firecrawl' in val.lower()):
                            tool_name = val
                            break
                        # Check if it's a dict-like object with name
                        if hasattr(val, 'name'):
                            tool_name = val.name
                            break
                    except:
                        continue

                if tool_name:
                    tool_counter += 1
                    tool_id = tool_id or f"tool_{tool_counter}"
                    active_tools[tool_id] = tool_name
                    print(f"\n[{tool_counter}] 🔧 Calling: {tool_name}...", flush=True)
                    return tool_counter, True
                else:
                    # Print raw_item structure for debugging
                    print(f"\n[DEBUG] raw_item attrs: {raw_attrs[:10]}", flush=True)
            except Exception as e:
                print(f"\n[DEBUG] Error inspecting raw_item: {e}", flush=True)

    return tool_counter, False


def handle_tool_output_event(event_item, active_tools: dict, completed_tools: list) -> None:
    """Handle tool output events and track completed tools."""
    tool_id = None

    # Try raw_item first
    if hasattr(event_item, 'raw_item') and hasattr(event_item.raw_item, 'tool_call_id'):
        tool_id = event_item.raw_item.tool_call_id
    elif hasattr(event_item, 'tool_call_id'):
        tool_id = event_item.tool_call_id
    elif hasattr(event_item, 'raw_item') and hasattr(event_item.raw_item, 'tool_call'):
        if hasattr(event_item.raw_item.tool_call, 'id'):
            tool_id = event_item.raw_item.tool_call.id
    elif hasattr(event_item, 'tool_call'):
        if hasattr(event_item.tool_call, 'id'):
            tool_id = event_item.tool_call.id
        elif hasattr(event_item.tool_call, 'function') and hasattr(event_item.tool_call.function, 'name'):
            # Try to match by name if ID not available
            tool_name_match = event_item.tool_call.function.name
            for tid, tname in active_tools.items():
                if tname == tool_name_match:
                    tool_id = tid
                    break

    if tool_id and tool_id in active_tools:
        tool_name = active_tools.pop(tool_id)
        completed_tools.append(tool_name)
    elif active_tools:
        # Fallback: use the first active tool
        tool_id, tool_name = next(iter(active_tools.items()))
        active_tools.pop(tool_id)
        completed_tools.append(tool_name)
6. अब, हम स्ट्रीमिंग लूप और पर्सिस्टेंस को वायर-अप करते हैं। हम एजेंट से आने वाले स्ट्रीमिंग इवेंट्स प्रोसेस करते हैं, टोकन्स को आते ही प्रिंट करते हैं, रियल-टाइम में reasoning और टूल कॉल्स दिखाते हैं, कुछ गड़बड़ी होने पर सहजता से नॉन-स्ट्रीमिंग रन पर फॉलबैक करते हैं, और अंत में कुछ उपयोगी मेटाडाटा के साथ पूरी निष्पादन योजना को एक markdown फाइल में लिखते हैं।
async def process_streaming_events(result, repo: str, issue_number: int) -> str:
    """Process streaming events from the agent execution."""
    final_output = ""
    active_tools = {}  # Track active tool calls by ID
    tool_counter = 0
    completed_tools = []
    first_event_received = False

    # Stream the events as they come in
    async for event in result.stream_events():
        # Handle raw response events (token-by-token streaming) - print immediately
        if event.type == "raw_response_event" and isinstance(event.data, ResponseTextDeltaEvent):
            if not first_event_received:
                first_event_received = True
            delta = event.data.delta
            print(delta, end="", flush=True)
            final_output += delta
        # Handle run item events (higher level updates)
        elif event.type == "run_item_stream_event":
            item_type = getattr(event.item, 'type', 'unknown')

            # Show reasoning events
            if item_type == "reasoning_item":
                handle_reasoning_event(event.item)
            elif item_type == "tool_call_item":
                tool_counter, handled = handle_tool_call_event(event.item, active_tools, tool_counter)
                if handled:
                    first_event_received = True
            elif item_type == "tool_call_output_item":
                handle_tool_output_event(event.item, active_tools, completed_tools)
            elif item_type == "message_output_item":
                message_text = ItemHelpers.text_message_output(event.item)
                if message_text and (not final_output or message_text not in final_output):
                    print(f"\n{message_text}", flush=True)
                    final_output += message_text

    print()  # Add newline after streaming

    # Show summary of tools used
    if completed_tools:
        print(f"---\n\n📊 Tools used ({len(completed_tools)}): {', '.join(completed_tools)}", flush=True)

    # If no streaming events occurred, fall back to final output
    if not final_output:
        final_output = result.final_output
        if final_output:
            print(final_output, flush=True)

    return final_output

async def run_agent_with_streaming(agent, user_prompt: str, repo: str, issue_number: int) -> str:
    """Run the agent with streaming support and fallback handling."""
    try:
        # Run agent with streaming (run_streamed is synchronous, returns immediately)
        result = Runner.run_streamed(
            agent,
            input=user_prompt,
            context={"repo": repo, "issue_number": issue_number},
        )

        return await process_streaming_events(result, repo, issue_number)

    except Exception as e:
        print(f"⚠️  Error: {e}", flush=True)
        # Fallback to standard async run
        result = await Runner.run(
            agent,
            input=user_prompt,
            context={"repo": repo, "issue_number": issue_number},
        )
        print(result.final_output, flush=True)
        return result.final_output

def save_output_to_file(markdown_file: pathlib.Path, repo: str, issue_number: int, final_output: str) -> None:
    """Save the final output to a markdown file."""
    with open(markdown_file, 'w', encoding='utf-8') as f:
        f.write(f"# GitHub Issue Analysis: {repo}#{issue_number}\n\n")
        f.write(f"**Generated on:** {datetime.now().strftime('%Y-%m-%d %H:%M:%S')}\n\n")
        f.write(f"**Repository:** {repo}\n")
        f.write(f"**Issue Number:** {issue_number}\n\n")
        f.write("---\n\n")
        f.write(final_output)

    print(f"---\n\n✅ Saved: {markdown_file}", flush=True)
7. अंत में, हम सब कुछ मुख्य एंट्री पॉइंट में जोड़ते हैं। हम आर्ग्युमेंट्स पार्स करते हैं, रेपो और इश्यू लेते हैं, एनवायरनमेंट वेलिडेट करते हैं, एजेंट और उसका प्रॉम्प्ट बनाते हैं, स्ट्रीमिंग सहित प्लानर चलाते हैं (आवश्यकता पड़ने पर सिंक रन पर फॉलबैक), और परिणाम सेव करते हैं।
async def main() -> None:
    """Main entry point for the application."""
    args = parse_args()
    repo, issue_number = get_user_input(args)
    validate_environment()

    agent = build_planner_agent()
    user_prompt = build_user_prompt(repo, issue_number)
    markdown_file = setup_output_file(repo, issue_number)

    print(f"\n🔍 Analyzing {repo}#{issue_number}...\n")

    # Run the agent with streaming support
    try:
        final_output = await run_agent_with_streaming(agent, user_prompt, repo, issue_number)
    except Exception as e:
        print(f"⚠️  Error: {e}", flush=True)
        # Final fallback to standard sync run
        result = Runner.run_sync(
            agent,
            input=user_prompt,
            context={"repo": repo, "issue_number": issue_number},
        )
        print(result.final_output, flush=True)
        final_output = result.final_output

    # Save output to file
    save_output_to_file(markdown_file, repo, issue_number, final_output)


if __name__ == "__main__":
    asyncio.run(main())
नोट: सोर्स कोड, कॉन्फ़िगरेशन, और डॉक्यूमेंटेशन GitHub रिपॉज़िटरी पर उपलब्ध हैं: kingabzpro/Issue-Analyzer। कृपया इसे देखें और परिणामों को दोहराते समय इसे मार्गदर्शक के रूप में उपयोग करें।
हमारे CLI ऐप का उपयोग करने के दो तरीके हैं: इंटरैक्टिव मोड, जिसमें ऐप आपसे एक-एक करके रिपॉज़िटरी नाम और इश्यू नंबर माँगेगा, और CLI मोड, जिसमें ऐप लॉन्च करते समय आपको सारी जानकारी देनी होगी।
इंटरैक्टिव मोड शुरू करने के लिए, निम्न कमांड टाइप करें:
python src/app.pyशुरू होने पर, आपसे रिपॉज़िटरी नाम और इश्यू नंबर देने को कहा जाएगा, और ऐप आपकी सहायता के लिए टूल्स और reasoning का उपयोग शुरू कर देगा।
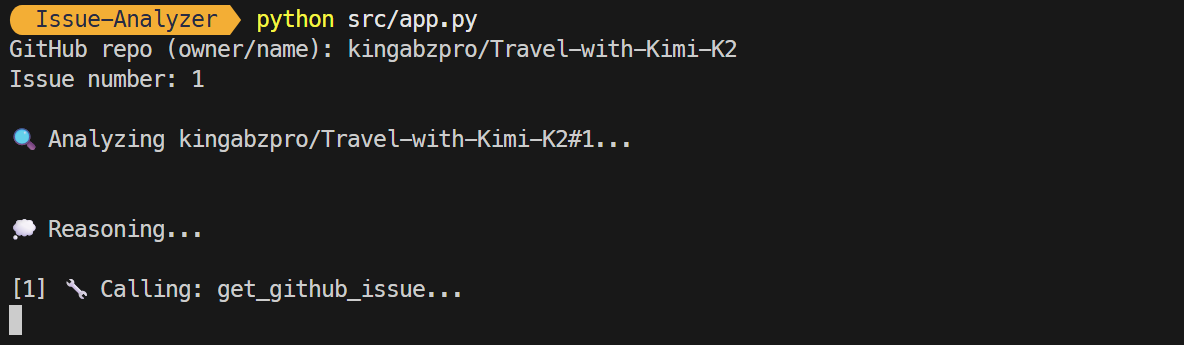
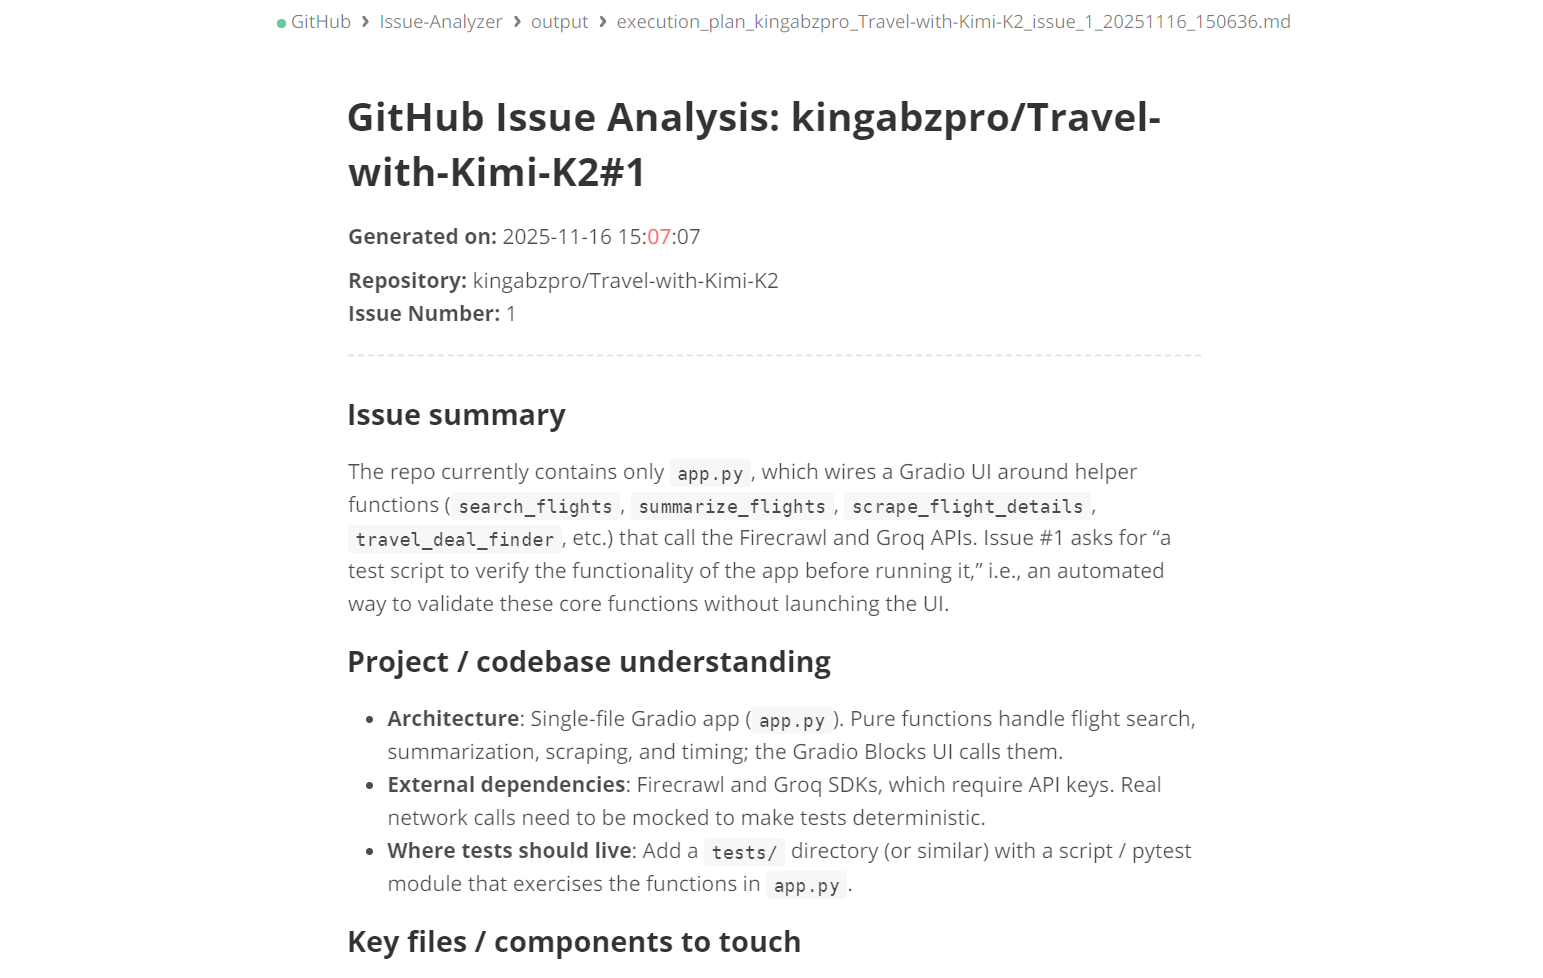
परिणामस्वरूप, कुछ ही सेकंड में आपको इश्यू का सारांश और उसे हल करने के तरीके मिलेंगे। इस सारांश में उपयोग किए गए टूल्स और वह markdown फाइल कहाँ सेव हुई है, इसकी जानकारी शामिल होगी।
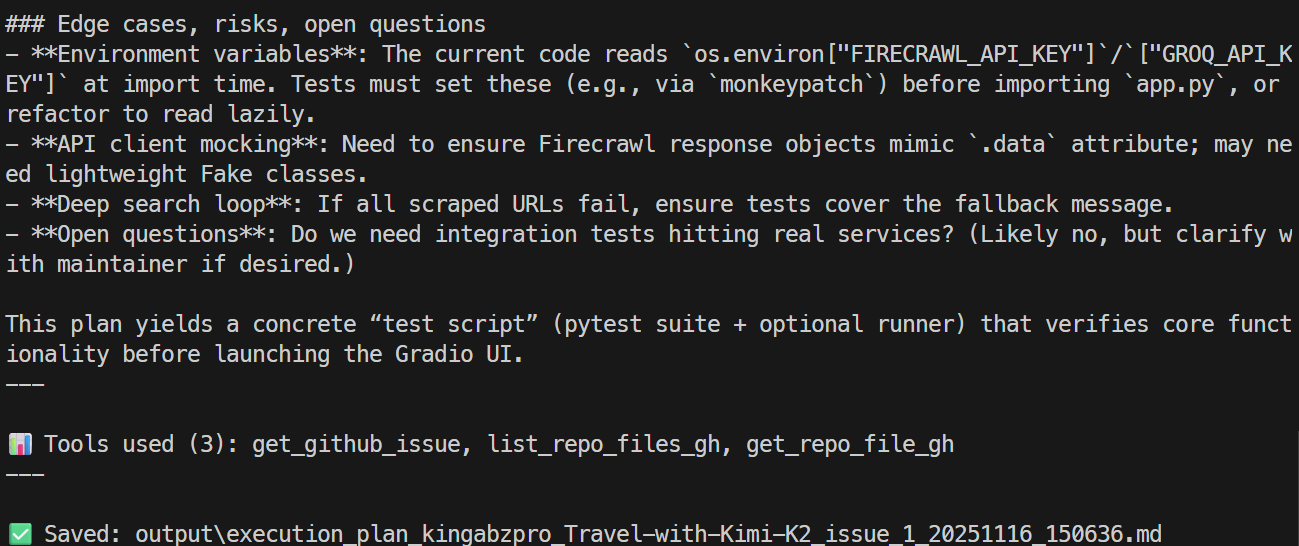
आप विस्तृत इश्यू प्लान की समीक्षा करने के लिए markdown फाइल खोल सकते हैं।
CLI मोड में कमांड में सीधे रिपॉज़िटरी नाम और इश्यू आर्ग्युमेंट शामिल होना चाहिए, जैसा नीचे दिखाया गया है:
python src/app.py --repo kingabzpro/Travel-with-Kimi-K2 --issue 1पूरा प्रोसेस स्ट्रीम किया जाता है, यानी आप देखेंगे कि एजेंट कौन से टूल्स उपयोग कर रहा है और क्या वह प्रभावी ढंग से तर्क कर रहा है या नहीं। अंत में उत्पन्न उत्तर भी स्ट्रीम होगा।
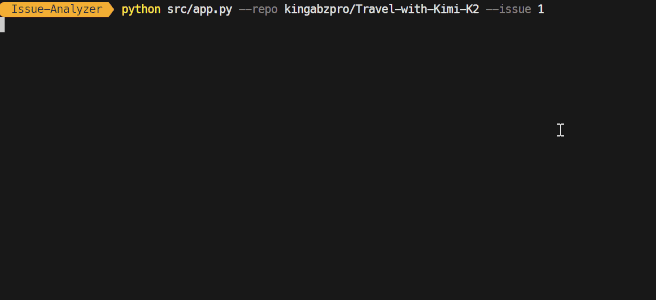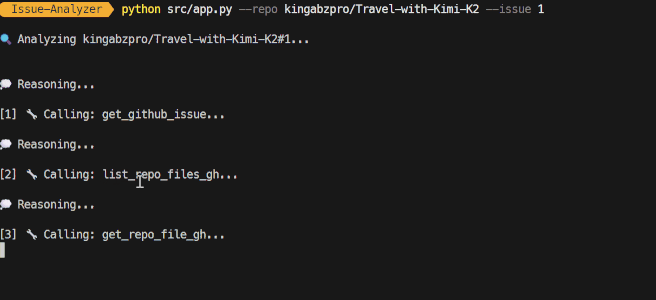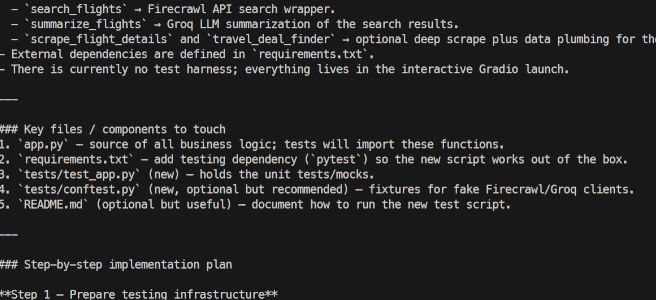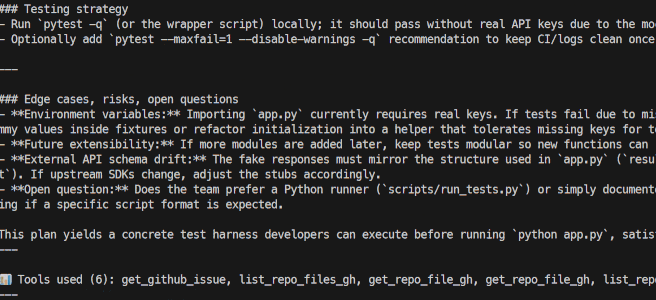
GitHub Issue Analyzer का वर्तमान संस्करण इश्यूज़ को समझने और सटीक निष्पादन योजनाएँ बनाने के लिए डिज़ाइन किया गया है।
हालाँकि, किसी एजेंटिक वर्कफ़्लो की असली क्षमता योजना बनने के बाद के सभी चरणों को स्वचालित करने में निहित है। यहाँ कुछ बड़े अपग्रेड हैं जिन्हें आप सिस्टम में लागू कर सकते हैं:
प्रोजेक्ट का लक्ष्य एक योजना को स्वत: रूप से एक कार्यशील pull request में बदलना है। इससे डेवलपमेंट प्रक्रिया सुगम होगी और वर्कफ़्लो अधिक कुशल बनेगा।
इस फ़ीचर में एजेंट से सीधे नई ब्रांच बनाने की क्षमता शामिल होगी, जो बदलावों के क्रियान्वयन को आसान बनाएगी। साथ ही, एजेंट जनरेट की गई योजना के आधार पर कोड में संशोधन लागू करेगा और GitHub CLI वर्कफ़्लोज़ चलाएगा, जैसे gh pr create और gh pr view।
इसके अलावा, सिस्टम स्वत: रूप से pull request विवरण, changelogs, और लिंक्ड इश्यू रेफरेंसेज़ जनरेट करेगा। यह लेबल्स को भी समझदारी से लगाएगा—उन्हें bug fixes, enhancements, या refactors के रूप में वर्गीकृत करेगा।
कुल मिलाकर, यह पहल एजेंट को एक पूर्णतः स्वायत्त Issue to Pull Request ऑटोमेशन सिस्टम में बदल देती है, जिससे डेवलपमेंट चक्र में उत्पादकता और स्थिरता में उल्लेखनीय वृद्धि होती है।
यह अपग्रेड GitHub इश्यू विश्लेषण की प्रक्रिया को बैच क्षमताएँ देकर बेहतर बनाएगा। व्यक्तिगत समस्याओं पर ध्यान केंद्रित करने के बजाय, टीमें एक साथ कई इश्यूज़ पर बैच स्कैन कर सकेंगी। यह नया फ़ीचर पूरे बैकलॉग का समानांतर या क्यूड विश्लेषण करने देगा, जिससे बड़ी मात्रा में इश्यूज़ को प्रभावी ढंग से संभालना आसान होगा।
इसके अलावा, यह अपग्रेड डुप्लिकेट या संबंधित इश्यूज़ की पहचान को सुविधा देगा, जिससे बेहतर संगठन संभव होगा। इश्यूज़ को जटिलता, सबसिस्टम, या प्रभाव जैसे मानदंडों के आधार पर वर्गीकृत किया जा सकता है।
ऑपरेशंस को और सुव्यवस्थित करने के लिए, टीमें GitHub या Firecrawl टूल्स को बैच मोड में चला सकेंगी, जिससे दक्षता में काफी सुधार होगा। अंततः, यह अपग्रेड टीमों को एक ही कमांड देता है जो स्वत: रूप से दर्जनों या सैकड़ों इश्यूज़ को एक साथ ट्रायेज कर सकता है।
Pull request (PR) बनाने से पहले, यह आवश्यक है कि एजेंट प्रस्तावित बदलावों को केवल जनरेट करने के बजाय पूरी तरह मान्य करे। इस मान्यकरण प्रक्रिया में कई योजनाबद्ध फ़ीचर्स शामिल होने चाहिए, जिनमें GitHub Actions या लोकल टेस्ट रनर्स के माध्यम से यूनिट टेस्ट चलाना ताकि यह सुनिश्चित हो कि कोड अपेक्षित रूप से व्यवहार करता है।
डिपेंडेंसी वेलिडेशन भी महत्वपूर्ण है। इसमें इम्पोर्ट्स की शुद्धता की जाँच, किसी भी मिसिंग मॉड्यूल की पहचान, और वर्ज़न मिसमैच को हल करना शामिल है जो प्रोजेक्ट को प्रभावित कर सकते हैं। इसके अतिरिक्त, लिंटिंग, फ़ॉर्मैटिंग, और टाइप चेकिंग कोड की गुणवत्ता बनाए रखने में अहम भूमिका निभाते हैं।
यह भी ज़रूरी है कि ये संशोधन मौजूदा बिल्ड पाइपलाइंस को बाधित न करें, और API में किसी ब्रेकिंग बदलाव या रिग्रेशन का पता चल सके। इन चरणों का पालन करके, हम सुनिश्चित कर सकते हैं कि PR साफ़, सुरक्षित, और प्रोडक्शन डिप्लॉयमेंट के लिए तैयार रहे।
GPT-5.1 Codex और openai-agents के साथ उन्नत, बहु-चरण एजेंट्स बनाना आश्चर्यजनक रूप से सरल है। आपको बस अपने टूल्स परिभाषित करने हैं और मॉडल को यह स्पष्ट निर्देश देने हैं कि उन्हें कब और कैसे उपयोग करना है।
इस ट्यूटोरियल में, मैंने GitHub CLI का उपयोग किया क्योंकि यह तेज़, सहज और इंटीग्रेट करना आसान है, लेकिन आप उतनी ही आसानी से GitHub Python SDK, डायरेक्ट API कॉल्स, या कोई अन्य CLI या Bash यूटिलिटी भी उपयोग कर सकते हैं। असली शक्ति इसकी लचीलापन है।
आप इस सेटअप को जितना चाहें आगे बढ़ा सकते हैं।
उदाहरण के लिए, आप बना सकते हैं:
इस ट्यूटोरियल का लक्ष्य दिखाना था कि GPT-5.1 Codex वास्तव में क्या कर सकता है: यह टूल-कॉलिंग को बेझिझक संभालता है, बड़े कोडबेस समझता है, संरचित रीजनिंग करता है, और बिना लगातार उपयोगकर्ता इनपुट के लंबी ऑटोमेशन चेन चला सकता है।
यदि आप AI एजेंट्स बनाना और सीखना चाहते हैं, तो मैं हमारे AI Agents with Google ADK कोर्स के साथ-साथ हमारी बनाने योग्य AI एजेंट प्रोजेक्ट्स की सूची देखने की अनुशंसा करता/करती हूँ।
शीर्ष DataCamp कोर्स
{count, plural, one {कोर्स} other {कोर्स}}
{count, plural, one {कोर्स} other {कोर्स}}
{count, plural, one {कोर्स} other {कोर्स}}
