
Last chance! 50% off DataCamp Premium
Sale ends in
एआई की तेजी से बदलती दुनिया में, बड़े भाषा मॉडल्स के आगमन ने हमारे टेक्स्ट से इंटरैक्ट करने और उसे जनरेट करने के तरीके को बदल दिया है। नवंबर 2022 में OpenAI के ChatGPT के रिलीज़ होने के बाद से, बड़े भाषा मॉडल्स की एक नई लहर रोज़ सामने आ रही है।
इन मॉडल्स में, Cohere Command प्रैक्टिशनर्स के बीच एक प्रमुख विकल्प बन गया है। Cohere डेवलपर्स और व्यवसायों को उनकी एप्लिकेशन्स और उपयोग मामलों में फाउंडेशनल मॉडल्स की शक्ति का लाभ उठाने के लिए अत्याधुनिक टूल्स प्रदान करता है।
यह शुरुआती मार्गदर्शिका Cohere के API की पेशकशों का वर्णन करने का उद्देश्य रखती है, जिसमें इसकी क्षमताओं, लाभों, और व्यावहारिक कार्यान्वयन रणनीतियों की गहन पड़ताल शामिल है।
हम बड़े भाषा मॉडल्स का एक त्वरित अवलोकन करके शुरू करेंगे, लेकिन यदि आप अधिक व्यापक दृष्टिकोण चाहते हैं, तो Large Language Models (LLMs) पर यह कोर्स देखें।
बड़े भाषा मॉडल्स (LLMs) उन्नत एआई सिस्टम हैं जो मानव-सदृश टेक्स्ट को समझते और उत्पन्न करते हैं। इन्हें विशाल मात्रा में डेटा पर प्रशिक्षित किया जाता है ताकि ये जटिल पैटर्न समझ सकें, भाषा की बारीकियों को पकड़ सकें, और सुसंगत प्रतिक्रियाएँ दे सकें।
LLMs विभिन्न भाषा-संबंधी कार्य कर सकते हैं, जैसे अनुवाद, टेक्स्ट पूर्णता, सारांश, और संवादात्मक इंटरैक्शन।
Cohere इस क्षेत्र का एक महत्वपूर्ण खिलाड़ी है, जो एक उपयोगकर्ता-अनुकूल API प्रदान करता है जिससे डेटा वैज्ञानिक इन LLM क्षमताओं तक पहुँच पाते हैं और अपने वर्कफ़्लो को सरल बनाते हैं।
2019 में स्थापित, Cohere एक कनाडाई उद्यम है जो व्यवसायों के लिए आर्टिफिशियल इंटेलिजेंस समाधान बनाने के लिए समर्पित है। यह बड़े भाषा मॉडल (LLM) उद्योग में तेजी से एक महत्वपूर्ण नाम बन गया है, जिसे अक्सर OpenAI GPT और Anthropic Claude जैसे प्रतिस्पर्धियों के साथ उल्लेख किया जाता है।
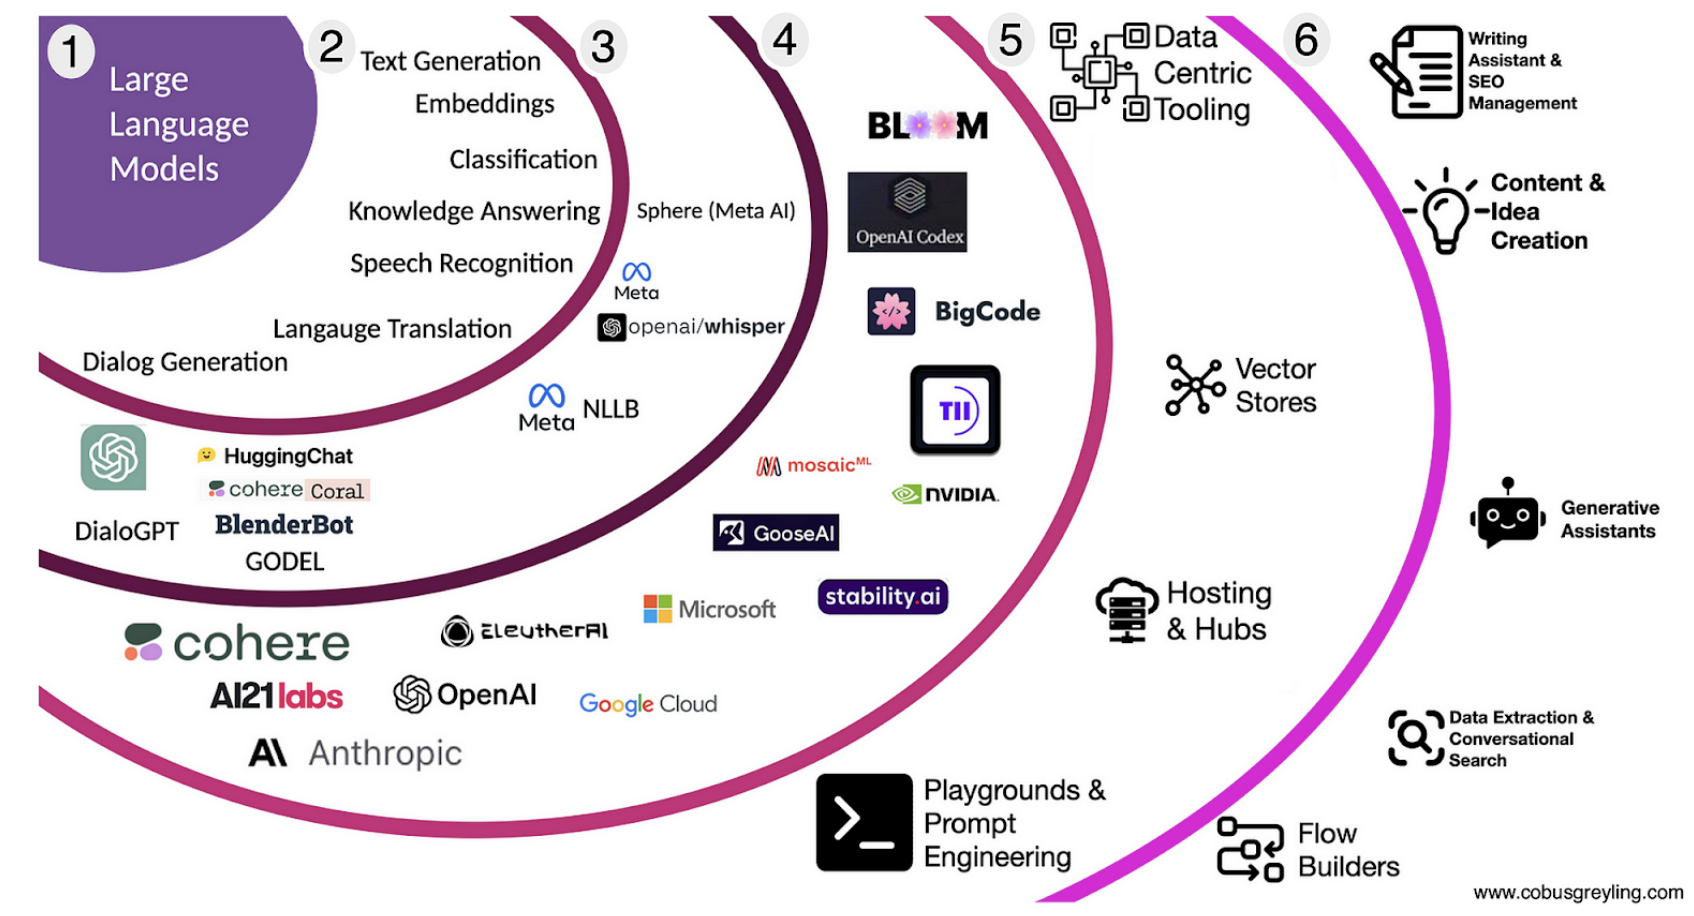
स्रोत: Cobus Greyling, Large Language Model Landscape, Medium
मुख्य रूप से, Cohere भाषा जनरेशन के लिए फाउंडेशनल मॉडल्स विकसित करता और उपलब्ध कराता है, जो डेवलपर्स और व्यवसायों के लिए मुख्यतः इसके API सर्विस के माध्यम से सुलभ हैं।
Cohere मुख्यतः तीन प्रकार के मॉडल्स प्रदान करता है:
हम Cohere मॉडल्स तक दो तरीकों से पहुँच सकते हैं:
Cohere एक एक्सक्लूसिव चैट इंटरफ़ेस भी प्रदान करता है जो ChatGPT जैसा है—जिसे अंदर से Command R+ संचालित करता है।
Cohere Playground, Cohere मॉडल्स के साथ इंटरैक्ट करने के लिए एक उपयोगकर्ता-अनुकूल इंटरफ़ेस प्रदान करता है, जो GPT के साथ काम करने जैसे सहज अनुभव देता है।
उपयोगकर्ता विभिन्न मॉडल क्षमताओं का अन्वेषण और प्रयोग कर सकते हैं, टेक्स्ट जनरेट कर सकते हैं और इसके व्यवहार के बारे में समझ बना सकते हैं। अपने स्लीक और सुलभ डिज़ाइन के साथ, Cohere Playground उपयोगकर्ताओं को तेजी से प्रोटोटाइप बनाने और Cohere के मॉडल ऑफ़रिंग्स का परीक्षण करने में सक्षम बनाता है।
Cohere Playground उपयोगकर्ताओं के लिए मॉडल्स का अन्वेषण और प्रयोग करने हेतु निःशुल्क है (उत्पादन में जाने तक यह मुफ़्त है)।
Cohere Playground का उपयोग करने के लिए, हमें पहले Cohere की वेबसाइट पर साइन अप करना होगा।
इसके बाद, हम साइन इन कर सकते हैं, और हम नीचे दिखाए गए पेज पर पहुँचेंगे—जो OpenAI प्लेटफ़ॉर्म के Playground से काफी मिलता-जुलता है। दाईं ओर के ड्रॉपडाउन का उपयोग करके, हम विभिन्न Cohere मॉडल्स चुन सकते हैं।
Playground में अलग-अलग कार्यों के लिए थोड़े अलग इंटरफ़ेस हैं। ऊपर की ओर, आपके पास चार विकल्प होते हैं: Chat, Classify, Embed, और Generate।
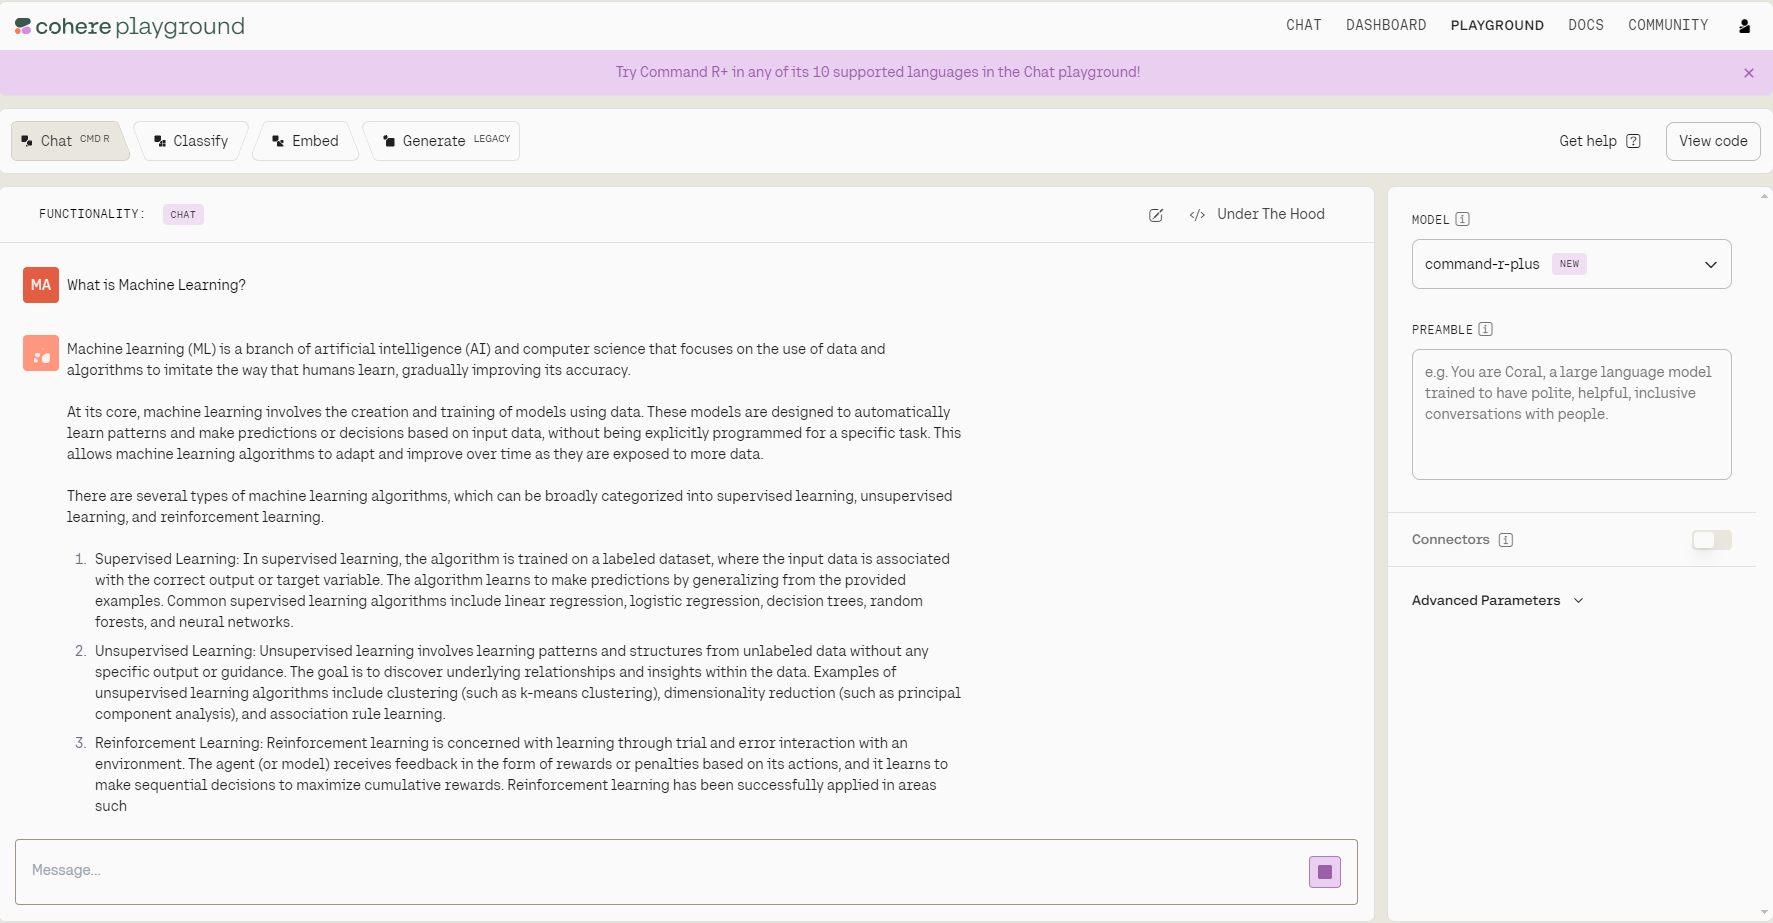
Cohere Playground का डैशबोर्ड
Cohere Playground, Cohere मॉडल्स की क्षमताओं का जल्दी से परीक्षण करने के लिए बढ़िया है, लेकिन यदि आप कोई एप्लिकेशन या वर्कफ़्लो बना रहे हैं, तो आपको इन मॉडल्स तक पहुँचने का एक प्रोग्रामेटिक तरीका चाहिए। वहीं पर Cohere का API काम आता है!
Cohere के API तक पहुँचना काफी सीधा है। संक्षेप में, हमें ये करने होंगे:
आइए इन चरणों पर एक-एक करके बात करते हैं।
हम pip का उपयोग करके cohere क्लाइंट इंस्टॉल कर सकते हैं।
!pip install cohereअब, हमें एक API कुंजी की आवश्यकता है।
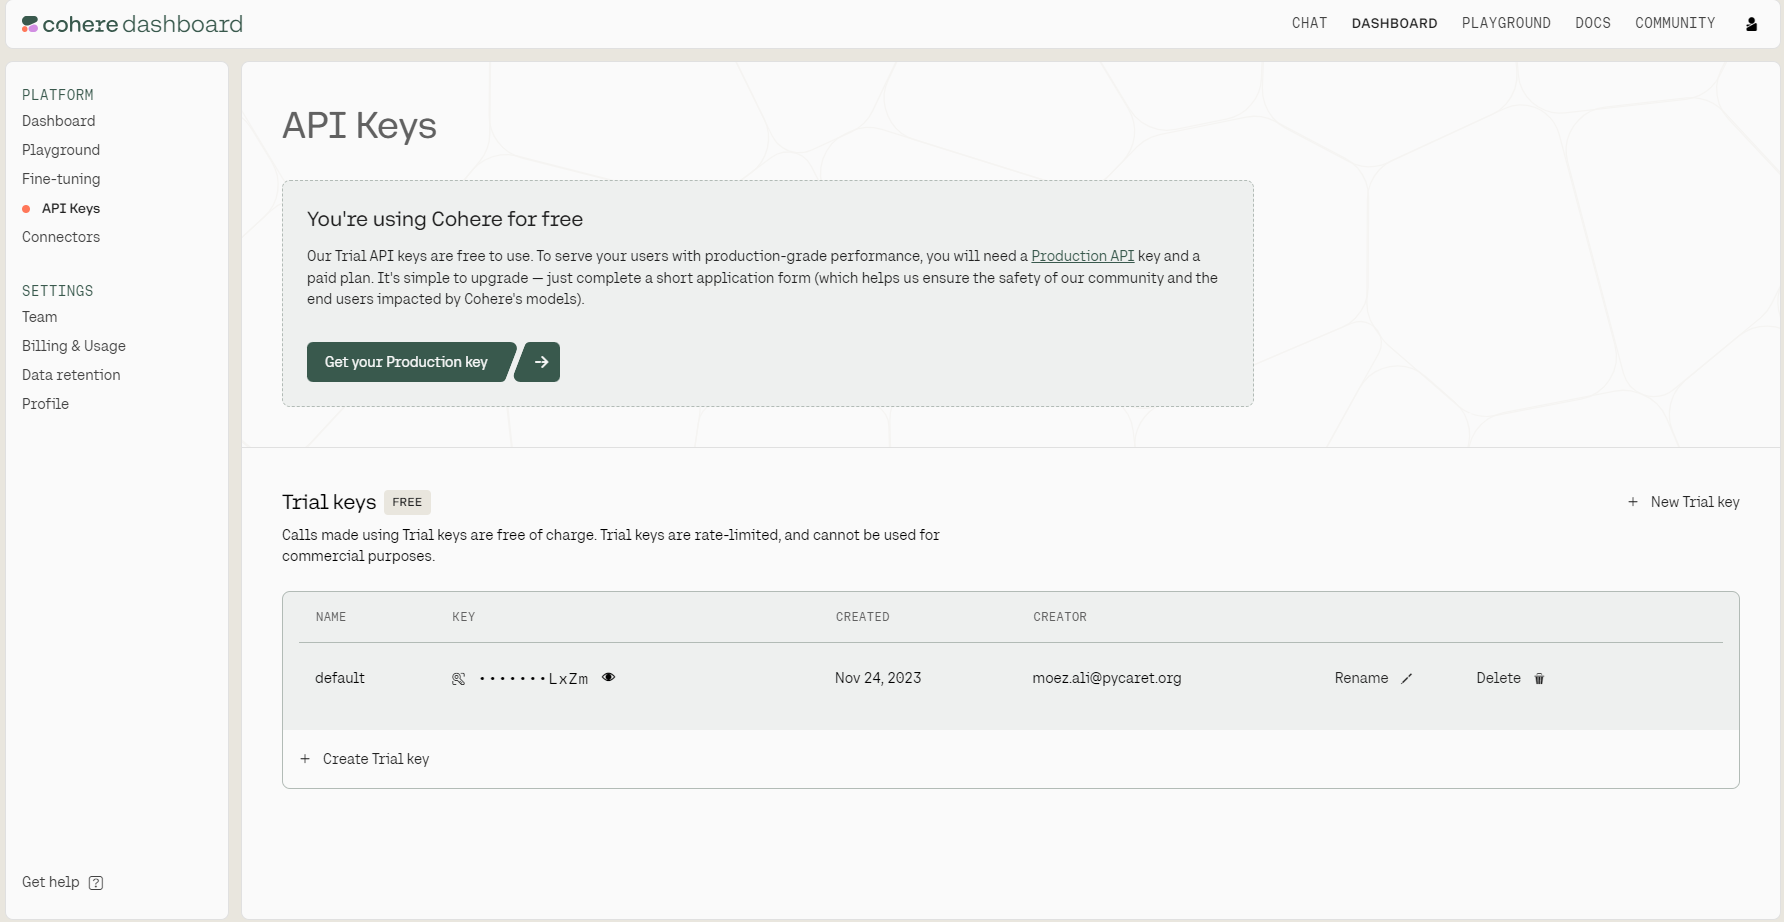
जैसा कि हम नीचे की छवि में देख सकते हैं, API कुंजियों के दो प्रकार होते हैं: प्रोडक्शन और ट्रायल। इस ट्यूटोरियल के उद्देश्य से, हमें केवल एक ट्रायल कुंजी चाहिए। हम कुंजी के बगल में कॉपी आइकन पर क्लिक करके इसे कॉपी कर सकते हैं।
अब जबकि हमारे पास cohere लाइब्रेरी इंस्टॉल है और हमारी API कुंजी भी, हम एक API कॉल कर सकते हैं। नीचे दिए गए कोड में, हम:
cohere लाइब्रेरी इम्पोर्ट करते हैं।Client ऑब्जेक्ट बनाते हैं।co.chat() का उपयोग करके मॉडल को कॉल करते हैं।import cohere
co = cohere.Client('your_token_here')
message = "What is Machine Learning?"
response = co.chat(
message=message,
model="command",
temperature=0.3
)
answer = response.text
print(answer)Machine learning is a branch of computer science that focuses on developing algorithms and models that enable computers to learn and make predictions or decisions without being explicitly programmed. It is a key component of artificial intelligence (AI).
Machine Learning allows systems to identify patterns in data, uncover insights, and improve processes through iterative learning. Instead of writing explicit programs, ML enables the creation of models that can analyze data, identify patterns, and predict outcomes. These models are refined and optimized through a process known as training, which involves feeding the models annotated examples or real-world data.
(...)पहले, हमने response.text का उपयोग करके उत्तर प्राप्त किया था। लेकिन रिस्पॉन्स ऑब्जेक्ट में और भी जानकारी होती है, और हम इसे response.dict() का उपयोग करके एक्सेस कर सकते हैं—यह एक JSON फ़ाइल लौटाएगा जिसमें सभी मेटाडेटा शामिल होंगे, जिनमें रिस्पॉन्स मैसेज भी शामिल है:
response.dict()
{
   "text":"Machine Learning (ML) is a ....",
   "generation_id":"cebf4874-1e3d-429a-8699-8b9639b943dd",
   "finish_reason":"COMPLETE",
   "chat_history":[
      {
         "message":"What is Machine Learning?",
         "role":"USER"
      },
      {
         "message":"Machine Learning (ML) is a ....",
         "role":"CHATBOT"
      }
   ],
   "meta":{
      "api_version":{
         "version":"1"
      },
      "billed_units":{
         "input_tokens":56,
         "output_tokens":252
      },
      "tokens":{
         "input_tokens":67,
         "output_tokens":252
      }
   },
   "response_id":"df34a5f8-f1cd-407f-b1b5-5971aa12ae2a"
}
आइए response ऑब्जेक्ट के प्रत्येक फ़ील्ड को समझें:
text: मॉडल द्वारा जनरेट किया गया संदेश।generation_id: जनरेट किए गए उत्तर से जुड़ी ID, जिसका उपयोग Feedback API एंडपॉइंट के साथ अच्छे उत्तरों को हाइलाइट करने और कमजोर उत्तरों की रिपोर्ट करने के लिए किया जा सकता है।finish_reason: यह बताता है कि जनरेशन क्यों समाप्त हुई और यह निम्न में से एक हो सकता है:COMPLETE: मॉडल ने सफलतापूर्वक संदेश जनरेट करना समाप्त कर दिया।MAX_TOKENS: जनरेशन पूरी होने से पहले मॉडल की कॉन्टेक्स्ट सीमा तक पहुँच गई।chat_history: संवाद का चैट-लॉग फ़ॉर्मेट में प्रस्तुत इतिहास।meta: टोकन काउंट, बिलिंग आदि की जानकारी।response_id: जहाँ generation_id टेक्स्ट जनरेशन के एकल प्रयास पर केंद्रित है, वहीं response_id पूरे रिस्पॉन्स ऑब्जेक्ट की पहचान करता है जिसमें वह जनरेटेड टेक्स्ट और अन्य प्रासंगिक डेटा शामिल होता है।मान लीजिए आप एक चैटबॉट विकसित कर रहे हैं जो उपयोगकर्ता की क्वेरीज़ का उत्तर देता है। पिछली बातचीत का संदर्भ होने से भाषा मॉडल अधिक प्रासंगिक उत्तर दे सकता है।
मल्टी-टर्न बातचीत में, पिछली इंटरैक्शन्स का संदर्भ बनाए रखना सुसंगत और प्रासंगिक प्रतिक्रियाएँ जनरेट करने के लिए आवश्यक है। Cohere का API इसे chat_history पैरामीटर के माध्यम से चैट इतिहास शामिल करने देकर संभव बनाता है।
यह मॉडल को बातचीत के प्रवाह को समझने और पहले के आदान-प्रदान के आधार पर उचित रूप से प्रतिक्रिया देने में मदद करता है। आइए एक उदाहरण देखें।
message = "How is this related to Artificial Intelligence?"


response = co.chat(
  model="command-r-plus",
  chat_history=[
    {"role": "USER", "text": "What is Large Language Model?"},
    {"role": "CHATBOT", "text": "Large Language Model is a type ..."},
  ],
  message="How is this related to Artificial Intelligence?"
)


print(response.text)
Large language models (LLMs) are a key component of artificial intelligence (AI), and their development has played a significant role in advancing the field of AI. Here's how they are related:
1. Language Understanding and Generation: AI aims to create intelligent systems that can understand and respond to human language. LLMs are designed to process and generate human-like language, which is a fundamental aspect of human intelligence. By training on vast amounts of text data, LLMs learn to recognize patterns, syntax, semantics, and context, enabling them to interpret and generate language in a way that is similar to how humans do.
2. Machine Learning and Neural Networks: LLMs are typically built using machine learning techniques, particularly deep learning and neural networks. These are core areas of AI research. Neural networks, inspired by the structure of the human brain, enable LLMs to learn and make connections between different pieces of information. By training on large datasets, LLMs can identify patterns, relationships, and meanings in the data, which is a fundamental aspect of AI.
3. (...)जब उपयोगकर्ता ने पूछा "How is this related to Artificial Intelligence?", तो मॉडल ने समझा कि "this" से तात्पर्य बड़े भाषा मॉडल्स (LLMs) से है। यह chat_history पैरामीटर की वजह से संभव हुआ, जिसने पिछली इंटरैक्शन्स से आवश्यक संदर्भ प्रदान किया। मल्टी-टर्न बातचीत में संदर्भ बनाए रखना प्रासंगिक और सुसंगत प्रतिक्रियाएँ जनरेट करने के लिए अहम है।
यह अच्छी तरह काम करता है, लेकिन ऊपर दिए गए उदाहरण की तरह chat_history को मैन्युअली API को पास करना यथार्थवादी नहीं है। chat_history को हार्डकोड करने के बजाय, हम बातचीत के साथ-साथ इसे डायनेमिक रूप से बना सकते हैं।
इसे हासिल करने के कई तरीके हैं। सबसे सरल तरीका API में conversation_id का उपयोग करना है। आइए एक उदाहरण देखें:
# First message
response = co.chat(
  model="command-r-plus",
  message="What is Large Language Models?",
  conversation_id='newuser1',
)

print(response.text)
Large Language Models (LLMs) are a type of artificial intelligence model specifically designed to process and generate human language. These models are typically based on deep learning and neural network architectures and are trained on vast amounts of text data. Here's an overview of LLMs and their key characteristics:
1. Definition:
- Large Language Models are machine learning models that are trained on large-scale textual data to understand, generate, and manipulate human language. They aim to capture the complexities of language, including syntax, semantics, and context.
2. Training Data:
- LLMs are trained on massive amounts of text data, often consisting of billions or even trillions of words. This training data can come from various sources such as books, articles, websites, social media, and other text-based documents.
3. (...)और अब मॉडल को एक और संदेश देते हैं—ध्यान दें कि conversation_id पहले संदेश के साथ सुसंगत रखा गया है। जब तक conversation_id सुसंगत रहता है, API स्वतः पिछले संदेशों को संदर्भ के रूप में उपयोग करेगा।
# Second message
response = co.chat(
  model="command-r-plus",
  message="How is it related to Artificial Intelligence?",
  conversation_id='newuser1',
)
print(response.text)
Large Language Models (LLMs) are a crucial component and a powerful manifestation of Artificial Intelligence (AI). Here's how LLMs are closely related to AI:
1. AI Foundation:
- Artificial Intelligence is a broad field that encompasses the development of computer systems capable of performing tasks typically associated with human intelligence. This includes areas like machine learning, natural language processing, computer vision, robotics, and decision-making.
- LLMs fall under the umbrella of AI as they are designed to understand, generate, and respond to human language, which is a fundamental aspect of human intelligence.
2. Machine Learning:
- Machine learning is a subset of AI that focuses on the development of algorithms and models that enable computers to learn and improve over time, based on data and experience, without being explicitly programmed.
- LLMs are built using machine learning techniques, particularly deep learning and neural networks. They are trained on large datasets to identify patterns, understand context, and generate responses, demonstrating their ability to learn and improve from data.
3. (...)यदि आप बातचीत जारी रखना चाहते हैं, तो हमें conversation_id को सुसंगत रखना होगा, और यह स्वतः सभी पिछली बातचीत को याद रखेगा। conversation_id का उपयोग chat_history के साथ मिलाकर नहीं किया जाना चाहिए। ये परस्पर अनन्य हैं।
यदि आप और जानना चाहते हैं, तो Cohere का प्रलेखन देखें।
आइए Cohere के सबसे उन्नत मॉडल की कीमत को देखें और उसकी तुलना OpenAI और Anthropic के शीर्ष स्वामित्व वाले भाषा मॉडल्स से करें (हम प्रत्येक कंपनी के सबसे शक्तिशाली मॉडल पर फोकस करेंगे)। मई 2024 तक, कीमतें इस प्रकार हैं:
|
मॉडल |
$ / मिलियन इनपुट टोकन |
$ / मिलियन आउटपुट टोकन |
|
Cohere Command R+ |
$3.00 |
$15.00 |
|
Anthropic Claude Opus |
$15.00 |
$75.00 |
|
OpenAI GPT-4 Turbo |
$10.00 |
$30.00 |
हालाँकि Cohere Command R+ आकर्षक लागत लाभ प्रदान करता है, इन मॉडल्स के व्यापक प्रदर्शन स्पेक्ट्रम पर विचार करना महत्वपूर्ण है। Anthropic Claude Opus और GPT-4 Turbo ने बेंचमार्क्स में लगातार अधिक मजबूत प्रदर्शन दिखाया है।
चाहे आप अपने एप्लिकेशन्स को बेहतर बनाने के इच्छुक डेवलपर हों या अत्याधुनिक एआई को शामिल करने का लक्ष्य रखने वाला व्यवसाय, Cohere ऐसे बड़े मॉडल्स प्रदान करता है जो GPT और Claude जैसे अन्य फाउंडेशनल मॉडल्स के मुकाबले प्रतिस्पर्धी हैं—और वह भी काफी कम कीमत पर।
इस ब्लॉग में, हमने जाना कि Cohere क्या है और इसे Playground या API के माध्यम से कैसे एक्सेस करें।
यदि आप विषय को और खंगालना चाहते हैं, तो यह कोड-अलॉन्ग देखें: Using Large Language Models with the Cohere API।
यदि आप और गहराई में जाकर एंड-टू-एंड एआई एप्लिकेशन्स विकसित करना सीखना चाहते हैं, तो देखें Developing LLM Applications with LangChain।
APIs और LLMs पर और जानें—इन कोर्सेज़ के साथ!
कोर्स
कोर्स
कोर्स
