Last chance! 50% off DataCamp Premium
Sale ends in
In this tutorial, we'll walk through a small Java module that exposes custom tools, stores notes as JSON in Oracle AI Database, and retrieves them with full-text search.
If you're building AI agents, short-term chat history is usually not enough. Real assistants often need a small amount of durable memory so they can store important facts and retrieve them later.
This tutorial shows how to build that pattern with a minimal Java module. You'll use LangChain4j tools, a simple agent interface, and Oracle AI Database as the backing store. Instead of adding embeddings or a full retrieval pipeline, this sample keeps the design intentionally small: notes are saved as JSON documents and searched with Oracle Text.
By the end, you will understand how the module wires together:
LangChain4j agent interface@Tool methodsJDBC repository for durable note storageLangChain4j lets you expose ordinary Java methods as tools that a model can call when it needs external capabilities. In this module, those capabilities are memory-oriented:
searchMemories(String question) finds relevant saved notesstoreMemory(String note) writes a new durable noteThat is different from standard chat history that stores chat messages in an in-memory context window.
Persistent tool-based memory decides when it needs to search or store notes, and the underlying data lives in a database.
This pattern is useful when you want an agent to remember facts like incident notes, runbook reminders, or follow-up actions without building a larger retrieval system too early.
Persistent, database-backed memory can also be accessed concurrently by one or more agents without data contention.
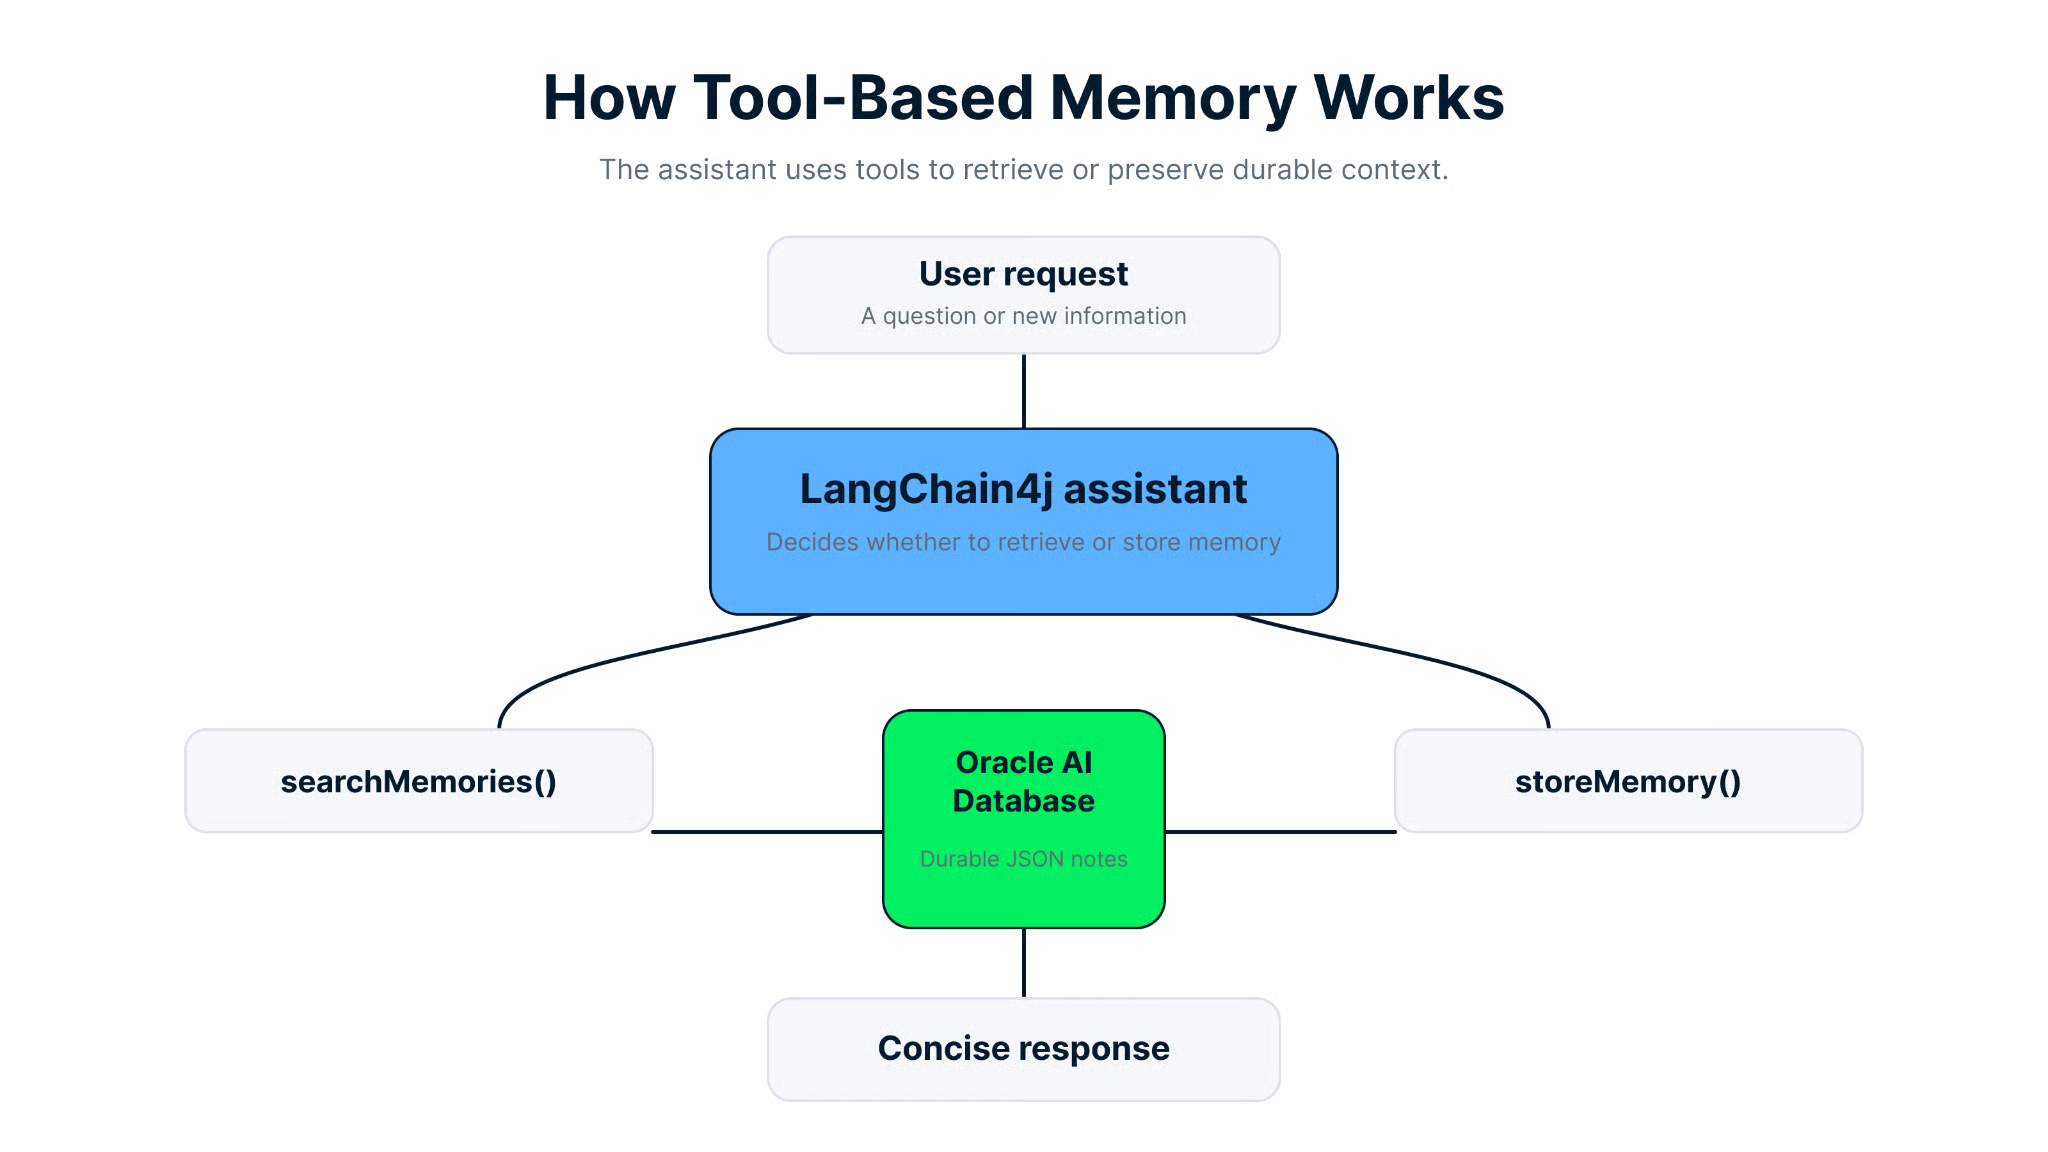
Tool-based memory lets the assistant retrieve existing notes or store new notes in a durable database.
This sample is small, but it demonstrates several important agent design ideas.
The MemoryTools class exposes two methods annotated with @Tool. That means LangChain4j can make them available to the agent without extra wrapper code.
// Retrieve relevant notes and format them for the assistant.
 @Tool(
     	"Search saved memory notes when earlier context might help answer the user."
 )
 public String searchMemories(String question) {
 	List<MemoryRepository.Note> matches = repository.search(question, 3);
 	if (matches.isEmpty()) {
     	return "No saved memory matched that question.";
 	}

 	StringBuilder builder = new StringBuilder();
 	for (int i = 0; i < matches.size(); i++) {
     	MemoryRepository.Note note = matches.get(i);
     	builder.append(i + 1)
             	.append(". [M")
             	.append(note.id())
             	.append("] ")
             	.append(note.text());
     	if (i + 1 < matches.size()) {
         	builder.append('\n');
     	}
 	}
 	return builder.toString();
 }
This method does two useful things. It delegates retrieval to the repository, and it formats the results in a model-friendly way such as [M12] some note text.
That makes the tool output easy for the agent to cite in its final response.
Notes are stored in an agent_memories table as native JSON documents. Each row contains:
idmemory_doccreated_at timestampThe module initializes the schema automatically:
-- Create a JSON-backed table for durable agent notes.
 CREATE TABLE IF NOT EXISTS agent_memories (
 	id NUMBER GENERATED ALWAYS AS IDENTITY PRIMARY KEY,
 	memory_doc JSON NOT NULL,
 	created_at TIMESTAMP DEFAULT CURRENT_TIMESTAMP NOT NULL
 )
This keeps the storage model simple while still giving you structured data and database-managed durability.
The repository does not generate embeddings. Instead, it extracts keywords from the user’s question, removes stop words, builds an Oracle Text expression with ACCUM, and searches the JSON document content with json_textcontains.
That is especially helpful for identifiers and operational terms like CHG2145, where exact or near-exact token matching often matters more than semantic similarity.
The Application class creates the repository, initializes the schema, seeds a few notes, constructs the chat model, and starts a terminal loop. That makes the example easy to run and easy to adapt into another service later.
Before running the module, make sure your local environment matches the project’s requirements.
You need:
OPENAI_API_KEY environment variableThe Maven project depends on:
langchain4jlangchain4j-open-aiojdbc11Testcontainers for integration testsSet your OpenAI API key first:
# Set the API key used by the chat model.
 export OPENAI_API_KEY=<your key>
Then run the app from the project directory:
# Compile and run the sample with the database connection details.
 mvn compile exec:java \
     -Dexec.args="jdbc:oracle:thin:@localhost:1521/freepdb1 testuser testpwd"
The application expects exactly three arguments:
1. JDBC URL
2. Database username
3. Database password
If those are missing, Application.main() throws an IllegalArgumentException. If OPENAI_API_KEY is missing, it throws an IllegalStateException.
When the app starts, it:
1. Creates a MemoryRepository
2. Initializes the database schema
3. Seeds three sample notes if the table is empty
4. Builds an OpenAiChatModel
5. Wires the model and tools into AiServices
6. Starts a CLI loop that reads user input until you type exit
That means you can try memory retrieval immediately without manually inserting rows first.
Now let’s walk through the module in the same order the application uses it.
LangChain4j uses a Java interface to describe the agent contract. In this project, that interface is MemoryAssistant.
// Define the interface that receives each user message.
 public interface MemoryAssistant {

 	@SystemMessage("""
         	You are a simple assistant with access to durable memory notes.
         	Use searchMemories when earlier notes might help answer the user.
         	If the user explicitly asks you to remember something for later, call storeMemory.
         	Keep answers concise.
         	""")
 	@UserMessage("{{message}}")
 	String chat(@V("message") String message);
 }
The important part is the system message. It tells the model when to use each tool:
That is a good example of lightweight tool policy. The prompt is short, but it is specific enough to guide tool selection.
The agent does not talk to the repository directly. Instead, it calls the MemoryTools layer.
Here is the storage method:
// Save a note and return its generated memory identifier.
 @Tool(
     	"Store a new memory note when the user asks you to remember something "
             	+ "important for later."
 )
 public String storeMemory(String note) {
 	long id = repository.store(note);
 	return "Stored memory M" + id + ".";
 }
This is intentionally compact. A user might say:
Remember that the next shift should verify the checkout retry queue stays below 50.If the model follows the system prompt correctly, it calls storeMemory(), the repository persists the note, and the tool returns something like:
Stored memory M4.Later, the user can ask:
What should the next shift verify?At that point, the agent can call searchMemories() and use the returned note to answer.
The repository is where most of the durable memory logic lives. It is still plain JDBC, which makes the design easy to inspect.
At a high level, MemoryRepository is responsible for:
Oracle Text searchThe insertion path normalizes and validates note text before storing it:
// Normalize the note, store its JSON document, and return the generated ID.
 public long store(String note) {
 	String normalized = normalizeNote(note);
 	Instant createdAt = Instant.now();
 	try (
         	Connection connection = dataSource.getConnection();
         	PreparedStatement statement = connection.prepareStatement(
                 	INSERT_SQL,
                 	new String[]{"id"})
 	) {
     	statement.setObject(
             	1,
                 toJsonDocument(normalized, createdAt),
             	OracleTypes.JSON
     	);
     	statement.setTimestamp(2, Timestamp.from(createdAt));
     	statement.executeUpdate();
     	try (ResultSet keys = statement.getGeneratedKeys()) {
         	if (keys.next()) {
             	return keys.getLong(1);
         	}
     	}
     	throw new IllegalStateException(
             	"No generated id returned for stored memory."
     	);
 	} catch (SQLException e) {
     	throw new RuntimeException("Failed to store memory", e);
 	}
 }
The JSON document itself looks like this:
{
 	"noteText": "Runbook note: use section 3 to validate checkout recovery after a rollback.",
 	"createdAt": "2026-04-27T17:00:00Z"
 }
This structure is simple, but it is enough to support both persistence and text search.
The most interesting part of the repository is the search() method:
// Search by extracted keywords or fall back to recent notes.
 public List<Note> search(String question, int maxResults) {
 	List<String> keywords = extractKeywords(question);
 	if (keywords.isEmpty()) {
     	return findRecent(maxResults);
 	}
 	return textSearch(buildTextExpression(keywords), maxResults);
 }
This method follows a practical flow:
1. Tokenize the user question
2. Lowercase the tokens
3. Remove stop words such as the, what, and remember
4. Keep meaningful short tokens when they include digits
5. Build an Oracle Text expression with ACCUM
6. Search the JSON data with json_textcontains
That “digits are allowed” detail is important. It helps terms like CHG2145 survive keyword extraction, which is exactly the kind of identifier-heavy lookup many operational agents need.
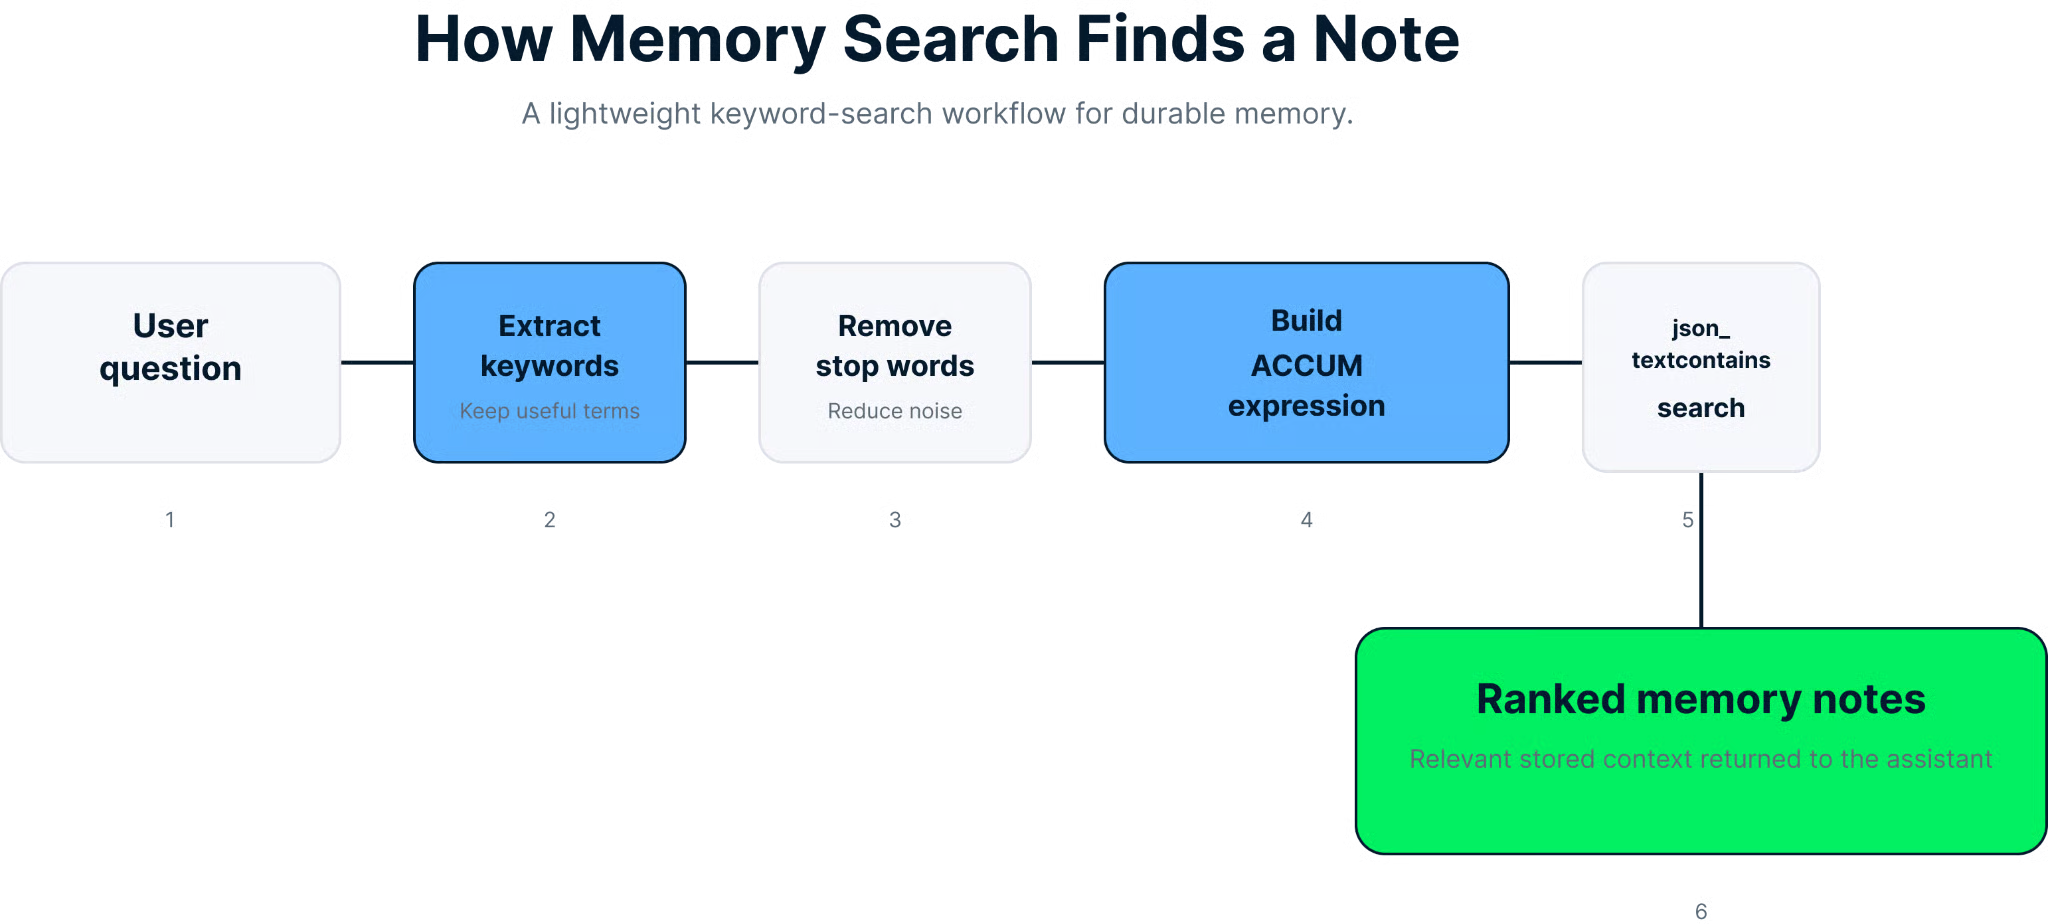
The search workflow converts a question into a keyword expression and returns ranked memory notes.
The SQL search query is:
-- Rank matching notes by Oracle Text relevance.
 SELECT id,
    	JSON_VALUE(
        	memory_doc,
        	'$.noteText' RETURNING VARCHAR2(2000 CHAR)
    	) AS note_text,
    	created_at,
    	SCORE(1) AS text_score
 FROM agent_memories
 WHERE JSON_TEXTCONTAINS(memory_doc, '$', ?, 1)
 ORDER BY SCORE(1) DESC, id DESC
 FETCH FIRST ? ROWS ONLY
If the question does not yield useful keywords, the repository falls back to recent notes. That gives the agent a reasonable default instead of returning an empty search too early.
The application ties the pieces together with AiServices.builder():
// Build the chat model, then attach the memory tools to the assistant.
 ChatModel chatModel = OpenAiChatModel.builder()
     	.apiKey(apiKey)
         .modelName("gpt-5-nano")
     	.build();

 MemoryAssistant assistant = AiServices.builder(MemoryAssistant.class)
     	.chatModel(chatModel)
     	.tools(new MemoryTools(repository))
     	.build();
This is the full pattern in one place:
After that, the console loop simply passes user input into assistant.chat(input).
The application prints a few starter prompts:
What do we know about CHG2145?
 Remember that the next shift should verify the checkout retry queue stays below 50.
 What should the next shift verify?
These prompts are useful because they exercise the full memory lifecycle:
This module is intentionally narrow, which is a strength when you are learning the pattern. Still, there are a few practical details to keep in mind.
The system prompt tells the model to store memory only when the user explicitly asks for it. That helps reduce accidental writes. If you broaden the prompt carelessly, the model may start persisting low-value notes.
This repository is best for short operational notes, reminders, and identifiers. It is not yet a full retrieval-augmented generation system with embeddings, chunking, hybrid search, or ranking.
For strings like incident IDs, ticket numbers, and change request references, keyword-oriented retrieval is often a better starting point than semantic search. This sample reflects that tradeoff clearly.
The project’s tests are integration tests powered by Testcontainers. If Docker is not available, mvn test will fail before the repository logic runs. That is an environment issue, not necessarily an application bug.
Run the tests with:
# Run the integration tests.
 mvn test
The tests cover two important behaviors:
A common mistake in agent projects is adding vector storage, conversation history, summarization, and retrieval policies all at once. This sample shows a better progression:
1. Define a concrete memory use case
2. Expose explicit tools
3. Back those tools with durable storage
4. Verify the retrieval behavior
5. Only then consider more advanced memory patterns
If you want to keep building agent skills after this tutorial, these DataCamp resources are a good next step:
You have now seen how to build a small but useful memory-enabled agent with LangChain4j, Java, and Oracle AI Database. The core idea is simple: give the model explicit memory tools, store notes durably as JSON, and retrieve them with a straightforward search strategy.
This design is a strong foundation because it is easy to understand and easy to extend. Once this pattern is working, you can add better filtering, richer note schemas, user scoping, or even vector search if the use case demands it.
If you want to keep learning about agent design, the next good step is to compare this tool-based memory pattern with broader agent frameworks and orchestration workflows. In particular, it is worth exploring how explicit tools, retrieval patterns, and multi-step agents fit together in larger AI systems.
Top DataCamp Courses
Course
Course
Track
Tutorial
Victor Martin
10 min
Tutorial
Aashi Dutt
12 min
Tutorial
Bexruz (Bex) Tuychiev
14 min
Tutorial
Andrea Valenzuela
15 min
Tutorial
Vaibhav Mehra
code-along
Casius Sibanda Lee