
Last chance! 50% off DataCamp Premium
Sale ends in
DeepSeek R1 के लॉन्च के बाद, OpenAI ने अपने अत्याधुनिक रीज़निंग मॉडल o3-mini के साथ जवाब दिया है। यह नया मॉडल अपने पूर्ववर्ती o1 मॉडल की तुलना में छोटा, तेज़ और अधिक कुशल होने के लिए डिज़ाइन किया गया है, जबकि कोडिंग, STEM, और तार्किक समस्या-समाधान से जुड़े कार्यों में उत्कृष्टता प्राप्त करता है।
OpenAI ने इस मॉडल को सभी उपयोगकर्ताओं के लिए निःशुल्क उपलब्ध कराया है, जिनमें ChatGPT और अन्य प्लेटफ़ॉर्म के उपयोगकर्ता भी शामिल हैं, जिससे उन्नत रीज़निंग क्षमताएँ पहले से कहीं अधिक सुलभ हो गई हैं।
o3-mini के बारे में अधिक जानने के लिए आप इस ब्लॉग पोस्ट को देख सकते हैं, OpenAI’s O3: Features, O1 Comparison, Release Date & More.
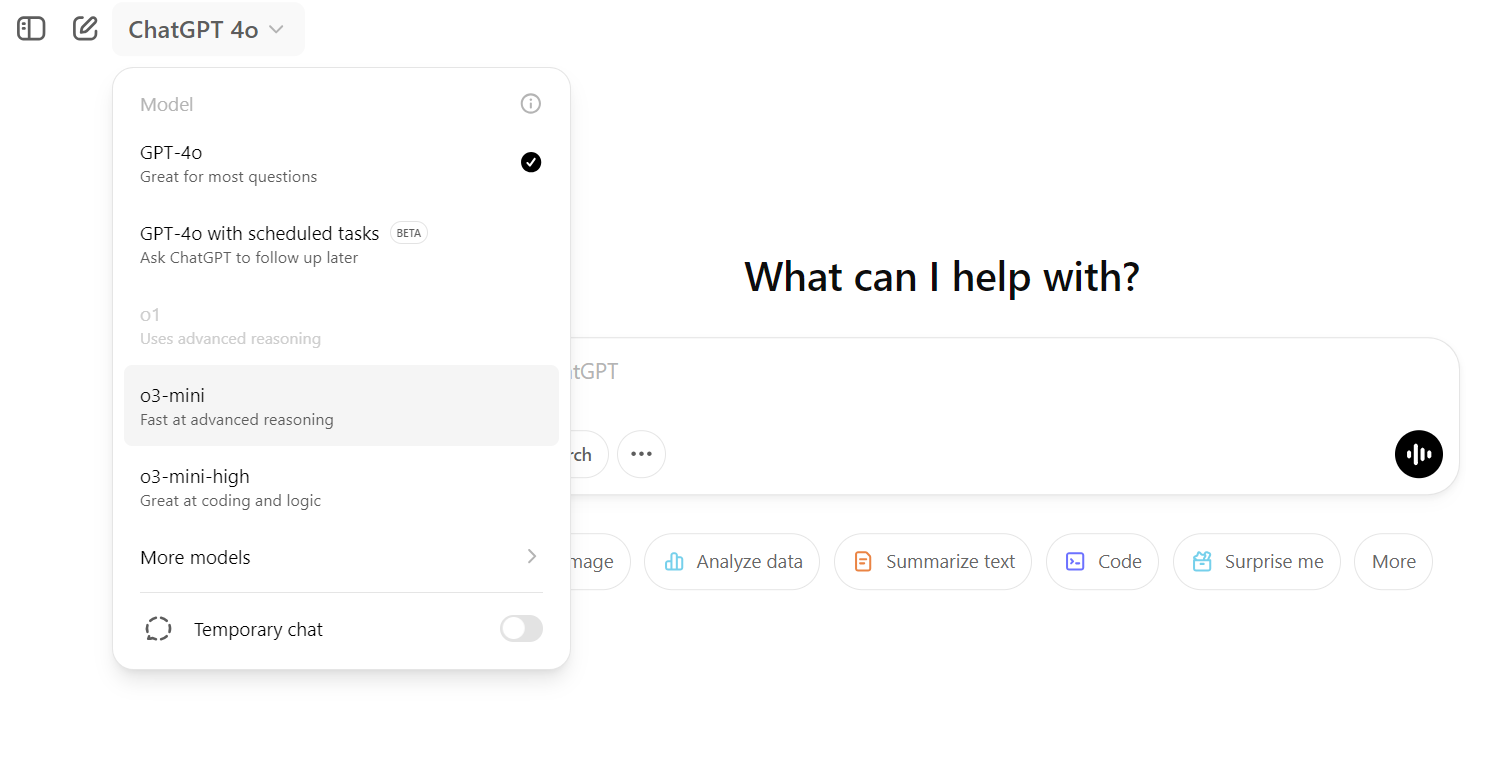
स्रोत: ChatGPT
इस ट्यूटोरियल में, हम o3-mini मॉडल की तकनीकी क्षमताओं का अन्वेषण करेंगे। विशेष रूप से, हम इसकी जटिल तकनीकी कार्यों को संभालने की क्षमता, सटीक कोड जनरेट करने, और एक सही मशीन लर्निंग मॉडल बनाने, परीक्षण करने और डिप्लॉय करने के लिए स्पष्ट निर्देश प्रदान करने की क्षमता का परीक्षण करेंगे। अंत तक, हमारा लक्ष्य यह निर्धारित करना है कि क्या o3-mini तकनीकी और तार्किक समस्या-समाधान कार्यों के लिए एक अत्याधुनिक रीज़निंग मॉडल के रूप में अपनी अपेक्षाओं पर खरा उतरता है।
छवि: लेखक द्वारा
हम o3-mini से Placement Prediction डेटासेट का उपयोग करके एक मशीन लर्निंग एप्लिकेशन बनाने के लिए कहेंगे, जो यह निर्धारित कर सके कि कोई छात्र जॉब प्लेसमेंट के लिए पात्र है या नहीं। प्लानिंग से लेकर समाधान को डिप्लॉय करने तक, हम ChatGPT पर o3-mini मॉडल से सहायता लेंगे।
प्रोजेक्ट प्लानिंग चरण में, हम o3-mini मॉडल को सभी आवश्यक जानकारी देंगे और अपने लक्ष्यों का खाका प्रस्तुत करेंगे। हम इसे Placement Prediction एप्लिकेशन के निर्माण, प्रशिक्षण, और डिप्लॉयमेंट के लिए सभी ज़रूरी फ़ोल्डर और फ़ाइलें बनाने के लिए कहेंगे।
विशेष रूप से, हम:
प्रॉम्प्ट इस प्रकार है:
“I want to build a machine learning project to predict whether a student will be placed or not based on their academic and extracurricular data. The dataset contains the following columns:

- **StudentID**: Unique identifier for each student.

- **CGPA**: The overall grades achieved by the student.

- **Internships**: Number of internships a student has completed.

- **Projects**: Number of projects a student has completed.

- **Workshops/Certifications**: Indicates whether the student has attended workshops or completed certifications to upskill themselves.

- **AptitudeTestScore**: Score achieved in an aptitude test, which evaluates quantitative and logical thinking.

- **SoftSkillRating**: A rating of the student’s communication and interpersonal skills.

- **ExtraCurricularActivities**: Indicates whether the student is active in extracurricular activities (Yes/No).

- **PlacementTraining**: Indicates whether the student has undergone placement training (Yes/No).

- **SSC and HSC**: Senior Secondary and Higher Secondary marks.

- **PlacementStatus**: The target column, which has two classes: "Placed" and "Not Placed."

Here is a sample dataset row:

StudentID,CGPA,Internships,Projects,Workshops/Certifications,AptitudeTestScore,SoftSkillsRating,ExtracurricularActivities,PlacementTraining,SSC_Marks,HSC_Marks,PlacementStatus

1,7.5,1,1,1,65,4.4,No,No,61,79,NotPlaced

I need help creating a structured project with the following components:

1. **Data Analysis**: Perform exploratory data analysis (EDA) to understand the dataset, visualize trends, and identify correlations between features and the target variable.

2. **Model Building**: Create a machine learning pipeline to preprocess the data and train a model to predict the placement status.

3. **Experiment Tracking**: Set up a system to track experiments, including model performance metrics, hyperparameters, and results.

4. **Model Training**: Train the model using appropriate algorithms and evaluate its performance using metrics like accuracy, precision, recall, and F1-score.

5. **Hyperparameter Tuning**: Optimize the model’s performance by tuning hyperparameters using techniques like grid search or random search.

6. **Model Inference Application**: Build an application (e.g., a web app or API) to allow users to input student data and get predictions on placement status.

7. **Dockerfile for Containerization**: Create a Dockerfile to containerize the application for easy deployment.

8. **Cloud Deployment**: Deploy the application on a cloud platform (e.g., AWS, Azure, or Google Cloud) to make it accessible online.

9. **Accessing the Model**: Provide a way to access the deployed model via an API or web interface.

Please provide the following:

- A folder structure for organizing the project files. (Also provide bash command for creating the folders and files.)

- Python scripts or code snippets for each of the above components.

- Suggestions for tools and libraries to use (e.g., pandas, scikit-learn, Flask, Docker, etc.).

- Guidance on setting up experiment tracking (using MLflow).

- Steps for deploying the model on a Hugging Face Space.”
बदले में, आपको प्रोजेक्ट संरचना और सब कुछ शून्य से कैसे बनाया जाए, इस पर एक विस्तृत उत्तर प्राप्त होगा।
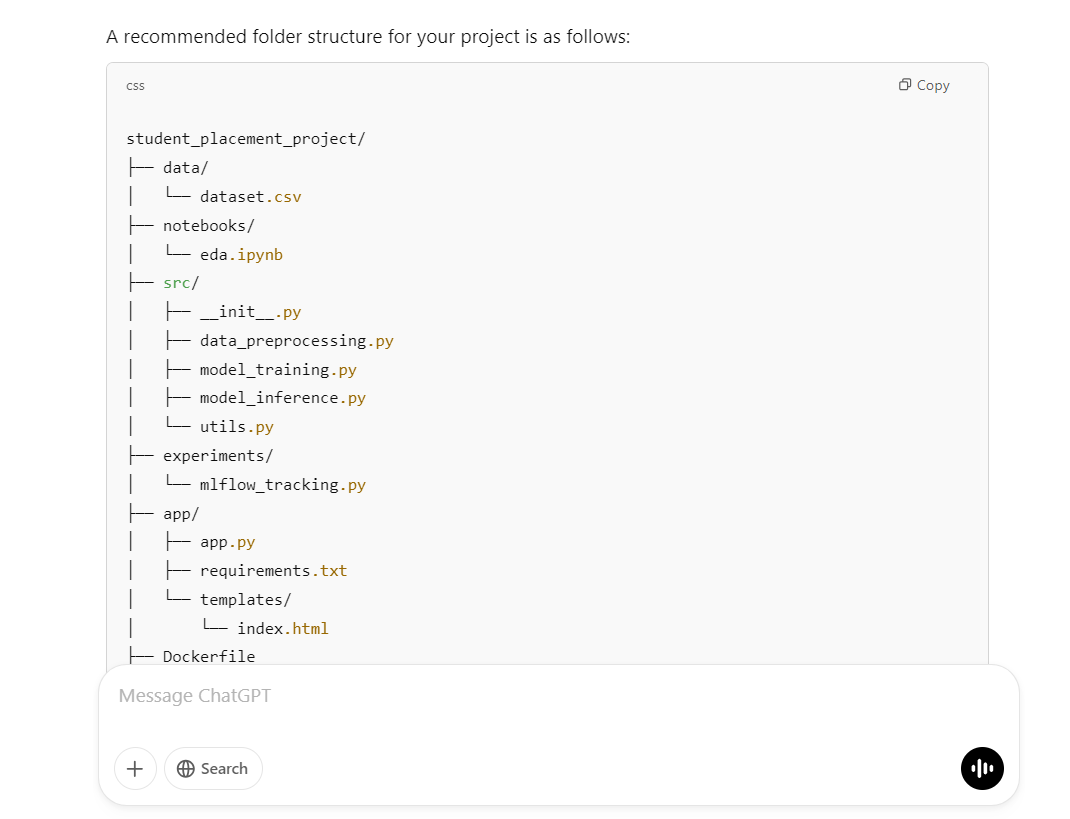
दिया गया स्क्रिप्ट प्रोजेक्ट डायरेक्टरी, फ़ोल्डर्स और सभी आवश्यक फ़ाइलें बनाएगा:
mkdir -p student_placement_project/{data,notebooks,src,experiments,app/templates}
touch student_placement_project/data/dataset.csv \
      student_placement_project/notebooks/eda.ipynb \
      student_placement_project/src/{__init__.py,data_preprocessing.py,model_training.py,model_inference.py,utils.py} \
      student_placement_project/experiments/mlflow_tracking.py \
      student_placement_project/app/{app.py,requirements.txt} \
      student_placement_project/app/templates/index.html \
      student_placement_project/{Dockerfile,requirements.txt,README.md}
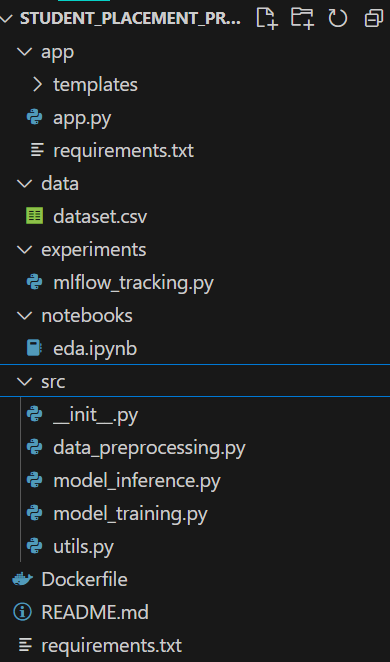
जैसा कि हम देख सकते हैं, इस स्क्रिप्ट ने हमारे लिए सभी आवश्यक कार्य पूरे कर दिए हैं।
प्रतिक्रिया में Jupyter नोटबुक फ़ाइल के लिए कोड दिया गया है। आपको बस कोड को एक-एक करके पेस्ट करना है और आउटपुट देखने के लिए चलाना है।
# notebooks/eda.ipynb
import pandas as pd
import seaborn as sns
import matplotlib.pyplot as plt
import numpy as np

# Load dataset
df = pd.read_csv('../data/dataset.csv')

# Basic info and descriptive statistics
print(df.info())
print(df.describe())

# Visualize distributions
sns.histplot(df['CGPA'], bins=20, kde=True)
plt.title('Distribution of CGPA')
plt.show()

# Correlation matrix
plt.figure(figsize=(10, 8))

# Compute correlation matrix only on numeric columns
numeric_df = df.select_dtypes(include=[np.number])
plt.figure(figsize=(10, 8))
corr = numeric_df.corr()
sns.heatmap(corr, annot=True, cmap="coolwarm")
plt.title("Feature Correlation Matrix")


# Count plot for PlacementStatus
sns.countplot(x='PlacementStatus', data=df)
plt.title('Placement Status Count')
plt.show()
यह कुछ ऐसा दिखता है। सभी डेटा एनालिटिक्स और ग्राफ़ एक ही फ़ाइल में हैं ताकि कोई भी समीक्षा कर सके।
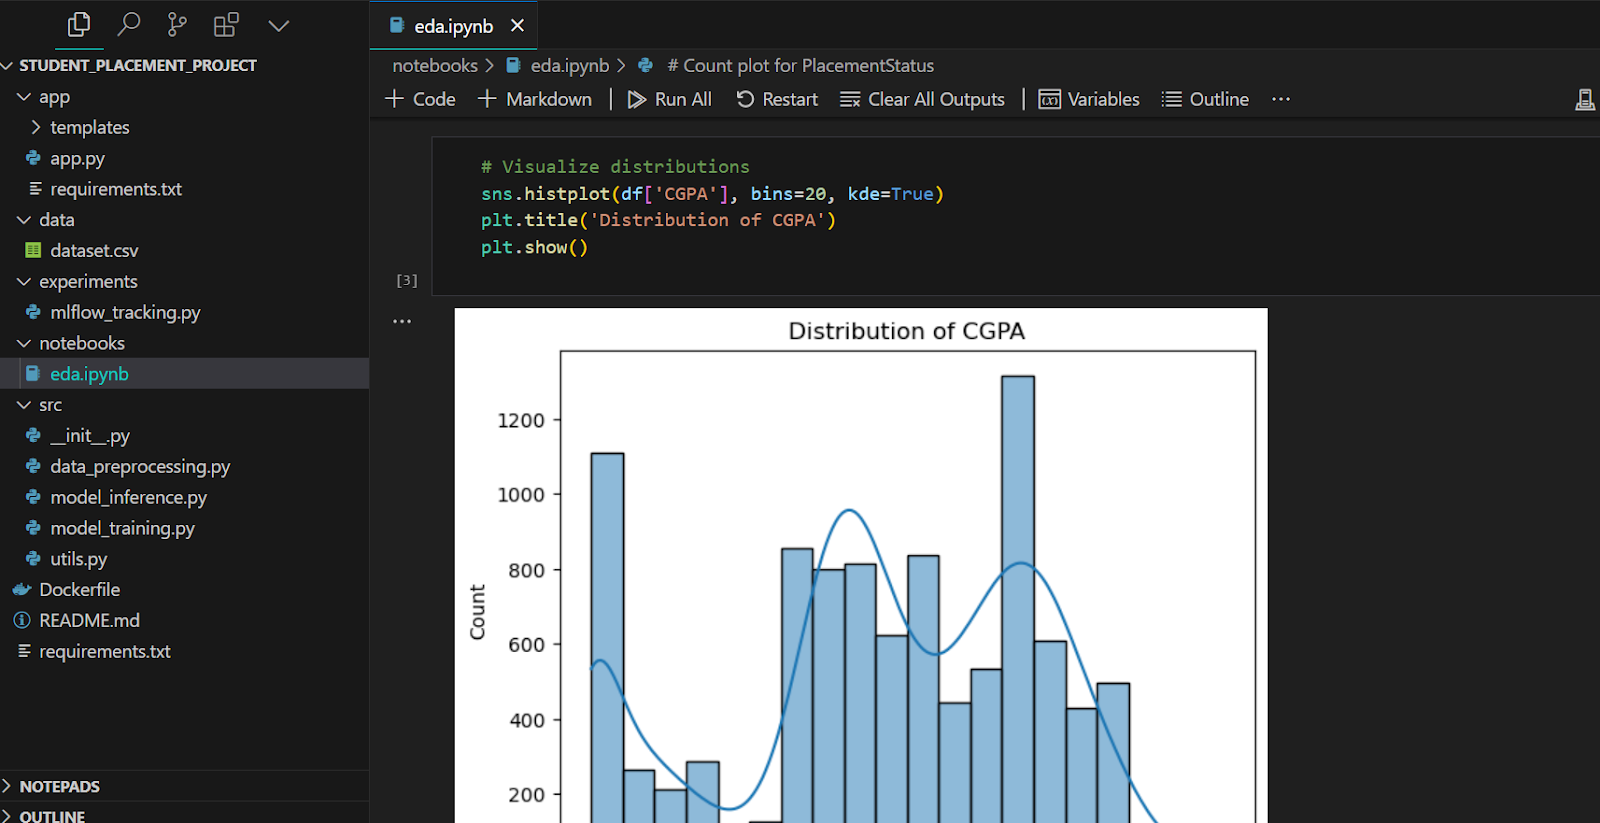
अगला, हम डेटा प्रीप्रोसेसिंग फ़ाइल बनाएंगे। कुछ मामूली बदलावों के अलावा, यह कोड सुचारू रूप से काम करता है।
# src/data_preprocessing.py
import pandas as pd
from sklearn.model_selection import train_test_split
from sklearn.preprocessing import StandardScaler


def load_and_preprocess_data(filepath):
    df = pd.read_csv(filepath)

    # Convert categorical columns
    df["ExtracurricularActivities"] = df["ExtracurricularActivities"].map(
        {"Yes": 1, "No": 0}
    )
    df["PlacementTraining"] = df["PlacementTraining"].map({"Yes": 1, "No": 0})
    df["Workshops/Certifications"] = df["Workshops/Certifications"].astype(
        int
    )  # assuming it's already 0/1

    # Convert target column to binary
    df["PlacementStatus"] = df["PlacementStatus"].map({"Placed": 1, "NotPlaced": 0})

    # Feature selection (excluding StudentID)
    X = df.drop(["StudentID", "PlacementStatus"], axis=1)
    y = df["PlacementStatus"]

    # Split dataset
    X_train, X_test, y_train, y_test = train_test_split(
        X, y, test_size=0.2, random_state=42
    )

    # Scaling numeric features (optional)
    scaler = StandardScaler()
    X_train_scaled = scaler.fit_transform(X_train)
    X_test_scaled = scaler.transform(X_test)

return X_train_scaled, X_test_scaled, y_train, y_test, scalerट्रेनिंग स्क्रिप्ट डेटा प्रोसेसिंग फ़ंक्शन को इम्पोर्ट करती है, पहले डेटा को प्रोसेस करती है, और फिर रैंडम फ़ॉरेस्ट मॉडल को प्रशिक्षित करती है। अंत में, यह मॉडल के प्रदर्शन मेट्रिक्स दिखाती है।
# src/model_training.py
import joblib
from sklearn.ensemble import RandomForestClassifier
from sklearn.metrics import accuracy_score, precision_score, recall_score, f1_score
from data_preprocessing import load_and_preprocess_data


def train_model(data_path):
    X_train, X_test, y_train, y_test, scaler = load_and_preprocess_data(data_path)

    # Initialize and train classifier
    clf = RandomForestClassifier(n_estimators=100, random_state=42)
    clf.fit(X_train, y_train)

    # Predictions and evaluation
    y_pred = clf.predict(X_test)
    metrics = {
        "accuracy": accuracy_score(y_test, y_pred),
        "precision": precision_score(y_test, y_pred),
        "recall": recall_score(y_test, y_pred),
        "f1_score": f1_score(y_test, y_pred),
    }
    print("Model Evaluation Metrics:", metrics)

    # Save model and scaler
    joblib.dump(clf, "model_rf.joblib")
    joblib.dump(scaler, "scaler.joblib")

    return clf, scaler, metrics


if __name__ == "__main__":
    train_model("data/dataset.csv")
78% सटीकता बुरी नहीं है।
$ python .\src\model_training.py

Model Evaluation Metrics: {'accuracy': 0.781, 'precision': 0.7462121212121212, 'recall': 0.7137681159420289, 'f1_score': 0.7296296296296296}
यदि आप इस क्षेत्र के और विषयों के बारे में सीखने के इच्छुक हैं, तो हमारा लोकप्रिय LLM ट्यूटोरियल देखें, Fine-Tuning DeepSeek R1 (Reasoning Model)। यह दुनिया के पहले ओपन-सोर्स रीज़निंग मॉडल को मेडिकल चेन-ऑफ-थॉट डेटासेट पर फाइन-ट्यून करने को कवर करता है ताकि भविष्य के लिए बेहतर AI डॉक्टर विकसित किए जा सकें।
हम Python स्क्रिप्ट्स को अलग फ़ोल्डर में नहीं रखना चाहते। हम mlflow_tracking.py फ़ाइल को src फ़ोल्डर में ले जाएंगे और experiments फ़ोल्डर हटा देंगे। कृपया ध्यान दें कि आपको o3-mini मॉडल से पूछने के बजाय कुछ छोटे बदलाव मैन्युअल रूप से करने होंगे।
# src/mlflow_tracking.py
import mlflow
import mlflow.sklearn
from model_training import train_model


def run_experiment(data_path):
    mlflow.set_experiment("Student_Placement_Prediction")

    with mlflow.start_run():
        # Train the model
        clf, scaler, metrics = train_model(data_path)

        # Log parameters (example)
        mlflow.log_param("model_type", "RandomForest")
        mlflow.log_param("n_estimators", 100)

        # Log metrics
        mlflow.log_metric("accuracy", metrics["accuracy"])
        mlflow.log_metric("precision", metrics["precision"])
        mlflow.log_metric("recall", metrics["recall"])
        mlflow.log_metric("f1_score", metrics["f1_score"])

        # Log the model
        mlflow.sklearn.log_model(clf, "model")

        print("Experiment logged in MLflow.")


if __name__ == "__main__":
    run_experiment("data/dataset.csv")
Python स्क्रिप्ट सुचारू रूप से चली और सारी जानकारी जेनरेट की।
$ python .\src\mlflow_tracking.py
Model Evaluation Metrics: {'accuracy': 0.781, 'precision': 0.7462121212121212, 'recall': 0.7137681159420289, 'f1_score': 0.7296296296296296}
2025/02/17 00:03:34 WARNING mlflow.models.model: Model logged without a signature and input example. Please set `input_example` parameter when logging the model to auto infer the model signature.
Experiment logged in MLflow.
सभी मशीन लर्निंग प्रयोग लोकली स्टोर होते हैं, जिन्हें आप MLflow UI से विज़ुअलाइज़ कर सकते हैं।
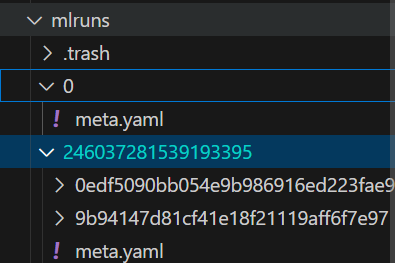
o3-mini की प्रतिक्रिया एक वैकल्पिक चरण भी देती है जिसे आप model_training.py स्क्रिप्ट में जोड़ सकते हैं। हमने यह चरण जोड़ा है ताकि देखें कि आपके मॉडल का प्रदर्शन बढ़ता है या नहीं।
# src/model_training.py
import joblib
from sklearn.ensemble import RandomForestClassifier
from sklearn.metrics import accuracy_score, precision_score, recall_score, f1_score
from data_preprocessing import load_and_preprocess_data
from sklearn.model_selection import GridSearchCV


def tune_model(X_train, y_train):
    param_grid = {"n_estimators": [50, 100, 150], "max_depth": [None, 5, 10]}
    clf = RandomForestClassifier(random_state=42)
    grid_search = GridSearchCV(clf, param_grid, cv=5, scoring="f1")
    grid_search.fit(X_train, y_train)
    print("Best parameters:", grid_search.best_params_)
    return grid_search.best_estimator_

def train_model(data_path):
    X_train, X_test, y_train, y_test, scaler = load_and_preprocess_data(data_path)

    # Initialize and train classifier
    clf = tune_model(X_train, y_train)

    # Predictions and evaluation
    y_pred = clf.predict(X_test)
    metrics = {
        "accuracy": accuracy_score(y_test, y_pred),
        "precision": precision_score(y_test, y_pred),
        "recall": recall_score(y_test, y_pred),
        "f1_score": f1_score(y_test, y_pred),
    }
    print("Model Evaluation Metrics:", metrics)

    # Save model and scaler
    joblib.dump(clf, "model_rf.joblib")
    joblib.dump(scaler, "scaler.joblib")

    return clf, scaler, metrics


if __name__ == "__main__":
    train_model("data/dataset.csv")
जैसा कि आप देख सकते हैं, हाइपरपैरामीटर ऑप्टिमाइज़ेशन से हमारे मॉडल का प्रदर्शन थोड़ा बढ़ गया है।
$ python .\src\model_training.py
Best parameters: {'max_depth': 5, 'n_estimators': 150}
Model Evaluation Metrics: {'accuracy': 0.791, 'precision': 0.7493917274939172, 'recall': 0.7439613526570048, 'f1_score': 0.7466666666666667}अब मॉडल इन्फ़रेंस बनाने का समय है। हम एक Flask वेब एप्लिकेशन विकसित करेंगे।
सबसे पहले, हमें मॉडल और स्केलर को लोड करना होगा। उसके बाद, हम यूज़र इनपुट को प्रोसेस करेंगे और भविष्यवाणी जनरेट करने के लिए उसे मॉडल को देंगे। यह एक काफ़ी सरल एप्लिकेशन है।
import joblib
import numpy as np

app = Flask(__name__)

# Load the trained model and scaler (update paths as necessary)
model = joblib.load("model_rf.joblib")
scaler = joblib.load("scaler.joblib")


@app.route("/")
def home():
    return render_template("index.html")


@app.route("/predict", methods=["POST"])
def predict():
    try:
        # Expecting form data from the HTML template
        CGPA = float(request.form.get("CGPA"))
        Internships = int(request.form.get("Internships"))
        Projects = int(request.form.get("Projects"))
        Workshops_Certifications = int(request.form.get("Workshops_Certifications"))
        AptitudeTestScore = float(request.form.get("AptitudeTestScore"))
        SoftSkillRating = float(request.form.get("SoftSkillRating"))
        ExtracurricularActivities = request.form.get("ExtracurricularActivities")
        PlacementTraining = request.form.get("PlacementTraining")
        SSC_Marks = float(request.form.get("SSC_Marks"))
        HSC_Marks = float(request.form.get("HSC_Marks"))

        # Convert categorical fields to numerical
        extra_act = 1 if ExtracurricularActivities.lower() == "yes" else 0
        placement_training = 1 if PlacementTraining.lower() == "yes" else 0

        # Construct feature vector
        features = [
            CGPA,
            Internships,
            Projects,
            Workshops_Certifications,
            AptitudeTestScore,
            SoftSkillRating,
            extra_act,
            placement_training,
            SSC_Marks,
            HSC_Marks,
        ]

        # Scale features and make prediction
        features_scaled = scaler.transform(np.array(features).reshape(1, -1))
        prediction = model.predict(features_scaled)
        result = "Placed" if prediction[0] == 1 else "Not Placed"

        return render_template("index.html", prediction=result)
    except Exception as e:
        return render_template("index.html", prediction=f"Error: {e}")


if __name__ == "__main__":
    app.run(host='0.0.0.0', port=5000, debug=True)
एप्लिकेशन के यूज़र इंटरफ़ेस को बनाने के लिए, हमने HTML कोड को index.html फ़ाइल में पेस्ट किया है। सब कुछ o3-mini मॉडल द्वारा प्रदान किया गया है। आप o3-mini से यूज़र इंटरफ़ेस को और बेहतर करने के लिए भी कह सकते हैं।
<!-- app/templates/index.html -->
<!DOCTYPE html>
<html>
<head>
    <title>Student Placement Prediction</title>
</head>
<body>
    <h1>Student Placement Prediction</h1>
    <form action="/predict" method="post" id="predictForm">
        <!-- Create inputs for each feature. Example for CGPA: -->
        <label for="CGPA">CGPA:</label>
        <input type="number" step="0.1" id="CGPA" name="CGPA" required><br><br>
        <!-- Add more inputs as per features -->
        <button type="submit">Predict</button>
    </form>
    <div id="result"></div>
    <script>
      document.getElementById('predictForm').addEventListener('submit', async (e) => {
          e.preventDefault();
          const formData = new FormData(e.target);
          const data = Object.fromEntries(formData.entries());
          // Adjust keys to match what the API expects
          data.ExtracurricularActivities = data.ExtracurricularActivities || 'No';
          data.PlacementTraining = data.PlacementTraining || 'No';

          const response = await fetch('/predict', {
              method: 'POST',
              headers: {'Content-Type': 'application/json'},
              body: JSON.stringify(data)
          });
          const result = await response.json();
          document.getElementById('result').innerText = JSON.stringify(result);
      });
    </script>
</body>
</html>
सब कुछ सेटअप हो जाने के बाद, ऐप चलाएँ और Flask द्वारा जनरेट किए गए URL पर क्लिक करें।
$ python .\app\app.py

 * Running on all addresses (0.0.0.0)
 * Running on http://127.0.0.1:5000
 * Running on http://192.168.100.41:5000
हमारा वेब एप्लिकेशन सुचारू रूप से काम कर रहा है।
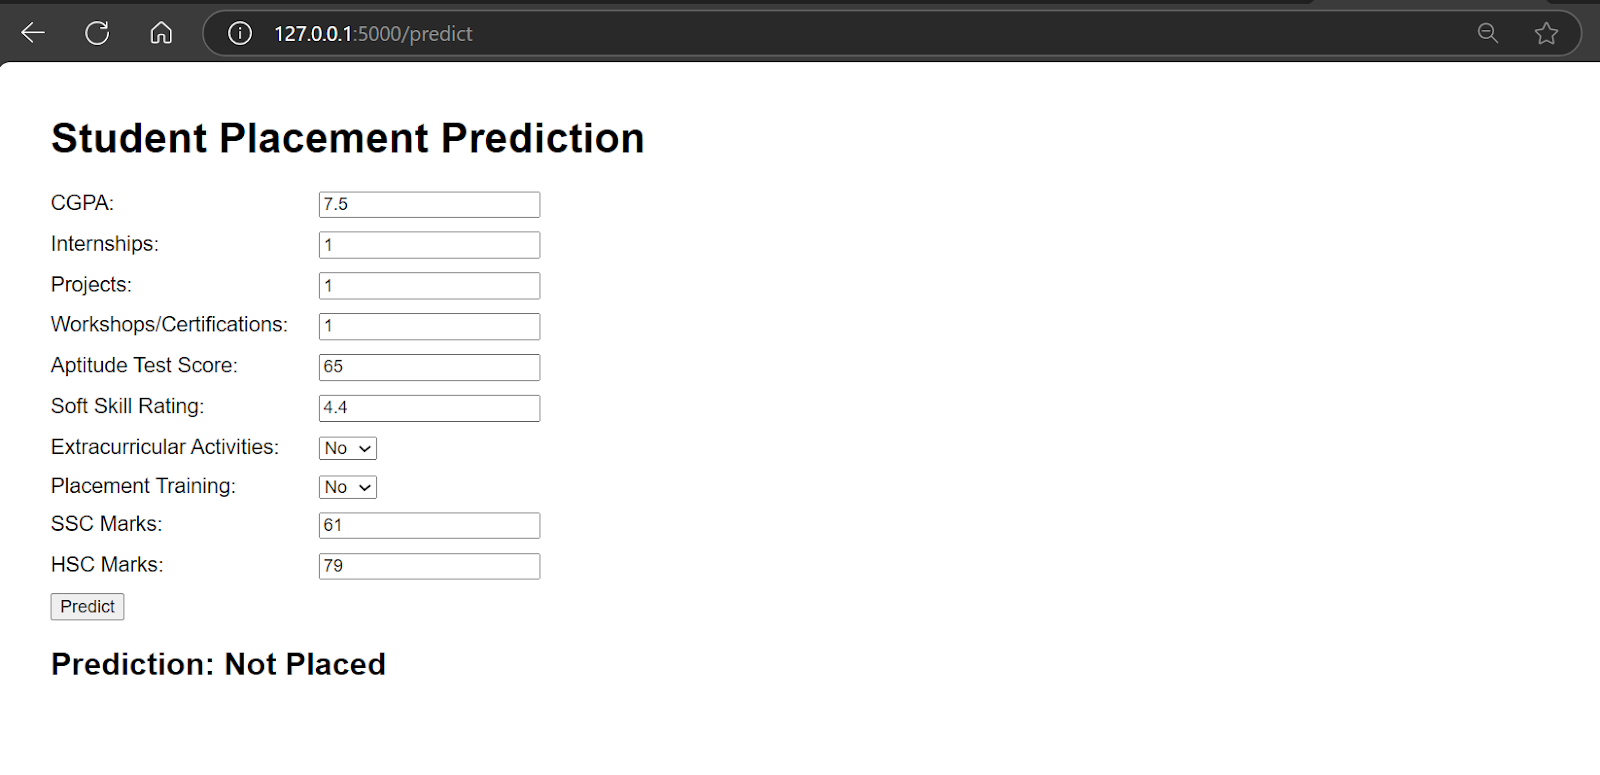
o3-mini मॉडल ने हमें Dockerfile भी प्रदान किया है, और हमें बस इसे लोकली बिल्ड करके क्लाउड पर डिप्लॉय करने से पहले परीक्षण करना है।
# Use an official Python runtime as a parent image
FROM python:3.12-slim

# Set the working directory in the container
WORKDIR /app

# Copy the requirements file and install dependencies
COPY requirements.txt ./
RUN pip install --upgrade pip && pip install -r requirements.txt

# Copy the entire project
COPY . .

# Expose port (adjust as necessary)
EXPOSE 5000

# Command to run the Flask app
CMD ["python", "app/app.py"]
Docker इमेज को निम्न कमांड से बिल्ड करें।
$ docker build -t kingabzpro/student_placement . 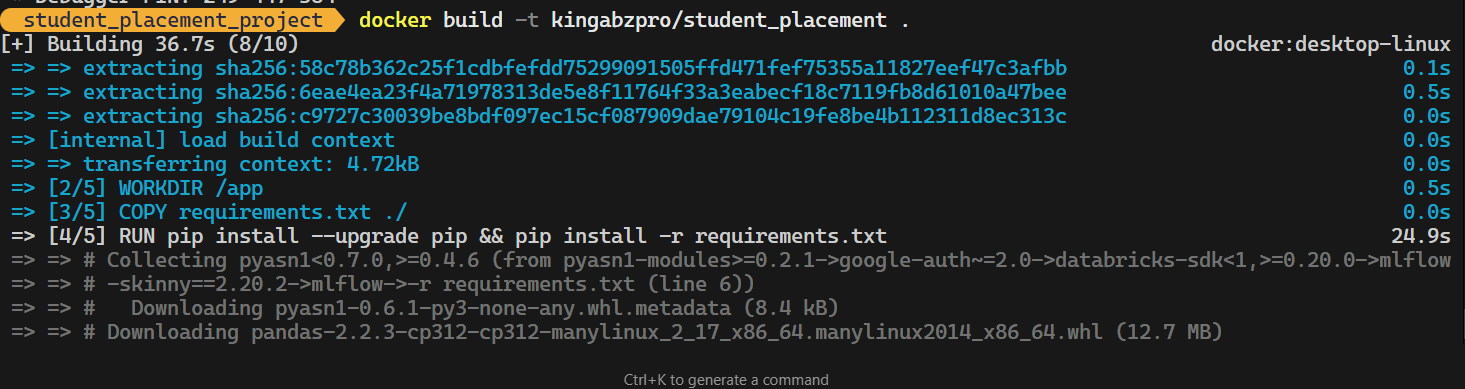
Docker इमेज को लोकली चलाएँ।
$ docker run -p 5000:5000 kingabzpro/student_placementआप देख सकते हैं कि हमारा Docker पूरी तरह चल रहा है।
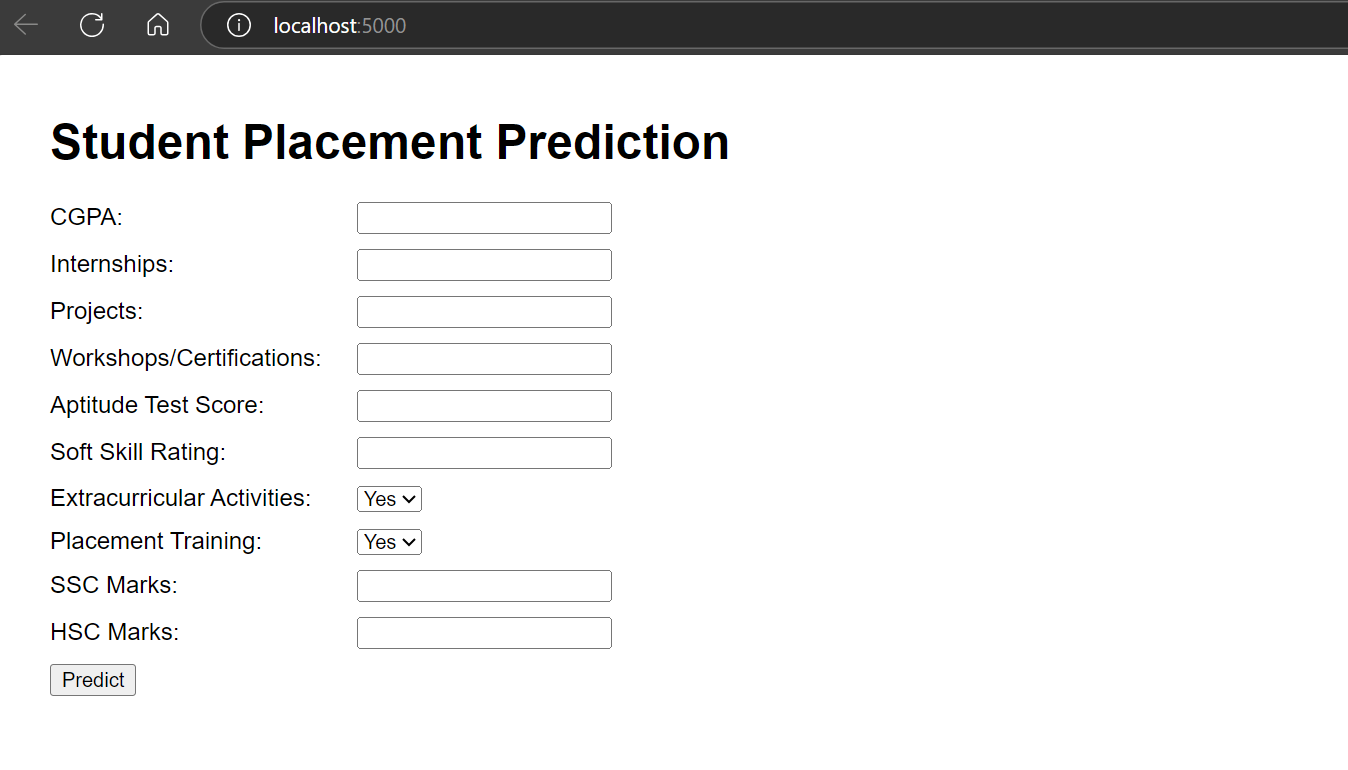
अब हमारे मशीन लर्निंग एप्लिकेशन को Hugging Face Cloud (Space) पर डिप्लॉय करने का समय है।
शुरू करने के लिए, आप नया स्पेस बना सकते हैं। एप्लिकेशन की सभी आवश्यक जानकारी जोड़ें और SDK के रूप में Docker चुनें।
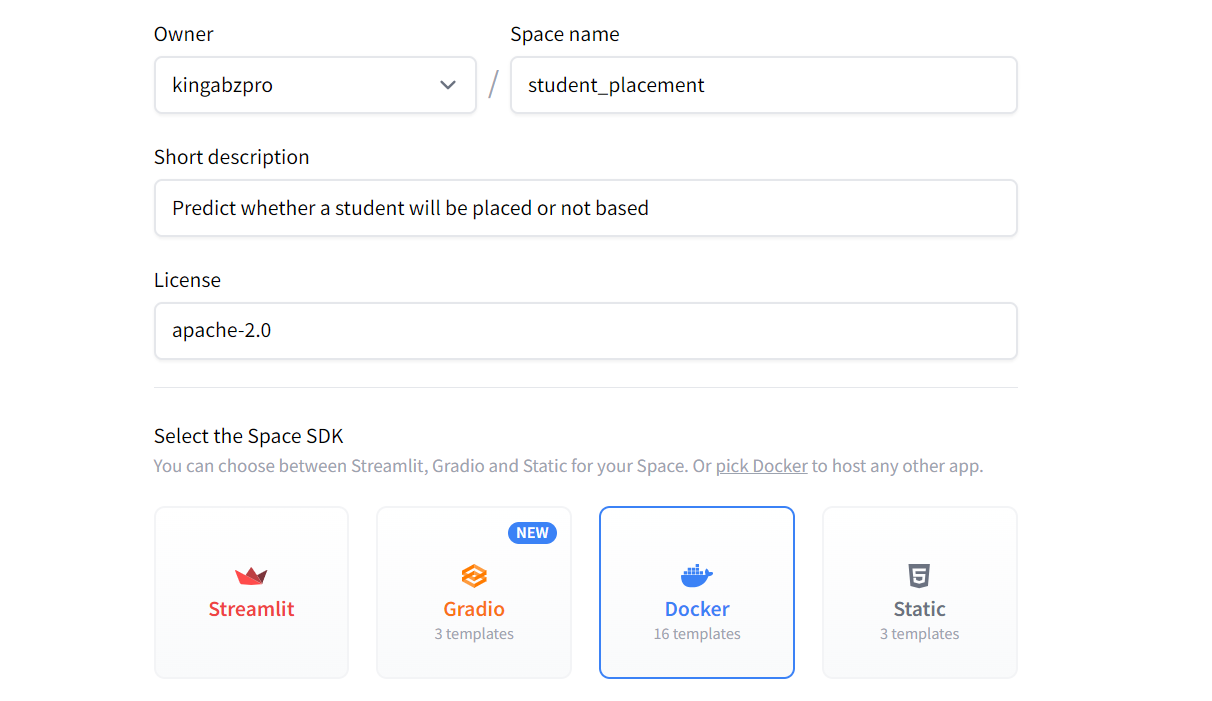
इसके बाद, यह आपको एप्लिकेशन को लोकली क्लोन करने के लिए एक URL जनरेट करेगा।
$ git clone https://huggingface.co/spaces/kingabzpro/student_placementअगला, मॉडल, स्केलर, app फ़ोल्डर, Dockerfile, और requirements.txt को एप्लिकेशन रिपॉज़िटरी में ले जाएँ।
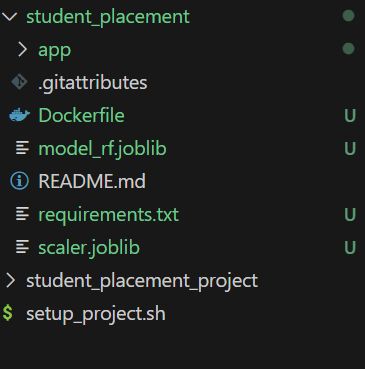
आप app.py फ़ाइल में अंतिम पंक्ति को अपडेट करके बदलाव कर सकते हैं:
app.run(host="0.0.0.0", port=7860, debug=True)Dockerfile में एक्सपोज़्ड पोर्ट की जाँच करें। हमें किसी भी पोर्ट एरर या समस्या से बचने के लिए ऐसा करना होगा:
# Expose port (adjust as necessary)
EXPOSE 7860
सारे बदलाव करने के बाद, अपने अपडेट्स को कमिट करें और रिमोट रिपॉज़िटरी पर पुश करें:
$ cd .\student_placement\
$ git add .
$ git commit -m "Initial commit of Dockerized student placement app"
$ git push
जैसे ही आप बदलाव पुश करेंगे, यह बिल्ड शुरू करेगा और फिर आपके एप्लिकेशन के लिए यूज़र इंटरफ़ेस डिप्लॉय कर देगा।
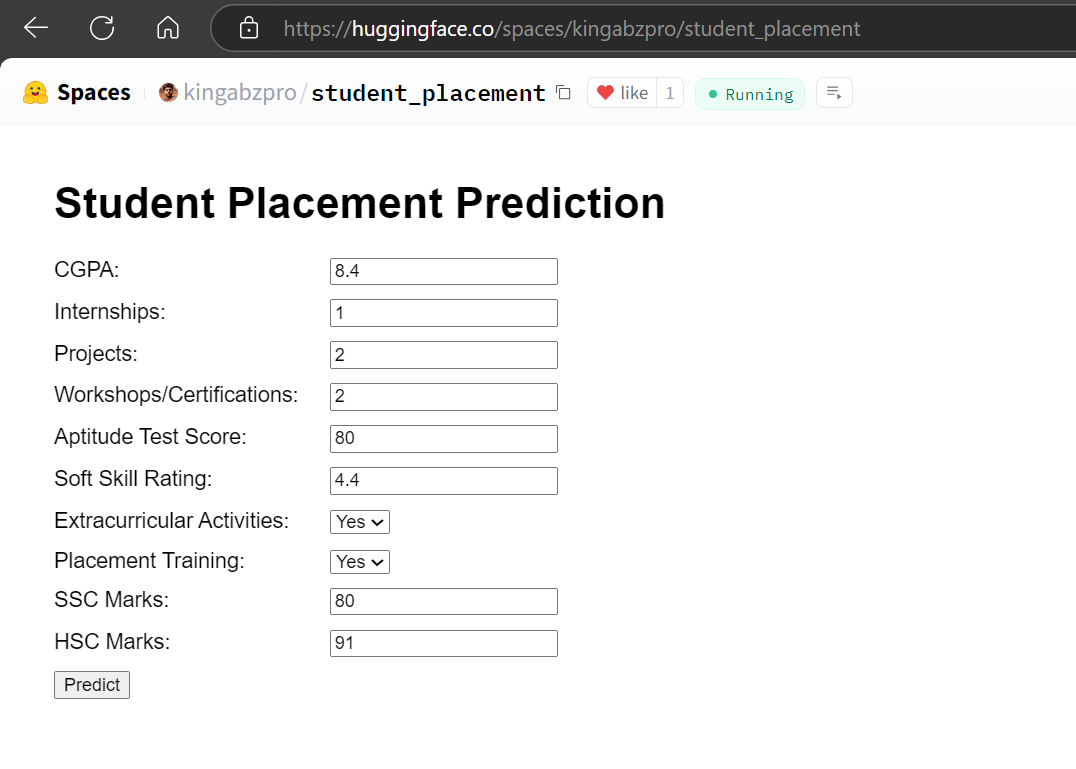
स्रोत: Student Placement
o3-mini ने प्रोजेक्ट डायरेक्टरी मैनेजमेंट से लेकर वेब एप्लिकेशन को क्लाउड पर सफलतापूर्वक डिप्लॉय करने तक बेहतरीन काम किया है।
आप Google के अत्याधुनिक मॉडल के बारे में भी पढ़ सकते हैं और इस ट्यूटोरियल का पालन करके अपना स्वयं का AI एप्लिकेशन बनाना सीख सकते हैं Building Multimodal AI Application with Gemini 2.0 Pro।
o3-mini मॉडल अलग है, जिसका मतलब है कि फ़ॉलो-अप रिक्वेस्ट करने और कोड डीबग करने में आपको सावधान रहना होगा। इसके साथ प्रभावी ढंग से काम करने में मदद के लिए यहाँ कुछ सुझाव हैं:
निर्देश देते समय सुनिश्चित करें कि वे स्पष्ट और सुसंगत हों। यदि आप कई कमांड देते हैं, तो o3-mini सबसे हालिया निर्देश को प्राथमिकता देगा। इसका अर्थ है कि लंबी प्रॉम्प्ट चेन में नवीनतम कमांड को वरीयता मिलेगी, जिससे पहले दिए गए निर्देश ओवरराइड हो सकते हैं।
कुछ कोड समस्याओं को मॉडल पर निर्भर होने के बजाय मैन्युअल रूप से हल करने की आवश्यकता हो सकती है। यदि आप o3-mini से कोड के किसी विशिष्ट हिस्से को ठीक करने के लिए कहते हैं, तो यह केवल उसी हिस्से को संशोधित करेगा। हालाँकि, इससे संबंधित हिस्से टूट सकते हैं, क्योंकि मॉडल हमेशा निर्भरताओं या व्यापक संदर्भ का ध्यान नहीं रखता।
अपने प्रॉम्प्ट में सभी प्रासंगिक विवरण शामिल करें, जैसे कच्चा डेटा, स्पष्ट रूप से परिभाषित रो और कॉलम, और कोई भी अतिरिक्त संदर्भ। इससे मॉडल आपकी रिक्वेस्ट को अधिक सटीक रूप से समझेगा और बेहतर परिणाम देगा।
स्पष्ट रूप से बताएं कि आप मॉडल से क्या वापस चाहते हैं। उदाहरण के लिए, यह निर्दिष्ट करें कि क्या आपको फ़ोल्डर्स, फ़ाइलें, Docker कमांड्स, या समाधान को लागू करने के चरण-दर-चरण निर्देश चाहिए। इससे आउटपुट आपकी अपेक्षाओं के अनुरूप रहेगा।
ऐसे सुव्यवस्थित बेस प्रॉम्प्ट से शुरू करें जो आपकी 90% जरूरतों को कवर करे। बेस स्थापित होने के बाद, आप प्रक्रिया को परिष्कृत करने, ठीक करने या और चरण जोड़ने के लिए फ़ॉलो-अप कमांड दे सकते हैं।
o3-mini मॉडल GPT-4o की तुलना में एक बेहतर विकल्प के रूप में उभरता है, जो o1 से तेज़ प्रदर्शन देता है और Python व HTML कोडिंग जैसे कार्यों में उत्कृष्ट है। उल्लेखनीय है कि o3-mini द्वारा जनरेट किया गया Python कोड अधिकांश समय बिना किसी समस्या के चलता है। यह HTML कोड को भी बेहतर बना सकता है, जिससे आप अपने यूज़र इंटरफ़ेस को सुधारकर उसे अधिक आकर्षक बना सकते हैं।
इस ट्यूटोरियल में, हमने मशीन लर्निंग प्रोजेक्ट के संदर्भ में o3-mini मॉडल की शक्ति का अन्वेषण किया। o3-mini डेटा वैज्ञानिकों, मशीन लर्निंग इंजीनियरों, और तकनीकी पेशेवरों के लिए एक उत्कृष्ट उपकरण साबित होता है। जटिल कार्यों को कुशलतापूर्वक संभालने की इसकी क्षमता इसे किसी भी वर्कफ़्लो में मूल्यवान बनाती है।
सर्वोत्तम परिणाम पाने के लिए, आपको बस अपने शुरुआती प्रॉम्प्ट में सभी प्रासंगिक सामग्री और डिलीवेरेबल्स सहित व्यापक संदर्भ प्रदान करना है। एक बार मॉडल आउटपुट जनरेट कर दे, तो आप अपने कोड एडिटर में जाकर स्क्रिप्ट्स चलाना शुरू कर सकते हैं और दिए गए निर्देशों के साथ कोड को लागू कर सकते हैं।
अगला कदम है कि आप अपने स्वयं के अत्याधुनिक LLMs को क्लाउड पर कैसे डिप्लॉय करें, यह सीखें। OpenAI पर निर्भर होने के बजाय, यह आपको अपनी लागत, सटीकता, और डेटा की पहुँच पर पूरा नियंत्रण देता है। इस प्रक्रिया के बारे में सब कुछ सीखने के लिए How to Deploy LLMs with BentoML ट्यूटोरियल का पालन करें।
शीर्ष DataCamp कोर्स
{count, plural, one {कोर्स} other {कोर्स}}
{count, plural, one {कोर्स} other {कोर्स}}
{count, plural, one {कोर्स} other {कोर्स}}
